Certified-Data-Engineer-Professional Latest Dumps & Certified-Data-Engineer-Professional Dumps Torrent & Certified-Data-Engineer-Professional Valid Dumps

Regarding the process of globalization, every fighter who seeks a better life needs to keep pace with its tendency to meet challenges. Certified-Data-Engineer-Professional certification is a stepping stone for you to stand out from the crowd. Nowadays, having knowledge of the Certified-Data-Engineer-Professional study braindumps become widespread, if you grasp solid technological knowledge, you are sure to get a well-paid job and be promoted in a short time. According to our survey, those who have passed the exam with our Certified-Data-Engineer-Professional Test Guide convincingly demonstrate their abilities of high quality, raise their professional profile, expand their network and impress prospective employers.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Develop unit and integration tests for data processing code
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Configure environments, dependencies, memory, and retry behavior
- 7. Use control flow operators in pipeline components
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
>> Valid Certified-Data-Engineer-Professional Exam Pdf <<
Certified-Data-Engineer-Professional - Fantastic Valid Databricks Certified Data Engineer Professional Exam Pdf
Many candidates who are ready to participate in the Databricks certification Certified-Data-Engineer-Professional exam may see many websites available online to provide resources about Databricks certification Certified-Data-Engineer-Professional exam. However, TopExamCollection is the only website whose exam practice questions and answers are developed by a study of the leading IT experts's reference materials. The information of TopExamCollection can ensure you pass your first time to participate in the Databricks Certification Certified-Data-Engineer-Professional Exam.
Databricks Certified Data Engineer Professional Sample Questions (Q140-Q145):
NEW QUESTION # 140
Where in the Spark UI can one diagnose a performance problem induced by not leveraging predicate push-down?
- A. In the Delta Lake transaction log. by noting the column statistics
- B. In the Executor's log file, by gripping for "predicate push-down"
- C. In the Storage Detail screen, by noting which RDDs are not stored on disk
- D. In the Query Detail screen, by interpreting the Physical Plan
- E. In the Stage's Detail screen, in the Completed Stages table, by noting the size of data read from the Input column
Answer: D
Explanation:
This is the correct answer because it is where in the Spark UI one can diagnose a performance problem induced by not leveraging predicate push-down. Predicate push-down is an optimization technique that allows filtering data at the source before loading it into memory or processing it further. This can improve performance and reduce I/O costs by avoiding reading unnecessary data. To leverage predicate push-down, one should use supported data sources and formats, such as Delta Lake, Parquet, or JDBC, and use filter expressions that can be pushed down to the source. To diagnose a performance problem induced by not leveraging predicate push-down, one can use the Spark UI to access the Query Detail screen, which shows information about a SQL query executed on a Spark cluster. The Query Detail screen includes the Physical Plan, which is the actual plan executed by Spark to perform the query. The Physical Plan shows the physical operators used by Spark, such as Scan, Filter, Project, or Aggregate, and their input and output statistics, such as rows and bytes. By interpreting the Physical Plan, one can see if the filter expressions are pushed down to the source or not, and how much data is read or processed by each operator.
NEW QUESTION # 141
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
- A. Spill resulting from attached volume storage being too small.
- B. Task queueing resulting from improper thread pool assignment.
- C. Skew caused by more data being assigned to a subset of spark-partitions.
- D. Network latency due to some cluster nodes being in different regions from the source data
- E. Credential validation errors while pulling data from an external system.
Answer: C
Explanation:
This is the correct answer because skew is a common situation that causes increased duration of the overall job. Skew occurs when some partitions have more data than others, resulting in uneven distribution of work among tasks and executors. Skew can be caused by various factors, such as skewed data distribution, improper partitioning strategy, or join operations with skewed keys. Skew can lead to performance issues such as long-running tasks, wasted resources, or even task failures due to memory or disk spills.
NEW QUESTION # 142
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement ?the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
What code will satisfy the requirements?
- A. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading < 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - B. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect_or_drop("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - C. @dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - D. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
Answer: C
Explanation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect,
@dlt.expect_or_drop, and @dlt.expect_all.
@dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows. Instead, failing rows can be written to a quarantine table.
@dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
Good rows (reading < 120) go to the silver table.
Bad rows (reading >= 120) go to a quarantine table.
Bad rows should not be included in silver.
The correct implementation is Option A, where:
The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
The quarantine table applies an expectation for reading >= 120, ensuring bad records are captured separately.
Other options are incorrect:
Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
NEW QUESTION # 143
A Data Engineer is building a simple data pipeline using Lakeflow Declarative Pipelines (LDP) in Databricks to ingest customer data. The raw customer data is stored in a cloud storage location in JSON format. The task is to create Lakeflow Declarative Pipelines that read the raw JSON data and write it into a Delta table for further processing. Which code snippet will correctly ingest the raw JSON data and create a Delta table using LDP?
- A. import dlt
@dlt.table
def raw_customers():
return spark.read.format("csv").load("s3://my-bucket/raw-customers/") - B. import dlt
@dlt.view
def raw_customers():
return spark.format.json("s3://my-bucket/raw-customers/") - C. import dlt
@dlt.table
def raw_customers():
return spark.read.json("s3://my-bucket/raw-customers/") - D. import dlt
@dlt.table
def raw_customers():
return spark.read.format("parquet").load("s3://my-bucket/raw-customers/")
Answer: C
Explanation:
The correct method to define a table using Lakeflow Declarative Pipelines (LDP) is with the
@dlt.table decorator, which persists the output as a managed Delta table. When ingesting raw JSON data, spark.read.json() or spark.read.format("json").load() is the standard approach. This reads JSON- formatted files from the source and stores them in Delta format automatically managed by Databricks.
NEW QUESTION # 144
A view is registered with the following code:
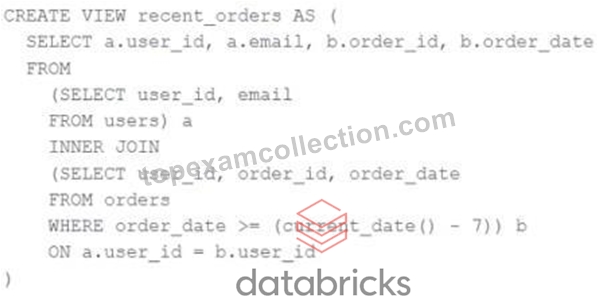
Both users and orders are Delta Lake tables.
Which statement describes the results of querying recent_orders?
- A. Results will be computed and cached when the view is defined; these cached results will incrementally update as new records are inserted into source tables.
- B. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- D. All logic will execute when the view is defined and store the result of joining tables to the DBFS; this stored data will be returned when the view is queried.
Answer: B
NEW QUESTION # 145
......
Passing the Certified-Data-Engineer-Professional exam requires many abilities of you: personal ability, efficient practice materials, as well as a small touch of luck. So your personal effort is brilliant but insufficient to pass exam, and our Certified-Data-Engineer-Professional exam materials can facilitate the process smoothly and successfully. Our Certified-Data-Engineer-Professional Study Dumps are suitable for you whichever level you are in right now. Whether you are in entry-level position or experienced exam candidates who have tried the exam before, this is the perfect chance to give a shot.
Latest Certified-Data-Engineer-Professional Test Objectives: https://www.topexamcollection.com/Certified-Data-Engineer-Professional-vce-collection.html
- Certified-Data-Engineer-Professional Latest Practice Questions 🚤 Certified-Data-Engineer-Professional Exam Sims ⏮ Certified-Data-Engineer-Professional Latest Dumps Files 🤞 Go to website ⇛ www.exam4labs.com ⇚ open and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 🎺Certified-Data-Engineer-Professional Latest Practice Questions
- The Databricks Certified-Data-Engineer-Professional Web-Based Practice Exam 🧎 Enter ⮆ www.pdfvce.com ⮄ and search for ➠ Certified-Data-Engineer-Professional 🠰 to download for free 🖱Certified-Data-Engineer-Professional Latest Dumps Files
- Exam Certified-Data-Engineer-Professional Introduction 🎋 Certified-Data-Engineer-Professional Exam Online 🔫 Certified-Data-Engineer-Professional Latest Practice Questions 🌖 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and obtain a free download on ☀ www.dumpsquestion.com ️☀️ 🍉Dumps Certified-Data-Engineer-Professional Torrent
- 100% Pass 2026 Latest Certified-Data-Engineer-Professional: Valid Databricks Certified Data Engineer Professional Exam Pdf 🤍 The page for free download of ⏩ Certified-Data-Engineer-Professional ⏪ on ⮆ www.pdfvce.com ⮄ will open immediately ⏮Certified-Data-Engineer-Professional Exam Online
- Valid Certified-Data-Engineer-Professional Exam Pdf High Hit Rate Questions Pool Only at www.torrentvce.com 🔽 Search for ▷ Certified-Data-Engineer-Professional ◁ on 【 www.torrentvce.com 】 immediately to obtain a free download 💏Certified-Data-Engineer-Professional Exam Online
- Certified-Data-Engineer-Professional New Dumps Book 🥎 Exam Certified-Data-Engineer-Professional Introduction 🍤 Guaranteed Certified-Data-Engineer-Professional Passing 😲 Easily obtain 【 Certified-Data-Engineer-Professional 】 for free download through 【 www.pdfvce.com 】 👗Certified-Data-Engineer-Professional Exam Sims
- Guaranteed Certified-Data-Engineer-Professional Passing ↘ Latest Certified-Data-Engineer-Professional Exam Camp 🚓 Latest Certified-Data-Engineer-Professional Braindumps Sheet 🍩 Search for [ Certified-Data-Engineer-Professional ] and download it for free on ⮆ www.prep4sures.top ⮄ website 🦉Certified-Data-Engineer-Professional Valid Exam Practice
- High Pass-Rate Valid Certified-Data-Engineer-Professional Exam Pdf by Pdfvce 📃 Easily obtain free download of “ Certified-Data-Engineer-Professional ” by searching on ( www.pdfvce.com ) 🧟Reliable Certified-Data-Engineer-Professional Exam Dumps
- Valid Certified-Data-Engineer-Professional Exam Pdf High Hit Rate Questions Pool Only at www.practicevce.com 🕖 Easily obtain ⇛ Certified-Data-Engineer-Professional ⇚ for free download through ▷ www.practicevce.com ◁ 🛷Certified-Data-Engineer-Professional Exam Online
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional Useful Valid Exam Pdf 📭 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and download it for free on ➠ www.pdfvce.com 🠰 website 🐩New Certified-Data-Engineer-Professional Test Pdf
- Databricks Valid Certified-Data-Engineer-Professional Exam Pdf: Databricks Certified Data Engineer Professional - www.pdfdumps.com Test Engine Simulation 🎉 Open ⏩ www.pdfdumps.com ⏪ enter 「 Certified-Data-Engineer-Professional 」 and obtain a free download 🤑Dumps Certified-Data-Engineer-Professional Torrent
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes