P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by ActualtestPDF: https://drive.google.com/open?id=1-Syj_5jwm7lJ_z1P9Np1M8q3rFL4bgtQ
If you are determined to purchase our AI-103 valid exam collection materials for your companies, if you pursue long-term cooperation with site, we will have some relate policy. Firstly we provide one-year service warranty for every buyer who purchased AI-103 valid exam collection materials. Every buyer can share one year free updates and preparation assist. Secondly if you want to get the free updates not just for one year, you want to still get the new version of Microsoft AI-103 valid exam collection materials after one year, you share 50% discount for the second year.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Topic 2: Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Topic 3: Implement generative AI solutions | 25-30% | - Develop generative AI applications
|
| Topic 4: Plan and manage Azure AI solutions | 25-30% | - Plan Azure AI resources
|
| Topic 5: Implement agentic solutions | 20-25% | - Build AI agents
|
The Microsoft AI-103 certification exam is one of the top-rated and valuable credentials in the Microsoft world. This Developing AI Apps and Agents on Azure AI-103 exam questions is designed to validate the candidate's skills and knowledge. With Microsoft AI-103 exam dumps everyone can upgrade their expertise and knowledge level. By doing this the successful Microsoft AI-103 Exam candidates can gain several personal and professional benefits in their career and achieve their professional career objectives in a short time period.
NEW QUESTION # 16
You have a chat app in a Microsoft Foundry project and an Azure AI Search vectorized index.
You need to connect to the index to meet the following requirements:
- Complex questions must retrieve information from multiple chunks.
- Multi-turn conversations must influence retrieval planning.
- Retrievals must run in parallel to reduce latency.
Which retrieval approach should you use?
Answer: D
Explanation:
An agentic Retrieval-Augmented Generation (RAG) architecture is the best fit for your requirements. Traditional, linear RAG pipelines struggle with complex, multi-turn dependencies, whereas an agentic approach natively solves them through iterative reasoning and tool orchestration.
Here is how an agentic RAG pattern specifically satisfies each the three technical requirements:
1. Complex Questions & Multi-Chunk Retrieval
The Challenge: Complex questions often require aggregating distinct pieces of information scattered across different documents or sections.
The Agentic Solution: An agent uses a Reasoning and Acting (ReAct) loop. It evaluates the user's query, breaks it down into sub-questions, and executes multiple distinct search queries. It then synthesizes the information from these diverse chunks before generating a final response.
2. Multi-Turn Conversations & Retrieval Planning
The Challenge: Standard RAG often just passes the latest user message or a simple chat history summary to the search index, which can lose context or misinterpret the user's true intent in long conversations.
The Agentic Solution: The agent acts as a query planner. It maintains the state of the conversation and dynamically decides if a retrieval is needed, what specific keywords or vectors to target based on past turns, and how to reformulate the query to bridge context gaps.
3. Parallel Retrievals for Low Latency
The Challenge: Sequential lookups drastically increase time-to-first-token (TTFT), harming the chat user experience.
The Agentic Solution: Modern AI agent frameworks allow the LLM to emit multiple tool calls simultaneously. The application layer can intercept these calls and execute parallel asynchronous queries against your Azure AI Search vectorized index, drastically minimizing latency.
Reference:
https://arxiv.org/html/2501.09136v1
NEW QUESTION # 17
You have a Microsoft Foundry project that contains an agent.
The knowledge source for the agent is a set of scanned PDF troubleshooting guides stored in Azure Blob Storage. The guide pages contain two-column layouts and tables.
You use Azure Content Understanding in Foundry Tools to process the PDFs.
You plan to ingest the processed content into an index for Retrieval Augmented Generation (RAG) and store extracted fields for downstream automation.
Stakeholders must be able to verify where each extracted field value came from in the original PDF and route low-reliability extractions for manual review.
You need to ensure that the Content Understanding document analyzer output includes a per- field confidence score and source grounding to locations within the source document.
What should you do?
Answer: D
Explanation:
To fulfill all your requirements using Azure Content Understanding in Foundry Tools, you need to configure a custom document analyzer with specific flags, set up an index ingestion pipeline, and build a downstream human-in-the-loop validation rule.
*-> 1. Enable Confidence Scores and Source Grounding
To force the analyzer to provide per-field confidence metrics and precise layout/bounding box coordinates for verification, you must opt-in to the estimate FieldSourceAndConfidence parameter within your configuration.
Option A (Global): Set estimateFieldSourceAndConfidence = true in the main analyzer config to evaluate all fields.
Option B (Field-Level): Set estimateSourceAndConfidence = true under individual field schemas.This ensures the generated JSON response populates the bounding box coordinates, page numbers, and a confidence score 0.0 to 1.0 for every extracted entity.
2. Configure Document Extraction for Two-Column & Table Layouts
3. Build the Ingestion Pipeline (RAG vs. Automation Dual-Path)
4. Implement Threshold Routing and Source Verification
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/content-understanding/document/overview
NEW QUESTION # 18
Hotspot Question
You develop a test method to verify the results retrieved from a call to the Azure Vision in Foundry Tools API. The call is used to analyze the existence of company logos in images. The call returns a collection of brands named brands.
You have the following code segment: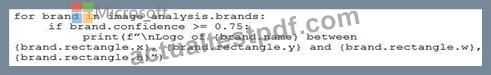
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.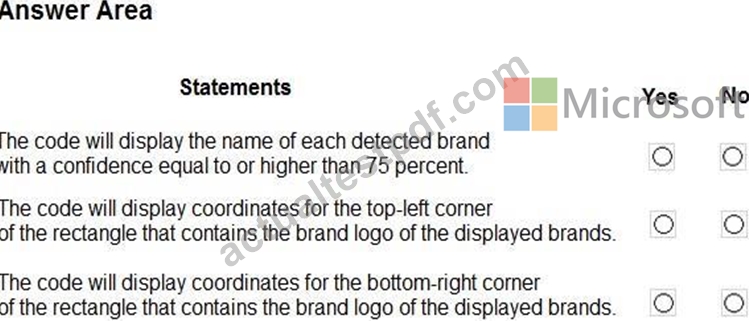
Answer:
Explanation: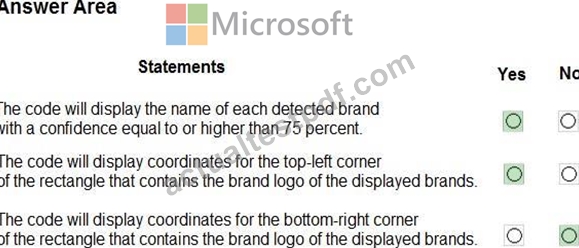
Explanation:
Box 1: Yes
The code segment correctly filters for and displays the name (and coordinates) of each detected brand only if the model's confidence score is 75 percent or higher.The expression if brand.confidence >= 0.75 guarantees that only brands meeting or exceeding this threshold are printed.
Box 2: Yes
The code segment will display the coordinates. Specifically, it prints the x and y values of the rectangle's top-left corner alongside its width (w) and height (h) for any detected brand with a confidence score equal to or greater than 0.75 (75%).
The provided code uses the properties directly to extract the bounding box:
brand.rectangle.x and brand.rectangle.y: The coordinates of the top-left corner of the bounding box.
brand.rectangle.w and brand.rectangle.h: The width and height of the bounding box.
Box 3: No
See Box 2 above.
Reference:
https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/concept-brand-detection
NEW QUESTION # 19
You need to optimize content filter configurations by running tests on sample questions.
Solution: From Content Safety Studio, you use the Moderate text content feature to run the tests.
Does this meet the requirement?
Answer: A
Explanation:
Comprehensive and Detailed 150 to 250 words of Explanation From Azure AI Apps and Agents Developer/Course Guide/topics:
Yes. Moderate text content is exactly the Content Safety testing workflow Microsoft documents for analyzing sample text and tuning harmful-content filtering.
Microsoft ' s current quickstart instructs users to open the Moderate text content panel, provide sample text, and select Run test . The service returns detected harm categories together with severity levels. The user can then open Configure filters , adjust which severity levels are allowed or prohibited for each category, and run the text again to verify the behavior. Microsoft Learn That directly satisfies the requirement to optimize the content-filter configuration by testing sample questions.
The Safety metaprompt capability influences generative model behavior but does not provide the same moderation-threshold testing. Protected material detection evaluates a separate protected-content concern and likewise is not the harmful-content filter test surface.
Therefore, the answer printed in the supplied document ( B, No ) conflicts with current Microsoft Learn documentation. The verified answer is A, Yes .
Study Guide alignment: configure safety filters, guardrails, risk detection, content moderation, and safety evaluations for generative AI and agentic systems . Microsoft Learn
NEW QUESTION # 20
You have a Microsoft Foundry project that contains an internal Q & A agent.
Users report the following issues when they ask the agent questions:
* An increase in the following response: "No relevant information found"
* Periodic HTTP 429 rate limit exceeded errors during peak hours
You need to identify whether each issue is caused by model unavailability, resource limits, or inference failures.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Metrics to enable: Model Availability Rate and Provisioned Utilization
Diagnostic log to collect: trace
The correct metrics are Model Availability Rate and Provisioned Utilization . Model Availability Rate identifies whether failures are caused by service-side model unavailability because it is calculated from total calls minus server errors. Provisioned Utilization identifies resource-limit conditions because Microsoft states that when utilization reaches or exceeds 100%, calls are throttled and HTTP 429 errors are returned. This directly maps to the reported peak-hour rate-limit errors.
The correct diagnostic log is trace . For an internal Q & A scenario, trace logging is required to analyze question-answering behavior, including unanswered questions. Microsoft's custom question answering analytics guidance states that diagnostic logging stores telemetry and chat logs and instructs enabling Trace in addition to Audit, RequestResponse, and AllMetrics. The sample Kusto queries for unanswered questions inspect the answer, question, score, and knowledge base ID, and filter unanswered results by a score of zero.
RequestResponse is useful for request status and latency, and Audit is for administrative operations, but neither is the best diagnostic category for analyzing Q & A inference behavior such as "No relevant information found." Reference topics: Foundry monitoring, model availability, provisioned utilization, diagnostic logging, custom question answering analytics, and trace logs.
NEW QUESTION # 21
......
If you free download the demos of our AI-103 study guide to have a try, then you will find that rather than solely theory-oriented, our AI-103 actual exam provides practice atmosphere when you download them, you can practice every day just like answering on the real AI-103 Practice Exam. We can help you demonstrate your personal ability and our AI-103 exam materials are the product you cannot miss.
Latest AI-103 Test Vce: https://www.actualtestpdf.com/Microsoft/AI-103-practice-exam-dumps.html
DOWNLOAD the newest ActualtestPDF AI-103 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1-Syj_5jwm7lJ_z1P9Np1M8q3rFL4bgtQ