BONUS!!! Download part of CertkingdomPDF Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=19-xoL1TjGQtvnyGXhJiZ4ZLF5BJcKO8y
Once you have any questions about our Databricks-Generative-AI-Engineer-Associate actual exam, you can contact our staff online or send us an email. We have a dedicated all-day online service to help you solve problems. Before purchasing, you may be confused about what kind of Databricks-Generative-AI-Engineer-Associate guide questions you need. You can consult our staff online. After the consultation, your doubts will be solved and you will choose the Databricks-Generative-AI-Engineer-Associate Learning Materials that suit you. Our online staff is professionally trained and they have great knowledge on the Databricks-Generative-AI-Engineer-Associate exam questions to help you pass the Databricks-Generative-AI-Engineer-Associate exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> New Databricks-Generative-AI-Engineer-Associate Exam Vce <<
Our Databricks-Generative-AI-Engineer-Associate study materials have designed three different versions for all customers to choose. The three different versions include the PDF version, the software version and the online version, they can help customers solve any questions and meet their all needs. Although the three different versions of our Databricks-Generative-AI-Engineer-Associate Study Materials provide the same demo for all customers, they also have its particular functions to meet different the unique needs from all customers. The most important function of the online version of our Databricks-Generative-AI-Engineer-Associate study materials is the practicality.
NEW QUESTION # 27
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: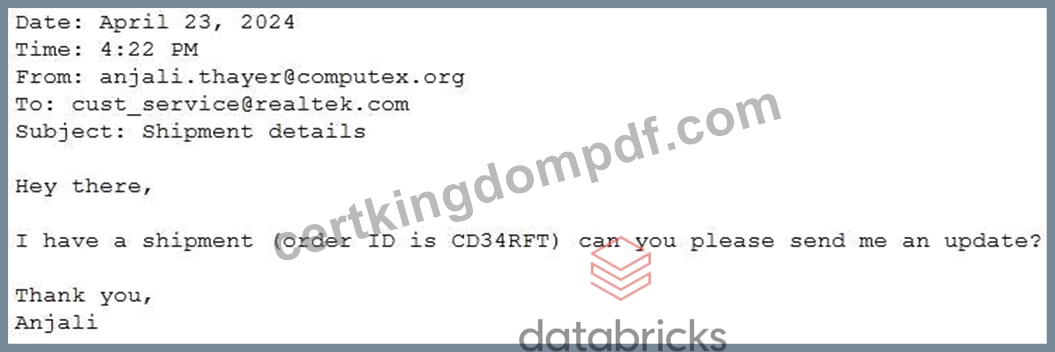
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
Answer: D
Explanation:
Problem Context : The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options :
* Option A : Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B : Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C : Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D : While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore, Option B is optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
NEW QUESTION # 28
A Generative AI Engineer is developing an agent system using a popular agent-authoring library. The agent comprises multiple parallel and sequential chains. The engineer encounters challenges as the agent fails at one of the steps, making it difficult to debug the root cause. They need to find an appropriate approach to research this issue and discover the cause of failure. Which approach do they choose?
Answer: A
Explanation:
For complex agentic systems (like those built with LangGraph or Autogen), standard logging is often insufficient because the "state" of the agent changes dynamically. MLflow Tracing is the designated Generative AI engineering standard for debugging these systems. Tracing provides a visual, hierarchical timeline of every call made during an agent's execution-including internal LLM reasoning, tool calls, and data transformations. When a step fails, the trace allows the engineer to click into that specific node to see the exact input sent to the LLM and the raw output received. This is much faster and more comprehensive than manually deconstructing the agent (D) or adding manual logs (C). While mlflow.evaluate (B) is useful for measuring performance across a whole dataset, it is not a tool for real-time debugging of a single execution failure.
NEW QUESTION # 29
A Generative Al Engineer has built an LLM-based system that will automatically translate user text between two languages. They now want to benchmark multiple LLM's on this task and pick the best one. They have an evaluation set with known high quality translation examples. They want to evaluate each LLM using the evaluation set with a performant metric.
Which metric should they choose for this evaluation?
Answer: B
Explanation:
The task is to benchmark LLMs for text translation using an evaluation set with known high-quality examples, requiring a performant metric. Let's evaluate the options.
* Option A: ROUGE metric
* ROUGE (Recall-Oriented Understudy for Gisting Evaluation) measures overlap between generated and reference texts, primarily for summarization. It's less suited for translation, where precision and word order matter more.
* Databricks Reference:"ROUGE is commonly used for summarization, not translation evaluation"("Generative AI Cookbook," 2023).
* Option B: BLEU metric
* BLEU (Bilingual Evaluation Understudy) evaluates translation quality by comparing n-gram overlap with reference translations, accounting for precision and brevity. It's widely used, performant, and appropriate for this task.
* Databricks Reference:"BLEU is a standard metric for evaluating machine translation, balancing accuracy and efficiency"("Building LLM Applications with Databricks").
* Option C: NDCG metric
* NDCG (Normalized Discounted Cumulative Gain) assesses ranking quality, not text generation.
It's irrelevant for translation evaluation.
* Databricks Reference:"NDCG is suited for ranking tasks, not generative output scoring" ("Databricks Generative AI Engineer Guide").
* Option D: RECALL metric
* Recall measures retrieved relevant items but doesn't evaluate translation quality (e.g., fluency, correctness). It's incomplete for this use case.
* Databricks Reference: No specific extract, but recall alone lacks the granularity of BLEU for text generation tasks.
Conclusion: Option B (BLEU) is the best metric for translation evaluation, offering a performant and standard approach, as endorsed by Databricks' guidance on generative tasks.
NEW QUESTION # 30
A Generative AI Engineer is creating an agent-based LLM system for their favorite monster truck team. The system can answer text based questions about the monster truck team, lookup event dates via an API call, or query tables on the team's latest standings.
How could the Generative AI Engineer best design these capabilities into their system?
Answer: D
Explanation:
In this scenario, the Generative AI Engineer needs to design a system that can handle different types of queries about the monster truck team. The queries may involve text-based information, API lookups for event dates, or table queries for standings. The best solution is to implement a tool-based agent system .
Here's how option B works, and why it's the most appropriate answer:
* System Design Using Agent-Based Model : In modern agent-based LLM systems, you can design a system where the LLM (Large Language Model) acts as a central orchestrator. The model can " decide
" which tools to use based on the query. These tools can include API calls, table lookups, or natural language searches. The system should contain a system prompt that informs the LLM about the available tools.
* System Prompt Listing Tools : By creating a well-crafted system prompt , the LLM knows which tools are at its disposal. For instance, one tool may query an external API for event dates, another might look up standings in a database, and a third may involve searching a vector database for general text- based information. The agent will be responsible for calling the appropriate tool depending on the query.
* Agent Orchestration of Calls : The agent system is designed to execute a series of steps based on the incoming query. If a user asks for the next event date, the system will recognize this as a task that requires an API call. If the user asks about standings, the agent might query the appropriate table in the database. For text-based questions, it may call a search function over ingested data. The agent orchestrates this entire process, ensuring the LLM makes calls to the right resources dynamically.
* Generative AI Tools and Context : This is a standard architecture for integrating multiple functionalities into a system where each query requires different actions. The core design in option B is efficient because it keeps the system modular and dynamic by leveraging tools rather than overloading the LLM with static information in a system prompt (like option D).
* Why Other Options Are Less Suitable :
* A (RAG Architecture) : While relevant, simply ingesting PDFs into a vector store only helps with text-based retrieval. It wouldn't help with API lookups or table queries.
* C (Conditional Logic with RAG/API/TABLE) : Although this approach works, it relies heavily on manual text parsing and might introduce complexity when scaling the system.
* D (System Prompt with Event Dates and Standings) : Hardcoding dates and table information into a system prompt isn't scalable. As the standings or events change, the system would need constant updating, making it inefficient.
By bundling multiple tools into a single agent-based system (as in option B), the Generative AI Engineer can best handle the diverse requirements of this system.
NEW QUESTION # 31
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error:
Python
from langchain.chains import LLMChain
from langchain_community.llms import OpenAI
from langchain_core.prompts import PromptTemplate
prompt_template = " Tell me a {adjective} joke "
prompt = PromptTemplate(input_variables=[ " adjective " ], template=prompt_template)
# ... (Error-prone section)
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: D
NEW QUESTION # 32
......
Valid Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate test dumps demo and latest test preparation for customer's success. Databricks offers latest Databricks Certified Generative AI Engineer Associate exam and valid practice questions book to help you pass the Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate Exam in your field. The Databricks Certified Generative AI Engineer Associate exam is 365 days updates and true. New Databricks-Generative-AI-Engineer-Associate study questions pdf in less time. And Databricks Certified Generative AI Engineer Associate Databricks-Generative-AI-Engineer-Associate price is benefit!
Databricks-Generative-AI-Engineer-Associate Test Voucher: https://www.certkingdompdf.com/Databricks-Generative-AI-Engineer-Associate-latest-certkingdom-dumps.html
BONUS!!! Download part of CertkingdomPDF Databricks-Generative-AI-Engineer-Associate dumps for free: https://drive.google.com/open?id=19-xoL1TjGQtvnyGXhJiZ4ZLF5BJcKO8y