Übrigens, Sie können die vollständige Version der DeutschPrüfung Data-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1Yt0BFUVg1b11ckG8dWy_F7rfD_ItQYVI
Es ist uns allen klar, dass das Hauptproblem in der IT-Branche ein Mangel an Qualität und Funktionalität ist. DeutschPrüfung stellt Ihnen alle notwendigen Schulungsunterlagen zur Amazon Data-Engineer-Associate Prüfung zur Verfügung. Ähnlich wie die reale Zertifizietungsprüfung verhelfen die Multiple-Choice-Fragen Ihnen zum Bestehen der Prüfung. Die Amazon Data-Engineer-Associate Prüfung Schulungsunterlagen von DeutschPrüfung sind überprüfte Prüfungsmaterialien. Alle diesen Fragen und Antworten zeigen unsere praktische Erfahrungen und Spezialisierung.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Data Store Management | 26% | - Optimize storage performance and cost - Select appropriate data storage solutions |
| Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
| Data Security and Governance | 18% | - Apply governance and compliance best practices - Implement data security controls |
>> Data-Engineer-Associate Fragenpool <<
Die Feedbacks von den IT-Kandidaten, die die schulungsunterlagen zur Amazon Data-Engineer-Associate (AWS Certified Data Engineer - Associate (DEA-C01)) IT-Prüfung von DeutschPrüfung benutzt haben, haben sich bewiesen, dass es leicht ist, die Prüfung mit Hilfe unserer DeutschPrüfung Produkten zu bestehen. Zur Zeit hat DeutschPrüfung die Schulungsprogramme zur beliebten Amazon Data-Engineer-Associate (AWS Certified Data Engineer - Associate (DEA-C01)) Zertifizierungsprüfung, die zielgerichteten Prüfungen beinhalten, entwickelt, um Ihr Know-How zu konsolidieren und sich gut auf die Prüfung vorzubereiten.
16. Frage
A university is developing an educational application that analyzes student essays. The application provides personalized feedback with accurate citations to the university ' s textbooks. The application needs to process essays in multiple languages. Application responses must include direct references to specific sections in the course materials and must be in the student ' s selected language.
Which solution will meet these requirements with the LEAST operational overhead?
Antwort: D
Begründung:
Option B is correct because Amazon Bedrock Knowledge Bases is the managed AWS service for retrieval- augmented generation using an organization's own content. AWS states that the RetrieveAndGenerate flow queries a knowledge base, generates responses based on retrieved results, and that the response includes citations only for relevant sources. AWS user guide pages also state that Knowledge Bases can return natural- language responses based on retrieved chunks from source documents. This directly fits the requirement for feedback with direct references to textbook sections.
This is also the least operational overhead choice because Amazon Bedrock manages ingestion, chunking, embedding, retrieval, and generation workflow components. Option A would require building and operating a custom vector solution. Option C adds multiple services and custom glue logic. Option D requires custom model hosting and fine-tuning, which is far more operationally heavy. For multilingual processing, Amazon Bedrock supports multilingual-capable models and multilingual embedding options, making it suitable for responses in the student's selected language when paired with an appropriate model.
17. Frage
A company ingests data from multiple data sources and stores the data in an Amazon S3 bucket. An AWS Glue extract, transform, and load (ETL) job transforms the data and writes the transformed data to an Amazon S3 based data lake. The company uses Amazon Athena to query the data that is in the data lake.
The company needs to identify matching records even when the records do not have a common unique identifier.
Which solution will meet this requirement?
Antwort: B
Begründung:
FindMatches is a transform available in AWS Lake Formation that uses ML to discover duplicate records or related records that might not have a common unique identifier.
It can be integrated into an AWS Glue ETL job to perform deduplication or matching tasks.
FindMatches is highly effective in scenarios where records do not share a key, such as customer records from different sources that need to be merged or reconciled.
Explanation:
The problem described requires identifying matching records even when there is no unique identifier. AWS Lake Formation FindMatches is designed for this purpose. It uses machine learning (ML) to deduplicate and find matching records in datasets that do not share a common identifier.
Reference:
Alternatives Considered:
A (Amazon Made pattern matching): Amazon Made is not a service in AWS, and pattern matching typically refers to regular expressions, which are not suitable for deduplication without a common identifier.
B (AWS Glue PySpark Filter class): PySpark's Filter class can help refine datasets, but it does not offer the ML-based matching capabilities required to find matches between records without unique identifiers.
C (Partition tables on a unique identifier): Partitioning requires a unique identifier, which the question states is unavailable.
AWS Glue Documentation on Lake Formation FindMatches
FindMatches in AWS Lake Formation
18. Frage
A company wants to migrate data from an Amazon RDS for PostgreSQL DB instance in the eu-east-1 Region of an AWS account named Account_A. The company will migrate the data to an Amazon Redshift cluster in the eu-west-1 Region of an AWS account named Account_B.
Which solution will give AWS Database Migration Service (AWS DMS) the ability to replicate data between two data stores?
Antwort: C
Begründung:
Option A is the best answer because AWS DMS documentation recommends that, when practical, you create the replication instance in the same Region as your target endpoint, and in the same VPC or subnet as your target endpoint. In this scenario, the target is the Amazon Redshift cluster in eu-west-1 in Account_B, so placing the replication instance there is the most appropriate design. AWS DMS uses the replication instance to connect to the source, read the source data, transform it as needed, and load it into the target.
This also makes architectural sense because the replication instance must have network connectivity to both endpoints, and colocating it with the Redshift target usually simplifies connectivity to the target warehouse and aligns with AWS guidance. A replication instance in Account_B, eu-west-1 can still connect to the PostgreSQL source in Account_A, eu-east-1, provided the required networking and permissions are configured. AWS DMS supports replication tasks by defining a replication instance plus source and target endpoints.
The study guide also identifies AWS DMS as the correct managed service for database migration and continuous replication scenarios, including full load and change data capture. That matches this cross-account, cross-Region migration use case.
19. Frage
A manufacturing company collects sensor data from its factory floor to monitor and enhance operational efficiency. The company uses Amazon Kinesis Data Streams to publish the data that the sensors collect to a data stream. Then Amazon Kinesis Data Firehose writes the data to an Amazon S3 bucket.
The company needs to display a real-time view of operational efficiency on a large screen in the manufacturing facility.
Which solution will meet these requirements with the LOWEST latency?
Antwort: C
Begründung:
This solution will meet the requirements with the lowest latency because it uses Amazon Managed Service for Apache Flink to process the sensor data in real time and write it to Amazon Timestream, a fast, scalable, and serverless time series database. Amazon Timestream is optimized for storing and analyzing time series data, such as sensor data, and can handle trillions of events per day with millisecond latency. By using Amazon Timestream as a source, you can create an Amazon QuickSight dashboard that displays a real-time view of operational efficiency on a large screen in the manufacturing facility. Amazon QuickSight is a fully managed business intelligence service that can connect to various data sources, including Amazon Timestream, and provide interactive visualizations and insights123.
The other options are not optimal for the following reasons:
* A. Use Amazon Managed Service for Apache Flink (previously known as Amazon Kinesis Data Analytics) to process the sensor data. Use a connector for Apache Flink to write data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard. This option is similar to option C, but it uses Grafana instead of Amazon QuickSight to create the dashboard.
Grafana is an open source visualization tool that can also connect to Amazon Timestream, but it requires additional steps to set up and configure, such as deploying a Grafana server on Amazon EC2, installing the Amazon Timestream plugin, and creating an IAM role for Grafana to access Timestream.
These steps can increase the latency and complexity of the solution.
* B. Configure the S3 bucket to send a notification to an AWS Lambda function when any new object is created. Use the Lambda function to publish the data to Amazon Aurora. Use Aurora as a source to create an Amazon QuickSight dashboard. This option is not suitable for displaying a real-time view of operational efficiency, as it introduces unnecessary delays and costs in the data pipeline. First, the sensor data is written to an S3 bucket by Amazon Kinesis Data Firehose, which can have a buffering interval of up to 900 seconds. Then, the S3 bucket sends a notification to a Lambda function, which can incur additional invocation and execution time. Finally, the Lambda function publishes the data to Amazon Aurora, a relational database that is not optimized for time series data and can have higher storage and performance costs than Amazon Timestream .
* D. Use AWS Glue bookmarks to read sensor data from the S3 bucket in real time. Publish the data to an Amazon Timestream database. Use the Timestream database as a source to create a Grafana dashboard.
This option is also not suitable for displaying a real-time view of operational efficiency, as it uses AWS Glue bookmarks to read sensor data from the S3 bucket. AWS Glue bookmarks are a feature that helps AWS Glue jobs and crawlers keep track of the data that has already been processed, so that they can resume from where they left off. However, AWS Glue jobs and crawlers are not designed for real-time data processing, as they can have a minimum frequency of 5 minutes and a variable start-up time.
Moreover, this option also uses Grafana instead of Amazon QuickSight to create the dashboard, which can increase the latency and complexity of the solution .
References:
* 1: Amazon Managed Streaming for Apache Flink
* 2: Amazon Timestream
* 3: Amazon QuickSight
* : Analyze data in Amazon Timestream using Grafana
* : Amazon Kinesis Data Firehose
* : Amazon Aurora
* : AWS Glue Bookmarks
* : AWS Glue Job and Crawler Scheduling
20. Frage
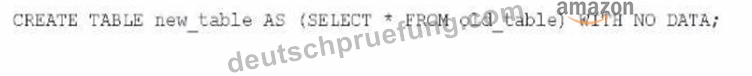
A data engineer needs to create a new empty table in Amazon Athena that has the same schema as an existing table named old-table.
Which SQL statement should the data engineer use to meet this requirement?



Antwort: B
Begründung:
Problem Analysis:
The goal is to create a new empty table in Athena with the same schema as an existing table (old_table).
The solution must avoid copying any data.
Key Considerations:
CREATE TABLE AS (CTAS) is commonly used in Athena for creating new tables based on an existing table.
Adding the WITH NO DATA clause ensures only the schema is copied, without transferring any data.
Solution Analysis:
Option A: Copies both schema and data. Does not meet the requirement for an empty table.
Option B: Inserts data into an existing table, which does not create a new table.
Option C: Creates an empty table but does not copy the schema.
Option D: Creates a new table with the same schema and ensures it is empty by using WITH NO DATA.
Final Recommendation:
Use D. CREATE TABLE new_table AS (SELECT * FROM old_table) WITH NO DATA to create an empty table with the same schema.
Athena CTAS Queries
CREATE TABLE Statement in Athena
21. Frage
......
In den letzten Jahren hat die Amazon Data-Engineer-Associate Zertifizierungsprüfung großen Einfluß aufs Alltagsleben geübt. Aber die Kernfrage ist, wie man die Amazon Data-Engineer-Associate Zertifizierungsprüfung einmalig bestehen. Die Antwort ist, dass Sie die Schulungsunterlagen zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von DeutschPrüfung benutzen sollen. Mit DeutschPrüfung können Sie Ihre erste Zertifizierungsprüfung bestehen. Worauf warten Sie noch?Kaufen Sie die Schulungsunterlagen zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von DeutschPrüfung, Sie werden sicher mehr bekommen, was Sie wünschen.
Data-Engineer-Associate Zertifikatsfragen: https://www.deutschpruefung.com/Data-Engineer-Associate-deutsch-pruefungsfragen.html
Übrigens, Sie können die vollständige Version der DeutschPrüfung Data-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1Yt0BFUVg1b11ckG8dWy_F7rfD_ItQYVI