Kostenlose gültige Prüfung Databricks Certified-Data-Engineer-Professional Sammlung - Examcollection

Mit DeutschPrüfung können Sie sich nicht nur wertvolle Zeit ersparen, sondern auch sich ganz beruhigt auf die Prüfung vorbereiten und sie erfolgreich bestehen. DeutschPrüfung hat eine gute Zuverlässigkeit und ein hohes Ansehen in der IT-Branche. Sie können kostenlos einen Teil der von DeutschPrüfung gebotene Databricks Certified-Data-Engineer-Professional Prüfungsfragen und Antworten als Probe herunterladen, um die Zuverlässigkeit unserer Produkte zu testen. Sie werden sicher mit unserern Produkten sehr zufrieden sein. Ich habe Vertrauen in unsere Produkte und glaube, dass die von DeutschPrüfung bietenden Prüfungsfragen und Antworten zu Databricks Certified-Data-Engineer-Professional Zertifizierung bald Ihre beste Wahl sein würden. Und sie würden sicher die Certified-Data-Engineer-Professional Zertifizierungsprüfung erfolgreich abschließen. Es ist ratsam, DeutschPrüfung zu wählen. DeutschPrüfung würde Ihnen die zufriedenen Produkte bieten.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Query Profile and Spark UI to monitor workloads
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Topic 2: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Create pipeline components using control flow operators such as if/else and foreach
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
| Topic 4: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 5: Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Topic 8: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 10: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
>> Certified-Data-Engineer-Professional Praxisprüfung <<
Databricks Certified-Data-Engineer-Professional Prüfung Übungen und Antworten
Die Qualität muss sich bawähren, was die Databricks Certified-Data-Engineer-Professional von uns DeutschPrüfung Ihnen genau garantieren können, weil wir immer die Test-Bank aktualisieren. Die fachliche Erklärungen der Antworten von unserer professionellen Gruppe machen unsere Produkte der Schlüssel des Bestehens der Databricks Certified-Data-Engineer-Professional. Die Versprechung „volle Rückerstattung bei der Durchfall„ ist auch Motivation für unser Team. Wir wollen für Sie die Prüfungsunterlagen der Databricks Certified-Data-Engineer-Professional immer verbessern. Innerhalb einem Jahr nach Ihrem Kauf, können Sie die neuesten Unterlagen der Databricks Certified-Data-Engineer-Professional weiter genießen ohne zusätzliche Gebühren.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q64-Q69):
64. Frage
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
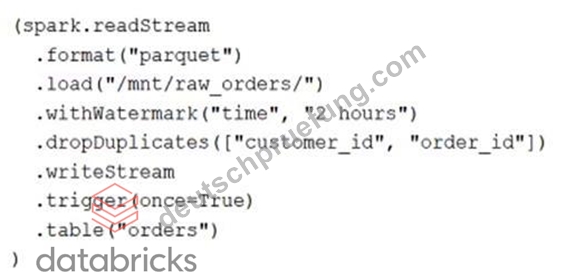
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
- B. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- C. Duplicate records arriving more than 2 hours apart will be dropped, but duplicates that arrive in the same batch may both be written to the orders table.
- D. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- E. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
Antwort: B
65. Frage
The data engineering team has configured a job to process customer requests to be forgotten (have their data deleted). All user data that needs to be deleted is stored in Delta Lake tables using default table settings.
The team has decided to process all deletions from the previous week as a batch job at 1am each Sunday. The total duration of this job is less than one hour. Every Monday at 3am, a batch job executes a series of VACUUM commands on all Delta Lake tables throughout the organization.
The compliance officer has recently learned about Delta Lake's time travel functionality. They are concerned that this might allow continued access to deleted data.
Assuming all delete logic is correctly implemented, which statement correctly addresses this concern?
- A. Because the default data retention threshold is 7 days, data files containing deleted records will be retained until the vacuum job is run 8 days later.
- B. Because the default data retention threshold is 24 hours, data files containing deleted records will be retained until the vacuum job is run the following day.
- C. Because Delta Lake time travel provides full access to the entire history of a table, deleted records can always be recreated by users with full admin privileges.
- D. Because Delta Lake's delete statements have ACID guarantees, deleted records will be permanently purged from all storage systems as soon as a delete job completes.
- E. Because the vacuum command permanently deletes all files containing deleted records, deleted records may be accessible with time travel for around 24 hours.
Antwort: A
Begründung:
https://learn.microsoft.com/en-us/azure/databricks/delta/vacuum
66. Frage
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
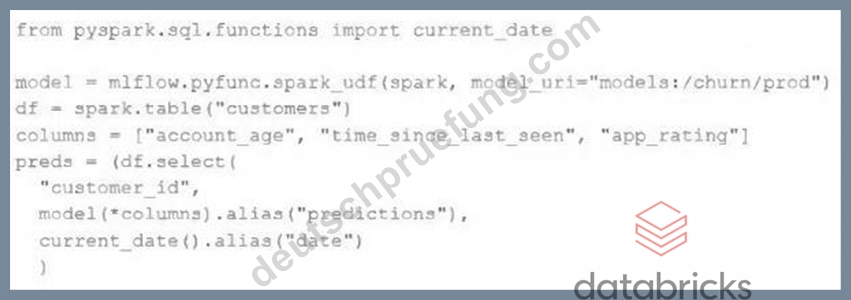
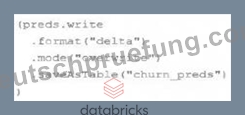
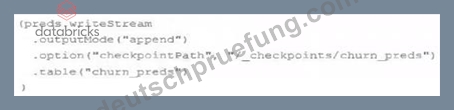
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A.
- B.
- C.
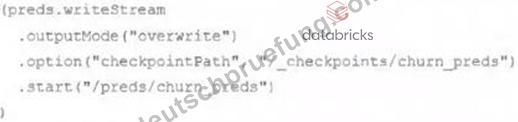
- D. preds.write.mode("append").saveAsTable("churn_preds")
- E. preds.write.format("delta").save("/preds/churn_preds")
Antwort: D
67. Frage
A streaming video analytics team ingests billions of events daily into a Unity Catalog-managed Delta table video_events. Analysts run ad-hoc point-lookup queries on columns like user_id, campaign_id, and region. The team manually runs OPTIMIZE video_events ZORDER BY (user_id, campaign_id, region), but still sees poor performance on recent data and dislikes the operational overhead. The team wants a hands-off way to keep hot columns co-located as query patterns evolve. Which Delta capability should the team leverage on video_events?
- A. Utilize Liquid Clustering (CLUSTER BY AUTO) and Predictive Optimization.
- B. Enable Delta caching.
- C. Enable auto-compaction (optimizeWrite and autoCompact).
- D. Schedule OPTIMIZE/ZORDER to run after each job to improve recent file performance.
Antwort: A
Begründung:
According to Databricks Delta Lake optimization documentation, Liquid Clustering is a next- generation file organization capability that automatically manages file co-location without requiring explicit partitioning or manual Z-ORDERing. When combined with Predictive Optimization, Databricks automatically maintains clustering across frequently filtered or queried columns, adapting dynamically as query workloads evolve.
This approach eliminates the need for manual maintenance (such as periodic OPTIMIZE or Z- ORDER commands) while improving query performance on large tables--particularly for high- ingest streaming workloads.
Delta caching (B) only improves performance for cached queries and does not address file layout issues, and (D) handles file size optimization but not clustering. Thus, C is the most efficient, modern, and low-maintenance solution recommended by Databricks.
68. Frage
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source. Which action should the team take?
- A. Repair the run with the new parameter.
- B. Share the analysis with the failing notebook owner so that they can fix it quickly.
- C. Update the task by adding the missing task parameter, and manually run the job.
- D. Repair the run with the new parameter, and update the task by adding the missing task parameter.
Antwort: D
Begründung:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
69. Frage
......
Sind Sie ein IT-Mann? Haben Sie sich an der populären IT-Zertifizirungsprüfung beteiligt? Wenn ja, würde ich Ihnen sagen, dass Sie wirklich glücklich sind. Unsere Schulungsunterlagen zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung von DeutschPrüfung werden Ihnen helfen, die Databricks Certified-Data-Engineer-Professional Prüfung 100% zu bestehen. Das ist eine echte Nachricht. Wollen Sie Fortschritte in der IT-Branche machen, wählen Sie doch DeutschPrüfung. Unsere Databricks Certified-Data-Engineer-Professional Dumps können Ihnen zum Bestehen allen Zertifizierungsprüfungen verhelfen. Sie sind außerdem billig. Wenn Sie nicht glauben, gucken Sie mal und Sie werden das Wissen.
Certified-Data-Engineer-Professional Lernressourcen: https://www.deutschpruefung.com/Certified-Data-Engineer-Professional-deutsch-pruefungsfragen.html
- Certified-Data-Engineer-Professional Fragen&Antworten 🕛 Certified-Data-Engineer-Professional Übungsmaterialien 🍠 Certified-Data-Engineer-Professional Antworten 🕍 Sie müssen nur zu { www.zertfragen.com } gehen um nach kostenloser Download von { Certified-Data-Engineer-Professional } zu suchen 🦜Certified-Data-Engineer-Professional Fragen&Antworten
- Certified-Data-Engineer-Professional Dumps Deutsch 😮 Certified-Data-Engineer-Professional Testengine ⏮ Certified-Data-Engineer-Professional Übungsmaterialien 🍫 Geben Sie ⏩ www.itzert.com ⏪ ein und suchen Sie nach kostenloser Download von ➽ Certified-Data-Engineer-Professional 🢪 🚓Certified-Data-Engineer-Professional Online Test
- Certified-Data-Engineer-Professional Antworten ⬅ Certified-Data-Engineer-Professional Deutsche Prüfungsfragen 📉 Certified-Data-Engineer-Professional Zertifizierungsprüfung 🎠 Suchen Sie einfach auf ➤ www.echtefrage.top ⮘ nach kostenloser Download von ➡ Certified-Data-Engineer-Professional ️⬅️ 🖖Certified-Data-Engineer-Professional Prüfungsmaterialien
- Certified-Data-Engineer-Professional Dumps Deutsch 🕖 Certified-Data-Engineer-Professional Prüfungsvorbereitung 🏧 Certified-Data-Engineer-Professional Prüfungsfrage 🎳 Geben Sie [ www.itzert.com ] ein und suchen Sie nach kostenloser Download von 《 Certified-Data-Engineer-Professional 》 🔳Certified-Data-Engineer-Professional Demotesten
- Die seit kurzem aktuellsten Databricks Certified-Data-Engineer-Professional Prüfungsunterlagen, 100% Garantie für Ihen Erfolg in der Databricks Certified Data Engineer Professional Prüfungen! 🤼 ➠ www.deutschpruefung.com 🠰 ist die beste Webseite um den kostenlosen Download von ▷ Certified-Data-Engineer-Professional ◁ zu erhalten 🍖Certified-Data-Engineer-Professional Prüfungsmaterialien
- Certified-Data-Engineer-Professional Schulungsmaterialien - Certified-Data-Engineer-Professional Dumps Prüfung - Certified-Data-Engineer-Professional Studienguide 🎼 Sie müssen nur zu ➠ www.itzert.com 🠰 gehen um nach kostenloser Download von [ Certified-Data-Engineer-Professional ] zu suchen 🏕Certified-Data-Engineer-Professional Prüfungsfrage
- Kostenlose Databricks Certified Data Engineer Professional vce dumps - neueste Certified-Data-Engineer-Professional examcollection Dumps 🦺 Suchen Sie jetzt auf 【 de.fast2test.com 】 nach ☀ Certified-Data-Engineer-Professional ️☀️ und laden Sie es kostenlos herunter 🍄Certified-Data-Engineer-Professional Fragenkatalog
- Kostenlos Certified-Data-Engineer-Professional Dumps Torrent - Certified-Data-Engineer-Professional exams4sure pdf - Databricks Certified-Data-Engineer-Professional pdf vce 🤽 Suchen Sie auf der Webseite [ www.itzert.com ] nach ➤ Certified-Data-Engineer-Professional ⮘ und laden Sie es kostenlos herunter 🚰Certified-Data-Engineer-Professional Fragen&Antworten
- Certified-Data-Engineer-Professional Trainingsmaterialien: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Lernmittel - Databricks Certified-Data-Engineer-Professional Quiz 🐄 URL kopieren ➠ www.zertpruefung.ch 🠰 Öffnen und suchen Sie ➽ Certified-Data-Engineer-Professional 🢪 Kostenloser Download 💧Certified-Data-Engineer-Professional Dumps Deutsch
- Certified-Data-Engineer-Professional Dumps Deutsch 🏣 Certified-Data-Engineer-Professional Zertifizierungsprüfung 🪁 Certified-Data-Engineer-Professional Zertifizierungsantworten 🤙 Suchen Sie auf ➡ www.itzert.com ️⬅️ nach kostenlosem Download von [ Certified-Data-Engineer-Professional ] 🔊Certified-Data-Engineer-Professional PDF Demo
- Certified-Data-Engineer-Professional Vorbereitungsfragen 🌈 Certified-Data-Engineer-Professional Demotesten 🪓 Certified-Data-Engineer-Professional Prüfungsmaterialien 🥚 Suchen Sie auf 「 www.pass4test.de 」 nach ➽ Certified-Data-Engineer-Professional 🢪 und erhalten Sie den kostenlosen Download mühelos ♥Certified-Data-Engineer-Professional Examsfragen
- dorahacks.io, www.notebook.ai, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes