The TorrentValid is committed from the day first to ace the Developing AI-Enabled Database Solutions (DP-800) exam questions preparation at any cost. To achieve this objective TorrentValid has hired a team of experienced and qualified DP-800 certification exam experts. They utilize all their expertise to offer top-notch Developing AI-Enabled Database Solutions (DP-800) exam dumps. These Microsoft DP-800 exam questions are being offered in three different but easy-to-use formats.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
The Developing AI-Enabled Database Solutions (DP-800) questions are in use by many customers currently, and they are preparing for their best future daily. Even the students who used it in the past to prepare for the Microsoft Certification Exam have rated our practice questions as one of the best. You will receive updates till 365 days after your purchase, and there is a 24/7 support system that assists you whenever you are stuck in any problem or issues.
NEW QUESTION # 32
You have an Azure AI Search service and an index named hotels that includes a vector field named DescriptionVector.
You query hotels by using the Search Documents REST API.
You need to implement a hybrid search query that uses DescriptionVector and includes captions.
How should you complete the REST request body? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.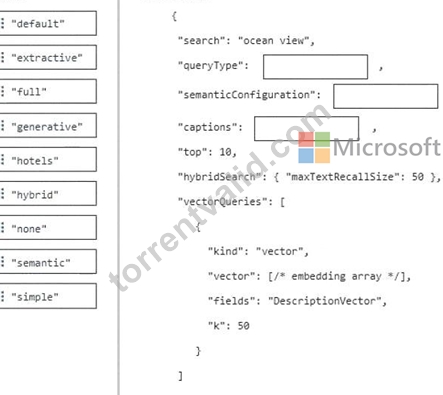
Answer:
Explanation: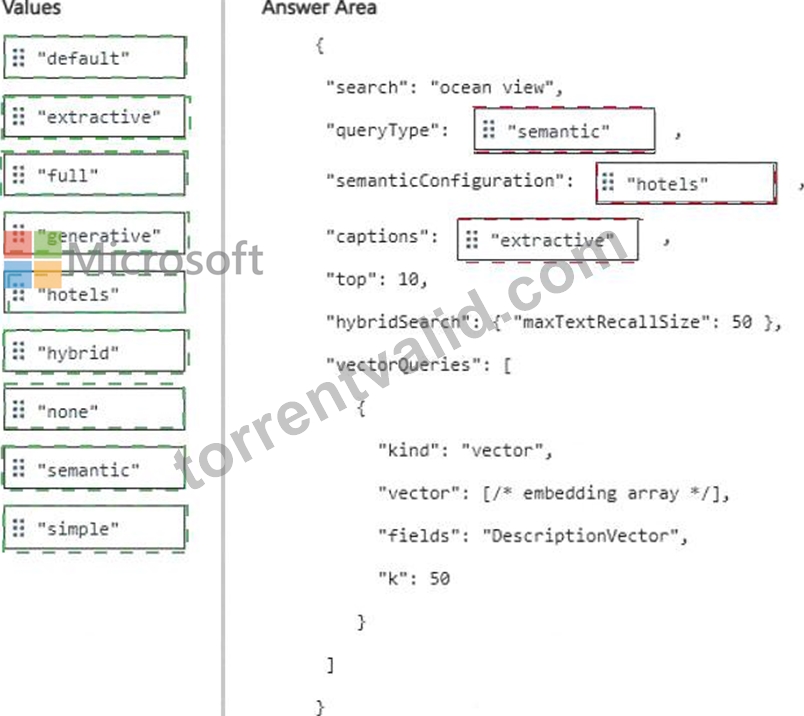
Explanation:
Verified Answer : =
* queryType # " semantic "
* semanticConfiguration # " hotels "
* captions # " extractive "
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The correct configuration is queryType: " semantic " , semanticConfiguration: " hotels " , and captions: " extractive " .
The request is already a hybrid search because it contains both a textual search value ( " ocean view " ) and a vectorQueries block targeting DescriptionVector . Microsoft documents that hybrid search executes full-text and vector searches together and merges their result sets. When semantic ranking is required, queryType must be set to " semantic " .
The semanticConfiguration value must reference the semantic configuration defined for the target index.
Since the index in this question is named hotels and the available answer choice is " hotels " , that is the appropriate configuration value in the supplied answer set. Microsoft's REST examples show that semantic queries require both queryType: " semantic " and a valid semanticConfiguration .
To return semantic captions, use " captions " : " extractive " . Microsoft states that extractive captions identify the most relevant passages from the indexed content and return them with each result. They are generated from existing document text rather than generated by an LLM.
The completed request body is therefore:
{
" search " : " ocean view " ,
" queryType " : " semantic " ,
" semanticConfiguration " : " hotels " ,
" captions " : " extractive " ,
" top " : 10,
" hybridSearch " : {
" maxTextRecallSize " : 50
},
" vectorQueries " : [
{
" kind " : " vector " ,
" vector " : [ /* embedding array */ ],
" fields " : " DescriptionVector " ,
" k " : 50
}
]
}
Final drag-and-drop selections:
* First target: " semantic "
* Second target: " hotels "
* Third target: " extractive "
NEW QUESTION # 33
You have an Azure SQL database that supports a customer-facing API. The API calls a stored procedure named dbo.GetCustomerOrders thousands of times per hour.
After a deployment that updated indexes and statistics, users report that the API endpoint backed by dbo.GetCustomerOrders is slower. In Query Store, the same query now has two persisted execution plans. During the last hour, the newer plan had a significantly higher average duration and CPU time than the older plan.
You need to restore the previous performance quickly, without changing the API code.
Which Transact-SQL command should you run?
Answer: B
Explanation:
We have encountered plan regression. This often happens after maintenance (like updating statistics) because the query optimizer generates a new execution plan that it thinks is better based on the new data distribution, but it ends up being less efficient in practice.
Since you've already identified the Plan ID for the faster plan and the Query ID from Query Store, you can force the "good" plan immediately using:
EXEC sp_query_store_force_plan @query_id = [YourQueryID], @plan_id = [YourFastPlanID]; Use code with caution.
This tells Azure SQL to ignore the new, slower plan and stick to the one that worked, providing an almost instant fix for your API's performance without requiring a code deployment.
Reference:
https://daxsws.com/blog/real-world-dynamics-365-performance-tuning-scenarios-and-fixes
NEW QUESTION # 34
You have a Microsoft SQL Server 2025 instance that has a managed identity enabled.
You have a database that contains a table named dbo.ManualChunks. dbo.ManualChunks contains product manuals.
A retrieval query already returns the top five matching chunks as nvarchar(max) text.
You need to call an Azure OpenAI REST endpoint for chat completions. The solution must provide the highest level of security.
You write the following Transact-SG1 code.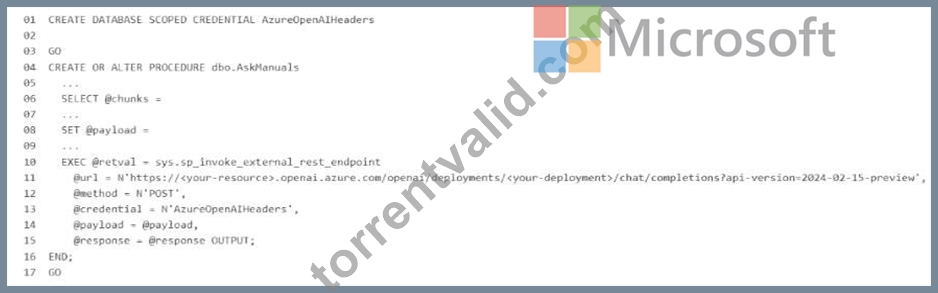
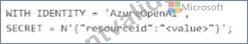
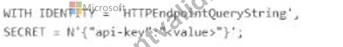
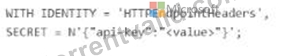
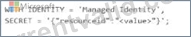
What should you insert at line 02?
Answer: E
Explanation:
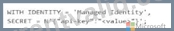
The correct answer is Option B because the requirement is to call an Azure OpenAI REST endpoint from SQL Server 2025 while providing the highest level of security , and the instance already has a managed identity enabled . For Microsoft's SQL AI features, the preferred secure pattern is to use a database scoped credential with IDENTITY = ' Managed Identity ' instead of storing an API key. Microsoft documents that SQL Server 2025 supports managed identity for external AI endpoints, and for Azure OpenAI the credential secret uses the Cognitive Services resource identifier: { " resourceid " : " https://cognitiveservices.azure.
com " } .
So line 02 should be:
WITH IDENTITY = ' Managed Identity ' ,
SECRET = ' { " resourceid " : " https://cognitiveservices.azure.com " } ' ; Why the other options are incorrect:
* A and D use HTTP header or query-string credentials with an API key , which is less secure than managed identity because a secret key must be stored and rotated manually. Microsoft recommends managed identity where supported to avoid embedded secrets.
* C mixes Managed Identity with an api-key secret, which is not the correct pattern for Azure OpenAI managed-identity authentication.
* E uses an invalid identity value for this scenario. The accepted credential identities for external REST endpoint calls include HTTPEndpointHeaders , HTTPEndpointQueryString , Managed Identity , and Shared Access Signature .
Because the endpoint is Azure OpenAI and the question explicitly asks for the highest security , managed identity with the Cognitive Services resource ID is the Microsoft-aligned answer.
NEW QUESTION # 35
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.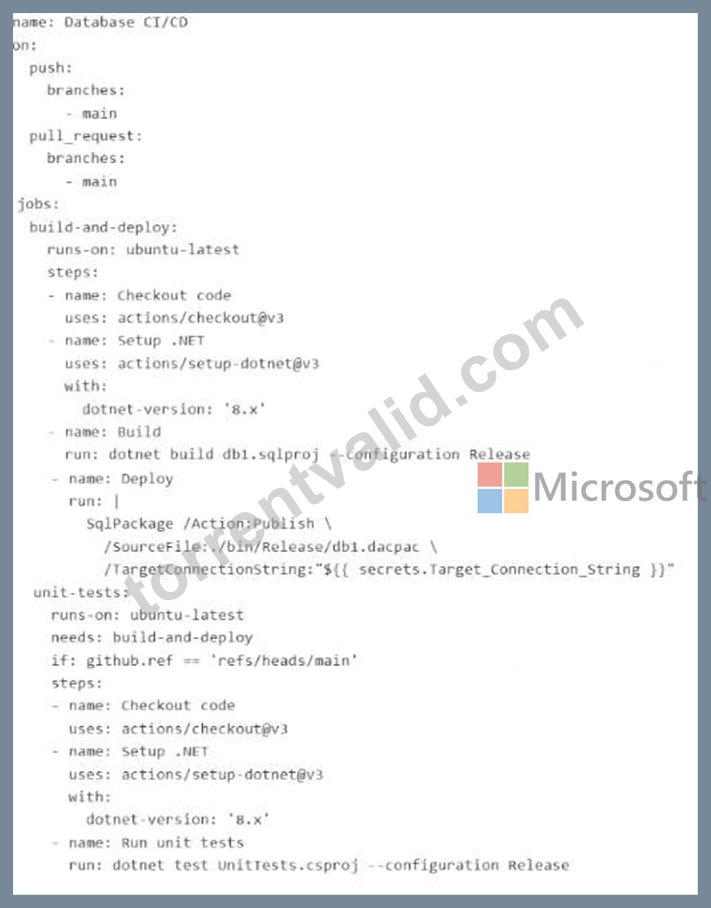
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.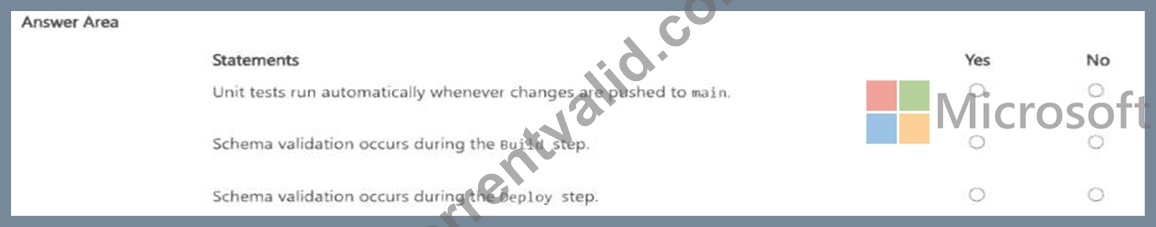
Answer:
Explanation: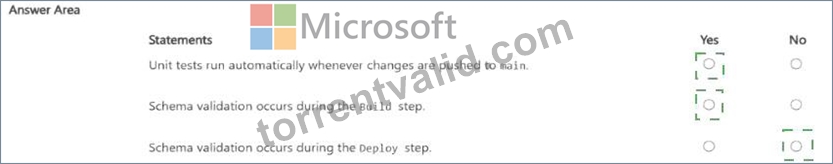
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
NEW QUESTION # 36
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.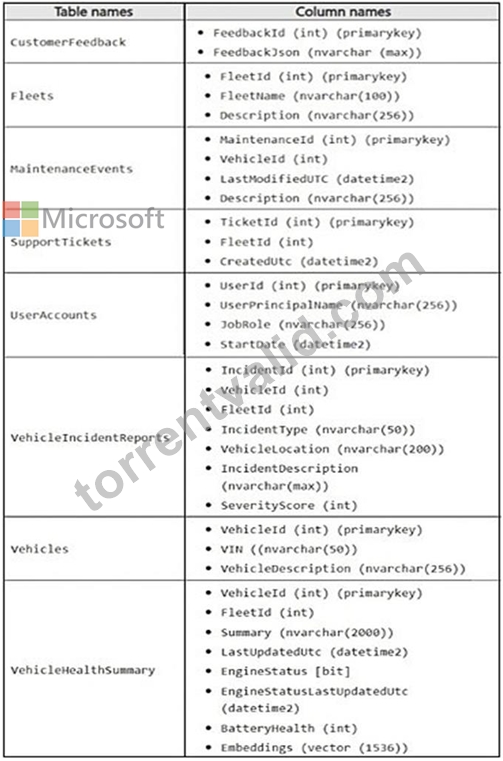
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.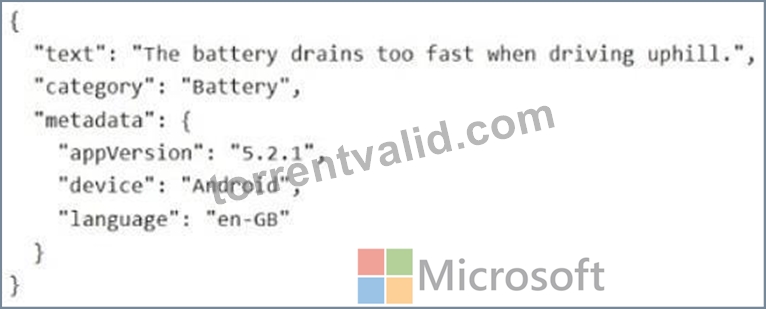
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.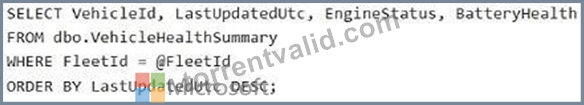
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to recommend a solution for the development team to retrieve the live metadata. The solution must meet the development requirements. What should you include in the recommendation?
Answer: B
Explanation:
Scenario: Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
To retrieve live metadata from Azure SQL databases and use it with GitHub Copilot in Visual Studio Code (VS Code), you must use the SQL Server (mssql) extension. This extension provides the native capability to extract a database schema as a .dacpac file directly within the editor.
1. Export the Schema as a .dacpac File
You can extract the schema of your live Azure SQL database using the SQL Server (mssql) extension.
2. Load the .dacpac into GitHub Copilot Context
Once the .dacpac file is saved in your VS Code workspace, you can provide it as context to GitHub Copilot Chat using #-mentions or Drag & Drop.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/data-tier- applications/extract-dacpac-from-database
NEW QUESTION # 37
......
Select our excellent DP-800 training questions, you will not regret it. According to the above introduction, you must have your own judgment. Quickly purchase our DP-800 study materials we will certainly help you improve your competitiveness with the help of our DP-800 simulating exam! Just image that you will have a lot of the opportunities to be employed by bigger and better company, and you will get a better position and a higher income. What are you waiting for? Just buy our exam braindumps!
DP-800 Test Answers: https://www.torrentvalid.com/DP-800-valid-braindumps-torrent.html