Choosing valid Microsoft dumps means closer to success. Before you buy our products, you can download the free demo of AI-500 test questions to check the accuracy of our dumps. Besides, there are 24/7 customer assisting to support you in case you may have any questions about AI-500 Dumps PDF or download link.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Topic 2: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Topic 3: Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
| Topic 4: Architect multi-agent solutions | 15–20% | - Design workflow and tool integration
|
Investing in a Designing and Implementing Multi-Agent AI Solutions (AI-500) certification is essential for professionals looking to advance their careers and stay competitive in the job market. With our actual Microsoft AI-500 questions PDF, AI-500 practice exams along with the support of our customer support team, you can be confident that you are getting the best possible AI-500 Preparation material for the test. Download Real AI-500 questions today and start your journey to success.
NEW QUESTION # 37
You need to implement an advanced prompt engineering strategy to resolve the Patient Intake agent issues.
The solution must prevent hardcoding new logic into the agent ' s core prompt.
What should you do?
Answer: B
Explanation:
The intake problem involves verbose, variable patient narratives and a requirement to avoid hardcoding new logic into the core prompt. Injecting dynamic context with curated few-shot examples gives the model representative demonstrations of how to identify clinically relevant symptoms while ignoring irrelevant narrative details. Microsoft AI-500 objectives explicitly include examples and dynamic context injection as advanced prompt-engineering techniques. Removing defensive guidance would weaken safety. Reducing the context window would not teach the model what information matters and could simply discard useful details.
Frequent full-model fine-tuning is operationally heavier and unnecessary for a behavior that can be demonstrated through curated examples. Dynamic few-shot context also allows the examples to be versioned and updated without rewriting the agent ' s base persona or application logic. Therefore C best addresses the extraction problem while preserving prompt lifecycle flexibility. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: AI-500 Study Guide - advanced prompt engineering
NEW QUESTION # 38
You have a Microsoft Foundry Agent Service solution that includes two agents.
You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create a dedicated memory store for each agent and configure a static agent scope value for each memory search tool.
Does this meet the goal?
Answer: B
Explanation:
A separate memory store for each agent correctly isolates the two agent domains, but a static scope shared by every user inside each store does not isolate end users. Multiple users ' memories would be written and searched within the same logical scope. Microsoft Foundry Memory explicitly recommends a user-derived scope such as `{{$userId}}` when per-user isolation is required. Scope-based deletion is also how one user ' s memory can be removed without deleting other users ' memories. With a single static scope, that deletion boundary does not exist. The proposed design therefore solves only the domain part of the problem and fails both user isolation and safe per-user deletion. Since all requirements must be satisfied, the correct answer is B, No. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 39
You have a production-readiness review that includes the following Microsoft Foundry Agent Service Model Context Protocol (MCP) tool configuration, discovered MCP tool metadata, and quality-gate rules.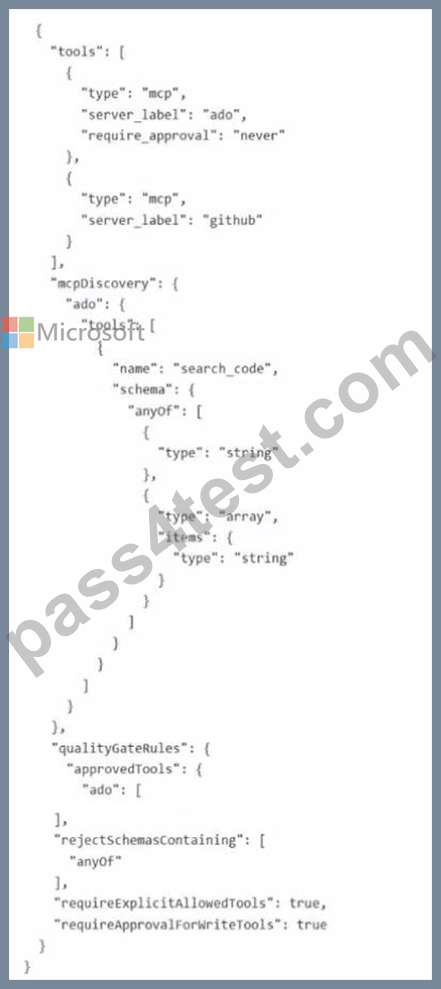
For each of the following statements, select Yes if the statement is true Otherwise, select No.
NOTE: Each correct selection is worth one point.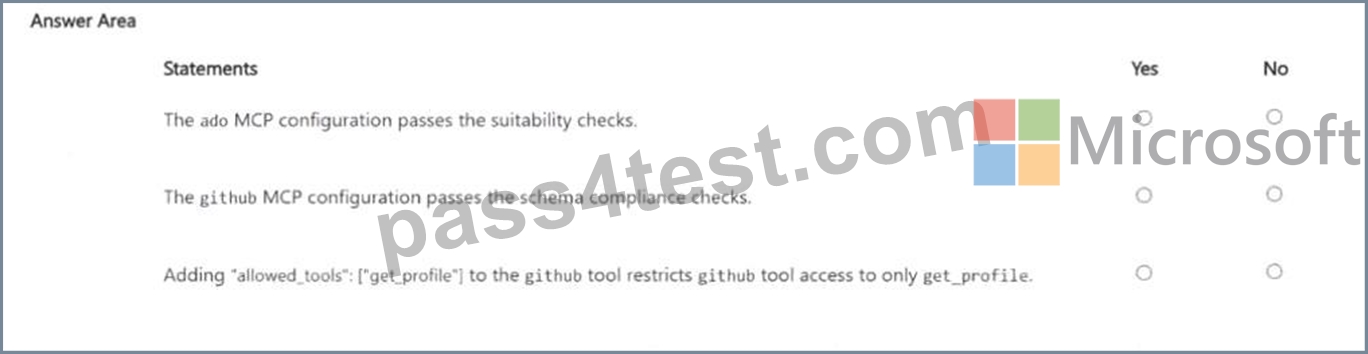
Answer:
Explanation: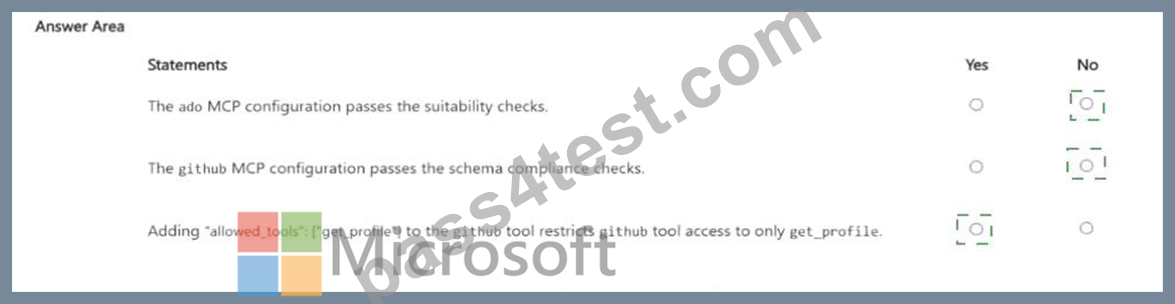
Explanation:
No / No / Yes
The ADO MCP configuration does not satisfy the stated production gate because it lacks the required allowed- tool restriction and disables approval; its discovered schema also conflicts with the gate ' s schema restrictions. The GitHub configuration likewise cannot be considered schema-compliant based on the shown metadata. The third statement, however, is true: Microsoft Foundry MCP tool configuration supports an
`allowed_tools` allowlist that limits which discovered MCP tools are exposed to the agent. Adding ` " allowed_tools " : [ " get_profile " ]` therefore restricts the GitHub MCP integration to that tool, assuming the name matches the discovered tool exactly. This control is materially stronger tha n relying on prompt instructions because excluded tools are not presented as available choices. The corrected sequence is No, No, Yes. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry agents - Model Context Protocol tools
NEW QUESTION # 40
You have a Microsoft Foundry multi-agent customer support solution that routes requests from an intake agent to a retrieval agent, and then to a resolution agent. A custom guardrail is assigned to the agents.
You discover that some legitimate support requests are blocked, and some injected instructions in retrieved documents are allowed.
You need to validate the updated guardrail. The solution must meet the following requirements:
* Identify false positives and false negatives.
* Verify policy coverage across the agent solution
* Prevent changing the production agent behavior during testing
* Measure intervention accuracy by using a control and intervention point.
What should you do?
Answer: A
Explanation:
The updated guardrail must be evaluated with known benign and adversarial cases so false positives and false negatives can be measured explicitly. Running labeled cases through every relevant workflow path also tests whether the guardrail is applied consistently at the intended intervention points. Microsoft AI-500 guidance includes guardrail testing with synthetic or curated data and emphasizes evaluation before production rollout.
Playground-only spot checks are too narrow to establish coverage. Switching production to annotate-only would change live behavior and use customers as the test population, violating the requirement to avoid production changes. A compliance configuration review verifies that a policy exists but does not measure whether it correctly detects or misses real inputs. Option B is therefore the only approach that produces repeatable evidence of intervention accuracy and policy coverage without changing production behavior. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: AI-500 Study Guide - guardrail testing and evaluation
NEW QUESTION # 41
You have a LangGraph workflow in Microsoft Foundry that is compiled as app by using a checkpointer. Each request includes a value named ticket_id.
You need to instrument the workflow so that each streamed run sends OpenTelemetry traces to Observability in Foundry. The solution must meet the following requirements:
* Correlate graph steps and tool calls for each request by the supplied ticket__id.
* Use the Azure Al OpenTelemetry tracer with the LangGraph invocation.
How should you complete the code? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.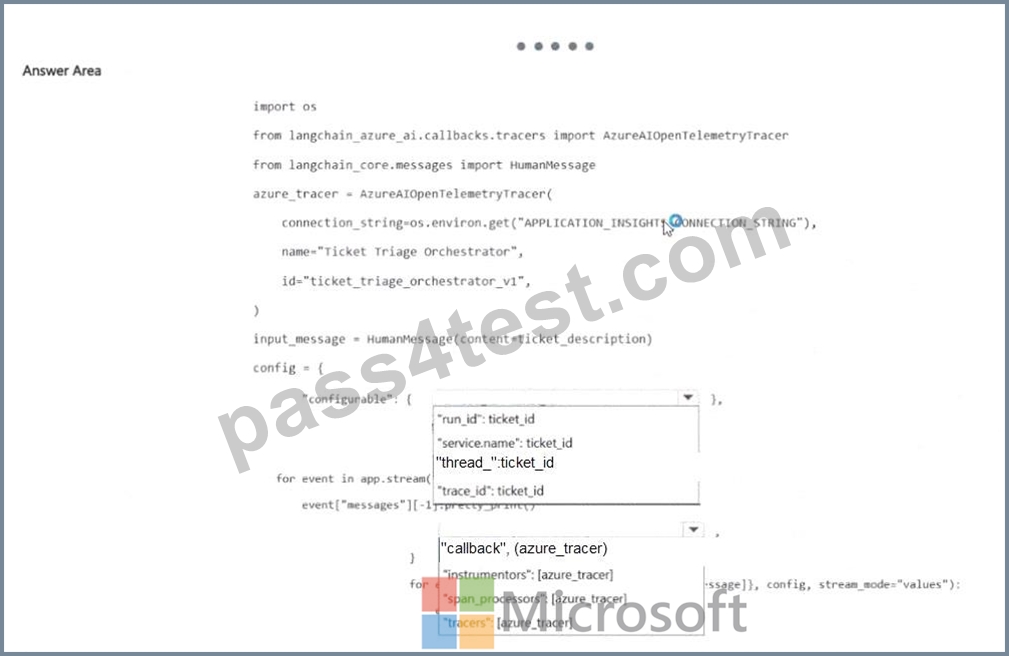
Answer:
Explanation: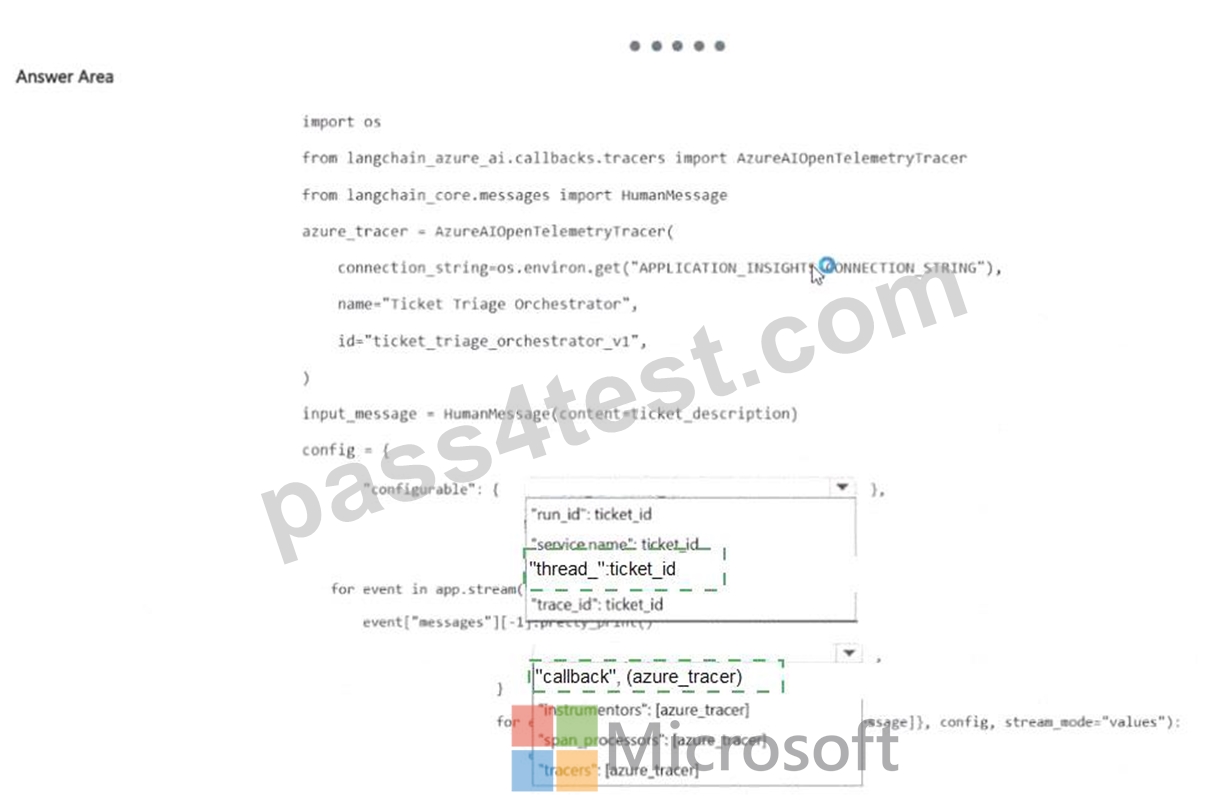
Explanation:
` " thread_id " : ticket_id` and ` " callbacks " : [azure_tracer]`.
LangGraph checkpointers use a stable `thread_id` under the configurable invocation context to associate execution and persisted state with the same logical request or conversation. Setting that value to the supplied
`ticket_id` allows graph steps and tool calls to be correlated to the ticket across a streamed run. Microsoft Foundry ' s LangGraph integration also uses `AzureAIOpenTelemetryTracer` through LangChain/LangGraph callbacks. Adding the tracer in the `callbacks` list causes agent, model, and tool spans to be emitted through OpenTelemetry and become visible in Foundry/Application Insights. A random run ID would not provide the stable checkpointer identity needed for state continuity, and fields such as `span_processors` are configured at a different instrumentation layer. Therefore the two code completions shown in the answer are correct. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents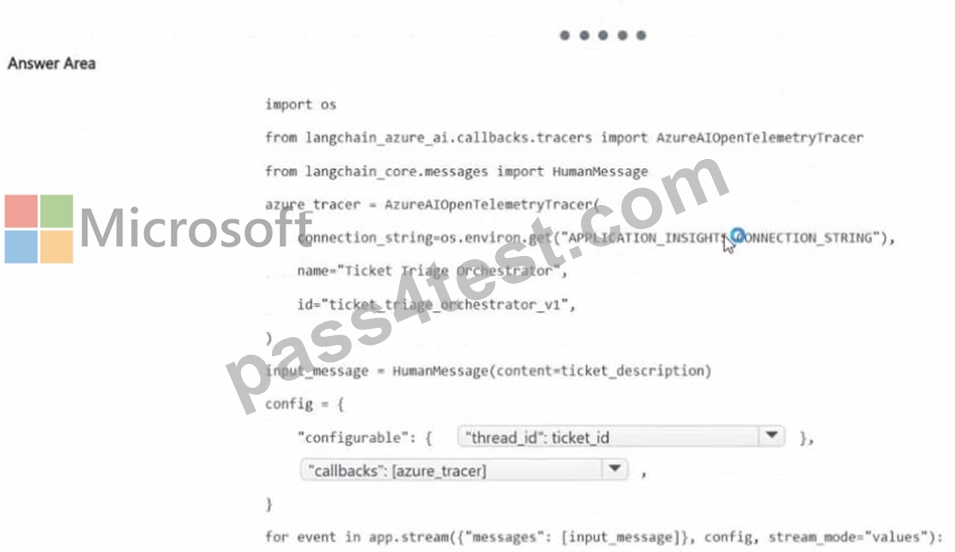
NEW QUESTION # 42
......
Most of the brands that offer Microsoft AI-500 study material provide it at high rates. However, Pass4Test saves your money by offering Microsoft AI-500 Real Questions at an affordable price. In addition, we offer up to 12 months of free AI-500 exam questions.
AI-500 Exam Duration: https://www.pass4test.com/AI-500.html