2026 Latest Itcertkey DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1jkXjxT7RLhJxzFPTF1Ymt7nCy07jNXW7
Our DP-600 study dumps are suitable for you whichever level you are in right now. Whether you are in entry-level position or experienced exam candidates who have tried the exam before, this is the perfect chance to give a shot. High quality and high accuracy DP-600 real materials like ours can give you confidence and reliable backup to get the certificate smoothly because our experts have extracted the most frequent-tested points for your reference, because they are proficient in this exam who are dedicated in this area over ten years. If you make up your mind of our DP-600 Exam Questions after browsing the free demos, we will staunchly support your review and give you a comfortable and efficient purchase experience this time.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Available Languages: | English, Japanese, Korean, Chinese (Simplified) |
| Certificate Validity Period: | 1 year |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
| Passing Score: | 700/1000 |
| Real Exam Qty: | 40-60 |
| Exam Duration: | 120 minutes |
| Exam Price: | $165 USD |
| Exam Format: | Case studies, Drag-and-drop, Multiple-choice |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or in-person testing center |
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
>> Latest Microsoft DP-600 Test Blueprint <<
That's why it's indispensable to use Implementing Analytics Solutions Using Microsoft Fabric (DP-600) real exam dumps. Itcertkey understands the significance of Updated Microsoft DP-600 Questions, and we're committed to helping candidates clear tests in one go. To help Microsoft DP-600 test applicants prepare successfully in one go, Itcertkey's DP-600 dumps are available in three formats: Implementing Analytics Solutions Using Microsoft Fabric (DP-600) web-based practice test, desktop DP-600 practice Exam software, and DP-600 dumps PDF.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 107
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.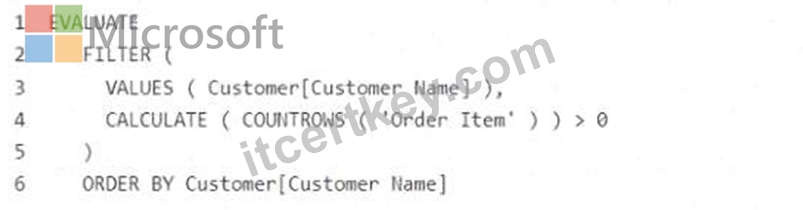
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
Does this meet the goal?
Answer: B
Explanation:
The command:
DESCRIBE DETAIL Customer
Returns metadata about the Delta table, such as format, schema, partitioning, size, number of files, and creation/modification timestamps.
However, it does not provide information about whether maintenance tasks (such as OPTIMIZE, VACUUM, or Z-Ordering) were performed on the table.
To check maintenance history, you would typically use:
DESCRIBE HISTORY Customer
which shows operations executed on the table (e.g., OPTIMIZE, VACUUM, MERGE).
Since DESCRIBE DETAIL does not satisfy the requirement, the solution does not meet the goal.
Reference:
DESCRIBE DETAIL in Delta Lake
DESCRIBE HISTORY in Delta Lake
NEW QUESTION # 108
You have a Fabric tenant that contains a semantic model named model1. The two largest columns in model1 are shown in the following table.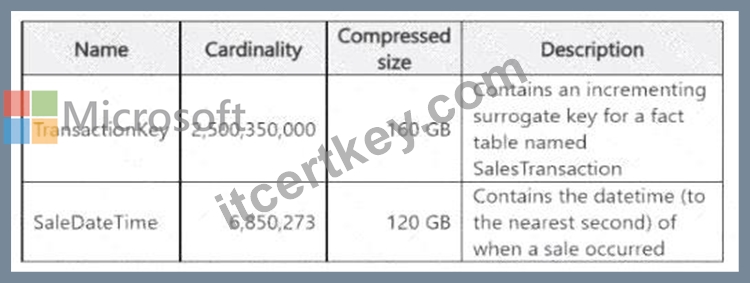
You need to optimize model 1. The solution must meet the following requirements:
* Reduce the model size.
* Increase refresh performance when using Import mode.
* Ensure that the datetime value for each sales transaction is available in the model.
What should you do on each column? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.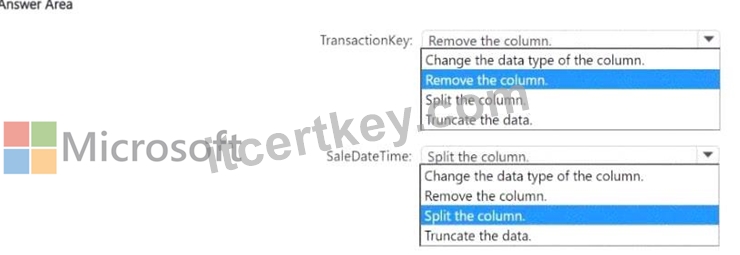
Answer:
Explanation: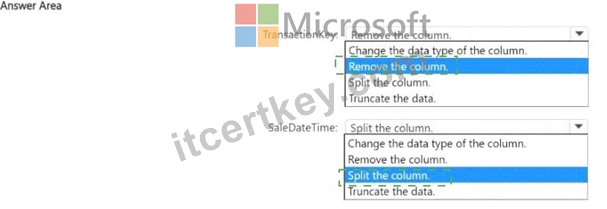
Explanation: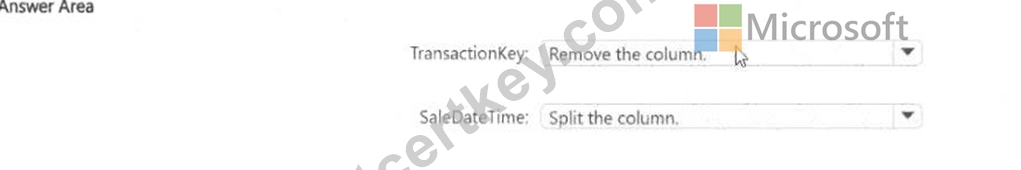
We are optimizing model1 in Fabric with two very large columns:
TransactionKey
Cardinality: 2.5 billion
Size: 160 GB
Description: surrogate key for SalesTransaction fact table.
SaleDateTime
Cardinality: 6.8 million
Size: 120 GB
Description: datetime (to the second) of when a sale occurred.
Goal:
Reduce model size.
Improve refresh performance (Import mode).
Ensure datetime values remain available.
Analysis per column
1. TransactionKey (very high cardinality)
Surrogate keys with extremely high cardinality do not add analytical value in a semantic model because they are not used in measures or grouping.
They take a lot of memory and reduce refresh performance.
Best practice: remove the column from the model.
2. SaleDateTime
Needed to analyze transactions by date and time.
However, storing the full datetime at second-level cardinality causes huge memory usage.
To optimize: split the column into Date and Time columns.
Reduces cardinality significantly.
Preserves full datetime information (can recombine if needed).
Improves compression and refresh speed.
Final Answer:
TransactionKey: Remove the column.
SaleDateTime: Split the column.
References:
Microsoft Fabric optimization guidance - reduce cardinality
Best practices for datetime optimization in semantic models
# Answer Selection:
TransactionKey # Remove the column
SaleDateTime # Split the column
NEW QUESTION # 109
You have a KQL database that contains a table named Readings.
You need to query Readings and return the results shown in the following table.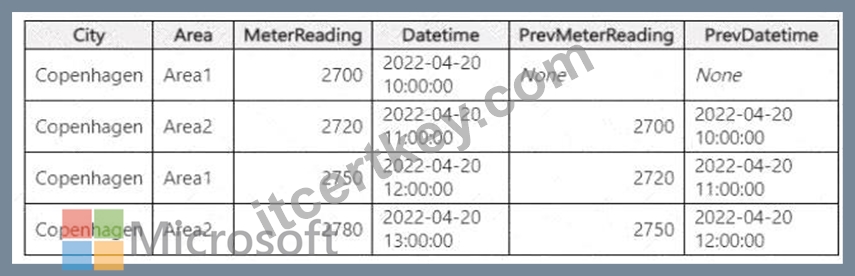
How should you complete the query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.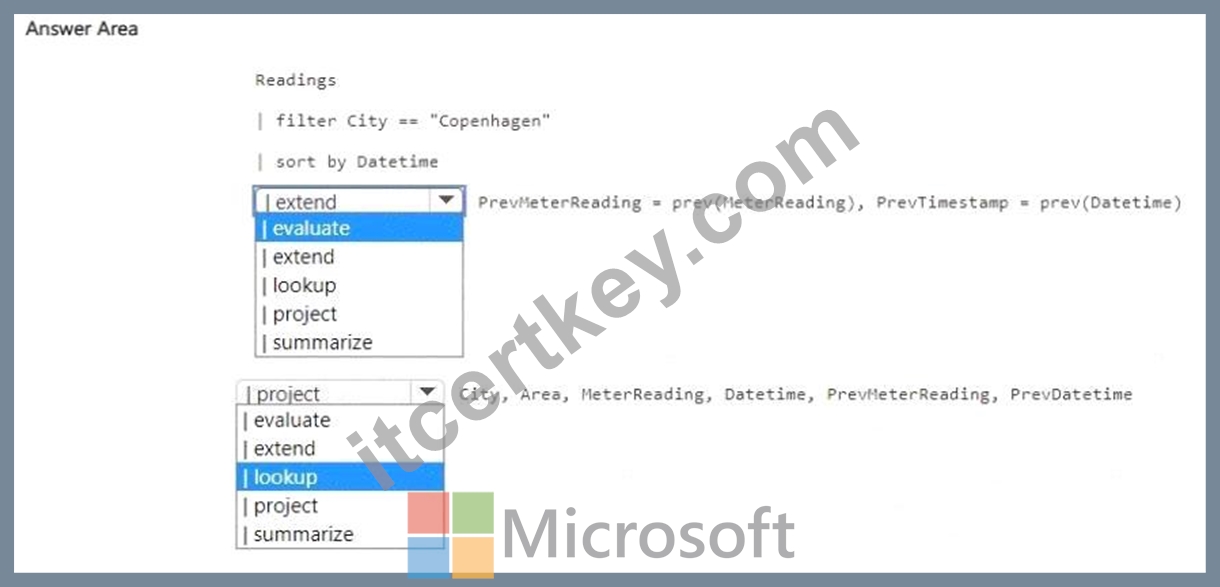
Answer:
Explanation: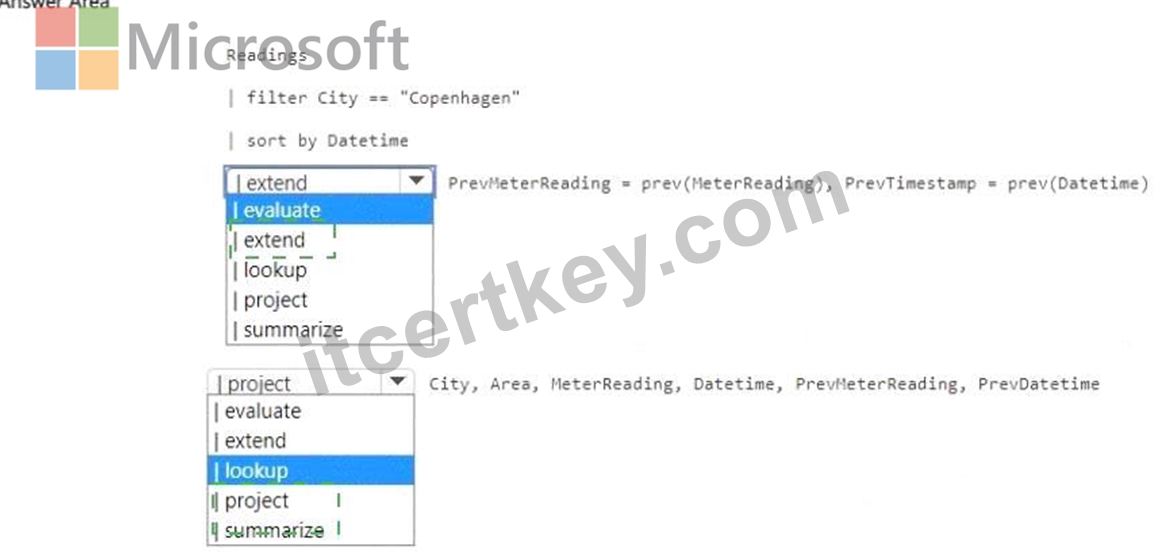
Explanation: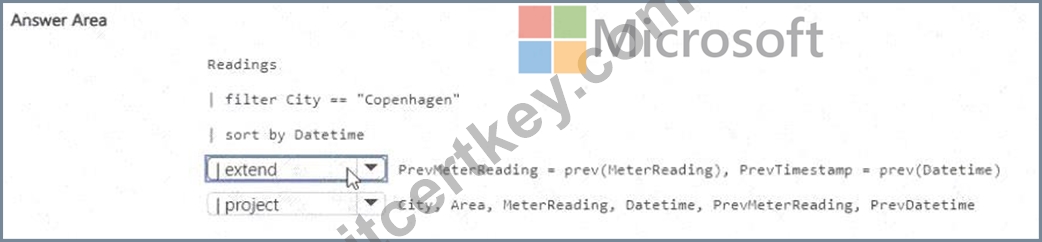
Comprehensive Detailed Explanation
We need to query a KQL database table named Readings to generate output that includes both the current reading and the previous reading values and datetime for each row.
Step 1: Understanding Requirements
The output table shows:
City, Area, MeterReading, Datetime
PrevMeterReading, PrevDatetime
The prev() function in KQL is used to access the value of a column from the previous row (based on order).
Step 2: Query Construction
We start with filtering:
Readings
| where City == " Copenhagen "
| sort by Datetime
To add columns that calculate the previous reading and previous datetime, we use extend:
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime) extend creates new columns.
prev() pulls the previous row's values.
Finally, we only want specific columns in the output. For this, we use project:
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Step 3: Completed Query Readings
| where City == " Copenhagen "
| sort by Datetime
| extend PrevMeterReading = prev(MeterReading), PrevDatetime = prev(Datetime)
| project City, Area, MeterReading, Datetime, PrevMeterReading, PrevDatetime Why This is Correct extend adds calculated columns.
prev() gives access to the previous row.
project selects only the required columns.
This matches exactly the table shown in the question.
References
Kusto Query Language - extend operator
Kusto Query Language - project operator
prev() function in KQL
NEW QUESTION # 110
You have a Fabric tenant that contains a lakehouse.
You are using a Fabric notebook to save a large DataFrame by using the following code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.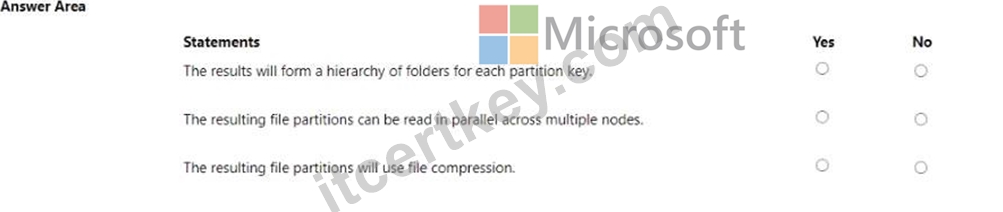
Answer:
Explanation: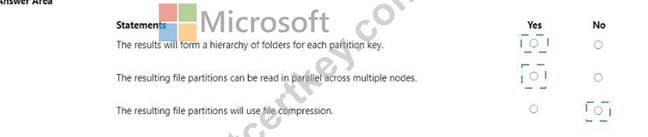
Explanation:
* The results will form a hierarchy of folders for each partition key. - Yes
* The resulting file partitions can be read in parallel across multiple nodes. - Yes
* The resulting file partitions will use file compression. - No
Partitioning data by columns such as year, month, and day, as shown in the DataFrame write operation, organizes the output into a directory hierarchy that reflects the partitioning structure. This organization can improve the performance of read operations, as queries that filter by the partitioned columns can scan only the relevant directories. Moreover, partitioning facilitates parallelism because each partition can be processed independently across different nodes in a distributed system like Spark. However, the code snippet provided does not explicitly specify that file compression should be used, so we cannot assume that the output will be compressed without additional context.
References =
* DataFrame write partitionBy
* Apache Spark optimization with partitioning
NEW QUESTION # 111
You have an Amazon Web Services (AWS) subscription that contains an Amazon Simple Storage Service (Amazon S3) bucket named bucketl.
You have a Fabric tenant that contains a lakehouse named LH1.
In LH1, you plan to create a OneLake shortcut to bucketl.
You need to configure authentication for the connection.
Which two values should you provide? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
NEW QUESTION # 112
......
DP-600 Certification Test Answers: https://www.itcertkey.com/DP-600_braindumps.html
DOWNLOAD the newest Itcertkey DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1jkXjxT7RLhJxzFPTF1Ymt7nCy07jNXW7