ActualPDF Databricks-Certified-Professional-Data-Engineer practice material can be accessed instantly after purchase, so you won't have to face any excessive issues for preparation of your desired Databricks Databricks-Certified-Professional-Data-Engineer certification exam. The Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps of ActualPDF has been made after seeking advice from many professionals. Our objective is to provide you with the best learning material to clear the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam.
Databricks Certified Professional Data Engineer is a certification exam that tests the skills and knowledge required to design and implement data solutions using Databricks. Databricks is a cloud-based data platform that helps organizations manage and process large amounts of data. Databricks Certified Professional Data Engineer Exam certification exam is designed for data engineers who are responsible for creating and maintaining data pipelines, managing data storage, and implementing data solutions.
Databricks Certified Professional Data Engineer certification exam is suitable for data engineers, data architects, and data scientists who are responsible for building and managing data pipelines and workflows. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the knowledge and skills required to design, implement, and manage data engineering workflows using Databricks. Candidates must have a solid understanding of data engineering concepts such as data modeling, data integration, data transformation, and data storage.
>> Databricks-Certified-Professional-Data-Engineer PDF Question <<
Passing the Databricks-Certified-Professional-Data-Engineer exam in the shortest time is the voice of all the examinees. But how to select the most valuable information in overwhelming learning materials is a headache thing for all examiners. After our unremitting efforts, our Databricks-Certified-Professional-Data-Engineer learning guide comes in everybody's expectation. Our professional experts not only have simplified the content and grasp the key points for our customers, but also recompiled the Databricks-Certified-Professional-Data-Engineer Preparation materials into simple language, you will get a leisure study experience as well as a doomed success on your coming Databricks-Certified-Professional-Data-Engineer exam.
The Databricks Databricks-Certified-Professional-Data-Engineer Exam is ideal for data engineers who want to demonstrate their expertise in designing, building, and maintaining big data processing pipelines using Databricks. Databricks Certified Professional Data Engineer Exam certification exam is tailored to the specific roles and responsibilities of a data engineer, and it covers a range of topics, including data ingestion, data transformations, data storage, and data analysis. By passing the exam, candidates can demonstrate their proficiency in using Databricks to solve complex big data challenges.
NEW QUESTION # 40
A denote the event 'student is female' and let B denote the event 'student is French'. In a class of 100 students
suppose 60 are French, and suppose that 10 of the French students are females. Find the probability that if I
pick a French student, it will be a girl, that is, find P(A|B).
Answer: B
Explanation:
Explanation
Since 10 out of 100 students are both French and female, then
P(AandB)=10100
Also. 60 out of the 100 students are French, so
P(B)=60100
So the required probability is:
P(A|B)=P(AandB)P(B)=10/10060/100=16
NEW QUESTION # 41
A nightly job ingests data into a Delta Lake table using the following code: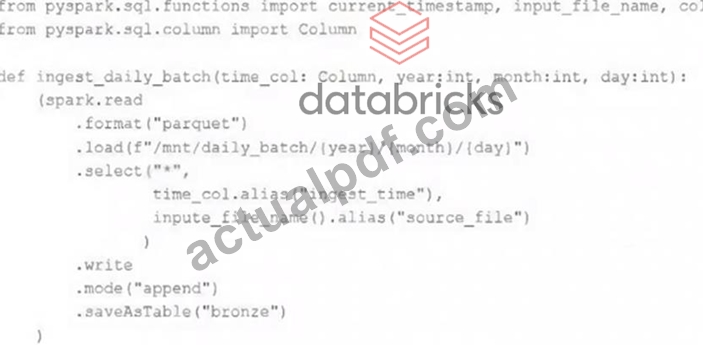
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
A . return spark.readStream.table("bronze")
B . return spark.readStream.load("bronze")
C .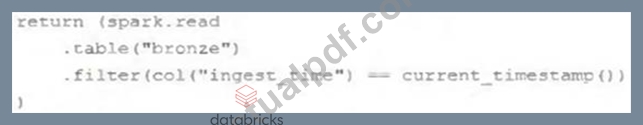
D .
return spark.read.option("readChangeFeed", "true").table ("bronze")
E .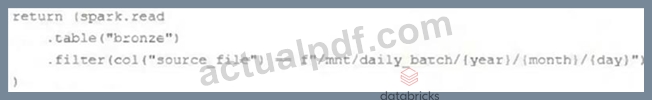
Answer: E
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 42
A Structured Streaming job deployed to production has been experiencing delays during peak hours of the day.
At present, during normal execution, each microbatch of data is processed in less than 3 seconds. During peak hours of the day, execution time for each microbatch becomes very inconsistent, sometimes exceeding 30 seconds. The streaming write is currently configured with a trigger interval of 10 seconds.
Holding all other variables constant and assuming records need to be processed in less than 10 seconds, which adjustment will meet the requirement?
Answer: A
Explanation:
Explanation
This is the correct answer because it can meet the requirement of processing records in less than 10 seconds without modifying the checkpoint directory or dropping records. The trigger once option is a special type of trigger that runs the streaming query only once and terminates after processing all available data. This option can be useful for scenarios where you want to run streaming queries on demand or periodically, rather than continuously. By using the trigger once option and configuring a Databricks job to execute the query every 10 seconds, you can ensure that all backlogged records are processed with each batch and avoid inconsistent execution times. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Trigger Once" section.
NEW QUESTION # 43
The security team is exploring whether or not the Databricks secrets module can be leveraged for connecting to an external database.
After testing the code with all Python variables being defined with strings, they upload the password to the secrets module and configure the correct permissions for the currently active user. They then modify their code to the following (leaving all other variables unchanged).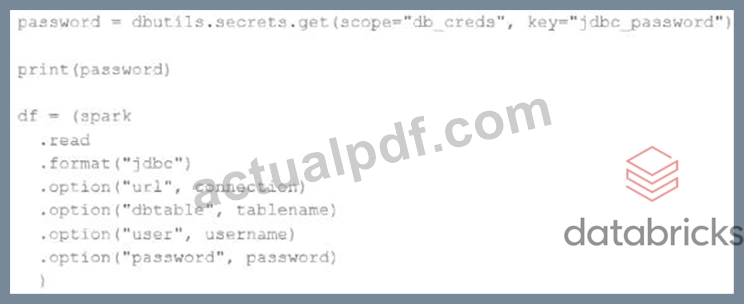
Which statement describes what will happen when the above code is executed?
Answer: A
Explanation:
This is the correct answer because the code is using the dbutils.secrets.get method to retrieve the password from the secrets module and store it in a variable. The secrets module allows users to securely store and access sensitive information such as passwords, tokens, or API keys. The connection to the external table will succeed because the password variable will contain the actual password value. However, when printing the password variable, the string "redacted" will be displayed instead of the plain text password, as a security measure to prevent exposing sensitive information in notebooks. Verified References: [Databricks Certified Data Engineer Professional], under "Security & Governance" section; Databricks Documentation, under
"Secrets" section.
NEW QUESTION # 44
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic: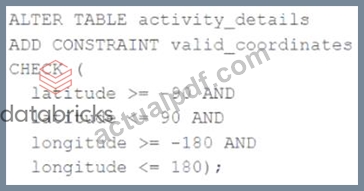
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
Answer: B
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
* Constraints: https://docs.delta.io/latest/delta-constraints.html
* ACID Transactions: https://docs.delta.io/latest/delta-intro.html#acid-transactions
NEW QUESTION # 45
......
Reliable Databricks-Certified-Professional-Data-Engineer Braindumps: https://www.actualpdf.com/Databricks-Certified-Professional-Data-Engineer_exam-dumps.html