BONUS!!! Japancert DP-100ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1Envkly4WjjcHg__mJ7QbLnK6K6aBHmKs
JapancertはもっぱらMicrosoftプロDP-100認証試験に関する知識を提供するのサイトで、ほかのサイト使った人はJapancertが最高の知識源サイトと比較しますた。Japancertの商品はとても頼もしいDP-100試験の練習問題と解答は非常に正確でございます。
DP-100試験の成功裏に合格すると、Microsoft Certified: Azure Data Scientist Associate認定が授与され、世界中の雇用主に認められます。この認定は、候補者のデータサイエンス分野におけるスキルと知識を証明するものであり、求職市場での競争力を高めることができます。
Japancert練習資料は、成功するための貴重な可能性を奪います。 このラインのプロのモデル会社として、DP-100トレーニング資料の成功:Designing and Implementing a Data Science Solution on Azureは予見できる結果になります。 一部の厳選された顧客でさえ、彼らの高品質と正確さの実践をやめることはできません。 私たちは品質の問題に非妥協的であり、あなたは彼らの習熟度を厳しく完全に確信することができます。 長年の訂正と修正を受けて、DP-100試験問題はすでに完璧になっています。 彼らは、エラーのない有望な練習資料です。 成功への道を示す指標として、私たちの練習資料はあなたの旅のあらゆる困難を乗り越えることができます。 すべての課題をウォークインのように扱うことはできませんが、DP-100シミュレーションの実践により、Microsoftレビューを効果的にすることができます。 それが彼らがラインのプロモデルである理由です。
Microsoft DP-100試験は、Microsoft Azureプラットフォーム上でのデータサイエンスソリューションの設計と実装に関する知識とスキルを証明したい個人向けの認定試験です。この試験は、データサイエンティスト、データエンジニア、および他のITプロフェッショナルが、自組織においてデータソリューションの設計と実装を担当している場合に向けられています。この試験は、機械学習モデルの設計と実装、予測モデルの構築、およびデータサイエンスのためのAzureサービスの展開と管理能力を測定します。
質問 # 211
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You plan to use a Python script to run an Azure Machine Learning experiment. The script creates a reference to the experiment run context, loads data from a file, identifies the set of unique values for the label column, and completes the experiment run:
from azureml.core import Run
import pandas as pd
run = Run.get_context()
data = pd.read_csv('data.csv')
label_vals = data['label'].unique()
# Add code to record metrics here
run.complete()
The experiment must record the unique labels in the data as metrics for the run that can be reviewed later.
You must add code to the script to record the unique label values as run metrics at the point indicated by the comment.
Solution: Replace the comment with the following code:
run.upload_file('outputs/labels.csv', './data.csv')
Does the solution meet the goal?
正解:A
解説:
label_vals has the unique labels (from the statement label_vals = data['label'].unique()), and it has to be logged.
Note:
Instead use the run_log function to log the contents in label_vals:
for label_val in label_vals:
run.log('Label Values', label_val)
8E6BA412E7DB6A14A62CC68E5EB6DAE3
Reference:
https://www.element61.be/en/resource/azure-machine-learning-services-complete-toolbox-ai
質問 # 212
You are creating data wrangling and model training solutions in an Azure Machine Learning workspace.
You must use the same Python notebook to perform both data wrangling and model training.
You need to use the Azure Machine Learning Python SDK v2 to define and configure the Synapse Spark pool asynchronously in the workspace as dedicated compute How should you complete the rode segment? To answer, select the appropriate options in the answer area.
NOTE: Lach correct selection is worth one point.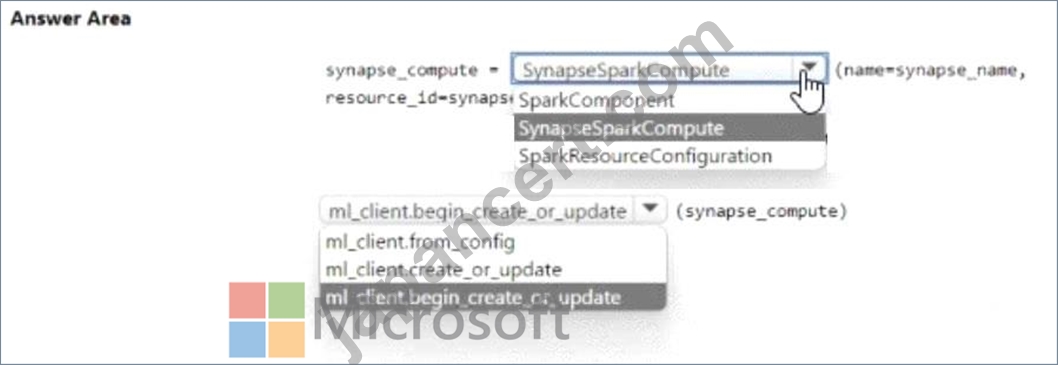
正解:
解説: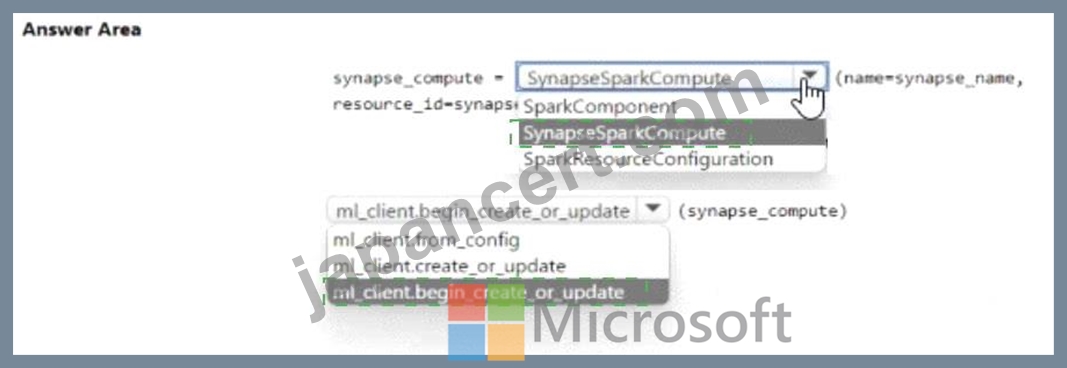
Explanation: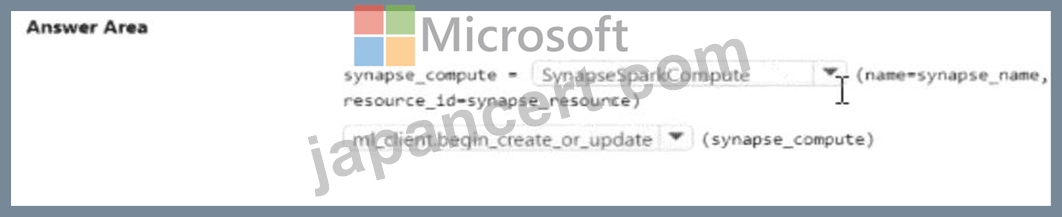
質問 # 213
Hotspot Question
You build a data pipeline in an Azure Machine Learning workspace by using the Azure Machine Learning SDK for Python. You create a data preparation step in the data pipeline.
You create the following code fragment in Python: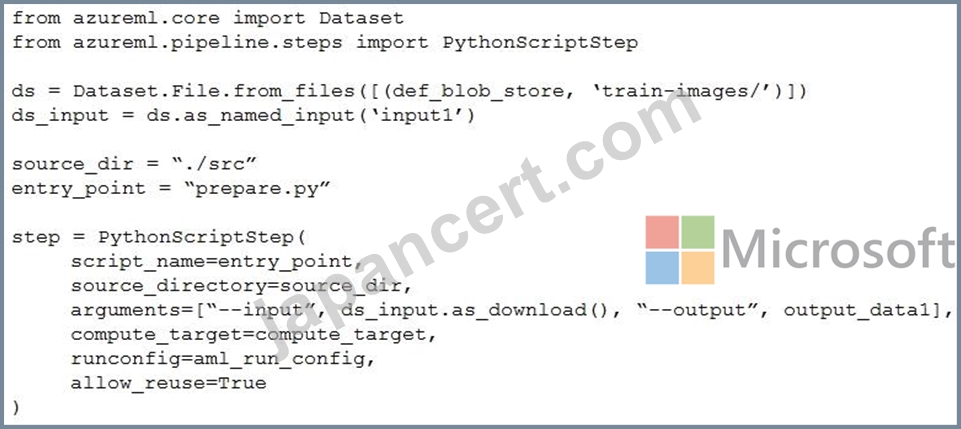
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.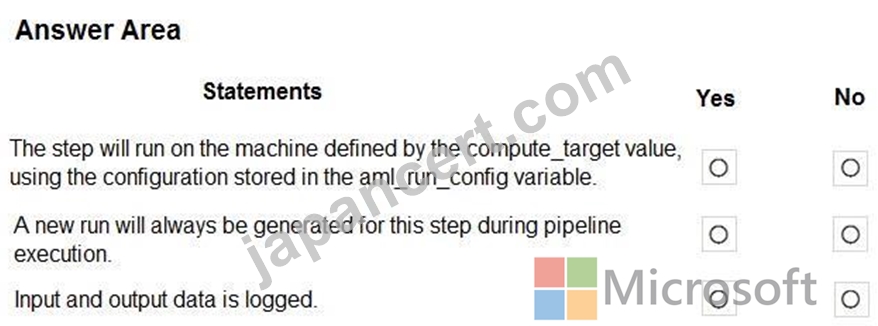
正解:
解説: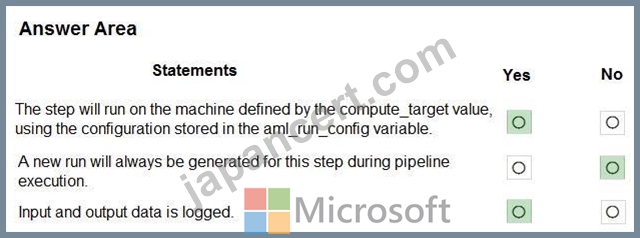
質問 # 214
You plan to preprocess text from CSV files. You load the Azure Machine Learning Studio default stop words list.
You need to configure the Preprocess Text module to meet the following requirements:
Ensure that multiple related words from a single canonical form.
Remove pipe characters from text.
Remove words to optimize information retrieval.
Which three options should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.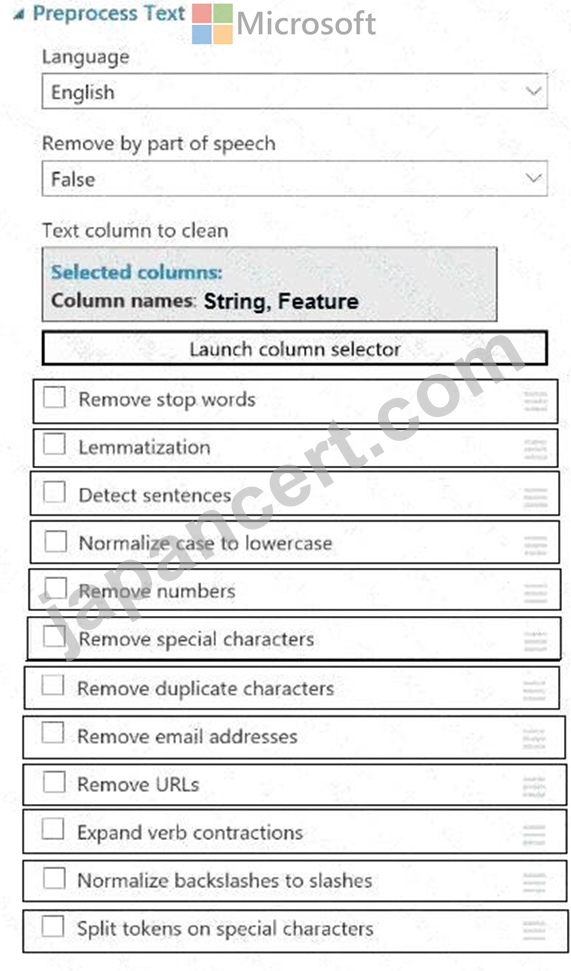
正解:
解説: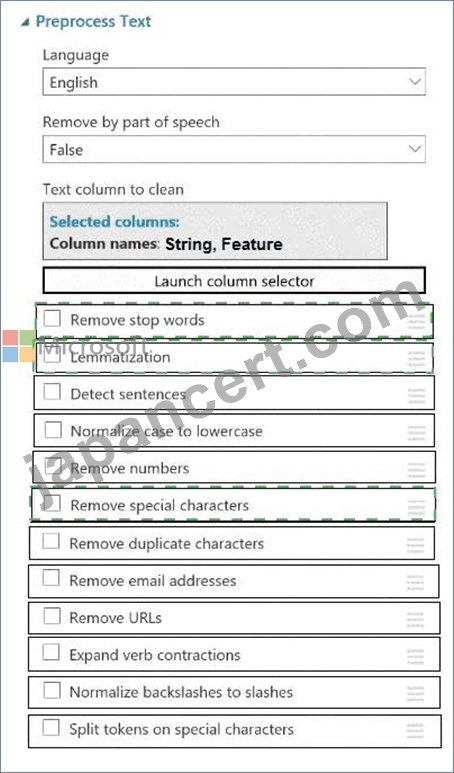
Explanation: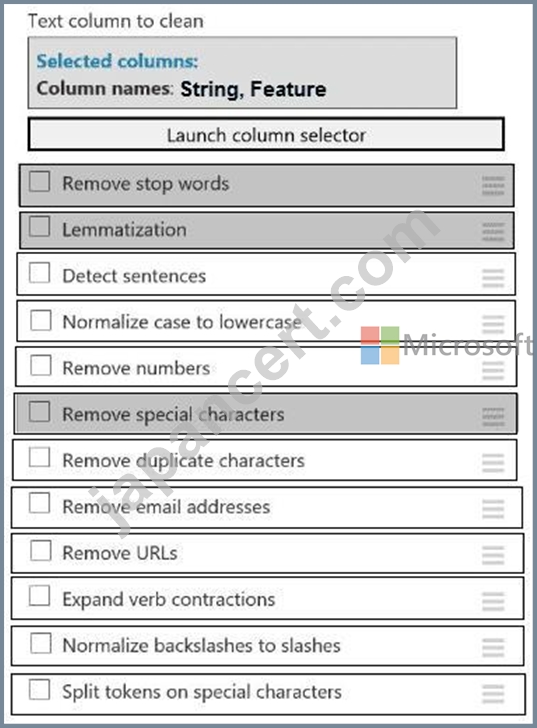
Box 1: Remove stop words
Remove words to optimize information retrieval.
Remove stop words: Select this option if you want to apply a predefined stopword list to the text column.
Stop word removal is performed before any other processes.
Box 2: Lemmatization
Ensure that multiple related words from a single canonical form.
Lemmatization converts multiple related words to a single canonical form Box 3: Remove special characters Remove special characters: Use this option to replace any non-alphanumeric special characters with the pipe | character.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/preprocess-text
質問 # 215
You create a binary classification model.
You need to evaluate the model performance.
Which two metrics can you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
正解:A、C
解説:
The evaluation metrics available for binary classification models are: Accuracy, Precision, Recall, F1 Score, and AUC.
Note: A very natural question is: 'Out of the individuals whom the model, how many were classified correctly (TP)?' This question can be answered by looking at the Precision of the model, which is the proportion of positives that are classified correctly.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio/evaluate-model-performance
質問 # 216
......
DP-100専門知識内容: https://www.japancert.com/DP-100.html
P.S. JapancertがGoogle Driveで共有している無料かつ新しいDP-100ダンプ:https://drive.google.com/open?id=1Envkly4WjjcHg__mJ7QbLnK6K6aBHmKs