2026 Latest Pass4suresVCE AI-200 PDF Dumps and AI-200 Exam Engine Free Share: https://drive.google.com/open?id=1EqS6oqRpjLUfr0McggWNS6KVjf9zJ5F0
In compliance with syllabus of the exam, our AI-200 practice materials are determinant factors giving you assurance of smooth exam. Our AI-200 practice materials comprise of a number of academic questions for your practice, which are interlinked and helpful for your exam. So, they are specified as one of the most successful AI-200 practice materials in the line. They can renew your knowledge with high utility with Favorable prices. So, they are reliably rewarding AI-200 practice materials with high utility value.
| Section | Objectives |
|---|---|
| Topic 1: Implement Azure AI solutions | - Implement natural language processing solutions - Implement computer vision solutions - Implement generative AI solutions using Azure OpenAI - Implement knowledge mining with Azure AI Search |
| Topic 2: Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
>> AI-200 Test Registration <<
We will provide you with comprehensive study experience by give you AI-200 free study material & Microsoft exam prep torrent. The questions & answers from the Microsoft practice torrent are all valid and accurate, made by the efforts of a professional IT team. The authority and validity of Microsoft AI-200 training practice are the guarantee for all the IT candidates. We arrange our experts to check the update every day. Once there is any new technology about AI-200 Exam Dumps, we will add the latest questions into the AI-200 study pdf, and remove the useless study material out, thus to ensure the AI-200 exam torrent you get is the best valid and latest. So 100% pass is our guarantee.
NEW QUESTION # 19
You are building a RAG (retrieval-augmented generation) solution using Azure AI Foundry. The knowledge base consists of 50,000 PDF documents stored in Azure Blob Storage.
You need to make the document content searchable by the language model with minimal custom code.
What should you use?
Answer: A
Explanation:
Use Azure AI Search integrated vectorization with a skillset . Integrated vectorization automates the main ingestion stages required for RAG: an Azure AI Search indexer can read documents directly from a supported data source such as Azure Blob Storage, extract and split document content into chunks, invoke an embedding model, and store both searchable text and vector representations in the search index. Microsoft specifically states that integrated vectorization reduces development and maintenance effort because developers do not need to implement the chunking and embedding pipeline manually.
A skillset can include a Text Split skill for chunking and an Azure OpenAI Embedding skill or another supported embedding skill for vector generation. At query time, a matching vectorizer can convert user questions into vectors so Azure AI Search can perform similarity or hybrid retrieval for grounding the language model.
Custom text classification solves a different NLP problem. Building Azure Functions to process all 50,000 PDFs manually would introduce unnecessary custom orchestration and maintenance. Azure Table Storage does not provide the native vector-search and RAG indexing capabilities required here.
Study Guide references: Azure AI Search # integrated vectorization; indexers; skillsets; Text Split skill; embedding skills; vector indexes; RAG retrieval.
NEW QUESTION # 20
You are developing an AI application. The application configuration will depend on a dynamically retrieved value of a designated key stored in an Azure App Configuration resource.
You must deploy the application to the test, staging, and production environments.
You need to be able to set the value differently in each environment.
Which feature of Azure App Configuration resource should you use?
Answer: C
Explanation:
You should use the Label feature of the Azure App Configuration resource.
In Azure App Configuration, keys can optionally include a label, which acts as a dimension or tag to create distinct variants of the same key. This allows you to store environment-specific values (such as test, staging, and production) under a single key name and load the appropriate configuration dynamically based on the current deployment environment.
References:
https://learn.microsoft.com/en-us/answers/questions/2108879/azure-app-configuration-resource-manager-api-is-de
NEW QUESTION # 21
You have a newly provisioned Azure subscription. You are designing a custom Event Grid workflow for AI inference events.
You need to implement the Event Grid components to support routing of high-confidence events to a downstream processor.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.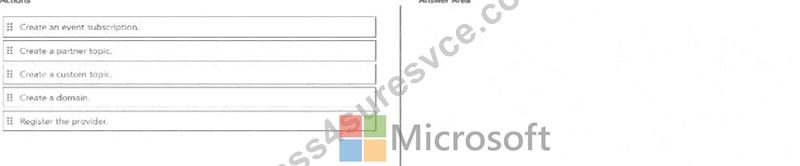
Answer:
Explanation: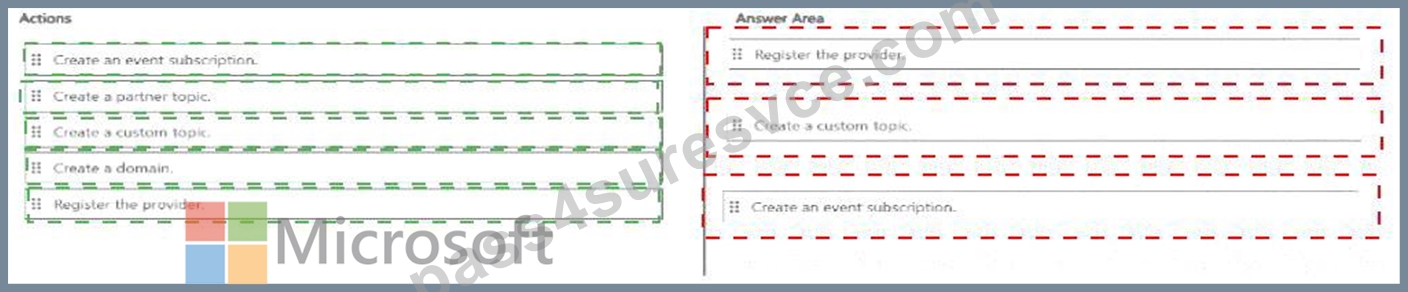
Explanation: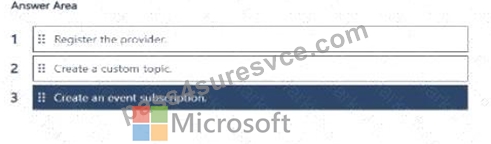
Verified answer: 1) Register the Event Grid resource provider; 2) create a custom topic; 3) create an event subscription.
Detailed Explanation: A newly provisioned subscription must have the Event Grid resource provider available before Event Grid resources can be created. The publisher needs a custom topic as the event-ingress resource, and routing to a downstream processor is then defined by an event subscription on that topic. The event subscription can include filters such as event type or data fields so that only high-confidence events reach the processor. Creating a partner topic or domain is unnecessary for the stated custom workflow.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Create an Event Grid custom topic or domain
NEW QUESTION # 22
You need to troubleshoot connectivity failures between microservices running in AKS.
Which troubleshooting actions should you perform? To answer, move the appropriate action to the correct troubleshooting scenario. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.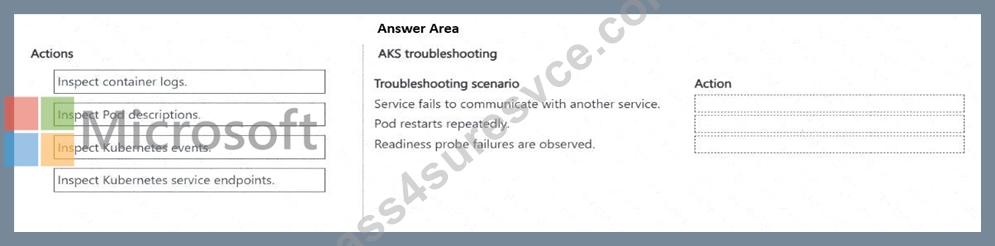
Answer:
Explanation: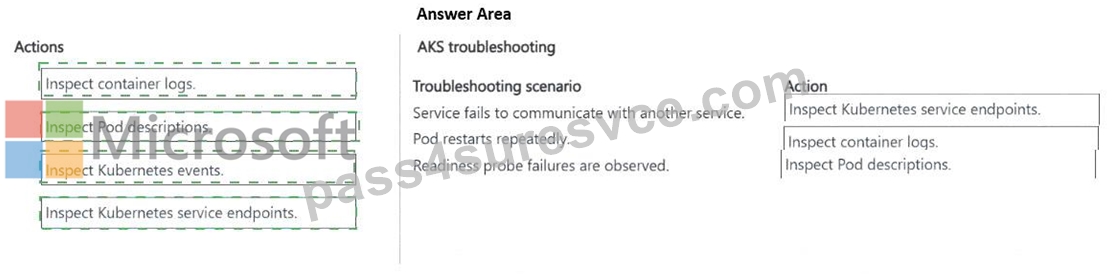
Explanation:
* Service fails to communicate with another service: Inspect Kubernetes service endpoints.
* Pod restarts repeatedly: Inspect container logs.
* Readiness probe failures are observed: Inspect Pod descriptions.
For a service-to-service communication failure , first inspect the Kubernetes service endpoints . Microsoft' s AKS troubleshooting guidance recommends verifying that the destination pod IP address and application port appear as endpoints for the Kubernetes Service. An empty or incorrect endpoint list commonly indicates a selector/label mismatch, incorrect port configuration, or unavailable backend pods.
For a pod that restarts repeatedly , inspect the container logs , including the previous container instance when necessary. Microsoft specifically recommends kubectl logs < pod > --previous for workloads that repeatedly restart because it exposes application errors and termination messages from the container immediately before the restart.
For readiness probe failures , inspect the Pod description by using kubectl describe pod. The description exposes the configured health probes, pod conditions, container state, and associated probe-failure events, allowing you to determine whether the probe path, port, timing, or application readiness behavior is incorrect.
Microsoft recommends reviewing kubectl describe output when pods are not Ready or health probes are failing.
Therefore, the correct mapping is service endpoints # container logs # Pod descriptions .
Study Guide references: AKS troubleshooting; Kubernetes Services and endpoints; container logging; Pod health; readiness/liveness probes; kubectl describe and kubectl logs.
NEW QUESTION # 23
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to configure a connection string for the partner-facing service according to the technical requirements.
What should you use?
Answer: B
Explanation:
Technical Requirements
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
To configure the connection string securely at runtime, you should use App Service environment variables combined with Azure Key Vault references.
Runtime Resolution: When you configure an App Service environment variable using the standard @Microsoft.KeyVault(...) syntax, Azure App Service resolves the secret value dynamically at runtime.
Managed Identity Integration: The App Service automatically uses its assigned system-assigned or user-assigned Managed Identity to authenticate against Azure Key Vault. No credentials are saved locally.
Separation of Concerns: The secret value remains centrally managed in Key Vault, fulfilling the constraint that secrets must not live inside code, configuration files, or image layers.
Reference:
https://learn.microsoft.com/en-us/azure/app-service/app-service-key-vault-references
NEW QUESTION # 24
......
These people who used our products have thought highly of our AI-200 study materials. If you decide to buy our products and tale it seriously consideration, we can make sure that it will be very easy for you to simply pass your exam and get the AI-200 certification in a short time. We are also willing to help you achieve your dream. Now give youself a chance to have a try on our AI-200 Study Materials. You will have no regret spending your valuable time on our AI-200 learning guide.
AI-200 Test Dumps Demo: https://www.pass4suresvce.com/AI-200-pass4sure-vce-dumps.html
BONUS!!! Download part of Pass4suresVCE AI-200 dumps for free: https://drive.google.com/open?id=1EqS6oqRpjLUfr0McggWNS6KVjf9zJ5F0