All of our DP-750 pdf torrent are up-to-date and reviewed by our IT experts and professionals. We have written our DP-750 study guide in such a way that you don't need to prepare anything else after practice our DP-750 Exam Questions. You can pass the real exam easily with our latest DP-750 vce dumps and this is the only smartest way to get success. Just contact us if you have any questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 4: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
The most important part of Microsoft DP-750 exam preparation is practice, and the right practice is often the difference between success and failure. TroytecDumps also makes your preparation easier with practice test software to help you get hands-on exam experience before the actual Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam. After consistent practice, the final exam will not be too difficult for a student who has already practiced from real Microsoft DP-750 exam questions.
NEW QUESTION # 38
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.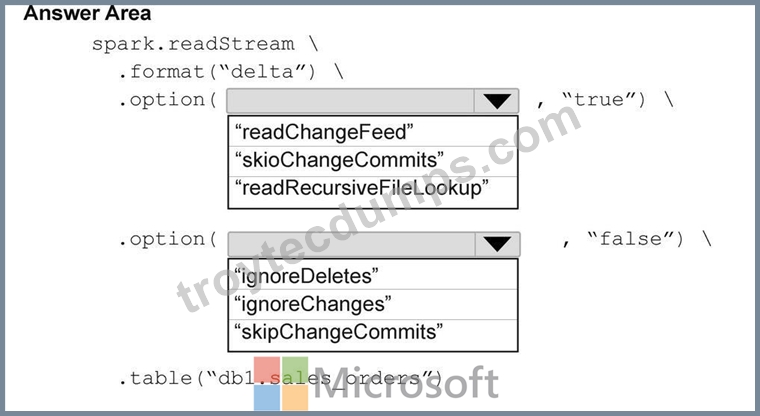
Answer:
Explanation: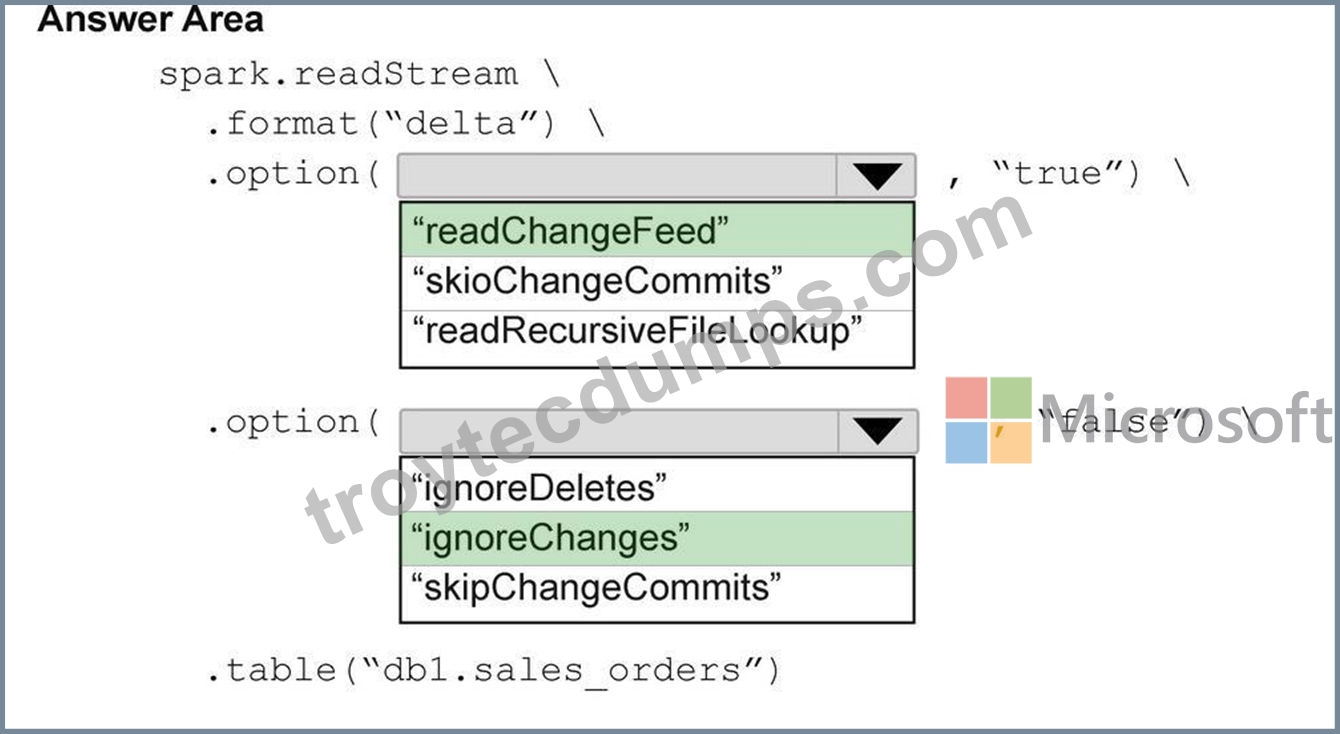
NEW QUESTION # 39
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: D
Explanation:
Create separate tasks for ingestion, cleansing, and curation is the best architectural fit.
This modular workflow approach natively addresses the scenario's technical challenges:
Modularity and Resource Efficiency: Splitting the pipeline into distinct, sequential tasks allows you to configure dedicated, non-interactive compute clusters tailored to the specific resource requirements of each phase (e.g., lightweight for ingestion, heavier memory for curation).
Handling Peak Loads: Independent task scaling ensures that the heavy ingestion phase can scale up to handle event hub spikes without dragging down or over-allocating resources for downstream processing.
Checkpointing & Schema Drift: Separate tasks allow structured streaming checkpoints to be cleanly isolated for each step, ensuring that if a pipeline restarts, it continues exactly where it left off without reprocessing old events. Schema evolution can also be intercepted and handled gracefully between stages rather than breaking a monolith script.
Scenario:
Technical Requirements, Contoso identifies the following environment and compute requirements:
-> Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Technical Requirements, Contoso identifies the following data ingestion and processing requirements:
-> Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
Problem Statements, The company's existing analytics environment has several issues:
Ingestion
Telemetry pipelines fall behind during peak loads.
Telemetry ingestion fails when schema drift occurs.
Streaming pipelines reprocess events after a pipeline restarts.
Reference:
https://www.meegle.com/en_us/topics/etl-pipeline/etl-pipeline-for-hadoop-ecosystems
NEW QUESTION # 40
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: D
NEW QUESTION # 41
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
Drag and Drop Question
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.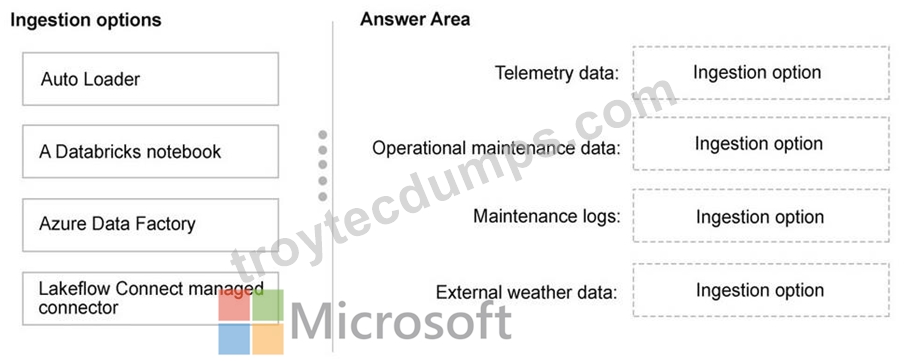
Answer:
Explanation: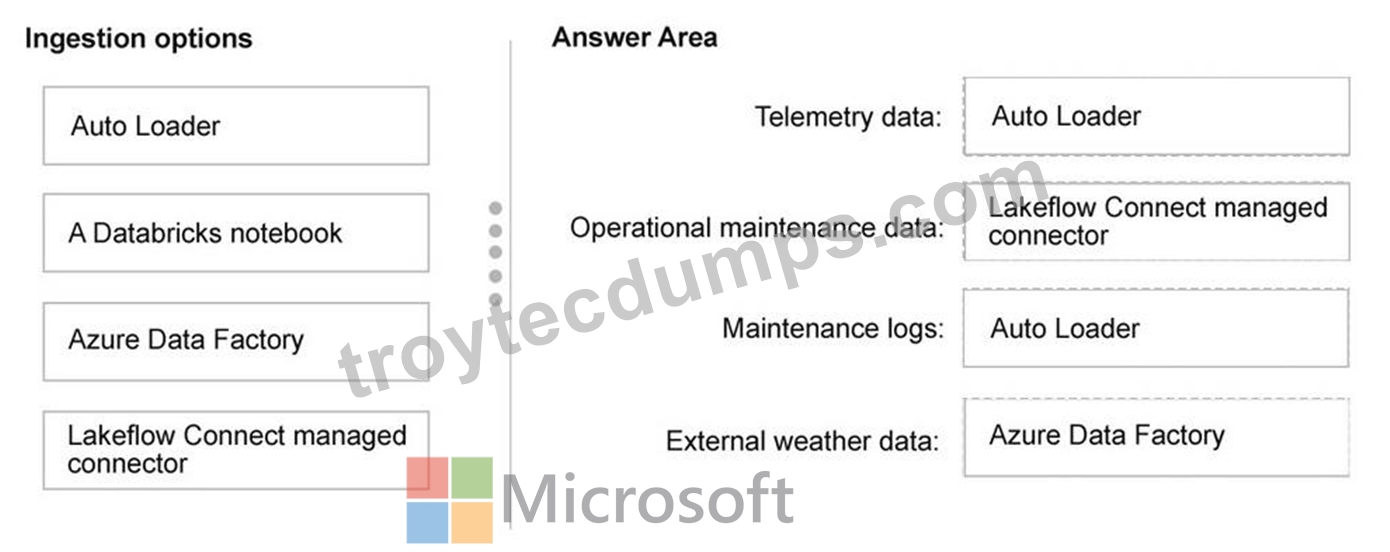
NEW QUESTION # 42
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1. Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
Lakeflow Connect is an ingestion service that physically copies data from external databases into Delta tables managed by Databricks. It's designed for scenarios where you want a replicated, writable Delta copy of external data - essentially a CDC-based ingestion pipeline.
That's the opposite of what's required here. The requirement states 'the data is NOT copied into Databricks- managed storage.' Lakeflow Connect would create Delta tables in Databricks and copy DB1's data into them
- a direct violation.
Additionally, Lakeflow Connect creates Databricks-native Delta tables rather than exposing DB1's original schemas and tables as virtual objects. Analysts querying through a Lakeflow Connect pipeline are querying a replicated copy, not the live source.
For zero-copy, live query federation of an external SQL Server into Unity Catalog, Lakehouse Federation (foreign catalog) is the correct tool.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/lakeflow-connect/
NEW QUESTION # 43
......
Learning with our DP-750 learning guide is quiet a simple thing, but some problems might emerge during your process of DP-750 exam materials or buying. Considering that our customers are from different countries, there is a time difference between us, but we still provide the most thoughtful online after-sale service on DP-750 training guide twenty four hours a day, seven days a week, so just feel free to contact with us through email anywhere at any time. Our commitment of helping you to pass DP-750 exam will never change.
DP-750 Examcollection Dumps Torrent: https://www.troytecdumps.com/DP-750-troytec-exam-dumps.html