Laden Sie die neuesten Zertpruefung Databricks-Certified-Data-Analyst-Associate PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1jOCtJOQxBeCOrvFfgy5R6lUJNoNuK0VW
Die Databricks Databricks-Certified-Data-Analyst-Associate Zertifizierungsprüfung ist schon eine der beliebten IT-Zertifizierungsprüfungen geworden. Aber für die Prüfung braucht man viel Zeit und Energie, um die Fachkenntnisse gut zu beherrschen. Im diesem Zeitalter, wo die Zeit sehr geschätzt wird, betrachtet man Zeit wie Geld. Das Schulungsprogramm zur Databricks Databricks-Certified-Data-Analyst-Associate Zertifizierungsprüfung von Zertpruefung dauert ungefähr 20 Stunden. Dann können Sie Ihre Fachkenntnisse konsolidierern und sich gut auf die Databricks Databricks-Certified-Data-Analyst-Associate Zertifizierungsprüfung vorbereiten.
| Section | Objectives |
|---|---|
| Topic 1: Data Visualization and Dashboards | - Creating dashboards in Databricks SQL
|
| Topic 2: Data Governance and Security | - Access control and permissions
|
| Topic 3: Databricks SQL and SQL Analytics | - Querying data using SQL in Databricks
|
| Topic 4: Data Management in Lakehouse | - Data ingestion and preparation
|
>> Databricks-Certified-Data-Analyst-Associate Prüfungsaufgaben <<
Wollen Sie Ihre IT-Fähigkeiten beweisen? Möchten Sie mehr Anerkennung und Berufschancen bekommen? Die Prüfungszertifizierung der Databricks Databricks-Certified-Data-Analyst-Associate ist ein bedeutendester Ausweis für Sie. Die Wichtigkeit der Zertifizierung der Databricks Databricks-Certified-Data-Analyst-Associate wissen fast alle Angestellte aus IT-Branche. Die Tatkraft von Menschen ist limitiert. Wenn Sie in einer kurzen Zeit diese wichtige Databricks Databricks-Certified-Data-Analyst-Associate Prüfung bestehen möchten, brauchen Sie unsere die Prüfungssoftware von uns Zertpruefung als Ihr bester Helfer für die Prüfungsvorbereitung. Umfassende Prüfungsaufgaben enthaltende und Mnemotechnik entsprechende Software kann Ihnen beim Erfolg der Databricks Databricks-Certified-Data-Analyst-Associate gut helfen!
18. Frage
A data analysis team is working with the table_bronze SQL table as a source for one of its most complex projects. A stakeholder of the project notices that some of the downstream data is duplicative. The analysis team identifies table_bronze as the source of the duplication.
Which of the following queries can be used to deduplicate the data from table_bronze and write it to a new table table_silver?
A)
CREATE TABLE table_silver AS
SELECT DISTINCT *
FROM table_bronze;
B)
CREATE TABLE table_silver AS
INSERT *
FROM table_bronze;
C)
CREATE TABLE table_silver AS
MERGE DEDUPLICATE *
FROM table_bronze;
D)
INSERT INTO TABLE table_silver
SELECT * FROM table_bronze;
E)
INSERT OVERWRITE TABLE table_silver
SELECT * FROM table_bronze;
Antwort: B
Begründung:
Option A uses the SELECT DISTINCT statement to remove duplicate rows from the table_bronze and create a new table table_silver with the deduplicated data. This is the correct way to deduplicate data using Spark SQL12. Option B simply inserts all the rows from table_bronze into table_silver, without removing any duplicates. Option C is not a valid syntax for Spark SQL, as there is no MERGE DEDUPLICATE statement.
Option D appends all the rows from table_bronze into table_silver, without removing any duplicates. Option E overwrites the existing data in table_silver with the data from table_bronze, without removing any duplicates. References: Delete Duplicate using SPARK SQL, Spark SQL - How to Remove Duplicate Rows
19. Frage
A data team has been given a series of projects by a consultant that need to be implemented in the Databricks Lakehouse Platform.
Which of the following projects should be completed in Databricks SQL?
Antwort: C
Begründung:
Databricks SQL is a service that allows users to query data in the lakehouse using SQL and create visualizations and dashboards1. One of the common use cases for Databricks SQL is to combine data from different sources and formats into a single, comprehensive dataset that can be used for further analysis or reporting2. For example, a data analyst can use Databricks SQL to join data from a CSV file and a Parquet file, or from a Delta table and a JDBC table, and create a new table or view that contains the combined data3.
This can help simplify the data management and governance, as well as improve the data quality and consistency. References:
* Databricks SQL overview
* Databricks SQL use cases
* Joining data sources
20. Frage
A data analyst has been asked to count the number of customers in each region and has written the following query: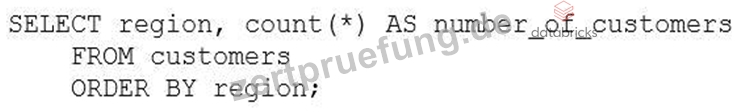
If there is a mistake in the query, which of the following describes the mistake?
Antwort: D
Begründung:
In the provided SQL query, the data analyst is trying to count the number of customers in each region.
However, they made a mistake by not including the "GROUP BY" clause to group the results by region.
Without this clause, the query will not return counts for each distinct region but rather an error or incorrect result. References: The need for a GROUP BY clause in such queries can be understood from Databricks SQL documentation: Databricks SQL.
I also noticed that you uploaded an image with your question. The image shows a snippet of an SQL query written in plain text on a white background. The query is attempting to select regions and count customers from a "customers" table and order the results by region. There's no visible syntax highlighting or any other color - it's monochromatic. The query is the same as the one in your question. I'm not sure why you included the image, but maybe you wanted to show me the exact format of your query. If so, you can also use code blocks to display formatted content such as SQL queries. For example, you can write:
SELECT region, count(*) AS number_of_customers
FROM customers
ORDER BY region;
This way, you can avoid uploading images and make your questions more clear and concise. I hope this helps.
#
21. Frage
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every 10 minutes.
A data analyst has created a dashboard based on this gold level data. The project stakeholders want to see the results in the dashboard updated within 10 minutes or less of new data becoming available within the gold- level tables.
What is the ability to ensure the streamed data is included in the dashboard at the standard requested by the project stakeholders?
Antwort: D
Begründung:
In this scenario, the data engineering team has configured a Structured Streaming pipeline that updates the gold-level tables every 10 minutes. To ensure that the dashboard reflects the most recent data, it is essential to set the dashboard ' s refresh schedule to an interval of 10 minutes or less. This synchronization ensures that stakeholders view the latest information shortly after it becomes available in the gold-level tables. Options B, C, and D do not directly address the requirement of aligning the dashboard refresh frequency with the data update interval.
22. Frage
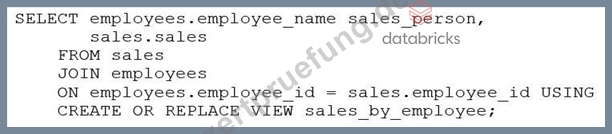
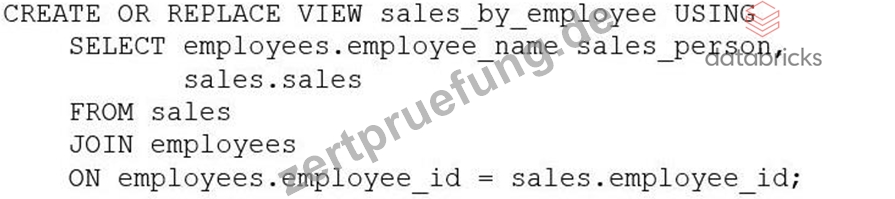
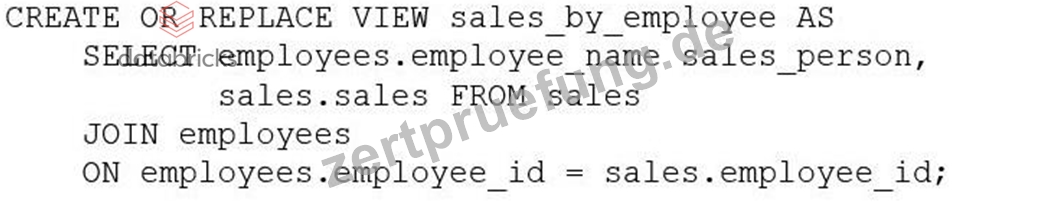
A business analyst has been asked to create a data entity/object called sales_by_employee. It should always stay up-to-date when new data are added to the sales table. The new entity should have the columns sales_person, which will be the name of the employee from the employees table, and sales, which will be all sales for that particular sales person. Both the sales table and the employees table have an employee_id column that is used to identify the sales person.
Which of the following code blocks will accomplish this task?
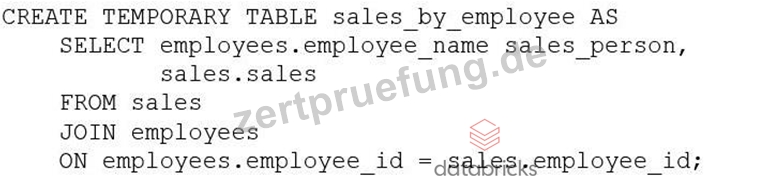
Antwort: C
Begründung:
The SQL code provided in Option D is the correct way to create a view named sales_by_employee that will always stay up-to-date with the sales and employees tables. The code uses the CREATE OR REPLACE VIEW statement to define a new view that joins the sales and employees tables on the employee_id column. It selects the employee_name as sales_person and all sales for each employee, ensuring that the data entity/object is always up-to-date when new data are added to these tables.
23. Frage
......
Die Databricks Databricks-Certified-Data-Analyst-Associate Zertifizierungsprüfung wird jetzt immer populärer. Es gibt viele verschiedene IT-Zertifizierungsprüfungen. Welche Prüfung haben Sie abgelegt? Lassen Wir hier Databricks Databricks-Certified-Data-Analyst-Associate Zertifizierungsprüfung als Beispiel erklären. Wenn Sie an der Databricks-Certified-Data-Analyst-Associate Prüfung teilnehmen, Databricks Databricks-Certified-Data-Analyst-Associate Dumps von Zertpruefung Ihnen helfen, sehr leicht die Prüfung zu bestehen.
Databricks-Certified-Data-Analyst-Associate Musterprüfungsfragen: https://www.zertpruefung.de/Databricks-Certified-Data-Analyst-Associate_exam.html
Außerdem sind jetzt einige Teile dieser Zertpruefung Databricks-Certified-Data-Analyst-Associate Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1jOCtJOQxBeCOrvFfgy5R6lUJNoNuK0VW