More and more people look forward to getting the 3V0-12.26 certification by taking an exam. However, the exam is very difficult for a lot of people. Especially if you do not choose the correct study materials and find a suitable way, it will be more difficult for you to pass the exam and get the 3V0-12.26 related certification. If you want to get the related certification in an efficient method, please choose the 3V0-12.26 Study Materials from our company. We can guarantee that the study materials from our company will help you pass the exam and get the certification in a relaxed and efficient method.
| Section | Objectives |
|---|---|
| Topic 1: Network Architecture (NSX) | - NSX design principles
|
| Topic 2: Storage Architecture (vSAN) | - vSAN design and configuration
|
| Topic 3: Lifecycle Management and Operations | - VCF lifecycle management
|
| Topic 4: VMware Cloud Foundation Architecture and Design Principles | - Cloud Foundation reference architecture
|
| Topic 5: vSphere and Compute Architecture | - Cluster design and resource management
|
| Topic 6: Availability, Resiliency, and Disaster Recovery | - High availability design
|
Hundreds of applicants who register themselves for the Advanced VMware Cloud Foundation 9.0 Architect (3V0-12.26) certification exam, lack updated practice test questions to prepare successfully in a short time. As a result of which, they don't crack the Advanced VMware Cloud Foundation 9.0 Architect (3V0-12.26) examination which causes a loss of time and money and sometimes loss of the encouragement to take the test for the second time. TestPassKing can save you from facing these issues with its real VMware 3V0-12.26 Exam Questions.
NEW QUESTION # 20
An architect is tasked with designing a VMware Cloud Foundation (VCF) architecture including multiple VKS clusters across different workload domains.
Security requirements mandate:
* Control plane isolation between tenant Kubernetes environments.
* No shared failure domains across tenants.
* Independent upgrade paths.
Given the requirements, which design approach meets these requirements?
Answer: B
Explanation:
D is correct. A dedicated Supervisor Cluster for each tenant establishes the strongest infrastructure and Kubernetes control-plane isolation. Each Supervisor has its own Kubernetes control plane and underlying vSphere infrastructure boundary, avoiding the shared control-plane dependency that would exist if multiple tenants used namespaces on the same Supervisor.
This design also addresses the requirement for independent failure domains . A Supervisor deployed on separate workload-domain infrastructure can be associated with distinct vSphere clusters, networking, storage, and lifecycle boundaries. Consequently, failure or maintenance affecting one tenant ' s Supervisor does not inherently affect another tenant ' s Kubernetes control plane.
The independent-upgrade requirement is also significant. Broadcom documents Supervisor and VKS lifecycle operations at the Supervisor level , including compatibility validation between the Supervisor, VKS service, and workload-cluster Kubernetes releases. VKS service upgrades are activated on the relevant Supervisor, reinforcing the Supervisor as an important lifecycle boundary.
A and B are useful security controls but do not isolate Kubernetes control planes or infrastructure failure domains. C provides namespace-level tenancy, but all namespaces still depend on the same Supervisor control plane and its lifecycle , so it cannot satisfy the stated isolation and independent-upgrade requirements.
Study Guide References/Topics: VCF VKS Architecture; Supervisor Clusters; Workload Domains; Tenant Isolation; Kubernetes Control-Plane Isolation; Failure Domains; Supervisor and VKS Lifecycle Management.
NEW QUESTION # 21
An architect is designing a VMware Cloud Foundation (VCF) infrastructure Virtual Private Cloud (VPC) IP Address Management (IPAM) Model. An architect recognizes a potential problem with maximum Private TGW blocks.
What is the maximum Private TGW IP blocks in a connectivity profile?
Answer: D
Explanation:
The correct limit is up to five Private Transit Gateway (TGW) IP blocks per VPC Connectivity Profile .
In the VCF 9 Virtual Networking Technical Reference, the IPAM model defines how address pools are exposed to VPCs. A VPC Connectivity Profile can contain both External IP Blocks and Private TGW IP Blocks , with each category supporting up to five IP blocks . The guide states that Private TGW blocks are assigned through the connectivity profile and are then used to allocate address space for Private-TGW subnets. ( Higher Logic Download ) Private-TGW addressing is scoped to the Transit Gateway and is particularly useful when multiple VPCs within the same NSX Project need routed communication with each other while keeping that address space private from external networks. The block is shared at the project/TGW level, and individual VPC subnets consume CIDRs from the available Private TGW blocks.
Therefore, an architect must account for the five-block maximum when planning IP address hierarchy, future subnet growth, aggregation strategy, and multi-tenant VPC expansion. If more address space is anticipated, the architect should choose sufficiently large, non-overlapping blocks from the outset rather than assuming an unlimited number of blocks can later be attached.
Study Guide References/Topics: VCF VPC IPAM; VPC Connectivity Profiles; Private Transit Gateway IP Blocks; Transit Gateway Networking; NSX VPC Address Management; IP Block Scalability.
NEW QUESTION # 22
An architect is designing a vSphere Kubernetes Service (VKS) solution that provides high availability for VKS Clusters.
The environment contains:
* One Workload Domain
* Three Clusters
* Six ESX hosts in each Cluster
* One vSphere Namespace across three vSphere Zones
The solution must provide cluster-level failure tolerance. In the event that one cluster goes offline, cluster- level failure tolerance must still be in place.
Which VKS Cluster design solution fits this requirement?
Answer: C
Explanation:
B is correct. In a multi-zone VKS design, the architect should explicitly map vSphere Zones to Kubernetes failure domains within the NodePools so that cluster nodes are distributed across independent infrastructure fault domains. This provides resilience against an entire underlying vSphere cluster or zone becoming unavailable.
Current Broadcom guidance for VKS multi-zone configurations confirms that a Node Pool can have an explicit failureDomain defined. In multi-zone environments, this allows the VKS topology controller to deterministically place nodes and their associated storage in the intended availability zone. Broadcom specifically documents explicit failure-domain configuration as the mechanism for controlling Node Pool placement in a multi-zone topology.
A is incorrect because worker nodes should not be assumed to be automatically balanced across independent vSphere Zones in a way that guarantees the required cluster-level failure tolerance.
C provides recovery from individual VM or ESXi host failure within an available vSphere cluster, but it cannot restart nodes when the entire underlying cluster or zone is offline.
D relates to Kubernetes service exposure and networking and has no bearing on failure-domain placement or infrastructure availability.
By explicitly assigning NodePools to separate failure domains, the design ensures surviving nodes remain available across the other zones after loss of one vSphere cluster.
Study Guide References/Topics: vSphere Kubernetes Service; VKS Multi-Zone Architecture; vSphere Zones; NodePools; Failure Domains; Cluster API Topology; Kubernetes High Availability.
NEW QUESTION # 23
An architect is responsible for designing a VMware Cloud Foundation (VCF) solution for a customer. The customer has provided the following requirements:
* There should be no single points of failure within the solution.
* The solution should survive the loss of any switch or networking interface card (NIC) with no downtime.
* The solution should survive the loss of any single host with minimal downtime.
* The solution should survive the loss of any rack with minimal downtime.
When documenting this design decision, which two consideration(s) should the architect make? (Choose two.)
Answer: B,C
Explanation:
B and E provide the required physical-network redundancy without introducing common single points of failure.
B is essential because NIC teaming should use uplinks located on different physical NIC cards . If both teamed ports reside on the same adapter, failure of that adapter, PCIe device, or associated hardware path can remove both uplinks simultaneously. Using separate physical adapters preserves connectivity when one NIC card fails. vSphere NIC teaming provides passive failover when one network adapter or network path becomes unavailable.
E is correct because each rack should contain redundant Top-of-Rack switches , with every ESX host connected to both switches. Loss or maintenance of one ToR therefore leaves the host connected through the surviving uplink and switch. Broadcom ' s operational guidance specifically validates redundant ToR designs by requiring each ESX host to have active uplinks to both ToR switches and confirming that traffic continues when either uplink is disabled.
C retains a NIC-card-level single point of failure. D creates a rack-level network failure domain. A requires cross-rack host cabling and is not the standard ToR redundancy pattern; rack resilience is achieved by distributing cluster hosts across racks while providing redundant ToRs within each rack.
Study Guide References/Topics: VCF Physical Network Design; NIC-Level Redundancy; NIC Teaming; Dual ToR Design; Rack Fault Domains; vSphere HA; Elimination of Single Points of Failure.
NEW QUESTION # 24
Match the definitions to the terms for MoSCoW ratings by dragging and dropping the Term on the left to the Definition on the right.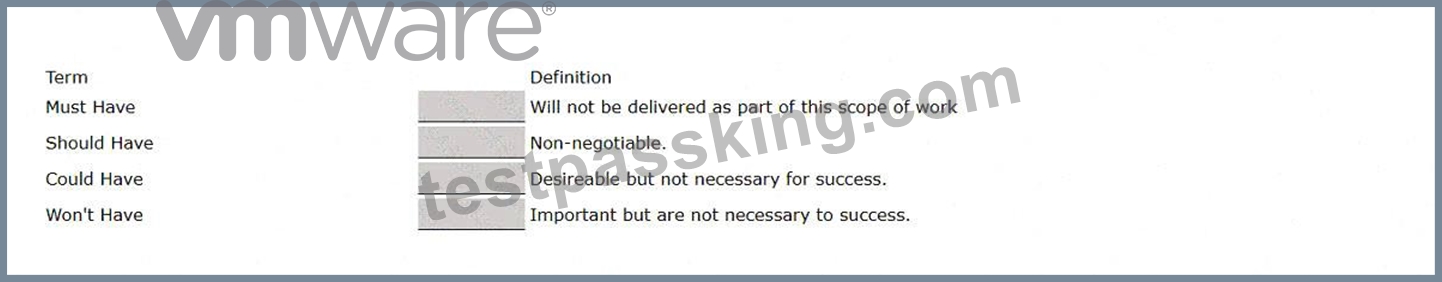
Answer:
Explanation:
Explanation:
Term
Correct Definition
Must Have
Non-negotiable.
Should Have
Important but are not necessary to success.
Could Have
Desirable but not necessary for success.
Won ' t Have
Will not be delivered as part of this scope of work.
The MoSCoW prioritization method classifies requirements according to how critical they are to the success and scope of a solution.
A Must Have requirement is non-negotiable . Failure to satisfy it means the solution does not meet an essential business or technical requirement.
A Should Have requirement is important and normally expected, but the project can still succeed without it if necessary. Such requirements may be deferred when schedule, cost, or resource constraints demand prioritization.
A Could Have requirement is desirable but has lower business impact. These capabilities are implemented when time and resources permit and can be removed from the current delivery with comparatively little effect on overall success.
A Won ' t Have requirement is explicitly excluded from the current scope. It is not necessarily permanently rejected; it may be reconsidered in a later phase or release.
For VCF architecture work, MoSCoW helps convert workshop findings into prioritized requirements and prevents optional functionality from competing with mandatory architectural objectives.
Study Guide References/Topics: Requirements Gathering; MoSCoW Prioritization; Conceptual Design; Business and Technical Requirements; Scope Management.
NEW QUESTION # 25
......
TestPassKing is professional platform to establish for compiling VMware exam materials for candidates, and we aim to help you to pass the examination as well as getting the related certification in a more efficient and easier way. Our answers and questions are compiled elaborately and easy to be mastered. Because our 3V0-12.26 Test Braindumps are highly efficient and the passing rate is very high you can pass the exam fluently and easily with little time and energy needed.
3V0-12.26 Valid Exam Sims: https://www.testpassking.com/3V0-12.26-exam-testking-pass.html