P.S. Kostenlose und neue Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Pass4Test verfügbar: https://drive.google.com/open?id=1NakZtXbtbAtTPCoKOaswLer851RDmHqD
Um die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung zu bestehen, ist es notwendig, geeignete Prüfungsmaterialien zu wählen. Unser Pass4Test bietet Ihnen die effiziente Materialien zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung. Die IT-Experten von Pass4Test sind alle erfahrungsreich. Die von ihnen erforschten Materialien sind den realen Prüfungsthemen fast gleich. Pass4Test ist eine Website, die den Kandidaten Bequemlichkeiten zur Zertifizierungsprüfung bietet und Ihnen helfen, die Google Professional-Machine-Learning-Engineer Prüfung zu bestehen.
| Section | Objectives |
|---|---|
| ML model development | - Evaluation
|
| Designing ML solutions | - ML architecture design
|
| Data preparation and processing | - Data ingestion and pipelines
|
| Deployment and operations | - Model deployment
|
| ML pipeline automation and orchestration | - Pipeline design
|
>> Professional-Machine-Learning-Engineer PDF <<
Die Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung von unserem Pass4Test können Ihre Kenntnisse während der Vorbereitungszeit prüfen und auch Ihre Leistungen innerhalb bestimmten Zeit bewerten. Unsere Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung sind das Ergebnis der langjährigen ständigen Untersuchung und Erforschung von den erfahrenen IT-Experten aus Pass4Test. Ihre Autorität ist über jeden Zweifel erhaben. Wenn Sie noch Befürchtungen haben, können Sie die kostenlose Demo herunterladen, dann entscheiden Sie sich, ob Sie Pass4Test wählen.
264. Frage
You have developed a BigQuery ML model that predicts customer churn and deployed the model to Vertex Al Endpoints. You want to automate the retraining of your model by using minimal additional code when model feature values change. You also want to minimize the number of times that your model is retrained to reduce training costs. What should you do?
Antwort: C
Begründung:
The best option for automating the retraining of your model by using minimal additional code when model feature values change, and minimizing the number of times that your model is retrained to reduce training costs, is to create a Vertex AI Model Monitoring job configured to monitor prediction drift, configure alert monitoring to publish a message to a Pub/Sub queue when a monitoring alert is detected, and use a Cloud Function to monitor the Pub/Sub queue, and trigger retraining in BigQuery. This option allows you to leverage the power and simplicity of Vertex AI, Pub/Sub, and Cloud Functions to monitor your model performance and retrain your model when needed. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can deploy a trained model to an online prediction endpoint, which can provide low-latency predictions for individual instances. Vertex AI can also provide various tools and services for data analysis, model development, model deployment, model monitoring, and model governance. A Vertex AI Model Monitoring job is a resource that can monitor the performance and quality of your deployed models on Vertex AI. A Vertex AI Model Monitoring job can help you detect and diagnose issues with your models, such as data drift, prediction drift, training/serving skew, or model staleness. Prediction drift is a type of model monitoring metric that measures the difference between the distributions of the predictions generated by the model on the training data and the predictions generated by the model on the online data. Prediction drift can indicate that the model performance is degrading, or that the online data is changing over time. By creating a Vertex AI Model Monitoring job configured to monitor prediction drift, you can track the changes in the model predictions, and compare them with the expected predictions. Alert monitoring is a feature of Vertex AI Model Monitoring that can notify you when a monitoring metric exceeds a predefined threshold. Alert monitoring can help you set up rules and conditions for triggering alerts, and choose the notification channel for receiving alerts. Pub/Sub is a service that can provide reliable and scalable messaging and event streaming on Google Cloud. Pub/Sub can help you publish and subscribe to messages, and deliver them to various Google Cloud services, such as Cloud Functions. A Pub/Sub queue is a resource that can hold messages that are published to a Pub/Sub topic. A Pub/Sub queue can help you store and manage messages, and ensure that they are delivered to the subscribers. By configuring alert monitoring to publish a message to a Pub/Sub queue when a monitoring alert is detected, you can send a notification to a Pub/Sub topic, and trigger a downstream action based on the alert. Cloud Functions is a service that can run your stateless code in response to events on Google Cloud. Cloud Functions can help you create and execute functions without provisioning or managing servers, and pay only for the resources you use. A Cloud Function is a resource that can execute a piece of code in response to an event, such as a Pub
/Sub message. A Cloud Function can help you perform various tasks, such as data processing, data transformation, or data analysis. BigQuery is a service that can store and query large-scale data on Google Cloud. BigQuery can help you analyze your data by using SQL queries, and perform various tasks, such as data exploration, data transformation, or data visualization. BigQuery ML is a feature of BigQuery that can create and execute machine learning models in BigQuery by using SQL queries. BigQuery ML can help you build and train various types of models, such as linear regression, logistic regression, k-means clustering, matrix factorization, and deep neural networks. By using a Cloud Function to monitor the Pub/Sub queue, and trigger retraining in BigQuery, you can automate the retraining of your model by using minimal additional code when model feature values change. You can write a Cloud Function that listens to the Pub/Sub queue, and executes a SQL query to retrain your model in BigQuery ML when a prediction drift alert is received. By retraining your model in BigQuery ML, you can update your model parameters and improve your model performance and accuracy 1 .
The other options are not as good as option C, for the following reasons:
* Option A: Enabling request-response logging on Vertex AI Endpoints, scheduling a TensorFlow Data Validation job to monitor prediction drift, and executing model retraining if there is significant distance between the distributions would require more skills and steps than creating a Vertex AI Model Monitoring job configured to monitor prediction drift, configuring alert monitoring to publish a message to a Pub/Sub queue when a monitoring alert is detected, and using a Cloud Function to monitor the Pub/Sub queue, and trigger retraining in BigQuery. Request-response logging is a feature of Vertex AI Endpoints that can record the requests and responses that are sent to and from the online prediction endpoint. Request-response logging can help you collect and analyze the online prediction data, and troubleshoot any issues with your model. TensorFlow Data Validation is a tool that can analyze and validate your data for machine learning. TensorFlow Data Validation can help you explore, understand, and clean your data, and detect various data issues, such as data drift, data skew, or data anomalies. Prediction drift is a type of data issue that measures the difference between the distributions of the predictions generated by the model on the training data and the predictions generated by the model on the online data. Prediction drift can indicate that the model performance is degrading, or that the online data is changing over time. By enabling request-response logging on Vertex AI Endpoints, and scheduling a TensorFlow Data Validation job to monitor prediction drift, you can collect and analyze the online prediction data, and compare the distributions of the predictions. However, enabling request-response logging on Vertex AI Endpoints, scheduling a TensorFlow Data Validation job to monitor prediction drift, and executing model retraining if there is significant distance between the distributions would require more skills and steps than creating a Vertex AI Model Monitoring job configured to monitor prediction drift, configuring alert monitoring to publish a message to a Pub/Sub queue when a monitoring alert is detected, and using a Cloud Function to monitor the Pub/Sub queue, and trigger retraining in BigQuery. You would need to write code, enable and configure the request- response logging, create and run the TensorFlow Data Validation job, define and measure the distance between the distributions, and execute the model retraining. Moreover, this option would not automate the retraining of your model, as you would need to manually check the prediction drift and trigger the retraining 2 .
* Option B: Enabling request-response logging on Vertex AI Endpoints, scheduling a TensorFlow Data Validation job to monitor training/serving skew, and executing model retraining if there is significant distance between the distributions would not help you monitor the changes in the model feature values, and could cause errors or poor performance. Training/serving skew is a type of data issue that measures the difference between the distributions of the features used to train the model and the features used to serve the model. Training/serving skew can indicate that the model is not trained on the representative data, or that the data is changing over time. By enabling request-response logging on Vertex AI Endpoints, and scheduling a TensorFlow Data Validation job to monitor training/serving skew, you can collect and analyze the online prediction data, and compare the distributions of the features. However, enabling request-response logging on Vertex AI Endpoints, scheduling a TensorFlow Data Validation job to monitor training/serving skew, and executing model retraining if there is significant distance between the distributions would not help you monitor the changes in the model feature values, and could cause errors or poor performance. You would need to write code, enable and configure the request-response logging, create and run the TensorFlow Data Validation job, define and measure the distance between the distributions, and execute the model retraining. Moreover, this option would not monitor the prediction drift, which is a more direct and relevant metric for measuring the model performance and quality 2 .
* Option D: Creating a Vertex AI Model Monitoring job configured to monitor training/serving skew, configuring alert monitoring to publish a message to a Pub/Sub queue when a monitoring alert is detected, and using a Cloud Function to monitor the Pub/Sub queue, and trigger retraining in BigQuery would not help you monitor the changes in the model feature values, and could cause errors or poor performance. Training/serving skew is a type of data issue that measures the difference between the distributions of the features used to train the model and the features used to serve the model. Training
/serving skew can indicate that the model is not trained on the representative data, or that the data is changing over time. By creating a Vertex AI Model Monitoring job configured to monitor training
/serving skew, you can track the changes in the model features, and compare them with the expected features. However, creating a Vertex AI Model Monitoring job configured to monitor training/serving skew, configuring alert monitoring to publish a message to a Pub/Sub queue when a monitoring alert is detected, and using a Cloud Function to monitor the Pub/Sub queue, and trigger retraining in BigQuery would not help you monitor the changes in the model feature values, and could cause errors or poor performance. You would need to write code, create and configure the Vertex AI Model Monitoring job, configure the alert monitoring, create and configure the Pub/Sub queue, and write a Cloud Function to trigger the retraining. Moreover, this option would not monitor the prediction drift, which is a more direct and relevant metric for measuring t he model performance and quality 1 .
References:
Preparing for Google Cloud Certification: Machine Learning Engineer , Course 3: Production ML Systems, Week 4: ML Governance Google Cloud Professional Machine Learning Engineer Exam Guide , Section 3: Scaling ML models in production
265. Frage
You are going to train a DNN regression model with Keras APIs using this code: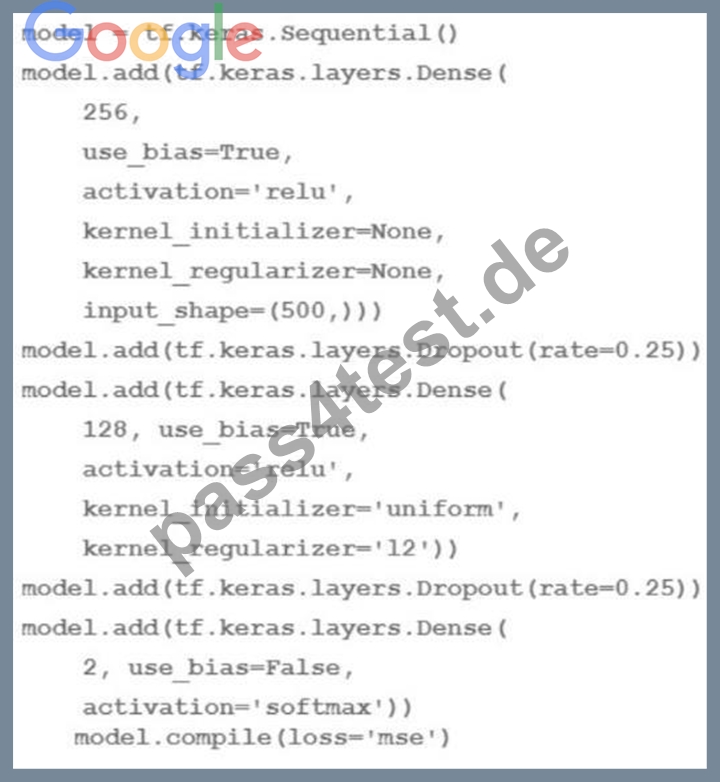
How many trainable weights does your model have? (The arithmetic below is correct.)
Antwort: A
Begründung:
The number of trainable weights in a DNN regression model with Keras APIs can be calculated by multiplying the number of input units by the number of output units for each layer, and adding the number of bias units for each layer. The bias units are usually equal to the number of output units, except for the last layer, which does not have bias units if the activation function is softmax1. In this code, the model has three layers: a dense layer with 256 units and relu activation, a dropout layer with 0.25 rate, and a dense layer with
2 units and softmax activation. The input shape is 500. Therefore, the number of trainable weights is:
* For the first layer: 500 input units * 256 output units + 256 bias units = 128256
* For the second layer: The dropout layer does not have any trainable weights, as it only randomly sets some of the input units to zero to prevent overfitting2.
* For the third layer: 256 input units * 2 output units + 0 bias units = 512 The total number of trainable weights is 128256 + 512 = 161024. Therefore, the correct answer is B.
References:
* How to calculate the number of parameters for a Convolutional Neural Network?
* Dropout (keras.io)
266. Frage
You have built a model that is trained on data stored in Parquet files. You access the data through a Hive table hosted on Google Cloud. You preprocessed these data with PySpark and exported it as a CSV file into Cloud Storage. After preprocessing, you execute additional steps to train and evaluate your model. You want to parametrize this model training in Kubeflow Pipelines. What should you do?
Antwort: A
Begründung:
The best option for parametrizing the model training in Kubeflow Pipelines is to add a ContainerOp to the pipeline that spins a Dataproc cluster, runs a transformation, and then saves the transformed data in Cloud Storage. This option has the following advantages:
* It allows the data transformation to be performed as part of the Kubeflow Pipeline, which can ensure the consistency and reproducibility of the data processing and the model training. By adding a ContainerOp to the pipeline, you can define the parameters and the logic of the data transformation step, and integrate it with the other steps of the pipeline, such as the model training and evaluation.
* It leverages the scalability and performance of Dataproc, which is a fully managed service that runs Apache Spark and Apache Hadoop clusters on Google Cloud. By spinning a Dataproc cluster, you can run the PySpark transformation on the Parquet files stored in the Hive table, and take advantage of the parallelism and speed of Spark. Dataproc also supports various features and integrations, such as autoscaling, preemptible VMs, and connectors to other Google Cloud services, that can optimize the data processing and reduce the cost.
* It simplifies the data storage and access, as the transformed data is saved in Cloud Storage, which is a scalable, durable, and secure object storage service. By saving the transformed data in Cloud Storage, you can avoid the overhead and complexity of managing the data in the Hive table or the Parquet files.
Moreover, you can easily access the transformed data from Cloud Storage, using various tools and frameworks, such as TensorFlow, BigQuery, or Vertex AI.
The other options are less optimal for the following reasons:
* Option A: Removing the data transformation step from the pipeline eliminates the parametrization of the model training, as the data processing and the model training are decoupled and independent. This option requires running the PySpark transformation separately from the Kubeflow Pipeline, which can introduce inconsistency and unreproducibility in the data processing and the model training. Moreover, this option requires managing the data in the Hive table or the Parquet files, which can be cumbersome and inefficient.
* Option B: Containerizing the PySpark transformation step, and adding it to the pipeline introduces additional complexity and overhead. This option requires creating and maintaining a Docker image that can run the PySpark transformation, which can be challenging and time-consuming. Moreover, this option requires running the PySpark transformation on a single container, which can be slow and inefficient, as it does not leverage the parallelism and performance of Spark.
* Option D: Deploying Apache Spark at a separate node pool in a Google Kubernetes Engine cluster, and adding a ContainerOp to the pipeline that invokes a corresponding transformation job for this Spark instance introduces additional complexity and cost. This option requires creating and managing a separate node pool in a Google Kubernetes Engine cluster, which is a fully managed service that runs Kubernetes clusters on Google Cloud. Moreover, this option requires deploying and running Apache Spark on the node pool, which can be tedious and costly, as it requires configuring and maintaining the Spark cluster, and paying for the node pool usage.
267. Frage
You are in the exploratory phase of development of a demand forecasting model. Several terabytes of historical sales and inventory records are stored in a BigQuery table. You need to create a new, clean table to perform preliminary analyses on metrics, such as moving averages of sales figures and weekly aggregates, without additional data movement. You want to use the simplest approach and minimize overhead. What should you do?
Antwort: B
Begründung:
BigQuery standard SQL can calculate moving averages with window functions, create weekly aggregates, and derive date-based features directly where the data resides. Materializing the query results into a new BigQuery table avoids data movement and additional ML or pipeline infrastructure, making it the simplest and lowest-overhead approach.
268. Frage
You are investigating the root cause of a misclassification error made by one of your models. You used Vertex Al Pipelines to tram and deploy the model. The pipeline reads data from BigQuery. creates a copy of the data in Cloud Storage in TFRecord format trains the model in Vertex Al Training on that copy, and deploys the model to a Vertex Al endpoint. You have identified the specific version of that model that misclassified: and you need to recover the data this model was trained on. How should you find that copy of the data ' ?
Antwort: C
Begründung:
* Option A is not the best answer because it requires modifying the pipeline to use the Vertex AI Feature Store, which may not be feasible or necessary for recovering the data that the model was trained on. The Vertex AI Feature Store is a service that helps you manage, store, and serve feature values for your machine learning models 1 , but it is not designed for storing the raw data or the TFRecord files.
* Option B is the best answer because it leverages the lineage feature of Vertex AI Metadata , which is a service that helps you track and manage the metadata of your machine learning workflows, such as datasets, models, metrics, and parameters 2 . The lineage feature allows you to view the relationships and dependencies among the artifacts and executions in your pipeline, and trace back the origin and history of any artifact 3 . By using the lineage feature, you can find the model artifact, determine the version of the model, identify the step that creates the data copy, and search in the metadata for its location.
* Option C is not the best answer because it relies on the logging features in the Vertex AI endpoint, which may not be accurate or reliable for finding the data copy. The logging features in the Vertex AI endpoint help you monitor and troubleshoot the onl ine predictions made by your deployed models, but they do not provide information about the training data or the pipeline steps 4 . Moreover, the timestamp of the model deployment may not match the timestamp of the pipeline run, as there may be delays or errors in the deployment process.
* Option D is not the best answer because it requires finding the job ID in Vertex AI Training, which may not be easy or straightforward. Vertex AI Training is a service that helps you train your custom models on Google Cloud, but it does not provide a direct way to link the training job to the model version or the pipeline run. Moreover, searching in the logs of the job may not reveal the location of the data copy, as the logs may only contain information about the training process and the metrics.
:
1 : Introduction to Vertex AI Feature Store | Vertex AI | Google Cloud
2 : Introduction to Vertex AI Metadata | Vertex AI | Google Cloud
3 : View lineage for ML workflows | Vertex AI | Google Cloud
4 : Monitor online predictions | Vertex AI | Google Cloud
[5]: Train custom models | Vertex AI | Google Cloud
269. Frage
......
Wir Pass4Test bieten Ihnen die Google Professional-Machine-Learning-Engineer Dumps mit der besten Qualität und die niedrigsten Kosten. Und es ist wichtiger, dass Pass4Test Ihnen den besten Service bieten. Solange Sie die Prüfungsunterlagen kaufen, können Sie sofort diese Unterlagen bekommen. Und Wir Pass4Test haben die Prüfungsunterlagen, die Sie am meisten wünschen und auch sehr geeignet. Außerdem können Sie nach dem Kauf einjährigen kostlosen Aktualisierungsservice bekommen. Innerhalb einem Jahr können Sie die neuste Version besitzen, solange Sie Ihre Google Professional-Machine-Learning-Engineer Prüfungsunterlagen aktualisieren wollen. Wir Pass4Test bemühen uns um Ihre Interesse und Bequemlichkeit.
Professional-Machine-Learning-Engineer Fragenkatalog: https://www.pass4test.de/Professional-Machine-Learning-Engineer.html
BONUS!!! Laden Sie die vollständige Version der Pass4Test Professional-Machine-Learning-Engineer Prüfungsfragen kostenlos herunter: https://drive.google.com/open?id=1NakZtXbtbAtTPCoKOaswLer851RDmHqD