P.S. Free & New Data-Engineer-Associate dumps are available on Google Drive shared by TestKingIT: https://drive.google.com/open?id=13Wc6dyYTXmM1UihsHajAWeUjbmX1hiZ3
You can directly refer our Amazon Data-Engineer-Associate study materials to prepare the exam. Once the newest test syllabus is issued by the official, our experts will quickly make a detailed summary about all knowledge points of the real Amazon Data-Engineer-Associate Exam in the shortest time. All in all, our Data-Engineer-Associate exam quiz will help you grasp all knowledge points.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Security and Governance | 18% | - Implement access control and authentication
- Enforce compliance and data governance
|
| Topic 2: Data Ingestion and Transformation | 34% | - Transform and enrich data
|
| Topic 3: Data Store Management | 26% | - Manage data lifecycle and storage tiers - Optimize storage performance and cost - Design and implement data storage solutions
|
| Topic 4: Data Operations and Support | 22% | - Backup, restore, and disaster recovery - Ensure reliability and scalability - Monitor and troubleshoot data pipelines
|
>> Practice Amazon Data-Engineer-Associate Exams <<
Practice tests are also a core part of the TestKingIT product. We recognize that retention of information is crucial, and interactive learning tools, such as practice exams are provided to help students retain the information they have learned. These Data-Engineer-Associate Practice Tests simulate the actual exam conditions and provide applicants with an accurate assessment of their readiness for the test.
NEW QUESTION # 174
A company has a data lake in Amazon S3. The company collects AWS CloudTrail logs for multiple applications. The company stores the logs in the data lake, catalogs the logs in AWS Glue, and partitions the logs based on the year. The company uses Amazon Athena to analyze the logs.
Recently, customers reported that a query on one of the Athena tables did not return any data. A data engineer must resolve the issue.
Which combination of troubleshooting steps should the data engineer take? (Select TWO.)
Answer: D,E
Explanation:
The problem likely arises from Athena not being able to read from the correct S3 location or missing partitions. The two most relevant troubleshooting steps involve checking the S3 location and repairing the table metadata.
* A. Confirm that Athena is pointing to the correct Amazon S3 location:
* One of the most common issues with missing data in Athena queries is that the query is pointed to an incorrect or outdated S3 location. Checking the S3 path ensures Athena is querying the correct data.
Reference:Amazon Athena Troubleshooting
C: Use the MSCK REPAIR TABLE command:
When new partitions are added to the S3 bucket without being reflected in the Glue Data Catalog, Athena queries will not return data from those partitions. The MSCK REPAIR TABLE command updates the Glue Data Catalog with the latest partitions.
Reference:MSCK REPAIR TABLE Command
Alternatives Considered:
B (Increase query timeout): Timeout issues are unrelated to missing data.
D (Restart Athena): Athena does not require restarting.
E (Delete and recreate table): This introduces unnecessary overhead when the issue can be resolved by repairing the table and confirming the S3 location.
References:
Athena Query Fails to Return Data
NEW QUESTION # 175
A company has used an Amazon Redshift table that is named Orders for 6 months. The company performs weekly updates and deletes on the table. The table has an interleaved sort key on a column that contains AWS Regions.
The company wants to reclaim disk space so that the company will not run out of storage space. The company also wants to analyze the sort key column.
Which Amazon Redshift command will meet these requirements?
Answer: D
Explanation:
Amazon Redshift is a fully managed, petabyte-scale data warehouse service that enables fast and cost- effective analysis of large volumes of data. Amazon Redshift uses columnar storage, compression, and zone maps to optimize the storage and performance of data. However, over time, as data is inserted, updated, or deleted, the physical storage of data can become fragmented, resulting in wasted disk space and degraded query performance. To address this issue, Amazon Redshift provides the VACUUM command, which reclaims disk space and resorts rows in either a specified table or all tables in the current schema1.
The VACUUM command has four options: FULL, DELETE ONLY, SORT ONLY, and REINDEX. The option that best meets the requirements of the question is VACUUM REINDEX, which re-sorts the rows in a table that has an interleaved sort key and rewrites the table to a new location on disk. An interleaved sort key is a type of sort key that gives equal weight to each column in the sort key, and stores the rows in a way that optimizes the performance of queries that filter by multiple columns in the sort key. However, as data is added or changed, the interleaved sort order can become skewed, resulting in suboptimal query performance. The VACUUM REINDEX option restores the optimal interleaved sort order and reclaims disk space by removing deleted rows. This option also analyzes the sort key column and updates the table statistics, which are used by the query optimizer to generate the most efficient query execution plan23.
The other options are not optimal for the following reasons:
* A. VACUUM FULL Orders. This option reclaims disk space by removing deleted rows and resorts the entire table. However, this option is not suitable for tables that have an interleaved sort key, as it does not restore the optimal interleaved sort order. Moreover, this option is the most resource-intensive and time-consuming, as it rewrites the entire table to a new location on disk.
* B. VACUUM DELETE ONLY Orders. This option reclaims disk space by removing deleted rows, but does not resort the table. This option is not suitable for tables that have any sort key, as it does not improve the query performance by restoring the sort order. Moreover, this option does not analyze the sort key column and update the table statistics.
* D. VACUUM SORT ONLY Orders. This option resorts the entire table, but does not reclaim disk space by removing deleted rows. This option is not suitable for tables that have an interleaved sort key, as it does not restore the optimal interleaved sort order.Moreover, this option does not analyze the sort key column and update the table statistics.
:
1: Amazon Redshift VACUUM
2: Amazon Redshift Interleaved Sorting
3: Amazon Redshift ANALYZE
NEW QUESTION # 176
A company stores customer data that contains personally identifiable information (PII) in an Amazon Redshift cluster. The company's marketing, claims, and analytics teams need to be able to access the customer data.
The marketing team should have access to obfuscated claim information but should have full access to customer contact information.
The claims team should have access to customer information for each claim that the team processes.
The analytics team should have access only to obfuscated PII data.
Which solution will enforce these data access requirements with the LEAST administrative overhead?
Answer: C
Explanation:
Step 1: Understand the Data Access Requirements
The question presents distinct access needs for three teams:
Marketing team: Needs full access to customer contact info but only obfuscated claim information.
Claims team: Needs access to customer information relevant to the claims they process.
Analytics team: Needs only obfuscated PII data.
These teams require different levels of access, and the solution needs to enforce data security while keeping administrative overhead low.
Step 2: Why Option B is Correct
Option B (Creating Views) is a common best practice in Amazon Redshift to restrict access to specific data without duplicating data or managing multiple clusters. By creating views:
You can define customized views of the data with obfuscated fields for the analytics team and marketing team while still providing full access where necessary.
Views provide a logical separation of data and allow Redshift administrators to grant access permissions based on roles or groups, ensuring that each team sees only what they are allowed to.
Obfuscation or masking of PII can be easily applied to the views by transforming or hiding sensitive data fields.
This approach avoids the complexity of managing multiple Redshift clusters or S3-based data lakes, which introduces higher operational and administrative overhead.
Step 3: Why Other Options Are Not Ideal
Option A (Separate Redshift Clusters) introduces unnecessary administrative overhead by managing multiple clusters. Maintaining several clusters for each team is costly, redundant, and inefficient.
Option C (Separate Redshift Roles) involves creating multiple roles and managing complex masking policies, which adds to administrative burden and complexity. While Redshift does support column-level access control, it's still more overhead than managing simple views.
Option D (Move to S3 and Lake Formation) is a more complex and heavy-handed solution, especially when the data is already stored in Redshift. Migrating the data to S3 and setting up a data lake with Lake Formation introduces significant operational complexity that isn't needed for this specific requirement.
Conclusion:
Creating views in Amazon Redshift allows for flexible, fine-grained access control with minimal overhead, making it the optimal solution to meet the data access requirements of the marketing, claims, and analytics teams.
NEW QUESTION # 177
A data engineer needs to create an Amazon Athena table based on a subset of data from an existing Athena table named cities_world. The cities_world table contains cities that are located around the world. The data engineer must create a new table named cities_us to contain only the cities from cities_world that are located in the US.
Which SQL statement should the data engineer use to meet this requirement?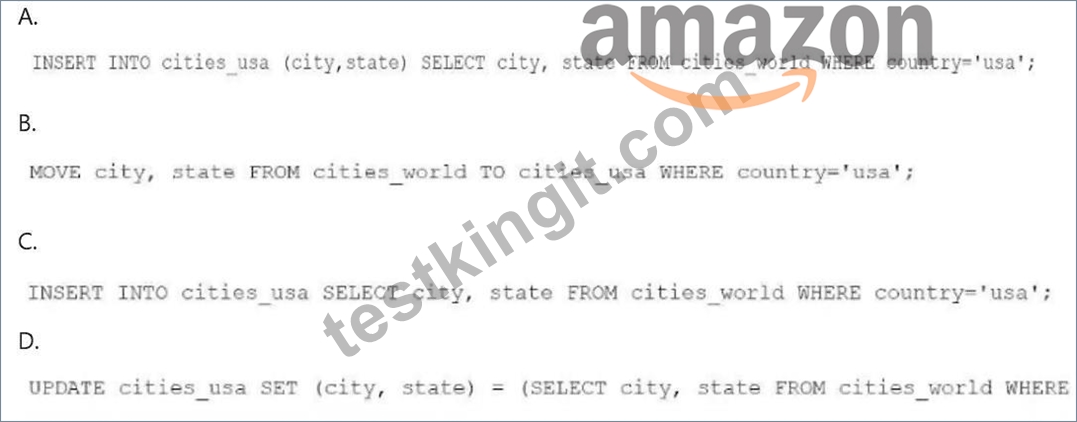
Answer: C
Explanation:
To create a new table named cities_usa in Amazon Athena based on a subset of data from the existing cities_world table, you should use an INSERT INTO statement combined with a SELECT statement to filter only the records where the country is ' usa ' . The correct SQL syntax would be:
Option A: INSERT INTO cities_usa (city, state) SELECT city, state FROM cities_world WHERE country= ' usa ' ;This statement inserts only the cities and states where the country column has a value of ' usa ' from the cities_world table into the cities_usa table. This is a correct approach to create a new table with data filtered from an existing table in Athena.
Options B, C, and D are incorrect due to syntax errors or incorrect SQL usage (e.g., the MOVE command or the use of UPDATE in a non-relevant context).
References:
Amazon Athena SQL Reference
Creating Tables in Athena
NEW QUESTION # 178
A data engineer needs to maintain a central metadata repository that users access through Amazon EMR and Amazon Athena queries. The repository needs to provide the schema and properties of many tables. Some of the metadata is stored in Apache Hive. The data engineer needs to import the metadata from Hive into the central metadata repository.
Which solution will meet these requirements with the LEAST development effort?
Answer: D
Explanation:
The AWS Glue Data Catalog is an Apache Hive metastore-compatible catalog that provides a central metadata repository for various data sources and formats. You can use the AWS Glue Data Catalog as an external Hive metastore for Amazon EMR and Amazon Athena queries, and import metadata from existing Hive metastores into the Data Catalog. This solution requires the least development effort, as you can use AWS Glue crawlers to automatically discover and catalog the metadata from Hive, and use the AWS Glue console, AWS CLI, or Amazon EMR API to configure the Data Catalog as the Hive metastore. The other options are either more complex or require additional steps, such as setting up Apache Ranger for security, managing a Hive metastore on an EMR cluster or an RDS instance, or migrating the metadata manually.
References:
* Using the AWS Glue Data Catalog as the metastore for Hive (Section: Specifying AWS Glue Data Catalog as the metastore)
* Metadata Management: Hive Metastore vs AWS Glue (Section: AWS Glue Data Catalog)
* AWS Glue Data Catalog support for Spark SQL jobs (Section: Importing metadata from an existing Hive metastore)
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide (Chapter 5, page 131)
NEW QUESTION # 179
......
TestKingIT provide high pass rate of the Data-Engineer-Associate exam materials that are compiled by experts with profound experiences according to the latest development in the theory and the practice so they are of great value. Please firstly try out our Data-Engineer-Associate training braindump before you decide to buy our Data-Engineer-Associate Study Guide as we have free demo on the web. It is worthy for you to buy our Data-Engineer-Associate exam preparation not only because it can help you pass the Data-Engineer-Associate exam successfully but also because it saves your time and energy.
Data-Engineer-Associate Valid Test Voucher: https://www.testkingit.com/Amazon/latest-Data-Engineer-Associate-exam-dumps.html
BONUS!!! Download part of TestKingIT Data-Engineer-Associate dumps for free: https://drive.google.com/open?id=13Wc6dyYTXmM1UihsHajAWeUjbmX1hiZ3