さらに、Xhs1991 DP-700ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=15_5c6w6ZKgE3fYLyCj6IrwsKQySWDqG8
MicrosoftのDP-700の認定試験証明書を取りたいなら、Xhs1991が貴方達を提供した資料をかったら、お得です。Xhs1991はもっぱら認定試験に参加するIT業界の専門の人士になりたい方のために模擬試験の練習問題と解答を提供した評判の高いサイトでございます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement and manage an analytics solution | 30-35% | - Implement lifecycle management and source control for analytics assets - Orchestrate processes with Data Factory pipelines - Configure and manage workspace settings and item access - Implement security and governance |
| Topic 2: Ingest and transform data | 30-35% | - Ingest data using Data Factory pipelines and Dataflows Gen2 - Design and implement loading patterns - Ingest and transform data using eventstreams - Optimize and manage Delta tables - Transform data using Dataflows Gen2 and notebooks |
| Topic 3: Monitor and optimize an analytics solution | 30-35% | - Implement error handling in pipelines - Optimize performance of data storage and queries - Monitor Fabric items |
時代の発展に伴い、人間的な文明が発展し、Xhs1991も発展しています。Xhs1991は君の早くMicrosoftのDP-700認定試験に合格するために、きみのもっと輝い未来のために、君の他人に羨ましいほど給料のために、ずっと努力しています。長年の努力を通じて、Xhs1991のMicrosoftのDP-700認定試験の合格率が100パーセントになっていました。Xhs1991を選ぶなら、成功を選ぶのに等しいです。
質問 # 129
You need to create the product dimension.
How should you complete the Apache Spark SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.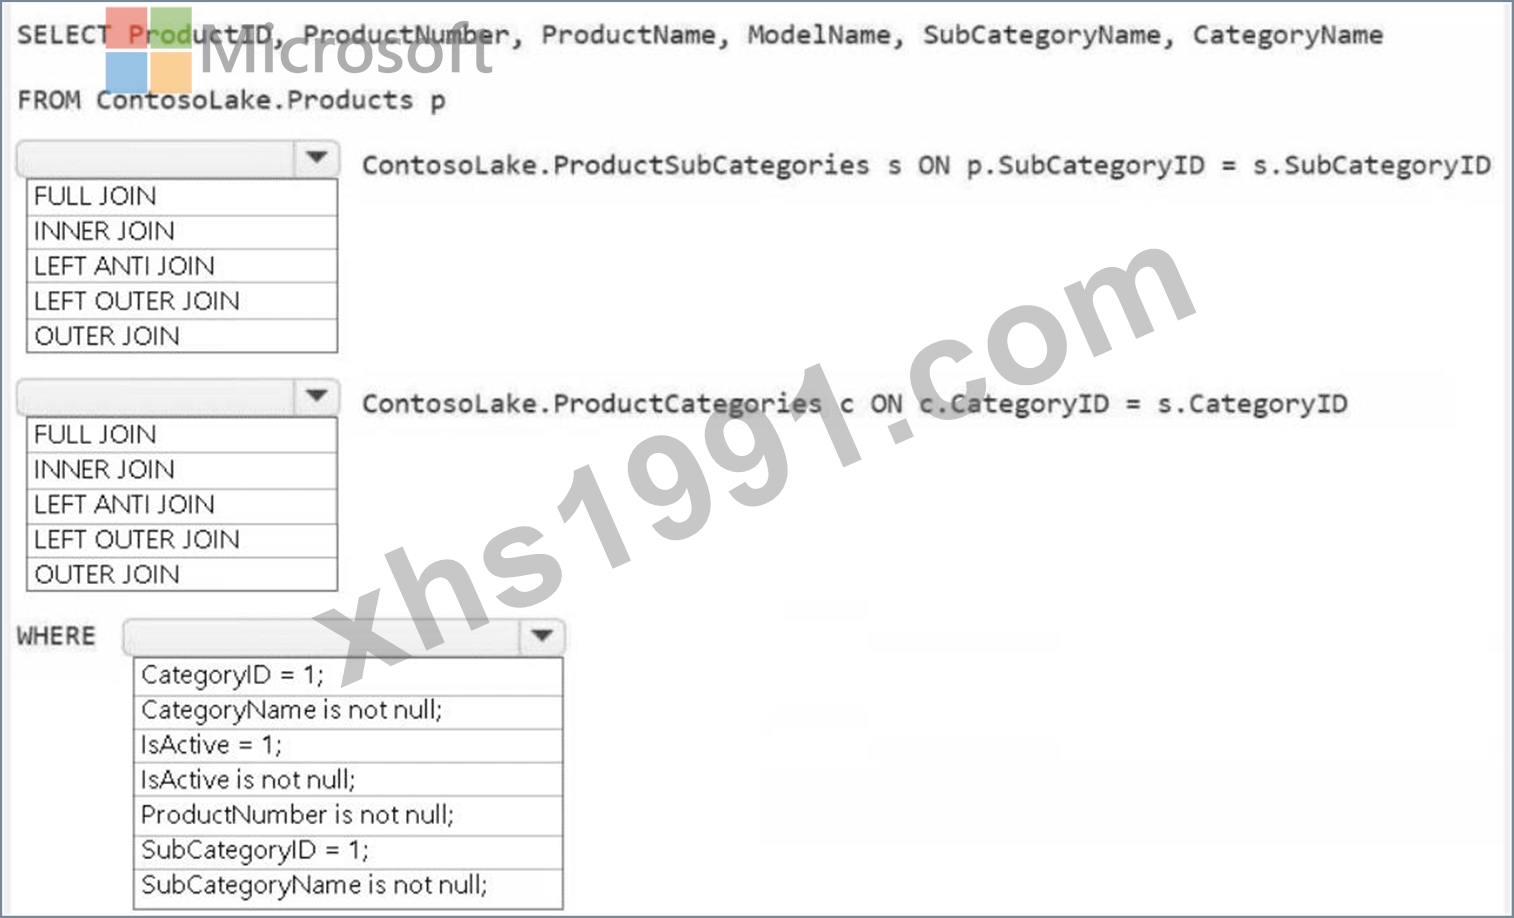
正解:
解説: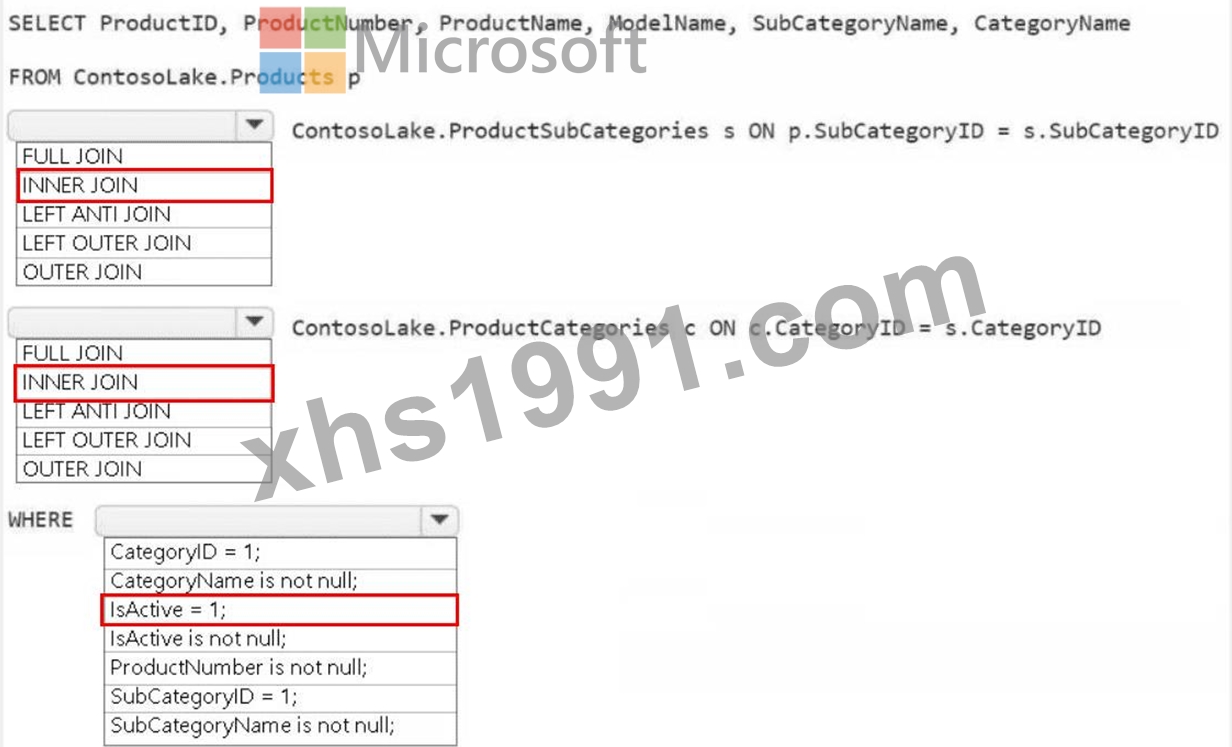
Topic 2, Litware, Inc
Overview
This is a case study. Case studies are not timed separately. You can use as much exam time as you would like to complete each case. However, there may be additional case studies and sections on this exam. You must manage your time to ensure that you are able to complete all questions included on this exam in the time provided.
To answer the questions included in a case study, you will need to reference information that is provided in the case study. Case studies might contain exhibits and other resources that provide more information about the scenario that is described in the case study. Each question is independent of the other questions in this case study.
At the end of this case study, a review screen will appear. This screen allows you to review your answers and to make changes before you move to the next section of the exam. After you begin a new section, you cannot return to this section.
To start the case study
To display the first question in this case study, click the Next button. Use the buttons in the left pane to explore the content of the case study before you answer the questions. Clicking these buttons displays information such as business requirements, existing environment, and problem statements. If the case study has an All Information tab, note that the information displayed is identical to the information displayed on the subsequent tabs. When you are ready to answer a question, click the Question button to return to the question.
Overview
Litware, Inc. is a publishing company that has an online bookstore and several retail bookstores worldwide. Litware also manages an online advertising business for the authors it represents.
Existing Environment. Fabric Environment
Litware has a Fabric workspace named Workspace1. High concurrency is enabled for Workspace1.
The company has a data engineering team that uses Python for data processing.
Existing Environment. Data Processing
The retail bookstores send sales data at the end of each business day, while the online bookstore constantly provides logs and sales data to a central enterprise resource planning (ERP) system.
Litware implements a medallion architecture by using the following three layers: bronze, silver, and gold. The sales data is ingested from the ERP system as Parquet files that land in the Files folder in a lakehouse. Notebooks are used to transform the files in a Delta table for the bronze and silver layers. The gold layer is in a warehouse that has V-Order disabled.
Litware has image files of book covers in Azure Blob Storage. The files are loaded into the Files folder.
Existing Environment. Sales Data
Month-end sales data is processed on the first calendar day of each month. Data that is older than one month never changes.
In the source system, the sales data refreshes every six hours starting at midnight each day.
The sales data is captured in a Dataflow Gen1 dataflow. When the dataflow runs, new and historical data is captured. The dataflow captures the following fields of the source:
Sales Date
Author
Price
Units
SKU
A table named AuthorSales stores the sales data that relates to each author. The table contains a column named AuthorEmail. Authors authenticate to a guest Fabric tenant by using their email address.
Existing Environment. Security Groups
Litware has the following security groups:
Sales
Fabric Admins
Streaming Admins
Existing Environment. Performance Issues
Business users perform ad-hoc queries against the warehouse. The business users indicate that reports against the warehouse sometimes run for two hours and fail to load as expected. Upon further investigation, the data engineering team receives the following error message when the reports fail to load: "The SQL query failed while running." The data engineering team wants to debug the issue and find queries that cause more than one failure.
When the authors have new book releases, there is often an increase in sales activity. This increase slows the data ingestion process.
The company's sales team reports that during the last month, the sales data has NOT been up-to-date when they arrive at work in the morning.
Requirements. Planned Changes
Litware recently signed a contract to receive book reviews. The provider of the reviews exposes the data in Amazon Simple Storage Service (Amazon S3) buckets.
Litware plans to manage Search Engine Optimization (SEO) for the authors. The SEO data will be streamed from a REST API.
Requirements. Version Control
Litware plans to implement a version control solution in Fabric that will use GitHub integration and follow the principle of least privilege.
Requirements. Governance Requirements
To control data platform costs, the data platform must use only Fabric services and items. Additional Azure resources must NOT be provisioned.
Requirements. Data Requirements
Litware identifies the following data requirements:
Process the SEO data in near-real-time (NRT).
Make the book reviews available in the lakehouse without making a copy of the data.
When a new book cover image arrives in the Files folder, process the image as soon as possible.
質問 # 130
You have a Fabric workspace that contains a lakehouse named Lakehouse1. Data is ingested into Lakehouse1 as one flat table. The table contains the following columns.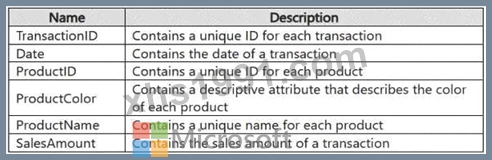
You plan to load the data into a dimensional model and implement a star schema. From the original flat table, you create two tables named FactSales and DimProduct. You will track changes in DimProduct.
You need to prepare the data.
Which three columns should you include in the DimProduct table? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:A、B、C
解説:
In a star schema, the DimProduct table serves as a dimension table that contains descriptive attributes about products. It will provide context for the FactSales table, which contains transactional data. The following columns should be included in the DimProduct table:
* ProductName: The ProductName is an important descriptive attribute of the product, which is needed for analysis and reporting in a dimensional model.
* ProductColor: ProductColor is another descriptive attribute of the product. In a star schema, it makes sense to include attributes like color in the dimension table to help categorize products in the analysis.
* ProductID: ProductID is the primary key for the DimProduct table, which will be used to join the FactSales table to the product dimension. It's essential for uniquely identifying each product in the model.
質問 # 131
You need to implement the solution for the book reviews.
Which should you do?
正解:A
解説:
The requirement specifies that Litware plans to make the book reviews available in the lakehouse without making a copy of the data. In this case, creating a shortcut in Fabric is the most appropriate solution. A shortcut is a reference to the external data, and it allows Litware to access the book reviews stored in Amazon S3 without duplicating the data into the lakehouse.
質問 # 132
HOTSPOT
You have a Fabric workspace that contains an eventstream named EventStream1.
You discover that an EventStream1 transformation fails.
You need to find the following error information:
The error details, including the occurrence time
The total number of errors
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.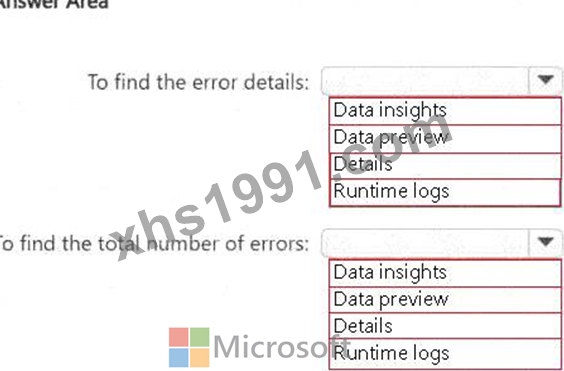
正解:
解説:
Explanation: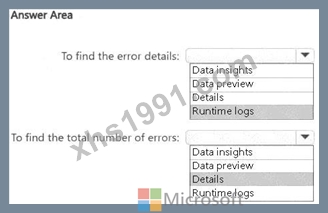
質問 # 133
You are implementing the following data entities in a Fabric environment:
Entity1: Available in a lakehouse and contains data that will be used as a core organization entity Entity2: Available in a semantic model and contains data that meets organizational standards Entity3: Available in a Microsoft Power BI report and contains data that is ready for sharing and reuse Entity4: Available in a Power BI dashboard and contains approved data for executive-level decision making Your company requires that specific governance processes be implemented for the data.
You need to apply endorsement badges to the entities based on each entity's use case.
Which badge should you apply to each entity? To answer, drag the appropriate badges the correct entities.
Each badge may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.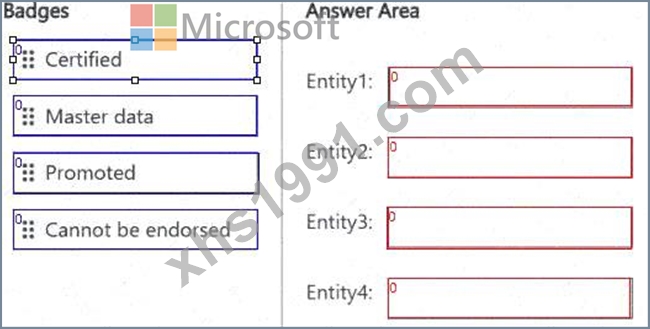
正解:
解説: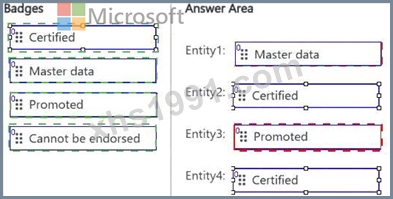
Explanation: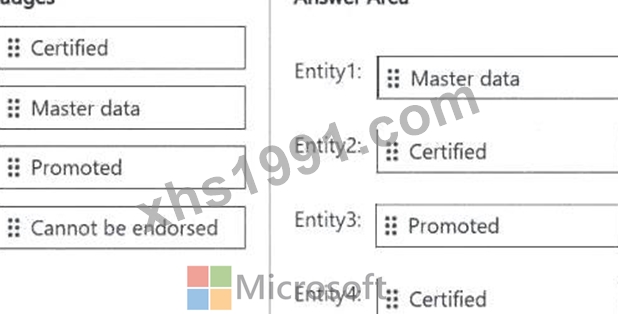
質問 # 134
......
我々のサイトであなたはMicrosoftに関する問題集を探すことができます。我々の専門家たちはあなたにMicrosoft認証に関する情報を提供します。我々の提供する資料を利用して、あなたは一回で試験に合格することができます。我々の最新のDP-700資料はあなたの復習に悩みを減ることができます。
DP-700最新知識: https://www.xhs1991.com/DP-700.html
P.S. Xhs1991がGoogle Driveで共有している無料かつ新しいDP-700ダンプ:https://drive.google.com/open?id=15_5c6w6ZKgE3fYLyCj6IrwsKQySWDqG8