100% Pass Professional Snowflake - SPS-C01 - Valid Dumps Snowflake Certified SnowPro Specialty - Snowpark Sheet

BONUS!!! Download part of PracticeVCE SPS-C01 dumps for free: https://drive.google.com/open?id=1khBEl9dVgDeWlkbDvClGN5UQMY4dDsJ9
I think these smart tips will help you to study well for the exam and get a brilliant score without any confusion. To get the Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 practice test, find a reliable source that provides the SPS-C01 Exam Dumps to their clients. Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 certification exams are not easy but quite tricky to know whether the applicant has complete knowledge regarding the subject or not.
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Session management and connection
- 1. Create and configure Snowpark sessions
- 2. Authentication and connection settings
- Snowpark architecture and execution model
- 1. Transformations vs actions
- 2. Lazy evaluation and DAG execution
- 3. Client-side vs server-side processing
|
| Topic 2: Snowpark API and Development | 30% | - Multi-language support
- 1. Java and Scala API basics
- 2. Environment setup and dependencies
- Python API fundamentals
- 1. Column operations and functions
- 2. Data persistence and writing results
- 3. DataFrame creation from tables, views, SQL
|
| Topic 3: Performance and Best Practices | 10% | - Security and governance
- 1. Access control and permissions
- 2. Data protection and compliance
- Optimization techniques
- 1. Query pushdown and execution plans
- 2. Caching and warehouse sizing
- 3. Minimizing data movement
|
| Topic 4: Data Transformations and Operations | 35% | - User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
- DataFrame manipulation
- 1. Selection, projection, renaming, casting
- 2. Joins, unions, set operations
- 3. Filtering, sorting, grouping, aggregation
- Advanced operations
- 1. Window functions and analytics
- 2. Pivot and unpivot transformations
- 3. Semi-structured data processing
|
>> Valid Dumps SPS-C01 Sheet <<
Real Snowflake SPS-C01 PDF Questions [2026]-The Greatest Shortcut Towards Success
There are three versions of our SPS-C01 learning engine which can allow all kinds of our customers to use conveniently in different situations. They are the PDF, Software and APP online versions. I specially recomend the APP online version of our SPS-C01 Exam Dumps. With the online app version of our SPS-C01 actual exam, you can just feel free to practice the questions in our SPS-C01 training materials on all kinds of electronic devices, such as IPAD, telephone, computer and so on!
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q26-Q31):
NEW QUESTION # 26
You are tasked with processing a large number of PDF files stored in an external stage named Each PDF contains scanned receipts, and you need to extract the total amount from each receipt. You plan to use Snowpark Python, SnowflakeFile object, and an OCR (Optical Character Recognition) library for text extraction. Assuming you have already set up the connection and session, what is the most efficient and secure way to read and process these PDF files using Snowpark and SnowflakeFile, minimizing data transfer and maximizing parallelism?
- A. Define an external function that takes the path to a file on the stage as input, performs OCR using a cloud-based OCR service and stores the result in an intermediate database table, then create a Snowpark DataFrame to query extracted amounts. Use 'session-read-option('PATTERN', ' to generate the initial DataFrame.
- B. Use 'session.read.option('PATTERN', ' to load the PDF files as binary data into a Snowpark DataFrame. Then, define a UDF that takes the binary data as input, converts it to a 'SnowflakeFile' object within the UDF, performs OCR, and extracts the amount.
- C. Read all PDF files into a Pandas DataFrame, then iterate through the DataFrame, downloading each file using 'SnowflakeFile.gef , perform OCR, extract the amount, and finally create a Snowpark DataFrame with the extracted amounts.
- D. Create a UDF that accepts a 'SnowflakeFile' object as input, performs OCR and amount extraction inside the UDF, and then call this UDF on a Snowpark DataFrame representing the files in the stage. Use 'session.read.option('PATTERN', ' to generate the initial DataFrame.
- E. List all files in the stage using 'session.sql('LlST iterate through the results, create a 'SnowflakeFile' object for each file path, download each file using 'SnowflakeFile.get' into the client machine, perform OCR, extract the amount, and create a Snowpark DataFrame with the extracted amounts.
Answer: D
Explanation:
Option B is the most efficient and secure approach. By creating a UDF that accepts a 'SnowflakeFile' object, the OCR processing happens within the Snowflake environment, close to the data. This minimizes data transfer out of Snowflake, improving performance and security. Using 'session-read-option('PATTERN', ' (with a dummy CSV format) is a clever way to create an initial DataFrame with file metadata for the UDF to operate on. Option A is inefficient as it transfers all PDFs to the client machine for processing. Option C requires converting binary data back to SnowflakeFile object inside UDF, which is not the intended use and might introduce complexity. Option D is highly inefficient and insecure as it involves downloading all files to the client, defeating the purpose of Snowpark. Option E, while using a cloud-based OCR service, adds complexity and dependency to external services.
NEW QUESTION # 27
You are building a Snowpark Python application to perform complex data transformations and want to leverage external packages not pre-installed in the Snowflake environment. You need to ensure these packages are available within your Snowpark session. Which of the following methods are valid for deploying and using these third-party packages within your Snowpark Python environment? (Select TWO)
- A. Manually install the packages on the Snowflake compute pool nodes before starting the Snowpark session.
- B. Deploy the required packages using the SnowCLl package management commands, and then the Snowpark session will be able to automatically use the deployed packages.
- C. Utilize Snowflake's Anaconda channel integration and specify the package names as strings in the method. Snowflake will automatically resolve and install the packages from the Anaconda channel.
- D. Create a 'conda' environment file ('environment.yml') specifying the required packages and use the method to upload the environment definition. Snowflake will automatically install the packages within the session's environment.
- E. Use the 'session.addDependency()' method to upload individual '.py' files containing the package code directly to the Snowflake internal stage.
Answer: C,D
Explanation:
Options B and D are the correct approaches for deploying and using external packages in Snowpark. Option B, using 'conda' environment files and , allows defining dependencies in a standard way. Option D, using with Snowflake's Anaconda integration, leverages Snowflake's managed environment. Option A is not the best and can lead to versioning issues. Option C is not possible as you don't have direct access to compute pool nodes. Option E relies on snowCLl, which is related to using the packages in UDFs and procedures, not necessarily for direct session use with external packages. Snowpark Sessions use to add packages directly.
NEW QUESTION # 28
Consider the following Snowpark Python code snippet designed to calculate a custom metric on financial data, using a vectorized UDF for performance. Identify potential performance bottlenecks and recommend optimization strategies.
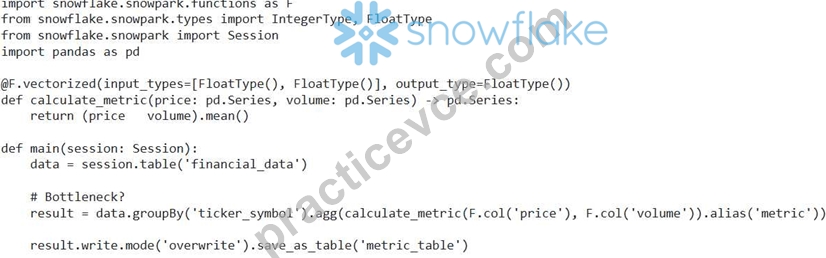
Which of the following actions (may be more than one) would MOST likely improve the performance of this Snowpark application?
- A. Ensure that the 'financial_data' table is clustered by 'ticker_symbor to optimize the 'groupBy' operation.
- B. Use to explicitly declare the Pandas dependency.
- C. Use before writing to the 'metric_table' , especially if the table is subsequently used downstream.
- D. Repartition the 'data' DataFrame by 'ticker_symbol' before the 'groupBy' operation using to improve data locality.
- E. Change 'FloatType' to 'DoubleType' as it provides more precision.
Answer: A,C,D
Explanation:
Clustering by 'ticker_symbol' significantly optimizes the 'groupBy' operation by organizing data physically for efficient retrieval. Caching the result before writing to a table is crucial if the intermediate result 'result' will be used multiple times, avoiding redundant computations. Repartitioning by 'ticker_symbol' before grouping helps distribute data evenly, improving parallelism and locality. While Pandas is generally available, explicitly declaring it might be necessary in certain isolated environments, so B can be considered a good practice, but not as impactful. Changing FloatType to DoubleType (C) will not lead to performnace improvement. It only changes precision level which is not required here.
NEW QUESTION # 29
You are working with a Snowpark application designed to process data from an event table. While testing a complex transformation involving several joins and window functions, you encounter the following error: 'java.lang.OutOfMemoryError: Java heap space'. The application uses Snowpark DataFrames and is running on a reasonably sized virtual warehouse. What is the MOST likely cause of this error in the context of Snowpark and Snowflake?
- A. An inefficient UDF (User-Defined Function) is consuming excessive memory within the Java runtime.
- B. The virtual warehouse is undersized for the volume of data being processed, leading to excessive spilling to disk and eventual memory exhaustion on the driver node.
- C. The Snowpark driver process is attempting to load the entire result set into memory, exceeding the available heap space.
- D. There's a circular dependency in the DataFrame transformations, causing an infinite loop and memory leak.
- E. Snowflake's internal query optimizer has generated a suboptimal execution plan, leading to excessive intermediate data materialization.
Answer: C
Explanation:
OutOfMemoryError in Snowpark is most often due to the driver process attempting to load a large result set into memory. Snowpark is designed to push down computations to Snowflake, but certain operations can force data to be collected on the driver. The correct response highlight this. While the other options might contribute, they are less likely to be the direct cause of a Java heap space error specifically.
NEW QUESTION # 30
You are working with a Snowpark DataFrame that contains product information including 'product_name' and 'description'. You need to create a new column named 'search_terms' that contains the first three words from the 'description' column, converted to lowercase. If the description has fewer than three words, the 'search_terms' column should contain all the words available. The words should be separated by a space. What is the MOST efficient way to achieve this using Snowpark?
Answer: A
Explanation:
Using a UDF (Option C) is a valid approach, but generally less efficient than leveraging built-in functions or existing Snowflake functions, especially for large datasets, because it involves serialization and deserialization between Python and Snowflake. Option A is not dynamic and will error on strings with fewer than three words. Option D will only correctly return the words if there are exactly three, otherwise it won 't match. E will just return the lowercased string and Snowflake UDF defined in SQL. Snowflake UDFs overhead, and are preferable for performance It is also less efficient than a UDF/Stored proc as it involves calling the Regex. Option is incorrect. Option B (UDF) is the most efficient, assuming GET FIRST THREE_WORDS is a are optimized for execution within the Snowflake environment, minimizing data transfer compared to Python UDFs in Snowpark.
NEW QUESTION # 31
......
Our SPS-C01 study materials are very popular in the international market and enjoy wide praise by the people in and outside the circle. We have shaped our SPS-C01 exam questions into a famous and top-ranking brand and we enjoy well-deserved reputation among the clients. Our SPS-C01 learning guide boosts many outstanding and superior advantages which other same kinds of exam materials don’t have. And we are very reliable in every aspect no matter on the quality or the according service.
Latest SPS-C01 Test Prep: https://www.practicevce.com/Snowflake/SPS-C01-practice-exam-dumps.html
- TOP Valid Dumps SPS-C01 Sheet - Trustable Snowflake Snowflake Certified SnowPro Specialty - Snowpark - Latest SPS-C01 Test Prep 👏 Search for ➤ SPS-C01 ⮘ and easily obtain a free download on ( www.vce4dumps.com ) 🤺SPS-C01 Valid Mock Test
- Free PDF Quiz Snowflake SPS-C01 Marvelous Valid Dumps Sheet 👓 Search for { SPS-C01 } and download it for free immediately on ➥ www.pdfvce.com 🡄 ✏SPS-C01 Valid Torrent
- Reliable SPS-C01 Exam Vce 🆑 SPS-C01 Reliable Test Duration 🧥 SPS-C01 Reliable Test Duration 🐰 Download 《 SPS-C01 》 for free by simply searching on ➠ www.examdiscuss.com 🠰 👷New SPS-C01 Exam Answers
- Snowflake SPS-C01 Exam Dumps - A Surefire Way To Achieve Success 🏸 Search for ➤ SPS-C01 ⮘ and easily obtain a free download on ( www.pdfvce.com ) 💚SPS-C01 Valid Torrent
- SPS-C01 Test Braindumps: Snowflake Certified SnowPro Specialty - Snowpark - SPS-C01 Pass-Sure Torrent - SPS-C01 Ttest Questions ⬛ Immediately open ➡ www.prepawayete.com ️⬅️ and search for ➽ SPS-C01 🢪 to obtain a free download 📷Reliable SPS-C01 Guide Files
- SPS-C01 Test Braindumps: Snowflake Certified SnowPro Specialty - Snowpark - SPS-C01 Pass-Sure Torrent - SPS-C01 Ttest Questions 📌 Easily obtain free download of ☀ SPS-C01 ️☀️ by searching on [ www.pdfvce.com ] 🛐Flexible SPS-C01 Learning Mode
- SPS-C01 Test Braindumps: Snowflake Certified SnowPro Specialty - Snowpark - SPS-C01 Pass-Sure Torrent - SPS-C01 Ttest Questions 🚾 Search for ✔ SPS-C01 ️✔️ and download it for free immediately on ▷ www.testkingpass.com ◁ 😙Free SPS-C01 Exam Questions
- Free PDF Quiz SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark –Professional Valid Dumps Sheet 🚋 Copy URL ⇛ www.pdfvce.com ⇚ open and search for ➡ SPS-C01 ️⬅️ to download for free 🏩SPS-C01 Frequent Updates
- Free SPS-C01 Exam Questions 🥦 Online SPS-C01 Training 📰 SPS-C01 Hottest Certification 📡 The page for free download of ➡ SPS-C01 ️⬅️ on { www.vce4dumps.com } will open immediately 💏SPS-C01 Testdump
- Snowflake SPS-C01 Exam Dumps - A Surefire Way To Achieve Success 🍄 Open website ▛ www.pdfvce.com ▟ and search for ▷ SPS-C01 ◁ for free download 🤠Valid SPS-C01 Exam Tips
- Latest SPS-C01 Dumps Free 🚰 New SPS-C01 Exam Answers 🤨 SPS-C01 Testdump 🛒 Search for 【 SPS-C01 】 and download exam materials for free through [ www.troytecdumps.com ] ⚔Reliable SPS-C01 Exam Pattern
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
What's more, part of that PracticeVCE SPS-C01 dumps now are free: https://drive.google.com/open?id=1khBEl9dVgDeWlkbDvClGN5UQMY4dDsJ9


