Failing to address these issues can result in wasted time and money. The ideal solution to overcome these challenges is to prepare with the latest and authentic DP-750 Exam Questions. Fortunately, there are trusted platforms like VCETorrent that provide up-to-date and Real DP-750 Questions for your preparation. To ensure your satisfaction, you can even try a free demo of Microsoft DP-750 questions before making a purchase.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
Choosing valid Microsoft dumps means closer to success. Before you buy our products, you can download the free demo of DP-750 test questions to check the accuracy of our dumps. Besides, there are 24/7 customer assisting to support you in case you may have any questions about DP-750 Dumps PDF or download link.
NEW QUESTION # 44
You need to configure resiliency for a job in Lakeflow Jobs named Job1 to meet the pipeline deployment and operation requirements.
What should you do?
Answer: A
Explanation:
Task-level retries allow the ingestion task to recover automatically from transient failures without rerunning unrelated tasks or restarting the complete workflow. Downstream tasks remain governed by their dependencies and start only after ingestion succeeds. This provides focused failure recovery and reduces unnecessary compute consumption. Disabling retries and relying on manual execution directly contradicts the requirement for resilient, automated pipeline operation. Setting the retry count to zero also prevents automatic retry behavior. Restarting the workflow from the first task whenever any task fails would repeat completed processing, increase costs, and potentially reingest data unnecessarily. Lakeflow Jobs supports individual retry policies for tasks, including the number of retries and delay between attempts, making option D the most controlled and operationally efficient configuration. Microsoft Learn
NEW QUESTION # 45
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to create a job in Lakeflow Jobs named Job1 that:
* Ingests data from cloud storage
* Runs two independent transformation tasks
The transformation tasks must run only after the ingestion completes and must run in parallel.
You need to design the task logic for Job1.
What should you configure?
Answer: C
Explanation:
Job1 should contain one ingestion task that acts as the common upstream dependency for two separate transformation tasks. Once ingestion succeeds, Lakeflow Jobs can start both downstream tasks concurrently because neither transformation depends on the other. This design represents the actual workflow, avoids duplicated ingestion, and reduces total execution time through parallelism. Creating two ingestion tasks would repeat the same source processing and could introduce inconsistent results or unnecessary costs. A single sequential task would prevent parallel transformation and make failures harder to isolate and retry. Defining three independent tasks without dependencies could allow transformations to start before ingestion has completed. An explicit directed task graph therefore provides the required execution order while preserving parallelism for independent downstream processing.
NEW QUESTION # 46
You have an Azure Databricks workspace that contains multiple all-purpose clusters.
You discover that some clusters remain idle for long periods after users finish their work.
You need to reduce compute costs without affecting active workloads.
What should you do?
Answer: D
Explanation:
To reduce compute costs from idle clusters without impacting active workloads, you must configure Auto-Termination and use Cluster Policies.
Core Remedies
*-> Auto-Termination: Set a strict inactivity timeout (e.g., 20-30 minutes) on all-purpose clusters to automatically shut them down when idle.
Cluster Policies: Enforce maximum auto-termination limits across the workspace so users cannot disable or set excessively long idle timeouts.
Single User Access Mode: Use this mode where possible, as it tracks idleness more accurately than Shared mode by monitoring the specific user's activity.
Reference:
https://medium.com/@sujathamudadla1213/databricks-lakehouse-platform-describe-how- clusters-are-terminated-and-the-impact-of-terminating-a-b6236689fd2e
NEW QUESTION # 47
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook 1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.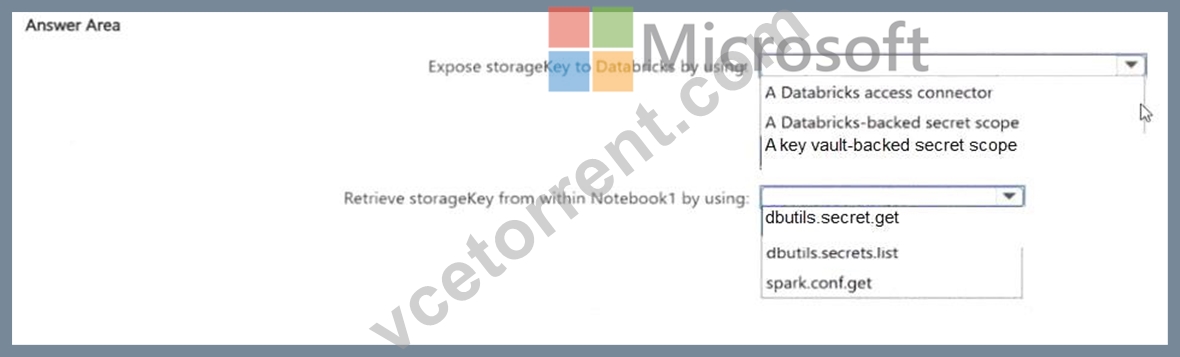
Answer:
Explanation: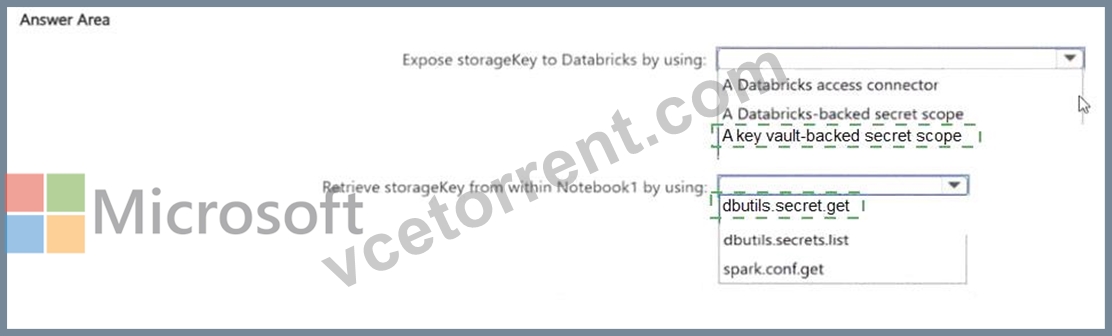
Explanation:
The solution is a Key Vault-backed secret scope combined with dbutils.secrets.get() in the notebook.
An Azure Key Vault-backed secret scope does not copy the secret value into Databricks. Every call to dbutils.
secrets.get() fetches the live current value directly from Key Vault at runtime. This means when the cloud security team rotates storageKey in Key Vault, the notebook automatically picks up the new value on its next run - no Databricks configuration changes needed. That satisfies 'always retrieve the latest value.' The principle of least privilege is upheld because only the secret scope has read access to Key Vault through a service principal or managed identity, and individual users never see the raw secret value - Databricks redacts it in logs automatically.
A Databricks-backed scope stores a copy of the secret inside Databricks, so it wouldn't automatically reflect Key Vault updates. Hardcoding or using environment variables would expose the secret in plain text.
Reference: https://learn.microsoft.com/en-us/azure/databricks/security/secrets/secret-scopes
NEW QUESTION # 48
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.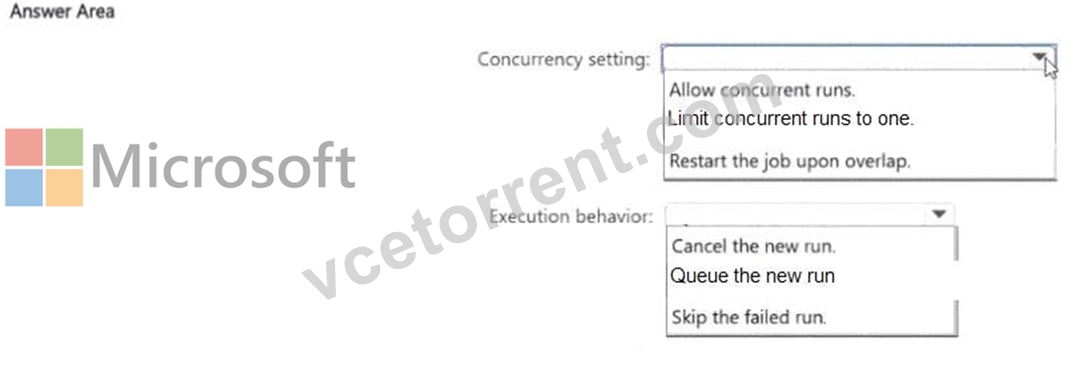
Answer:
Explanation: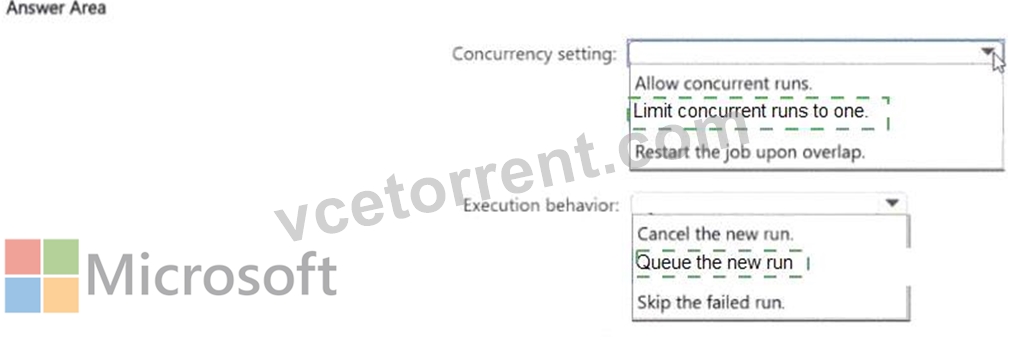
Explanation:
Two settings address the overlapping-run problem:
Concurrent Runs policy set to ' Skip ' (or ' Allow only one concurrent run ' ). When a new scheduled trigger fires while the previous run is still in progress, the new run is skipped rather than starting alongside the ongoing one. This prevents two runs from writing to the same tables at the same time - which is the data corruption risk the question highlights.
Cron-based schedule for the hourly trigger. A cron expression defines the regular execution cadence.
Combined with the concurrency setting, the job runs hourly but never overlaps.
An alternative to ' Skip ' is ' Wait ' (queue the new run), which ensures every scheduled run eventually executes - but for this scenario where overlapping is the primary concern, skipping the missed run is typically preferable to building up a queue of back-to-back executions.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#concurrent-runs
NEW QUESTION # 49
......
Business Applications DP-750 braindumps as your DP-750 exam prep material, we guarantee your success in the first attempt. If you do not pass the Implementing Data Engineering Solutions Using Azure Databricks DP-750 certification exam on your first attempt we will give you a full refound of your purchasing fee. If you purchase Microsoft Certified: Fabric Data Engineer Associate: Business Applications DP-750 Braindumps, you can enjoy the upgrade the exam question material service for free in one year.
Premium DP-750 Exam: https://www.vcetorrent.com/DP-750-valid-vce-torrent.html