According to the research of the past exams and answers, TrainingDump provide you the latest Databricks Databricks-Certified-Professional-Data-Engineer exercises and answers, which have have a very close similarity with real exam. TrainingDump can promise that you can 100% pass your first time to attend Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Related Certifications: | Databricks Certified Associate Data Engineer |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple Choice |
| Exam Duration: | 120 minutes |
| Passing Score: | 70% |
| Exam Price: | USD 200 |
| Available Languages: | Portuguese (Brazil), Japanese, Korean, English |
| Real Exam Qty: | 59 |
| Recommended Training: | Databricks Data Engineer Professional Training |
| Exam Registration: | Databricks Official Certification Registration |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored or onsite test center |
| Pre Condition: | No mandatory prerequisites; 1+ year hands-on experience and related training highly recommended |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/data-engineer-professional |
>> Databricks-Certified-Professional-Data-Engineer Reliable Exam Braindumps <<
As we all know, it is a must for all of the candidates to pass the exam if they want to get the related Databricks-Certified-Professional-Data-Engineer certification which serves as the best evidence for them to show their knowledge and skills. If you want to simplify the preparation process, here comes a piece of good news for you. Our Databricks-Certified-Professional-Data-Engineer Exam Question has been widely praised by all of our customers in many countries and our company has become the leader in this field. Now I would like to give you some detailed information about the advantages of our Databricks-Certified-Professional-Data-Engineer guide torrent.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) Certification Exam is a highly respected credential within the data engineering industry. Databricks Certified Professional Data Engineer Exam certification is specifically designed for professionals who have a deep understanding of data engineering principles, practices, and technologies. With this certification, data engineers can demonstrate their expertise in designing and building data pipelines, managing data workflows, and implementing data analytics solutions using Databricks.
NEW QUESTION # 21
A Delta Lake table was created with the below query: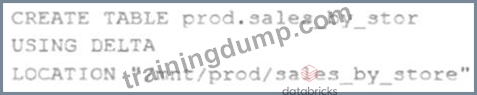
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: A
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An externaltable can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
NEW QUESTION # 22
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay." Exact extract: "Records older than the event-time watermark are considered late and may be dropped." Exact extract: "trigger(once) processes all available data once and then stops." The watermark of 2 hours bounds the deduplication state. Duplicate orders within the 2-hour window are removed; duplicates arriving later than 2 hours behind the corresponding first event are considered late and are ignored, so they won't appear, but any orders that themselves arrive later than the watermark will be dropped and thus be missing.
Reference:
NEW QUESTION # 23
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
Answer: A
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 24
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types.
What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables-it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to-Databricks sharing supports dynamic data sharing with update visibility and streaming reads. Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
NEW QUESTION # 25
A Databricks SQL dashboard has been configured to monitor the total number of records present in a collection of Delta Lake tables using the following query pattern:
SELECT COUNT (*) FROM table -
Which of the following describes how results are generated each time the dashboard is updated?
Answer: E
Explanation:
https://delta.io/blog/2023-04-19-faster-aggregations-metadata/#:~:text=You%20can%20get%20the%
20number,a%20given%20Delta%20table%20version.
NEW QUESTION # 26
......
Exam Databricks-Certified-Professional-Data-Engineer Price: https://www.trainingdump.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html