2026年CertJukenの最新KCNA PDFダンプおよびKCNA試験エンジンの無料共有:https://drive.google.com/open?id=1stEjy5Mj5XCqDqWp8zv6cEv-yFvstFaF
IT業種は急激に発展しているこの時代で、IT専門家を称賛しなければならないです。彼らは自身が持っている先端技術で色々な便利を作ってくれます。それに、会社に大量な人的·物的資源を節約させると同時に、案外のうまい効果を取得しました。彼らの給料は言うまでもなく高いです。そのような人になりたいのですか。羨ましいですか。心配することはないです。CertJukenのLinux FoundationのKCNAトレーニング資料はあなたに期待するものを与えますから。CertJukenを選ぶのは、成功を選ぶということになります。
| Certification Vendor: | Linux Foundation |
|---|---|
| Exam Name: | Kubernetes and Cloud Native Associate (KCNA) Exam |
| Exam Number: | KCNA |
| Real Exam Qty: | Approximately 60 |
| Exam Duration: | 90 minutes |
| Certificate Validity Period: | 3 years |
| Exam Format: | Multiple choice, Online proctored exam, Multiple select |
| Related Certifications: | Certified Kubernetes Application Developer (CKAD) Certified Kubernetes Administrator (CKA) Certified Kubernetes Security Specialist (CKS) |
| Available Languages: | English |
| Exam Price: | $250 USD |
| Passing Score: | 75% |
| Recommended Training: | Cloud Native Fundamentals / KCNA preparation courses Introduction to Kubernetes (LFS158) |
| Exam Registration: | Linux Foundation Certification Portal KCNA Exam Page |
| Sample Questions: | Linux Foundation KCNA Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No formal prerequisites; basic understanding of cloud, containers, and Kubernetes concepts is recommended |
| Official Syllabus URL: | https://training.linuxfoundation.org/certification/kubernetes-cloud-native-associate-kcna/ |
CertJukenは成立以来、ますます完全的な体系、もっと豊富な問題集、より安全的な支払保障、よりよいサービスを持っています。現在提供するLinux FoundationのKCNA試験の資料は多くのお客様に認可されました。ご購入のあとで我々はアフターサービスを提供します。あなたにLinux FoundationのKCNA試験のソフトの更新情況を了解させます。あなたは不幸で試験に失敗したら、我々は全額で返金します。
Linux FoundationのKCNA(Kubernetes and Cloud Native Associate)認定試験は、Kubernetesとクラウドネイティブ技術に関する知識とスキルを検証するグローバルに認められた認定プログラムです。Kubernetesは、コンテナ化されたアプリケーションの展開、スケーリング、管理を自動化するオープンソースのコンテナオーケストレーションシステムです。一方、クラウドネイティブ技術は、クラウドネイティブ環境でのアプリケーションの開発と展開を可能にするツールとプラクティスのセットを指します。
Linux Foundation KCNA(Kubernetes and Cloud Native Associate)認定試験は、Kubernetesとクラウドネイティブテクノロジーの分野の専門家のスキルと知識を検証する一般的な認定プログラムです。この認定試験は、Kubernetesとクラウドネイティブテクノロジーを使用して、スケーラブルで回復力のあるアプリケーションを開発、展開、および管理する候補者の習熟度をテストするように設計されています。
質問 # 54
What does vertical scaling an application deployment describe best?
正解:C
解説:
Vertical scaling means changing the resources allocated to a single instance of an application (more or less CPU/memory), which is why C is correct. In Kubernetes terms, this corresponds to adjusting container resource requests and limits (for CPU and memory). Increasing resources can help a workload handle more load per Pod by giving it more compute or memory headroom; decreasing can reduce cost and improve cluster packing efficiency.
This differs from horizontal scaling, which changes the number of instances (replicas). Option D describes horizontal scaling: adding/removing replicas of the same workload, typically managed by a Deployment and often automated via the Horizontal Pod Autoscaler (HPA). Option B describes scaling the infrastructure layer (nodes) which is cluster/node autoscaling (Cluster Autoscaler in cloud environments). Option A is not a standard scaling definition.
In practice, vertical scaling in Kubernetes can be manual (edit the Deployment resource requests/limits) or automated using the Vertical Pod Autoscaler (VPA), which can recommend or apply new requests based on observed usage. A key nuance is that changing requests/limits often requires Pod restarts to take effect, so vertical scaling is less "instant" than HPA and can disrupt workloads if not planned. That's why many production teams prefer horizontal scaling for traffic-driven workloads and use vertical scaling to right-size baseline resources or address memory-bound/cpu-bound behavior.
From a cloud-native architecture standpoint, understanding vertical vs horizontal scaling helps you design for elasticity: use vertical scaling to tune per-instance capacity; use horizontal scaling for resilience and throughput; and combine with node autoscaling to ensure the cluster has sufficient capacity. The definition the question is testing is simple: vertical scaling = change resources per application instance, which is option C.
質問 # 55
What is the main purpose of etcd in Kubernetes?
正解:D
解説:
The main purpose of etcd in Kubernetes is to store the cluster's state as a distributed key-value store, so A is correct. Kubernetes is API-driven: objects like Pods, Deployments, Services, ConfigMaps, Secrets, Nodes, and RBAC rules are persisted by the API server into etcd. Controllers, schedulers, and other components then watch the API for changes and reconcile the cluster accordingly. This makes etcd the "source of truth" for desired and observed cluster state.
Options B, C, and D are misconceptions. etcd does not store the running containers; that's the job of the kubelet/container runtime on each node, and container state is ephemeral. etcd does not store /etc configuration file copies. And while you may author objects as YAML manifests, Kubernetes stores them internally as API objects (serialized) in etcd-not as "YAML definitions for all components." The data is structured key/value entries representing Kubernetes resources and metadata.
Because etcd is so critical, its performance and reliability directly affect the cluster. Slow disk I/O or poor network latency increases API request latency and can delay controller reconciliation, leading to cascading operational problems (slow rollouts, delayed scheduling, timeouts). That's why etcd is typically run on fast, reliable storage and in an HA configuration (often 3 or 5 members) to maintain quorum and tolerate failures.
Backups (snapshots) and restore procedures are also central to disaster recovery: if etcd is lost, the cluster loses its state.
Security is also important: etcd can contain sensitive information (especially Secrets unless encrypted at rest).
Proper TLS, restricted access, and encryption-at-rest configuration are standard best practices.
So, the verified correct answer is A: etcd stores all cluster data/state in a key-value store.
=========
質問 # 56
How can persistent volume be provisioned?
正解:B
解説:
https://kubernetes.io/docs/concepts/storage/persistent-volumes/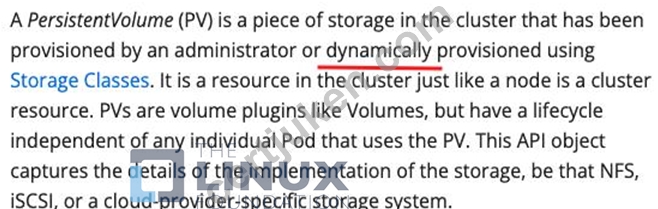
質問 # 57
CI/CD stands for:
正解:A
解説:
CI/CD is a foundational practice for delivering software rapidly and reliably, and it maps strongly to cloud native delivery workflows commonly used with Kubernetes. CI stands for Continuous Integration:
developers merge code changes frequently into a shared repository, and automated systems build and test those changes to detect issues early. CD is commonly used to mean Continuous Delivery or Continuous Deployment depending on how far automation goes. In many certification contexts and simplified definitions like this question, CD is interpreted as Continuous Deployment, meaning every change that passes the automated pipeline is automatically released to production. That matches option D.
In a Kubernetes context, CI typically produces artifacts such as container images (built from Dockerfiles or similar build definitions), runs unit/integration tests, scans dependencies, and pushes images to a registry. CD then promotes those images into environments by updating Kubernetes manifests (Deployments, Helm charts, Kustomize overlays, etc.). Progressive delivery patterns (rolling updates, canary, blue/green) often use Kubernetes-native controllers and Service routing to reduce risk.
Why the other options are incorrect: "Continuous Development" isn't the standard "D" term; it's ambiguous and not the established acronym expansion. "Cloud Integration/Cloud Development" is unrelated. Continuous Delivery (in the stricter sense) means changes are always in a deployable state and releases may still require a manual approval step, while Continuous Deployment removes that final manual gate. But because the option set explicitly includes "Continuous Deployment," and that is one of the accepted canonical expansions for CD, D is the correct selection here.
Practically, CI/CD complements Kubernetes' declarative model: pipelines update desired state (Git or manifests), and Kubernetes reconciles it. This combination enables frequent releases, repeatability, reduced human error, and faster recovery through automated rollbacks and controlled rollout strategies.
=========
質問 # 58
How is application data maintained in containers?
正解:D
解説:
Container filesystems are ephemeral: the writable layer is tied to the container lifecycle and can be lost when containers are recreated. Therefore, maintaining application data correctly means storing it in volumes, making D the correct answer. In Kubernetes, volumes provide durable or shareable storage that is mounted into containers at specific paths. Depending on the volume type, the data can persist across container restarts and even Pod rescheduling.
Kubernetes supports many volume patterns. For transient scratch data you might use emptyDir (ephemeral for the Pod's lifetime). For durable state, you typically use PersistentVolumes consumed by PersistentVolumeClaims (PVCs), backed by storage systems via CSI drivers (cloud disks, SAN/NAS, distributed storage). This decouples the application container image from its state and enables rolling updates, rescheduling, and scaling without losing data.
Options A and B ("folders") are incomplete because folders inside the container filesystem do not guarantee persistence. A folder is only as durable as the underlying storage; without a mounted volume, it lives in the container's writable layer and will disappear when the container is replaced. Option C is incorrect because
"sidecar containers" are not a data durability mechanism; sidecars can help ship logs or sync data, but persistent data should still be stored on volumes (or external services like managed databases).
From an application delivery standpoint, the principle is: containers should be immutable and disposable, and state should be externalized. Volumes (and external managed services) make this possible. In Kubernetes, this is a foundational pattern enabling safe rollouts, self-healing, and portability: the platform can kill and recreate Pods freely because data is maintained independently via volumes.
Therefore, the verified correct choice is D: Store data into volumes.
=========
質問 # 59
......
KCNAブロンズ教材: https://www.certjuken.com/KCNA-exam.html
ちなみに、CertJuken KCNAの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1stEjy5Mj5XCqDqWp8zv6cEv-yFvstFaF