P.S. Free & New Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by PDFBraindumps: https://drive.google.com/open?id=1YyIY7yMY9p5JMQ-UxqMeiB2POBbtIWGd
Here, we provide you with the best Databricks-Generative-AI-Engineer-Associate premium study files which will improve your study efficiency and give you right direction. The content of Databricks-Generative-AI-Engineer-Associate study material is the updated and verified by IT experts. Professional experts are arranged to check and trace the Databricks Databricks-Generative-AI-Engineer-Associate update information every day. The Databricks-Generative-AI-Engineer-Associate exam guide materials are really worthy of purchase. The high quality and accurate Databricks-Generative-AI-Engineer-Associate questions & answers are the guarantee of your success.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Databricks-Generative-AI-Engineer-Associate Exam Outline <<
Many candidates do not have actual combat experience, for the qualification examination is the first time to attend, they always feel aimless and worried about the Databricks-Generative-AI-Engineer-Associate exam very much. But we can help all of these candidates on Databricks-Generative-AI-Engineer-Associate study questions. Numerous grateful feedbacks form our loyal customers proved that we are the most popular vendor in this field to offer our Databricks-Generative-AI-Engineer-Associate preparation questions. You can totally relay on us.
NEW QUESTION # 34
A Generative AI Engineer is evaluating a customer-support agent in Databricks. The team needs to score each response on a domain-specific policy: the answer must cite an approved refund rule and must not mention unsupported escalation paths. Built-in evaluation metrics do not capture this logic. The team wants the metric to run during agent evaluation in Databricks and return a repeatable, structured score for each trace.
Which approach should the engineer use?
Answer: A
Explanation:
MLflow supports custom scorers for application-specific evaluation requirements that built-in metrics do not address. The engineer can define a scorer that examines the generated answer and, when necessary, the complete execution trace. It can verify references against an approved refund-rule list and check whether escalation statements violate the policy. The scorer returns structured feedback, such as a Boolean result, numerical score, or Feedback object, and is supplied to mlflow.genai.evaluate(). Deterministic checks are appropriate when repeatability is essential; semantic checks may require a carefully specified judge. Latency and token counts measure operational behavior rather than policy compliance. Reviewing traces manually does not create an automated metric, and the generating model's self-assessment is not an independent compliance evaluation. Databricks documentation
NEW QUESTION # 35
A company has a typical RAG-enabled, customer-facing chatbot on its website.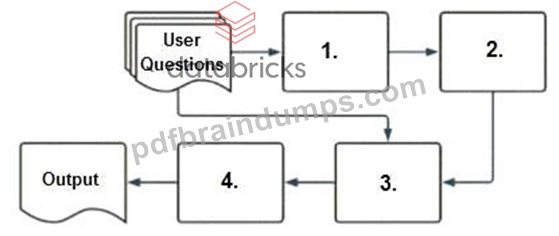
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: C
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 36
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: C
Explanation:
* Problem Context: When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options:
* Option A: Reaching out to data curatorsbeforeusing the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B: Usingoriginal datathat you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C: Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D: Reaching out to the data curatorsafteryou have already started using the trained model isnot appropriate. If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications. It's essential to clarify the licensing termsbeforeusing the data, not after.
Thus,Option Dis not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 37
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user' s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
Answer: B,C
Explanation:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here
' s why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
* Define an evaluation metric : Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user ' s query and the expected response.
* Recall measures the proportion of relevant information retrieved.
* NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
* Experiment with chunking strategies : Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user ' s query than others.
* Evaluate performance : By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
* Use the LLM as an evaluator : After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a " judge " function, where the LLM compares how well a given chunk answers previous user queries.
* Optimize based on the LLM ' s judgment : By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
* This metric could be a qualitative judgment on how closely the retrieved information matches the user ' s intent.
* Tune chunking parameters : Based on the LLM ' s judgment, the engineer can adjust the chunk size or structure to better align with the LLM ' s responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
NEW QUESTION # 38
A Generative AI Engineer is developing an agent system using a popular agent-authoring library. The agent comprises multiple parallel and sequential chains. The engineer encounters challenges as the agent fails at one of the steps, making it difficult to debug the root cause. They need to find an appropriate approach to research this issue and discover the cause of failure. Which approach do they choose?
Answer: D
Explanation:
For complex agentic systems (like those built with LangGraph or Autogen), standard logging is often insufficient because the "state" of the agent changes dynamically. MLflow Tracing is the designated Generative AI engineering standard for debugging these systems. Tracing provides a visual, hierarchical timeline of every call made during an agent's execution-including internal LLM reasoning, tool calls, and data transformations. When a step fails, the trace allows the engineer to click into that specific node to see the exact input sent to the LLM and the raw output received. This is much faster and more comprehensive than manually deconstructing the agent (D) or adding manual logs (C). While mlflow.evaluate (B) is useful for measuring performance across a whole dataset, it is not a tool for real-time debugging of a single execution failure.
NEW QUESTION # 39
......
Databricks-Generative-AI-Engineer-Associate certification has great effect in this field and may affect your career even future. Databricks-Generative-AI-Engineer-Associate real questions files are professional and high passing rate so that users can pass the exam at the first attempt. High quality and pass rate make us famous and growing faster and faster. Many candidates compliment that Databricks-Generative-AI-Engineer-Associate Study Guide materials are best assistant and useful for qualification exams, they have no need to purchase other training courses or books to study, and only by practicing our Databricks-Generative-AI-Engineer-Associate Generative AI Engineer exam braindumps several times before exam, they can pass exam in short time easily.
Databricks-Generative-AI-Engineer-Associate Reliable Test Pattern: https://www.pdfbraindumps.com/Databricks-Generative-AI-Engineer-Associate_valid-braindumps.html
BTW, DOWNLOAD part of PDFBraindumps Databricks-Generative-AI-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1YyIY7yMY9p5JMQ-UxqMeiB2POBbtIWGd