2026 Latest Prep4away AI-103 PDF Dumps and AI-103 Exam Engine Free Share: https://drive.google.com/open?id=1Pq7nAHhpPHNb5kkZH4j50Yj8wg_cSFhm
The AI-103 desktop practice exam software and AI-103 web-based practice test is very beneficial for the applicants in their preparation because these Microsoft AI-103 practice exam provides them with the Microsoft AI-103 Actual Test environment. Prep4away offers Microsoft AI-103 practice tests that are customizable. It means takers can change durations and questions as per their learning needs.
| Section | Objectives |
|---|---|
| Topic 1: Implement Natural Language Processing Solutions | - Translation and multilingual support - Language understanding and intent recognition - Text analytics and summarization |
| Topic 2: Plan and Manage Azure AI Solutions | - Model selection and lifecycle management - Responsible AI principles and governance - Azure AI resource provisioning and configuration |
| Topic 3: Develop Generative AI Applications and Agents | - AI agents architecture
|
| Topic 4: Knowledge Mining and Information Retrieval | - RAG (Retrieval Augmented Generation) patterns - Indexing and semantic search - Azure AI Search configuration |
| Topic 5: Implement Computer Vision Solutions | - OCR and document intelligence - Image classification and object detection |
If you buy the AI-103 study materials of us, we ensure you to pass the exam. Since the AI-103 study materials have the quality and the accuracy, and it will help you pass exam just one time. Buying AI-103 exam dumps are pass guaranteed and money back guaranteed for the failure. Furthermore, we choose international confirmation third party for payment for the AI-103 Exam Dumps, therefore we can ensure you the safety of your account and your money. The refund money will return to your payment account.
NEW QUESTION # 68
You have an invoice-processing application named App1 that uses Azure Content Understanding in Foundry Tools. You are building a new Content Understanding pipeline named Pipeline1 that must meet the following requirements:
* Compare an invoice to its related purchase order.
* Validate the invoice against static vendor contract documents.
* Return a single structured output that includes discrepancy findings.
You need to configure Pipeline1 and expose the pipeline as a single analyzer endpoint. What should you configure?
Answer: A
Explanation:
Configure a multi-file task in pro mode . At analysis time, provide the invoice and its related purchase order as the input documents. During analyzer creation, add the static vendor contracts as reference data . Pro mode can reason across multiple input documents and use reference documents as contextual knowledge for validation, enrichment, and discrepancy detection. Microsoft specifically documents the scenario of supplying an invoice and purchase order as inputs while using contract files as reference data to identify inconsistencies.
Define a field schema containing the required invoice information and generated discrepancy findings.
Building the task creates an analyzer ID that applications invoke through one analyzer API endpoint, producing a unified structured result governed by that schema.
Standard mode is optimized for straightforward processing of individual files. It does not support cross-file analysis, reference-dataset integration, or the multi-step reasoning required to compare invoices, purchase orders, and contractual conditions. A "multi-file task in standard mode" is therefore not a supported configuration. Confidence scores do not address document comparison and, notably, are not available in pro mode.
Study Guide alignment: configure Content Understanding analyzers, design structured schemas, process multiple documents, integrate reference data, and implement document validation workflows .
NEW QUESTION # 69
You have a Microsoft Foundry project that contains an agent for a customer support chat app.
The agent uses a memory store and a memory search tool.
You need to ensure that the conversation history does NOT persist across separate sessions.
To what should you set the scope of the memory tool?
Answer: C
Explanation:
To ensure that conversation history does not persist across separate sessions, you must set the scope to session.
The session scope restricts data access to the current active chat instance. It automatically wipes or ignores previous data when a new session starts.
Incorrect:
[Not C]
user or {{$userId}} scope: Persists data across multiple sessions for that specific user. This would cause the exact issue you want to avoid by carrying historical context into new conversations.
References:
https://ai.gopubby.com/agents-with-memory-conceptual-undestanding-part-01-f6caedfcd96d?gi=a9aa95df15c6
NEW QUESTION # 70
Hotspot Question
You have a Microsoft Foundry project that contains an agent.
You use a GitHub Actions workflow for CI/CD.
You need to configure the workflow to automatically evaluate the agent when a pull request (PR) is created and prevent branches from merging if the evaluation results do NOT meet the defined thresholds.
How should you configure the workflow? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.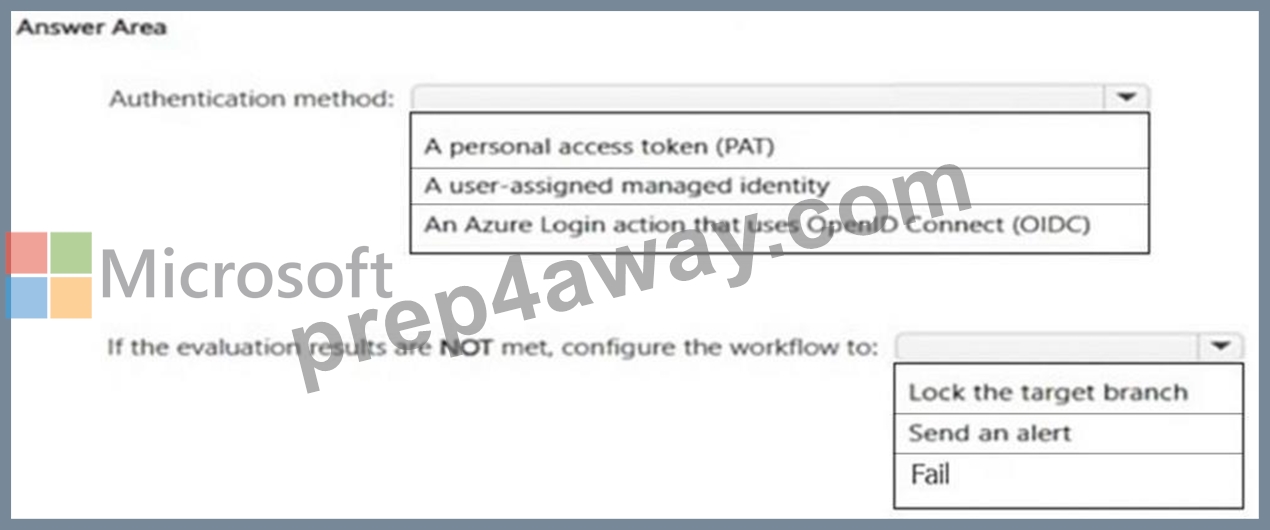
Answer:
Explanation: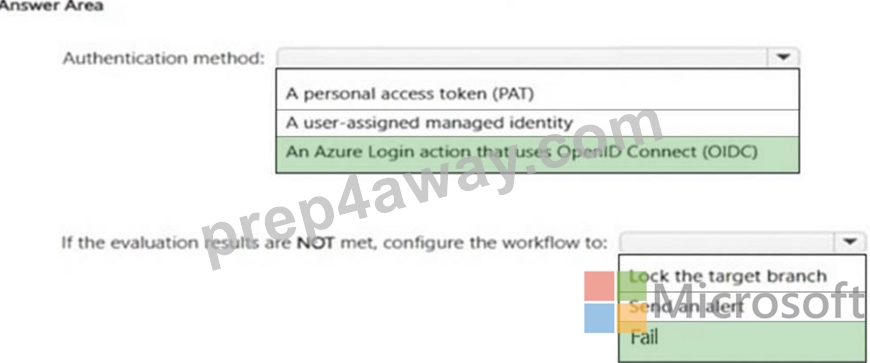
NEW QUESTION # 71
You have a Microsoft Foundry project.
You plan to build a customer support solution that contains an agent. The solution must meet the following requirements:
- Provide accurate, context-aware responses grounded in internal
product documentation stored in Azure AI Search.
- Require deep, multi-step reasoning across long contexts.
- Generate detailed natural language responses.
Which type of model should you use to power the agent?
Answer: A
Explanation:
For a support agent requiring deep multi-step reasoning, long context processing, and strict grounding in internal documents, the GPT-5.5 (or GPT-5.5-Pro) model from the Azure AI Foundry model catalog is the best choice.
Here is how GPT-5.5 directly addresses the requirements:
Deep Multi-Step Reasoning: These frontier models use deliberate reasoning and iterative planning before generating a response. This allows the agent to decompose complex support queries, analyze alternatives, and prevent hallucinations without requiring heavy custom prompt engineering.
Grounded, Accurate Responses:
Rather than doing this alone, pair the model with Foundry IQ connected to your Azure AI Search indices. Foundry IQ's agentic retrieval engine will pull exactly the right context, allowing GPT-5.5 to synthesize the answer and cite the original documentation.
Long Context Handling:
GPT-5.5 models support massive context windows, allowing them to ingest extensive previous conversational turns alongside detailed internal documentation in a single pass without losing track of important rules.
Note:
GPT-5.5 is a large language model (LLM).While it is a flagship LLM built on OpenAI's advanced transformer architecture, it also features natively omnimodal capabilities that allow it to process both text and images seamlessly within a single unified framework. However, when choosing between the specific categories provided, its primary core classification is a Large Language Model (LLM).
Key Details About GPT-5.5
Core Architecture: Large Language Model (LLM) built by OpenAI.
Primary Focus: Highly optimized for complex reasoning, multi-step problem solving, coding, and autonomous agentic workflows.
Input/Output Capabilities: Supports text and image inputs with text-based outputs.
Reference:
https://developers.openai.com/api/docs/guides/reasoning
NEW QUESTION # 72
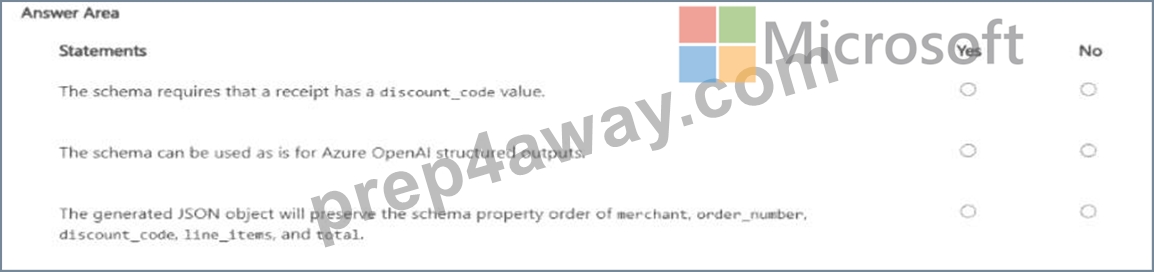
You have a Python application that uses Azure OpenAt structured outputs to extract fields from unstructured receipt text and support ticket text. The application uses the following schema.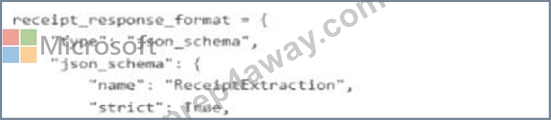
Answer:
Explanation: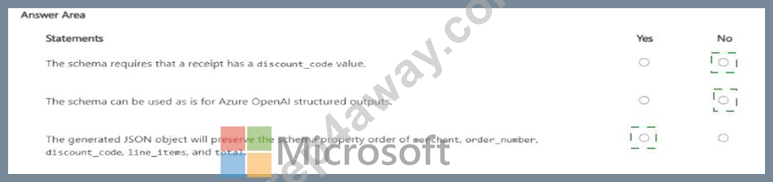
Explanation:
* The schema requires that a receipt has a discount_code value - No
* The schema can be used as is for Azure OpenAI structured outputs - No
* The generated JSON object will preserve the property order merchant, order_number, discount_code, line_items, and total - Yes The discount_code definition permits a nullable result. Consequently, the output can contain " discount_code
" : null when the source receipt contains no discount code. The property can be structurally present without containing a substantive discount-code value; therefore, the first statement is No .
The schema cannot be submitted unchanged. Azure OpenAI structured outputs support only a defined subset of JSON Schema. Every property declared in an object must be included in that object's required array.
Optional information must instead be represented as a required property whose type includes null. Each object must also specify " additionalProperties " : false. Furthermore, although nested anyOf constructs are supported, an anyOf construct cannot be used as the root schema. A schema that violates any of these restrictions must be revised before use, making the second statement No .
The third statement is Yes . Azure OpenAI structured outputs preserve keys in the order in which the properties are defined in the supplied schema. Therefore, the receipt object will emit merchant, order_number, discount_code, line_items, and total in that sequence. This behavior supports predictable parsing and downstream integration. The relevant curriculum area is Use Azure OpenAI in Foundry Models to generate content , including application integration and structured model responses.
NEW QUESTION # 73
......
There are various individuals who have never shown up for the Developing AI Apps and Agents on Azure certification test as of now. They know close to nothing about the Developing AI Apps and Agents on Azure exam model and how to attempt the requests. Microsoft AI-103 Dumps give an unequivocal thought of the last preliminary of the year model and how a promising rookie ought to attempt the solicitation paper to score well.
Exam AI-103 Vce Format: https://www.prep4away.com/Microsoft-certification/braindumps.AI-103.ete.file.html
BTW, DOWNLOAD part of Prep4away AI-103 dumps from Cloud Storage: https://drive.google.com/open?id=1Pq7nAHhpPHNb5kkZH4j50Yj8wg_cSFhm