Wenn Sie sich an der Microsoft AI-200 Zertifizierungsprüfung beteiligen, wählen Sie doch PrüfungFrage, was Erfolg bedeutet. Viel glück!
| Section | Objectives |
|---|---|
| Topic 1: Develop containerized solutions on Azure | - Implement containerized applications
|
| Topic 2: Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Topic 3: Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Topic 4: Connect to and consume Azure services | - Integrate Azure services
|
>> Microsoft AI-200 Zertifizierung <<
Wollen Sie Microsoft AI-200 Zertifizierungsprüfung bestehen und auch die AI-200 Zertifizierung besitzen? Wir PrüfungFrage können Ihren Erfolg gewährleisten. Es ist sehr wichtig, die entsprechenden Kenntnisse der AI-200 Prüfung vorzubereiten. Und es ist auch sehr wichtig, das geeignete hocheffektive Gerät zu benutzen. Microsoft AI-200 Dumps von PrüfungFrage sind unbedingt das beste Lerngerät, das geeignet für Sie ist. Sie können auch unglaubliche Ergebnisse von diesen hocheffektiven Dumps gefunden. Fürchten Sie sich Misserfolg der Microsoft AI-200 Prüfungen, klicken Sie bitte PrüfungFrage und Informieren Sie sich.
143. Frage
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Drag and Drop Question
You need to implement the semantic retrieval workflow for the recommendation engine to meet the technical and performance requirements of Fabrikam Inc.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.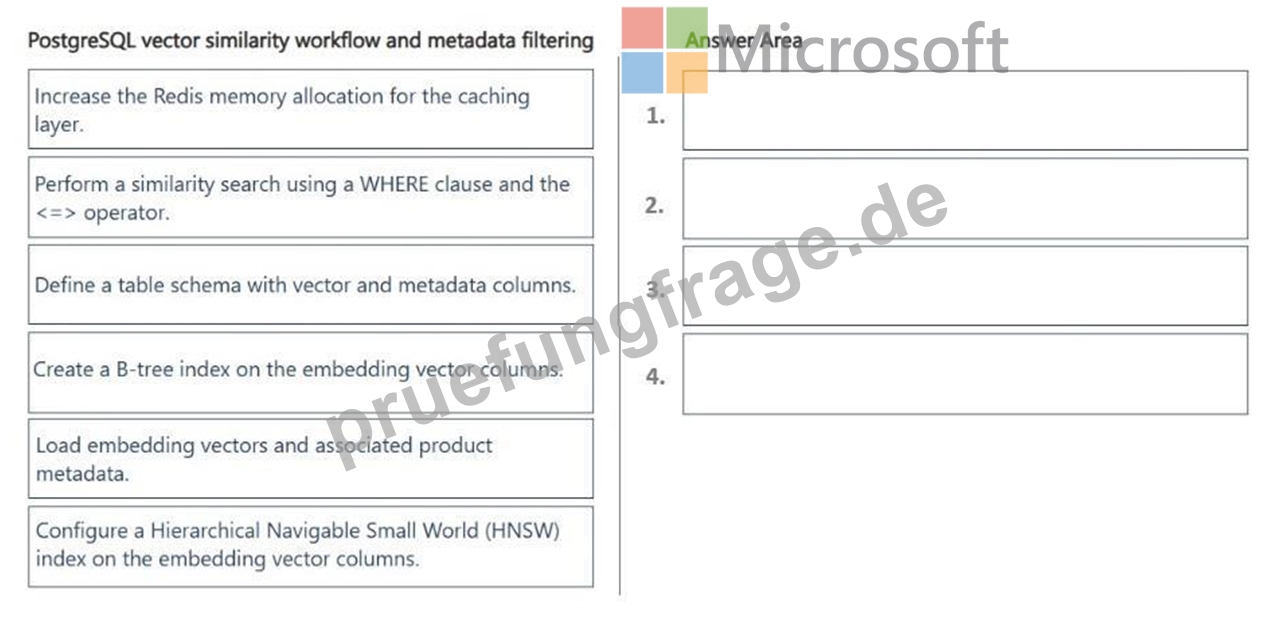
Antwort:
Begründung: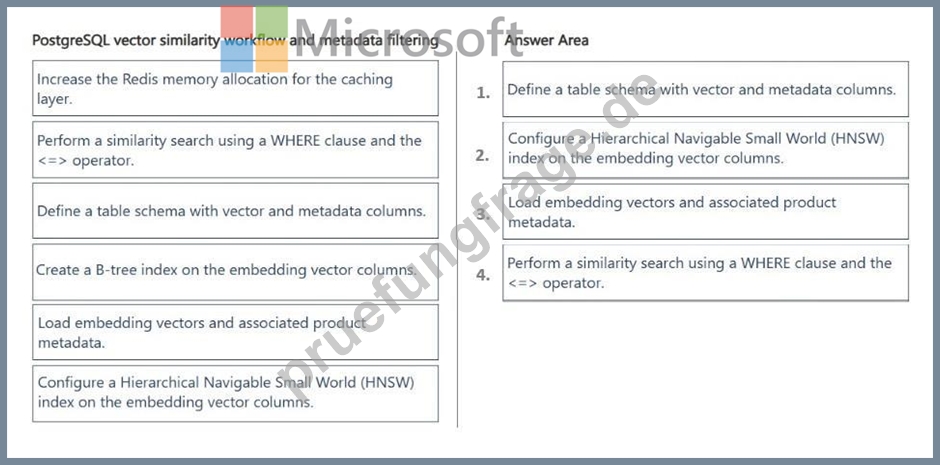
Explanation:
Scenario:
Current: The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Step 1: Define Table Schema with vector and metadata columns
Schema configuration: Establish the PostgreSQL table structure using the pgvector extension to store both the product metadata and the high-dimensional embedding vectors.
Step 2: Configure a Hierachical Navigable Small World (HNSW) index on the embedding vector columns Configure Vector Index HNSW indexing: Implement a Hierarchical Navigable Small World (HNSW) index rather than a B- tree index, as standard B-tree indexing cannot index multi-dimensional vector embeddings for similarity searches.
An HNSW (Hierarchical Navigable Small World) index is the correct choice for the embedding vector columns in this scenario, while a B-tree index is entirely unsuited for vector similarity search.
Step 3: Load embedding vectors and associated product metadata
Populate Database
Data ingestion: Load the pre-computed embedding vectors along with their corresponding product metadata into the newly indexed table.
Step 4: Perform a similarity search using a WHERE clause and the <=> operator Query Similar Items Similarity search: Execute vector similarity queries using the <=> operator (which denotes cosine distance in pgvector) to find and return the closest product recommendations.
Reference:
https://mobisoftinfotech.com/resources/blog/enhancing-rag-generative-ai-postgresql-hnsw-indexes
144. Frage
You have an Event Grid subscription that triggers an Azure Function.
You need to prevent loss of events in case the endpoint returns an HTTP 400 response.
Which action should you perform?
Antwort: B
Begründung:
Configuring a dead-letter destination is exactly the right step to take.
By default, when an endpoint returns an HTTP 400 (Bad Request) or HTTP 413 (Payload Too Large) response, Azure Event Grid immediately stops delivery attempts and drops the message.
It treats these specific errors as non-transient, client-side issues, meaning it skips its standard 24- hour retry policy.
Configuring a dead-letter destination ensures that these dropped events are safely preserved for future troubleshooting and reprocessing.
Reference:
https://turbo360.com/blog/azure-event-grid-dead-letter-monitoring
145. Frage
You are designing an Azure Function that will process orders from a new Azure Service Bus queue.
You need to prevent the system from processing messages more than once and preserve failed messages for investigation.
Which two actions should you implement? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Antwort: B,D
Begründung:
To ensure reliable order processing with zero duplicates and safe error handling, you should implement an Azure Function with an Azure Service Bus Trigger utilizing duplicate detection, PeekLock settlement, and custom dead-letter routing.
References:
https://azureintegrations.com/2020/03/01/azure-servce-bus-best-practises/
146. Frage
You are developing a Java application to be deployed in Azure. The application stores sensitive data in Azure Cosmos DB.
You need to configure Always Encrypted to encrypt the sensitive data inside the application.
What should you do first?
Antwort: D
Begründung:
Detailed Explanation: For Cosmos DB Always Encrypted, the key hierarchy starts with a customer-managed key held in Azure Key Vault. The data encryption key used by the client is protected by that customer- managed key. Microsoft's setup sequence therefore begins by preparing Key Vault and the CMK before creating DEKs or an encryption policy. Creating a managed identity, a container policy, or a DEK can be necessary later, but none precedes establishing the CMK that protects the client-side encryption key material.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Always Encrypted for Azure Cosmos DB
147. Frage
A recommendation system stores 1 million embeddings in Azure Database for PostgreSQL During peak hours. P95 similarity-query latency increases, and the cache hit ratio drops significantly.
You suspect that the vector index working set no longer fits in memory, resulting in more disk reads.
You need to scale server resources and validate the outcome.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.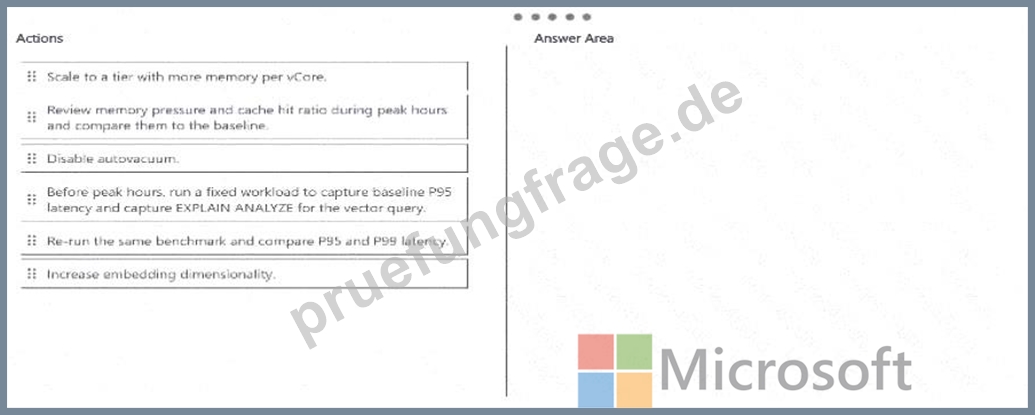
Antwort:
Begründung: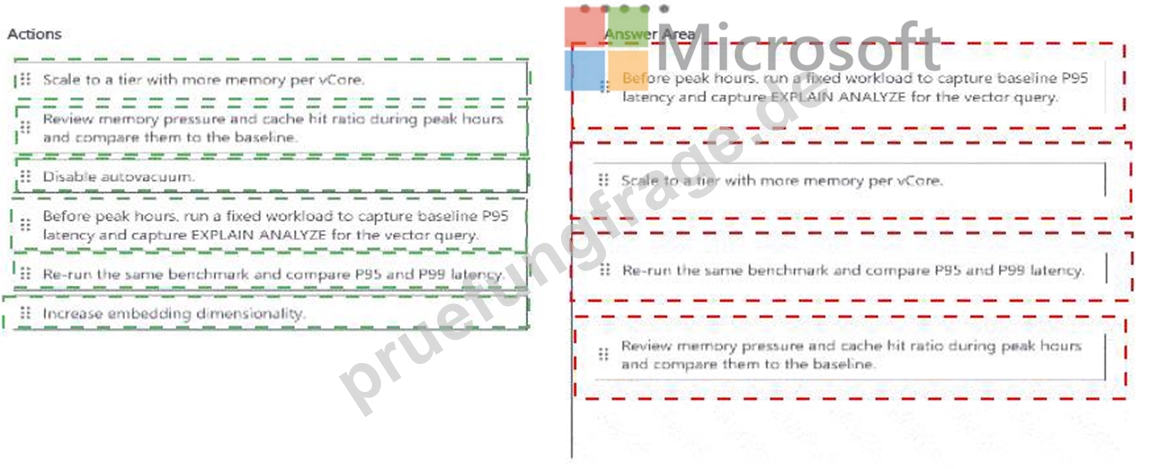
Explanation: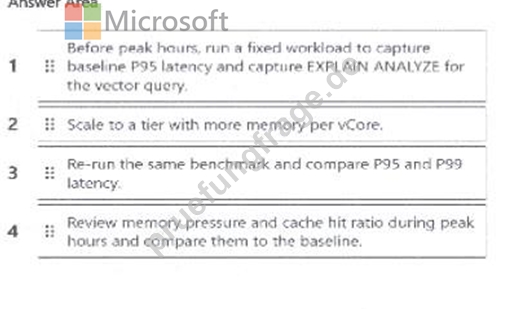
148. Frage
......
Suchen Sie nach die geeignetsten Prüfungsunterlagen der Microsoft AI-200? Sorgen Sie noch um das Ordnen der Unterlagen? PrüfungFrage als ein professioneller Lieferant der Software der IT-Zertifizierungsprüfung haben Ihnen die umfassendsten Unterlagen der Microsoft AI-200 vorbereitet. Jetzt können Sie Zeit fürs Suchen gespart und direkt auf die Microsoft AI-200 Prüfung vorbereiten!
AI-200 Online Praxisprüfung: https://www.pruefungfrage.de/AI-200-dumps-deutsch.html