DOWNLOAD the newest ExamDiscuss DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1EasDJead_W2n0RvVKDZ7zThk0mXGfGCO
Our materials can make you master the best DP-100 questions torrent in the shortest time and save your much time and energy to complete other thing. What most important is that our DP-100 study materials can be download, installed and used safe. We can guarantee to you that there no virus in our product. Not only that, we also provide the best service and the best DP-100 Exam Torrent to you and we can guarantee that the quality of our DP-100 learning dump is good. So please take it easy after the purchase and we won’t let your money be wasted.
| Section | Objectives |
|---|---|
| Topic 1: Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
| Topic 2: Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
| Topic 3: Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads - Manage compute and data assets |
| Topic 4: Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Topic 5: Train machine learning models | - Tune hyperparameters and evaluate models - Train models using Azure Machine Learning |
>> Pdf Demo DP-100 Download <<
Our DP-100 study materials concentrate the essence of exam materials and seize the focus information to let the learners master the key points. And our DP-100 learning materials provide multiple functions and considerate services to help the learners have no inconveniences to use our product. We guarantee to the clients if only they buy our study materials and learn patiently for some time they will be sure to pass the DP-100 test with few failure odds.
NEW QUESTION # 102
You create a batch inference pipeline by using the Azure ML SDK. You run the pipeline by using the following code:
from azureml.pipeline.core import Pipeline
from azureml.core.experiment import Experiment
pipeline = Pipeline(workspace=ws, steps=[parallelrun_step])
pipeline_run = Experiment(ws, 'batch_pipeline').submit(pipeline)
You need to monitor the progress of the pipeline execution.
What are two possible ways to achieve this goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.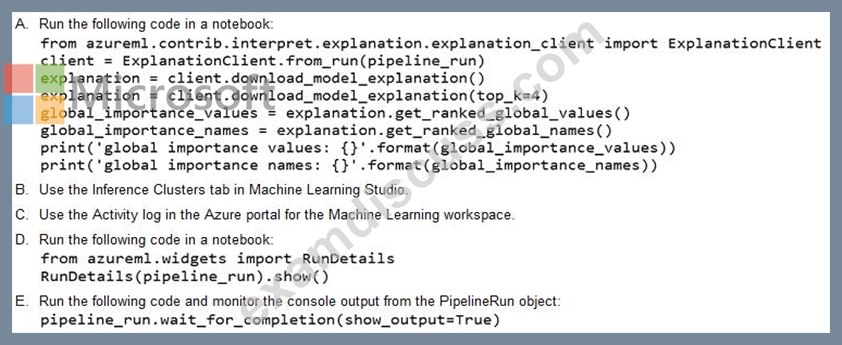
Answer: D,E
Explanation:
A batch inference job can take a long time to finish. This example monitors progress by using a Jupyter widget. You can also manage the job's progress by using:
* Azure Machine Learning Studio.
* Console output from the PipelineRun object.
from azureml.widgets import RunDetails
RunDetails(pipeline_run).show()
pipeline_run.wait_for_completion(show_output=True)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-use-parallel-run-step#monitor-the-parallel-run-job
NEW QUESTION # 103
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are using Azure Machine Learning to run an experiment that trains a classification model.
You want to use Hyperdrive to find parameters that optimize the AUC metric for the model. You configure a HyperDriveConfig for the experiment by running the following code: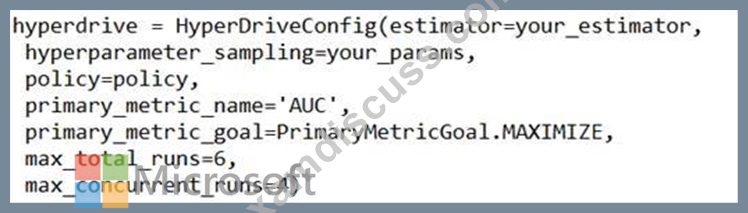
You plan to use this configuration to run a script that trains a random forest model and then tests it with validation data. The label values for the validation data are stored in a variable named y_test variable, and the predicted probabilities from the model are stored in a variable named y_predicted.
You need to add logging to the script to allow Hyperdrive to optimize hyperparameters for the AUC metric.
Solution: Run the following code: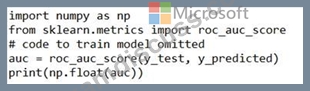
Does the solution meet the goal?
Answer: A
Explanation:
Use a solution with logging.info(message) instead.
Note: Python printing/logging example:
logging.info(message)
Destination: Driver logs, Azure Machine Learning designer
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-debug-pipelines
NEW QUESTION # 104
You create an Azure Machine learning workspace. The workspace contains a folder named src. The folder contains a Python script named script 1 .py.
You use the Azure Machine Learning Python SDK v2 to create a control script. You must use the control script to run script l.py as part of a training job.
You need to complete the section of script that defines the job parameters.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.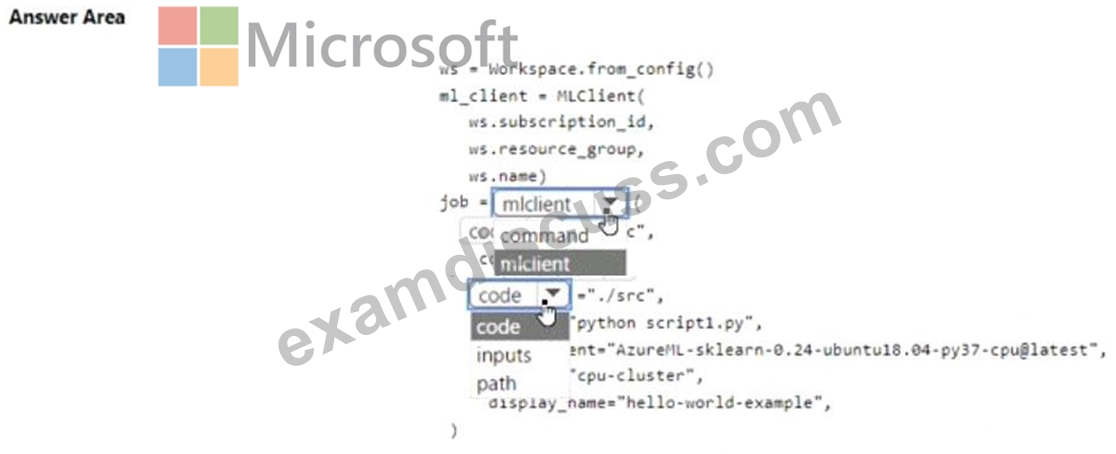
Answer:
Explanation: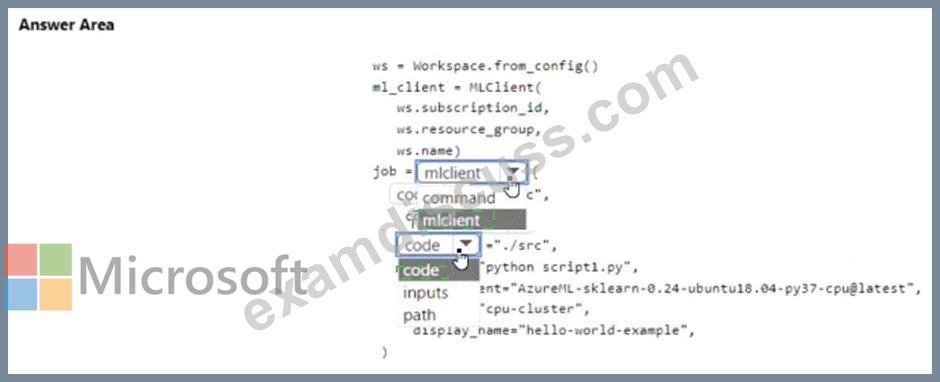
Explanation: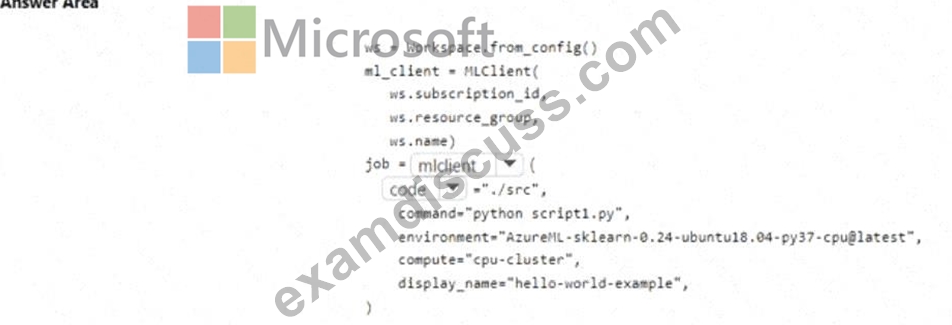
NEW QUESTION # 105
You use Azure Machine Learning to implement hyperparameter tuning with a Bandit early termination policy.
The policy uses a slack_factor set to 01. an evaluation interval set to 1, and an evaluation delay set to b.
You need to evaluate the outcome of the early termination policy
What should you evaluate? To answer, select the appropriate options m the answer area.
NOTE: Each correct selection is worth one point.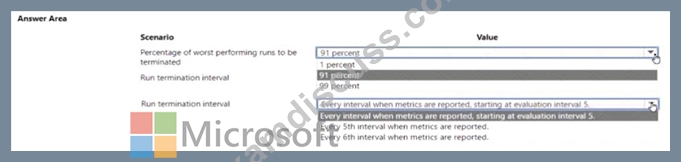
Answer:
Explanation: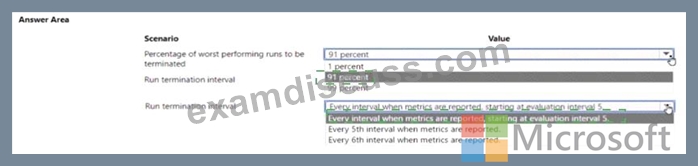
Explanation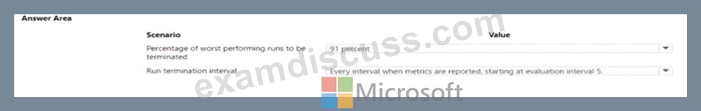
NEW QUESTION # 106
You are building an experiment using the Azure Machine Learning designer.
You split a dataset into training and testing sets. You select the Two-Class Boosted Decision Tree as the algorithm.
You need to determine the Area Under the Curve (AUC) of the model.
Which three modules should you use in sequence? To answer, move the appropriate modules from the list of modules to the answer area and arrange them in the correct order.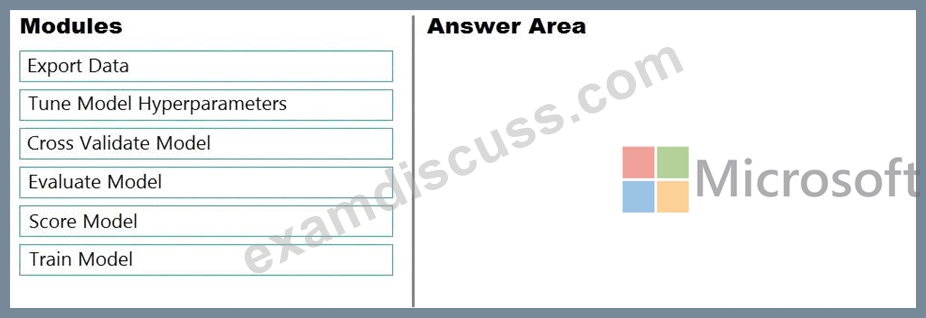
Answer:
Explanation: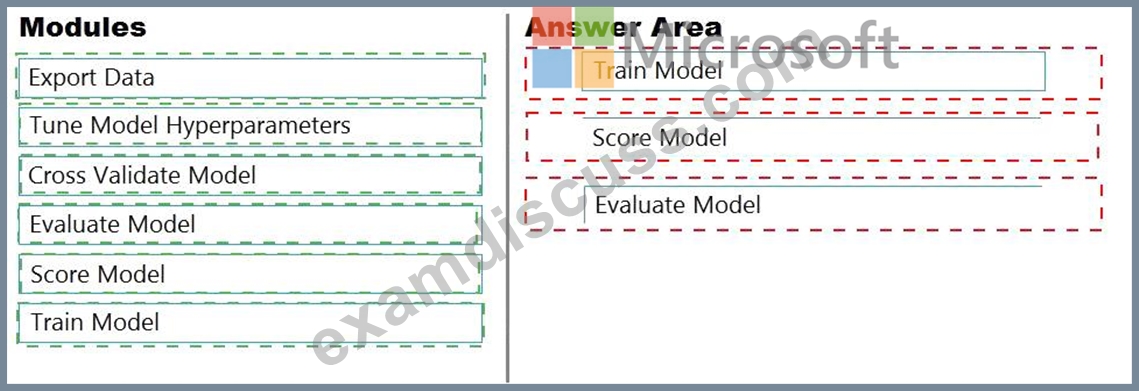
Explanation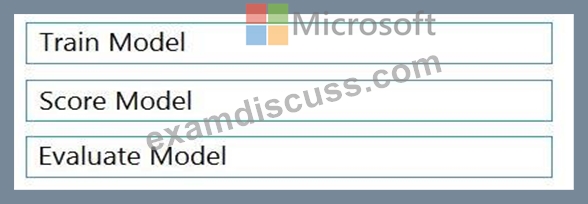
Step 1: Train Model
Two-Class Boosted Decision Tree
First, set up the boosted decision tree model.
1. Find the Two-Class Boosted Decision Tree module in the module palette and drag it onto the canvas.
2. Find the Train Model module, drag it onto the canvas, and then connect the output of the Two-Class Boosted Decision Tree module to the left input port of the Train Model module.
The Two-Class Boosted Decision Tree module initializes the generic model, and Train Model uses training data to train the model.
3. Connect the left output of the left Execute R Script module to the right input port of the Train Model module (in this tutorial you used the data coming from the left side of the Split Data module for training).
This portion of the experiment now looks something like this: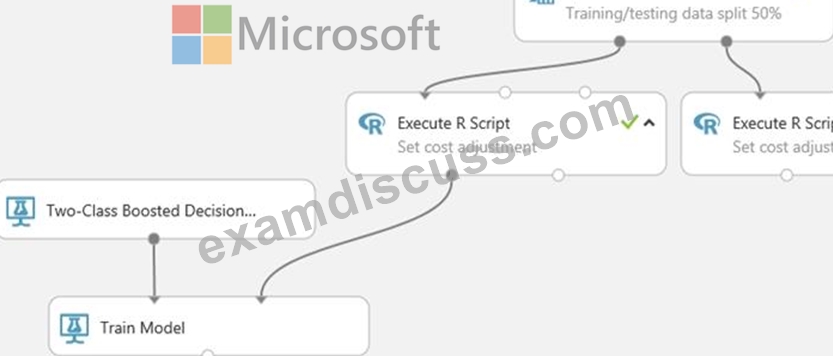
Step 2: Score Model
Score and evaluate the models
You use the testing data that was separated out by the Split Data module to score our trained models. You can then compare the results of the two models to see which generated better results.
Add the Score Model modules
1. Find the Score Model module and drag it onto the canvas.
2. Connect the Train Model module that's connected to the Two-Class Boosted Decision Tree module to the left input port of the Score Model module.
3. Connect the right Execute R Script module (our testing data) to the right input port of the Score Model module.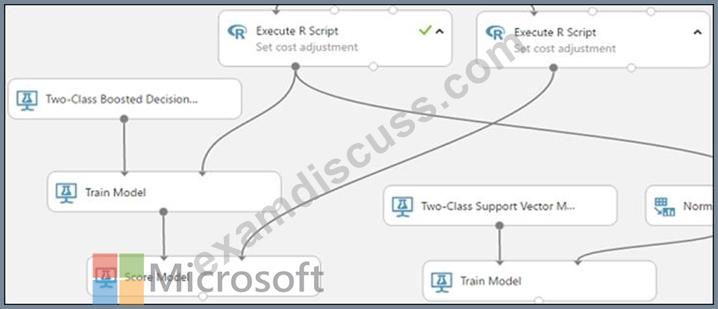
Step 3: Evaluate Model
To evaluate the two scoring results and compare them, you use an Evaluate Model module.
1. Find the Evaluate Model module and drag it onto the canvas.
2. Connect the output port of the Score Model module associated with the boosted decision tree model to the left input port of the Evaluate Model module.
3. Connect the other Score Model module to the right input port.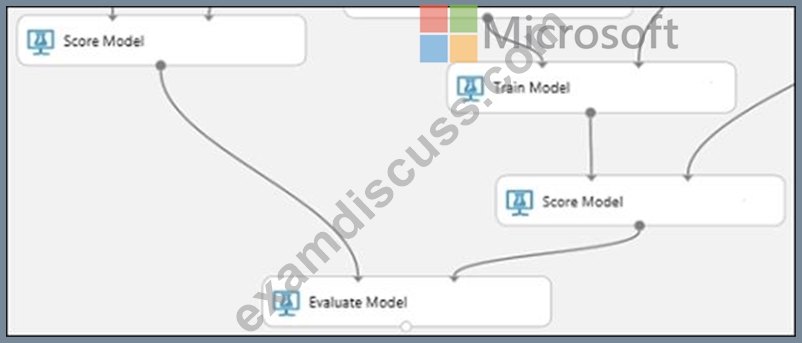
NEW QUESTION # 107
......
To solve all these problems, ExamDiscuss offers actual DP-100 Questions to help candidates overcome all the obstacles and difficulties they face during DP-100 examination preparation. With vast experience in this field, ExamDiscuss always comes forward to provide its valued customers with authentic, actual, and genuine DP-100 Exam Dumps at an affordable cost. All the Designing and Implementing a Data Science Solution on Azure (DP-100) questions given in the product are based on actual examination topics.
Updated DP-100 CBT: https://www.examdiscuss.com/Microsoft/exam/DP-100/
P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by ExamDiscuss: https://drive.google.com/open?id=1EasDJead_W2n0RvVKDZ7zThk0mXGfGCO