BTW, DOWNLOAD part of Lead1Pass DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1ensIoyLefziLrF9yHbN6Zwc2hv7VmbIl
It is convenient for our consumers to check Microsoft DP-750 exam questions free of charge before purchasing the Microsoft DP-750 practice exam. Microsoft is an excellent platform where you get relevant, credible, and unique Microsoft DP-750 Exam Dumps designed according to the specified pattern, material, and format as suggested by the Microsoft DP-750 exam.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
>> DP-750 Reliable Exam Testking <<
If you are curious or doubtful about the proficiency of our DP-750 practice materials, we can explain the painstakingly word we did behind the light. By abstracting most useful content into the DP-750 practice materials, they have help former customers gain success easily and smoothly. The most important part is that all contents were being sifted with diligent attention. No errors or mistakes will be found within our DP-750 practice materials. We stress the primacy of customers’ interests, and make all the preoccupation based on your needs.
NEW QUESTION # 31
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
Answer: C
Explanation:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
NEW QUESTION # 32
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.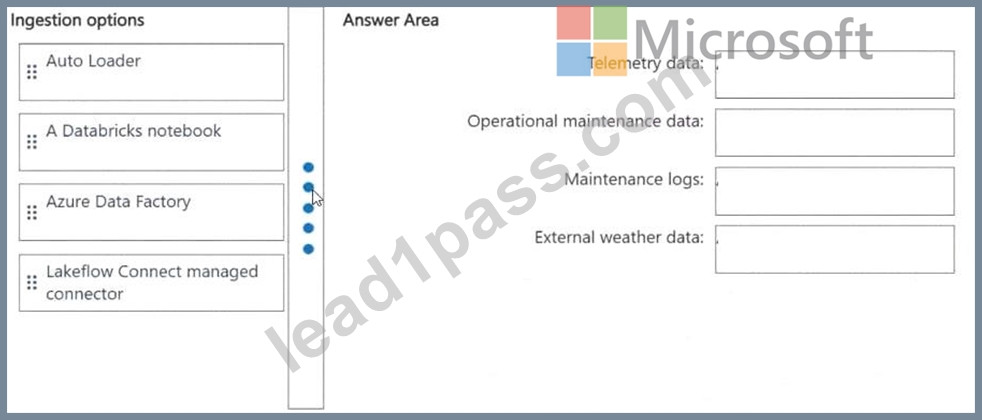
Answer:
Explanation: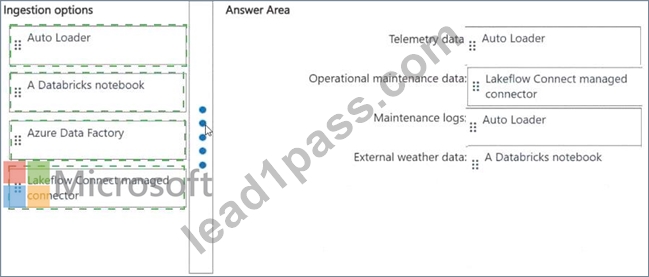
Explanation:
The right ingestion tool depends on the source characteristics:
File-based telemetry and maintenance data # Auto Loader (cloudFiles). It monitors ADLS Gen2 for new arrivals, handles schema inference and evolution for the frequent schema drift, and requires minimal operational effort.
Real-time telemetry from Event Hubs # Spark Structured Streaming with the azure-eventhubs-spark connector. This provides exactly-once semantics and checkpoint-based recovery, satisfying 'resume processing after failures without reprocessing.' Structured maintenance data from PostgreSQL # JDBC connector. Databricks supports direct JDBC reads from relational databases with pushdown predicates.
Daily CSV ERP extracts (50-100 GB) # COPY INTO or Auto Loader. Both support idempotent incremental batch loading into Delta tables with minimal code.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 33
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: D
Explanation:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
NEW QUESTION # 34
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1.
You need to meet the following requirements:
- Records that violate rule1 must NOT be written to Table1, but the
pipeline must continue processing valid records.
- Data engineers must be able to review expectation metrics by using
minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.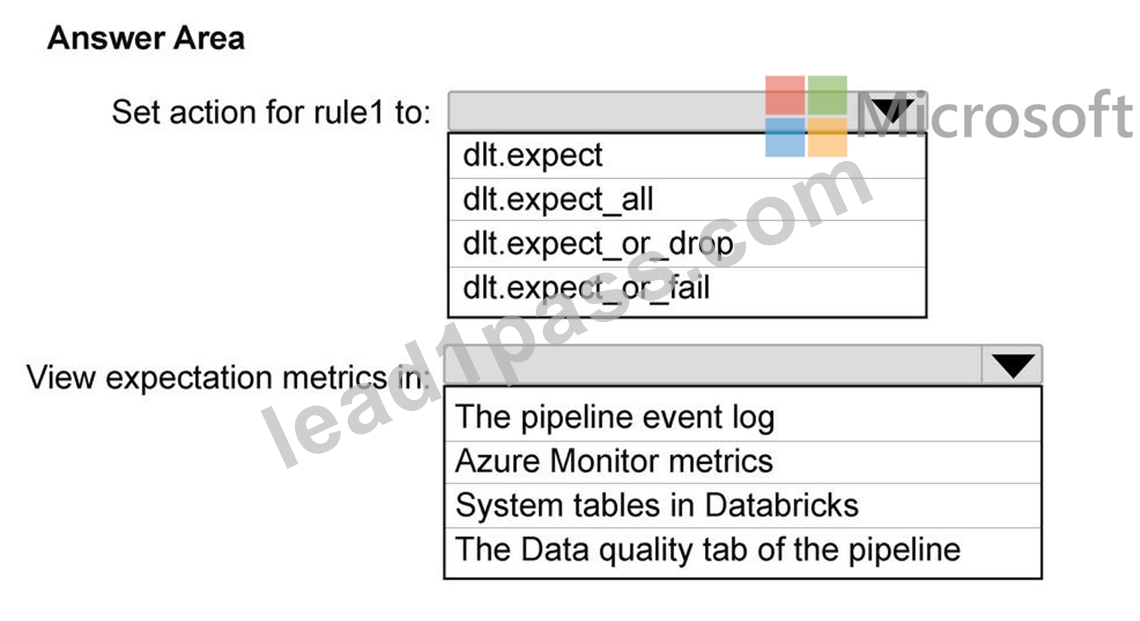
Answer:
Explanation: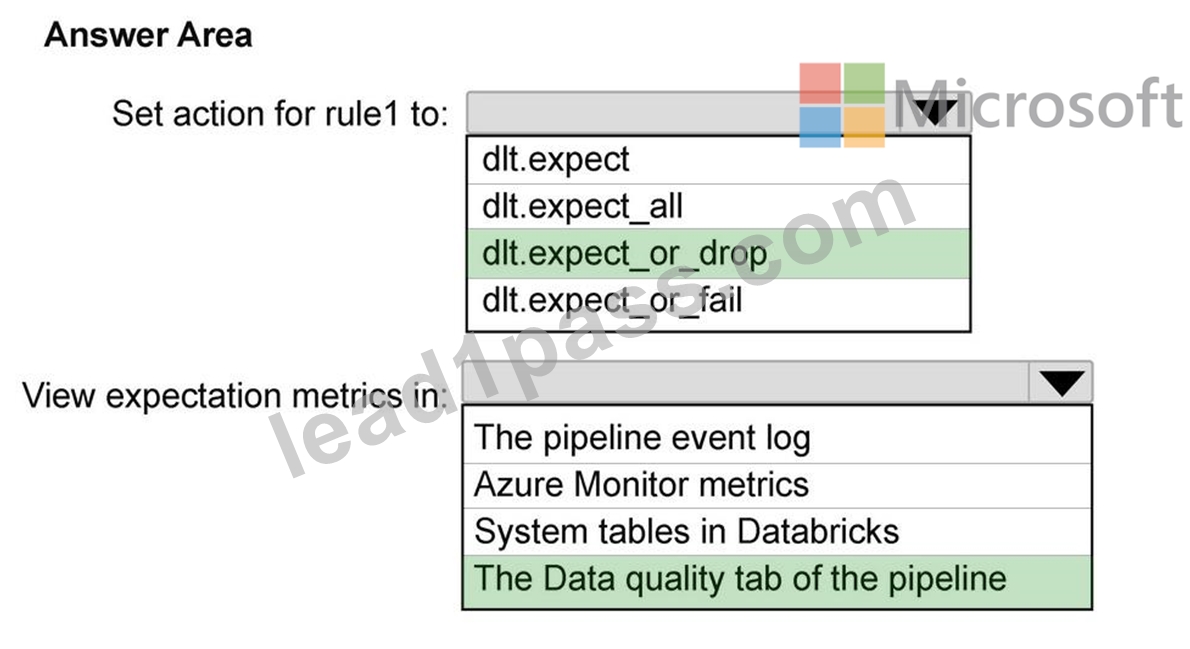
NEW QUESTION # 35
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments. What should you use?
Answer: C
Explanation:
The best option to use is the Databricks CLI.
The Databricks CLI is the core orchestration tool natively designed to validate, deploy, and manage Declarative Automation Bundles (formerly known as Databricks Asset Bundles) across multiple target environments using simple terminal commands like databricks bundle deploy.
Incorrect:
[Not A]
Git folders: Git folders are strictly a mechanism for version control, code syncing, and repository collaboration inside the workspace. While they are highly integrated with bundle development, they cannot directly deploy or provision bundle targets to isolated environments on their own without the CLI.
[Not C]
Databricks SDK for Python: While the Python SDK provides general programmatic access to Databricks APIs, it is not the primary or optimized tool for executing bundle operations. The bundle framework natively relies on the Databricks CLI executable to compile and translate your configurations.
[Not D]
Jobs UI: The Jobs user interface is built for manual interactions. It does not support native bundle multi-environment targeting or automated, repeatable CI/CD pipelines.
Reference:
https://docs.databricks.com/aws/en/dev-tools/bundles/
NEW QUESTION # 36
......
Our DP-750 preparation exam have assembled a team of professional experts incorporating domestic and overseas experts and scholars to research and design related exam bank, committing great efforts to work for our candidates. Most of the experts have been studying in the professional field for many years and have accumulated much experience in our DP-750 Practice Questions. The high-quality of our DP-750 exam questions are praised by tens of thousands of our customers. You may try it!
Well DP-750 Prep: https://www.lead1pass.com/Microsoft/DP-750-practice-exam-dumps.html
DOWNLOAD the newest Lead1Pass DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ensIoyLefziLrF9yHbN6Zwc2hv7VmbIl