Pass Guaranteed Useful Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam New Questions

We will provide you with three different versions of our Databricks-Certified-Professional-Data-Engineer exam questions on our test platform. You have the opportunity to download the three different versions from our test platform. The three different versions of our Databricks-Certified-Professional-Data-Engineer Test Torrent include the PDF version, the software version and the online version. The three different versions will offer you same questions and answers, but they have different functions.
| Section | Objectives |
|---|
| Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs
- Automate ETL pipelines and scheduling
- Pipeline reliability and fault tolerance
|
| Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads
- Implement Unity Catalog governance and access control
- Cost optimization and performance tuning
|
| Data Modeling and Storage | - Delta Lake table design and optimization
- Schema evolution and data partitioning strategies
- Design scalable data lakehouse architectures
|
| Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks
- Transform and clean datasets using Spark SQL and DataFrame APIs
- Handle batch and streaming data pipelines
|
>> Databricks-Certified-Professional-Data-Engineer New Questions <<
New Databricks-Certified-Professional-Data-Engineer Test Syllabus & Pass Databricks-Certified-Professional-Data-Engineer Rate
Once you learn all Databricks-Certified-Professional-Data-Engineer questions and answers in the study guide, try PrepAwayPDF's innovative testing engine for exam like Databricks-Certified-Professional-Data-Engineer practice tests. These tests are made on the pattern of the Databricks-Certified-Professional-Data-Engineer real exam and thus remain helpful not only for the purpose of revision but also to know the real exam scenario. To ensure excellent score in the exam, Databricks-Certified-Professional-Data-Engineer Braindumps are the real feast for all exam candidates. They contain questions and answers on all the core points of your exam syllabus. Most of these questions are likely to appear in the Databricks-Certified-Professional-Data-Engineer real exam.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q107-Q112):
NEW QUESTION # 107
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a scalar Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- B. Use a grouped-aggregate Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- C. Use applyInPandas on a Spark DataFrame so that each stock symbol group is received as a pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- D. Use a scalar_iter Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
Answer: C
Explanation:
applyInPandas is the documented grouped Pandas API for processing each group as a pandas DataFrame.
Spark passes all columns for each group together, which allows per-group state to be maintained naturally inside the function. By contrast, scalar Pandas UDFs are batch-oriented Series-to-Series operations, not group- state processing tools. ( Apache Spark ) This is why option C is the intended best answer among the listed choices. Option A adds unnecessary external persistence overhead, option B relies on unsupported global executor state, and option D misuses grouped aggregation semantics for row-by-row stateful logic. Spark also documents applyInPandas specifically as a grouped operation, while scalar Pandas UDFs process row batches and concatenate results rather than preserving grouped state semantics. ( Apache Spark )
======
NEW QUESTION # 108
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
- A. fs
- B. jobs
- C. configure
- D. libraries
- E. workspace
Answer: A
Explanation:
The libraries command group allows you to install, uninstall, and list libraries on Databricks clusters. You can use the libraries install command to install a custom Python Wheel on a cluster by specifying the --whl option and the path to the wheel file. For example, you can use the following command to install a custom Python Wheel named mylib-0.1-py3-none-any.whl on a cluster with the id 1234-567890-abcde123:
databricks libraries install --cluster-id 1234-567890-abcde123 --whl
dbfs:/mnt/mylib/mylib-0.1-py3-none-any.whl
This will upload the custom Python Wheel to the cluster and make it available for use with a production job.
You can also use the libraries uninstall command to uninstall a library from a cluster, and the libraries list command to list the libraries installed on a cluster.
References:
* Libraries CLI (legacy): https://docs.databricks.com/en/archive/dev-tools/cli/libraries-cli.html
* Library operations: https://docs.databricks.com/en/dev-tools/cli/commands.html#library-operations
* Install or update the Databricks CLI: https://docs.databricks.com/en/dev-tools/cli/install.html
NEW QUESTION # 109
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.
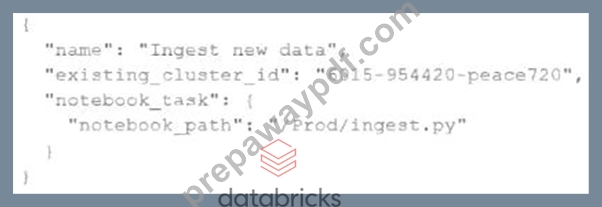
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
- A. Three new jobs named "Ingest new data" will be defined in the workspace, but no jobs will be executed.
- B. One new job named "Ingest new data" will be defined in the workspace, but it will not be executed.
- C. The logic defined in the referenced notebook will be executed three times on the referenced existing all purpose cluster.
- D. Three new jobs named "Ingest new data" will be defined in the workspace, and they will each run once daily.
- E. The logic defined in the referenced notebook will be executed three times on new clusters with the configurations of the provided cluster ID.
Answer: C
Explanation:
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with a name, an existing cluster id, and a notebook task. However, it does not specify any schedule or trigger for the job execution. Therefore, three new jobs with the same name and configuration will be created in the workspace, but none of them will be executed until they are manually triggered or scheduled.
Verified References: [Databricks Certified Data Engineer Professional], under "Monitoring & Logging" section; [Databricks Documentation], under "Jobs API - Create" section.
NEW QUESTION # 110
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns. The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB.
How should the data engineer meet this requirement?
- A. Combine partitioning and Z-ordering to maximize flexibility and minimize maintenance as query patterns change.
- B. Use Hive-style partitioning, as it provides efficient data skipping and is easy to change partition columns at any time.
- C. Apply Z-ordering, since it allows flexible reorganization of data layout without rewriting existing files and adapts easily to new filter columns.
- D. Enable liquid clustering, as it efficiently handles data skew, allows clustering keys to be changed without rewriting existing data, and adapts to evolving query patterns.
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation describes Liquid Clustering as the recommended data layout optimization for evolving workloads. Unlike traditional partitioning or Z-ordering, Liquid Clustering dynamically maintains data organization without rewriting existing files when clustering keys change. It handles data skew automatically and supports flexible re-clustering based on query patterns. Partitioning and Z-ordering require full data rewrites whenever key structures change, making them expensive for tables with frequently evolving access patterns. For tables under a few terabytes, Liquid Clustering offers the best balance between scalability, adaptability, and maintenance efficiency. Thus, option C aligns with Databricks' best practice for modern adaptive layout optimization.
NEW QUESTION # 111
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source.
Which action should the team take?
- A. Repair the run with the new parameter.
- B. Share the analysis with the failing notebook owner so that they can fix it quickly.
- C. Update the task by adding the missing task parameter, and manually run the job.
- D. Repair the run with the new parameter, and update the task by adding the missing task parameter.
Answer: D
Explanation:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution.
Thus, A follows the correct operational and recovery practice.
NEW QUESTION # 112
......
In the learning process, many people are blind and inefficient for without valid Databricks-Certified-Professional-Data-Engineer exam torrent and they often overlook some important knowledge points which may occupy a large proportion in the Databricks-Certified-Professional-Data-Engineer exam, and such a situation eventually lead them to fail the exam. While we can provide absolutely high quality guarantee for our Databricks-Certified-Professional-Data-Engineer practice materials, for all of our learning materials are finalized after being approved by industry experts. Without doubt, you will get what you expect to achieve, no matter your satisfied scores or according certification file
New Databricks-Certified-Professional-Data-Engineer Test Syllabus: https://www.prepawaypdf.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html
- 2026 Databricks-Certified-Professional-Data-Engineer New Questions Pass Certify | Professional New Databricks-Certified-Professional-Data-Engineer Test Syllabus: Databricks Certified Professional Data Engineer Exam 🕔 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and easily obtain a free download on 《 www.prepawayexam.com 》 ⛄Latest Databricks-Certified-Professional-Data-Engineer Dumps Book
- Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer –Newest New Questions 🕜 The page for free download of ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ on { www.pdfvce.com } will open immediately 🪕Valid Databricks-Certified-Professional-Data-Engineer Test Pass4sure
- Databricks-Certified-Professional-Data-Engineer Dumps Torrent 🍭 Databricks-Certified-Professional-Data-Engineer Pdf Torrent 🏂 Databricks-Certified-Professional-Data-Engineer Pdf Torrent ⛅ Search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 and obtain a free download on ➥ www.validtorrent.com 🡄 💈Databricks-Certified-Professional-Data-Engineer Pdf Free
- Latest Updated Databricks-Certified-Professional-Data-Engineer New Questions | Newest New Databricks-Certified-Professional-Data-Engineer Test Syllabus: Databricks Certified Professional Data Engineer Exam 🕌 Open [ www.pdfvce.com ] and search for 「 Databricks-Certified-Professional-Data-Engineer 」 to download exam materials for free 🏝New Databricks-Certified-Professional-Data-Engineer Test Practice
- Databricks Certified Professional Data Engineer Exam study guide - Databricks-Certified-Professional-Data-Engineer reliable questions - Databricks Certified Professional Data Engineer Exam pdf dumps 🤲 Search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ and download it for free on ⮆ www.prepawayete.com ⮄ website ⚾Databricks-Certified-Professional-Data-Engineer Sample Exam
- Databricks-Certified-Professional-Data-Engineer Latest Test Online 📈 Latest Databricks-Certified-Professional-Data-Engineer Test Questions 😫 Databricks-Certified-Professional-Data-Engineer Dumps Torrent 🦙 Easily obtain free download of ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ by searching on “ www.pdfvce.com ” 🤾Databricks-Certified-Professional-Data-Engineer Pdf Torrent
- Reliable Databricks-Certified-Professional-Data-Engineer Test Camp 🏃 Databricks-Certified-Professional-Data-Engineer Valid Exam Tutorial 🥱 Reliable Databricks-Certified-Professional-Data-Engineer Test Materials 💒 Download ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free by simply searching on ▷ www.exam4labs.com ◁ 🎫Databricks-Certified-Professional-Data-Engineer Latest Test Online
- Databricks-Certified-Professional-Data-Engineer Pdf Free ✴ Visual Databricks-Certified-Professional-Data-Engineer Cert Test 🌔 Databricks-Certified-Professional-Data-Engineer Latest Test Online 😢 Copy URL ▷ www.pdfvce.com ◁ open and search for 《 Databricks-Certified-Professional-Data-Engineer 》 to download for free 📇Databricks-Certified-Professional-Data-Engineer Pdf Torrent
- Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer –Newest New Questions 🍄 Easily obtain 「 Databricks-Certified-Professional-Data-Engineer 」 for free download through ☀ www.verifieddumps.com ️☀️ 🖕New Databricks-Certified-Professional-Data-Engineer Test Topics
- Free PDF Quiz Databricks - Fantastic Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam New Questions 🍚 Download ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free by simply entering ( www.pdfvce.com ) website 👷Databricks-Certified-Professional-Data-Engineer Sample Exam
- Latest Updated Databricks-Certified-Professional-Data-Engineer New Questions | Newest New Databricks-Certified-Professional-Data-Engineer Test Syllabus: Databricks Certified Professional Data Engineer Exam 🌒 Search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 on ▶ www.prepawayete.com ◀ immediately to obtain a free download 🌤Databricks-Certified-Professional-Data-Engineer Latest Test Online
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.twosapp.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, justpaste.me, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes