DOWNLOAD the newest DumpsQuestion ACD-301 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1wQ0G8d0GEH0JfOEOAo9Z_ifYvpBhMLb1
DumpsQuestion is a globally famous IT exam provider, offering the valid and latest Appian ACD-301 study material to all the candidates. Our mission is to provide quality ACD-301 vce dumps which is easy to understand. There are ACD-301 free demo for you to be downloaded. The purpose of the ACD-301 demo is to show our ACD-301 quality material to valuable customers. If you are satisfied with our ACD-301 latest dumps, you can rest assured to buy it.
| Section | Objectives |
|---|---|
| Process Modeling | - Advanced process model design - Exception handling and optimization |
| User Interface Design | - User experience best practices - Interface design and dynamic layouts |
| Data Management | - Data types and CDT structures - Record types and data stores |
| Application Design and Architecture | - Reusable components and design patterns - Solution structuring and application layering |
| Security and Deployment | - Deployment pipelines and environment management - Security roles and group management |
| Expression Language and Logic | - Advanced Appian expression functions - Rule design and optimization |
Highlight a person's learning effect is not enough, because it is difficult to grasp the difficulty of testing, a person cannot be effective information feedback, in order to solve this problem, our ACD-301 study materials provide a powerful platform for users, allow users to exchange of experience. Here, the all users of our ACD-301 Study Materials can through own id to login to the platform, realize the exchange and sharing with other users, even on the platform and more users to become good friends, encourage each other, to deal with the difficulties encountered in the process of preparation each other.
NEW QUESTION # 45
You are developing a case management application to manage support cases for a large set of sites. One of the tabs in this application s site Is a record grid of cases, along with Information about the site corresponding to that case. Users must be able to filter cases by priority level and status.
You decide to create a view as the source of your entity-backed record, which joins the separate case/site tables (as depicted in the following Image).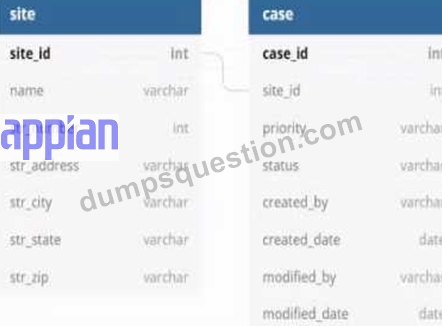
Which three column should be indexed?
Answer: B,C,E
Explanation:
Indexing columns can improve the performance of queries that use those columns in filters, joins, or order by clauses. In this case, the columns that should be indexed are site_id, status, and priority, because they are used for filtering or joining the tables. Site_id is used to join the case and site tables, so indexing it will speed up the join operation. Status and priority are used to filter the cases by the user's input, so indexing them will reduce the number of rows that need to be scanned. Name, modified_date, and case_id do not need to be indexed, because they are not used for filtering or joining. Name and modified_date are only used for displaying information in the record grid, and case_id is only used as a unique identifier for each record. Verified Appian Records Tutorial,Appian Best Practices As an Appian Lead Developer, optimizing a database view for an entity-backed record grid requires indexing columns frequently used in queries, particularly for filtering and joining. The scenario involves a record grid displaying cases with site information, filtered by "priority level" and "status," and joined via the site_id foreign key. The image shows two tables (site and case) with a relationship via site_id. Let's evaluate each column based on Appian's performance best practices and query patterns:
A . site_id:This is a primary key in the site table and a foreign key in the case table, used for joining the tables in the view. Indexing site_id in the case table (and ensuring it's indexed in site as a PK) optimizes JOIN operations, reducing query execution time for the record grid. Appian's documentation recommends indexing foreign keys in large datasets to improve query performance, especially for entity-backed records. This is critical for the join and must be included.
B . status:Users filter cases by "status" (a varchar column in the case table). Indexing status speeds up filtering queries (e.g., WHERE status = 'Open') in the record grid, particularly with large datasets. Appian emphasizes indexing columns used in WHERE clauses or filters to enhance performance, making this a key column for optimization. Since status is a common filter, it's essential.
C . name:This is a varchar column in the site table, likely used for display (e.g., site name in the grid). However, the scenario doesn't mention filtering or sorting by name, and it's not part of the join or required filters. Indexing name could improve searches if used, but it's not a priority given the focus on priority and status filters. Appian advises indexing only frequently queried or filtered columns to avoid unnecessary overhead, so this isn't necessary here.
D . modified_date:This is a date column in the case table, tracking when cases were last updated. While useful for sorting or historical queries, the scenario doesn't specify filtering or sorting by modified_date in the record grid. Indexing it could help if used, but it's not critical for the current requirements. Appian's performance guidelines prioritize indexing columns in active filters, making this lower priority than site_id, status, and priority.
E . priority:Users filter cases by "priority level" (a varchar column in the case table). Indexing priority optimizes filtering queries (e.g., WHERE priority = 'High') in the record grid, similar to status. Appian's documentation highlights indexing columns used in WHERE clauses for entity-backed records, especially with large datasets. Since priority is a specified filter, it's essential to include.
F . case_id:This is the primary key in the case table, already indexed by default (as PKs are automatically indexed in most databases). Indexing it again is redundant and unnecessary, as Appian's Data Store configuration relies on PKs for unique identification but doesn't require additional indexing for performance in this context. The focus is on join and filter columns, not the PK itself.
Conclusion: The three columns to index are A (site_id), B (status), and E (priority). These optimize the JOIN (site_id) and filter performance (status, priority) for the record grid, aligning with Appian's recommendations for entity-backed records and large datasets. Indexing these columns ensures efficient querying for user filters, critical for the application's performance.
Appian Documentation: "Performance Best Practices for Data Stores" (Indexing Strategies).
Appian Lead Developer Certification: Data Management Module (Optimizing Entity-Backed Records).
Appian Best Practices: "Working with Large Data Volumes" (Indexing for Query Performance).
NEW QUESTION # 46
You are reviewing the Engine Performance Logs in Production for a single application that has been live for six months. This application experiences concurrent user activity and has a fairly sustained load during business hours. The client has reported performance issues with the application during business hours.During your investigation, you notice a high Work Queue - Java Work Queue Size value in the logs. You also notice unattended process activities, including timer events and sending notification emails, are taking far longer to execute than normal.The client increased the number of CPU cores prior to the application going live.What is the next recommendation?
Answer: A
Explanation:
As an Appian Lead Developer, analyzing Engine Performance Logs to address performance issues in a Production application requires understanding Appian's architecture and the specific metrics described. The scenario indicates a high "Work Queue - Java Work Queue Size," which reflects a backlog of tasks in the Java Work Queue (managed by Appian engines), and delays in unattended process activities (e.g., timer events, email notifications). These symptoms suggest the Appian engines are overloaded, despite the client increasing CPU cores. Let's evaluate each option:
A . Add more engine replicas:This is the correct recommendation. In Appian, engine replicas (part of the Appian Engine cluster) handle process execution, including unattended tasks like timers and notifications. A high Java Work Queue Size indicates the engines are overwhelmed by concurrent activity during business hours, causing delays. Adding more engine replicas distributes the workload, reducing queue size and improving performance for both user-driven and unattended tasks. Appian's documentation recommends scaling engine replicas to handle sustained loads, especially in Production with high concurrency. Since CPU cores were already increased (likely on application servers), the bottleneck is likely the engine capacity, not the servers.
B . Optimize slow-performing user interfaces:While optimizing user interfaces (e.g., SAIL forms, reports) can improve user experience, the scenario highlights delays in unattended activities (timers, emails), not UI performance. The Java Work Queue Size issue points to engine-level processing, not UI rendering, so this doesn't address the root cause. Appian's performance tuning guidelines prioritize engine scaling for queue-related issues, making this a secondary concern.
C . Add more application servers:Application servers handle web traffic (e.g., SAIL interfaces, API calls), not process execution or unattended tasks managed by engines. Increasing application servers would help with UI concurrency but wouldn't reduce the Java Work Queue Size or speed up timer/email processing, as these are engine responsibilities. Since the client already increased CPU cores (likely on application servers), this is redundant and unrelated to the issue.
D . Add execution and analytics shards:Execution shards (for process data) and analytics shards (for reporting) are part of Appian's data fabric for scalability, but they don't directly address engine workload or Java Work Queue Size. Shards optimize data storage and query performance, not real-time process execution. The logs indicate an engine bottleneck, not a data storage issue, so this isn't relevant. Appian's documentation confirms shards are for long-term scaling, not immediate performance fixes.
Conclusion: Adding more engine replicas (A) is the next recommendation. It directly resolves the high Java Work Queue Size and delays in unattended tasks, aligning with Appian's architecture for handling concurrent loads in Production. This requires collaboration with system administrators to configure additional replicas in the Appian cluster.
Appian Documentation: "Engine Performance Monitoring" (Java Work Queue and Scaling Replicas).
Appian Lead Developer Certification: Performance Optimization Module (Engine Scaling Strategies).
Appian Best Practices: "Managing Production Performance" (Work Queue Analysis).
NEW QUESTION # 47
For each scenario outlined, match the best tool to use to meet expectations. Each tool will be used once Note: To change your responses, you may deselected your response by clicking the blank space at the top of the selection list.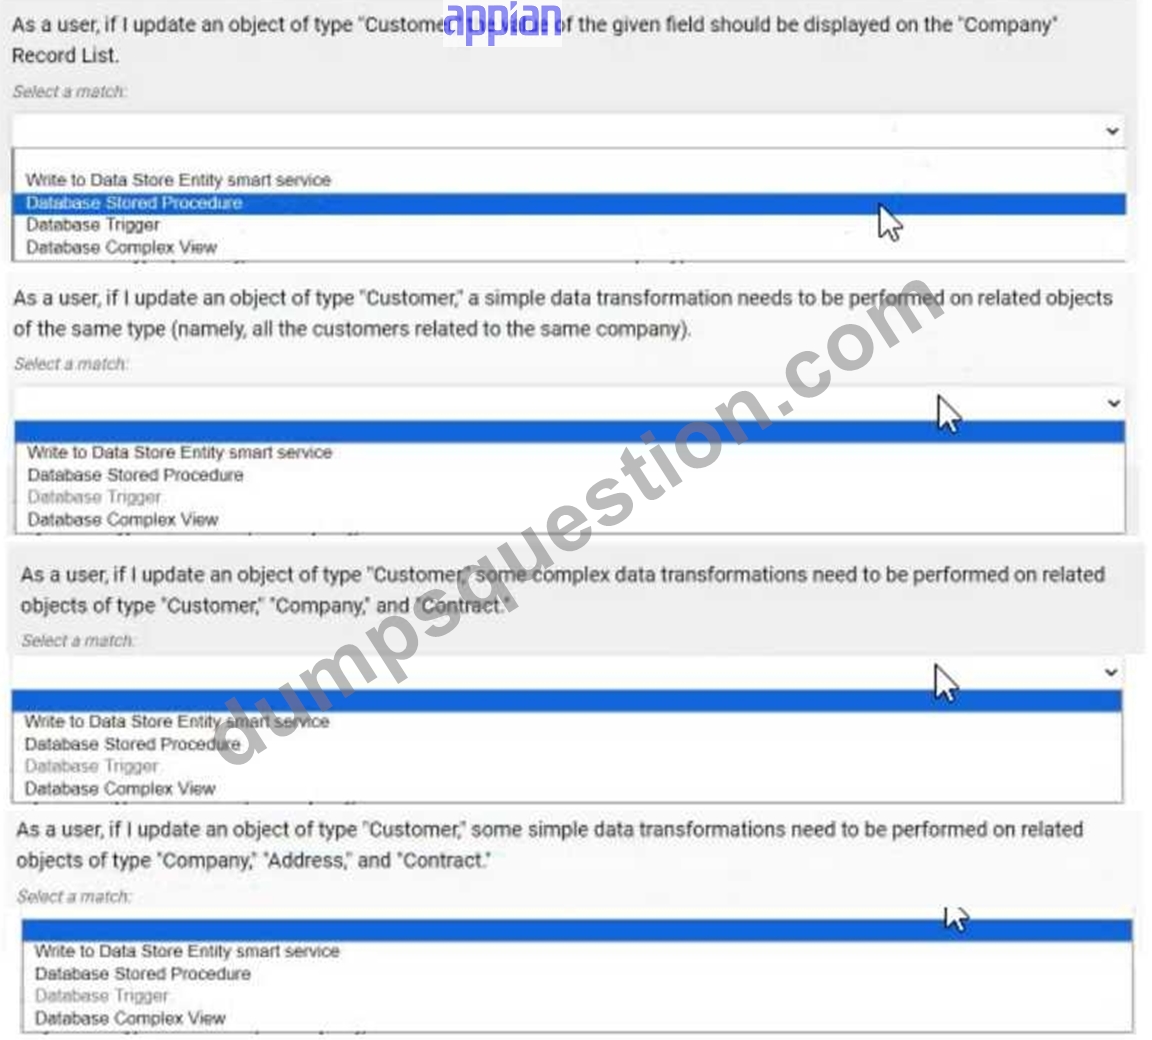
Answer:
Explanation: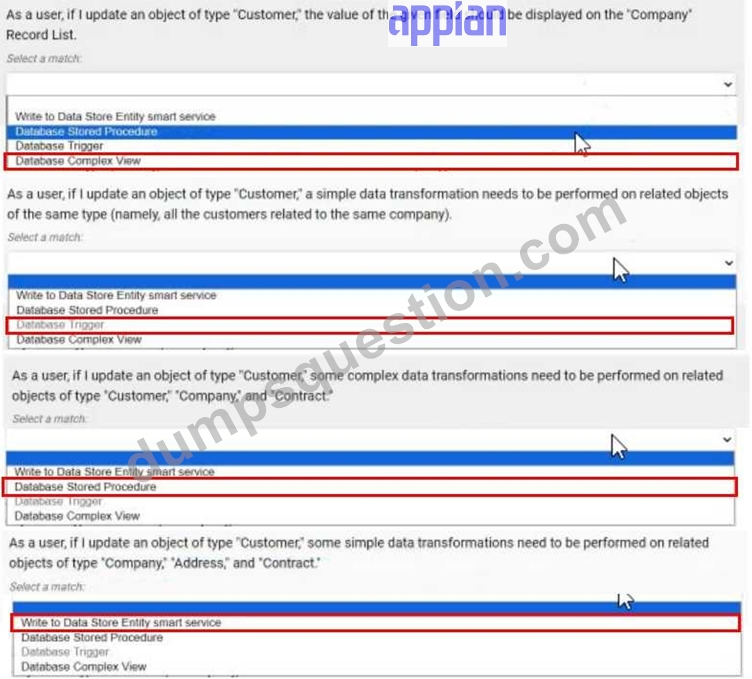
NEW QUESTION # 48
You have 5 applications on your Appian platform in Production. Users are now beginning to use multiple applications across the platform, and the client wants to ensure a consistent user experience across all applications.
You notice that some applications use rich text, some use section layouts, and others use box layouts. The result is that each application has a different color and size for the header.
What would you recommend to ensure consistency across the platform?
Answer: B
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, ensuring a consistent user experience across multiple applications on the Appian platform involves centralizing reusable components and adhering to Appian's design governance principles. The client's concern about inconsistent headers (e.g., different colors, sizes, layouts) across applications using rich text, section layouts, and box layouts requires a scalable, maintainable solution. Let's evaluate each option:
A . Create constants for text size and color, and update each section to reference these values:
Using constants (e.g., cons!TEXT_SIZE and cons!HEADER_COLOR) is a good practice for managing values, but it doesn't address layout consistency (e.g., rich text vs. section layouts vs. box layouts). Constants alone can't enforce uniform header design across applications, as they don't encapsulate layout logic (e.g., a!sectionLayout() vs. a!richTextDisplayField()). This approach would require manual updates to each application's components, increasing maintenance overhead and still risking inconsistency. Appian's documentation recommends using rules for reusable UI components, not just constants, making this insufficient.
B . In the common application, create a rule that can be used across the platform for section headers, and update each application to reference this new rule:
This is the best recommendation. Appian supports a "common application" (often called a shared or utility application) to store reusable objects like expression rules, which can define consistent header designs (e.g., rule!CommonHeader(size: "LARGE", color: "PRIMARY")). By creating a single rule for headers and referencing it across all 5 applications, you ensure uniformity in layout, color, and size (e.g., using a!sectionLayout() or a!boxLayout() consistently). Appian's design best practices emphasize centralizing UI components in a common application to reduce duplication, enforce standards, and simplify maintenance-perfect for achieving a consistent user experience.
C . In the common application, create one rule for each application, and update each application to reference its respective rule:
This approach creates separate header rules for each application (e.g., rule!App1Header, rule!App2Header), which contradicts the goal of consistency. While housed in the common application, it introduces variability (e.g., different colors or sizes per rule), defeating the purpose. Appian's governance guidelines advocate for a single, shared rule to maintain uniformity, making this less efficient and unnecessary.
D . In each individual application, create a rule that can be used for section headers, and update each application to reference its respective rule:
Creating separate rules in each application (e.g., rule!App1Header in App 1, rule!App2Header in App 2) leads to duplication and inconsistency, as each rule could differ in design. This approach increases maintenance effort and risks diverging styles, violating the client's requirement for a "consistent user experience." Appian's best practices discourage duplicating UI logic, favoring centralized rules in a common application instead.
Conclusion: Creating a rule in the common application for section headers and referencing it across the platform (B) ensures consistency in header design (color, size, layout) while minimizing duplication and maintenance. This leverages Appian's application architecture for shared objects, aligning with Lead Developer standards for UI governance.
Appian Documentation: "Designing for Consistency Across Applications" (Common Application Best Practices).
Appian Lead Developer Certification: UI Design Module (Reusable Components and Rules).
Appian Best Practices: "Maintaining User Experience Consistency" (Centralized UI Rules).
The best way to ensure consistency across the platform is to create a rule that can be used across the platform for section headers. This rule can be created in the common application, and then each application can be updated to reference this rule. This will ensure that all of the applications use the same color and size for the header, which will provide a consistent user experience.
The other options are not as effective. Option A, creating constants for text size and color, and updating each section to reference these values, would require updating each section in each application. This would be a lot of work, and it would be easy to make mistakes. Option C, creating one rule for each application, would also require updating each application. This would be less work than option A, but it would still be a lot of work, and it would be easy to make mistakes. Option D, creating a rule in each individual application, would not ensure consistency across the platform. Each application would have its own rule, and the rules could be different. This would not provide a consistent user experience.
Best Practices:
When designing a platform, it is important to consider the user experience. A consistent user experience will make it easier for users to learn and use the platform.
When creating rules, it is important to use them consistently across the platform. This will ensure that the platform has a consistent look and feel.
When updating the platform, it is important to test the changes to ensure that they do not break the user experience.
NEW QUESTION # 49
You are the lead developer for an Appian project, in a backlog refinement meeting. You are presented with the following user story:
"As a restaurant customer, I need to be able to place my food order online to avoid waiting in line for takeout." Which two functional acceptance criteria would you consider 'good'?
Answer: C,D
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, defining "good" functional acceptance criteria for a user story requires ensuring they are specific, testable, and directly tied to the user's need (placing an online food order to avoid waiting in line). Good criteria focus on functionality, usability, and reliability, aligning with Appian's Agile and design best practices. Let's evaluate each option:
A . The user will click Save, and the order information will be saved in the ORDER table and have audit history:
This is a "good" criterion. It directly validates the core functionality of the user story-placing an order online. Saving order data in the ORDER table (likely via a process model or Data Store Entity) ensures persistence, and audit history (e.g., using Appian's audit logs or database triggers) tracks changes, supporting traceability and compliance. This is specific, testable (e.g., verify data in the table and logs), and essential for the user's goal, aligning with Appian's data management and user experience guidelines.
B . The user will receive an email notification when their order is completed:
While useful, this is a "nice-to-have" enhancement, not a core requirement of the user story. The story focuses on placing an order online to avoid waiting, not on completion notifications. Email notifications add value but aren't essential for validating the primary functionality. Appian's user story best practices prioritize criteria tied to the main user need, making this secondary and not "good" in this context.
C . The system must handle up to 500 unique orders per day:
This is a non-functional requirement (performance/scalability), not a functional acceptance criterion. It describes system capacity, not specific user behavior or functionality. While important for design, it's not directly testable for the user story's outcome (placing an order) and isn't tied to the user's experience. Appian's Agile methodologies separate functional and non-functional requirements, making this less relevant as a "good" criterion here.
D . The user cannot submit the form without filling out all required fields:
This is a "good" criterion. It ensures data integrity and usability by preventing incomplete orders, directly supporting the user's ability to place a valid online order. In Appian, this can be implemented using form validation (e.g., required attributes in SAIL interfaces or process model validations), making it specific, testable (e.g., verify form submission fails with missing fields), and critical for a reliable user experience. This aligns with Appian's UI design and user story validation standards.
Conclusion: The two "good" functional acceptance criteria are A (order saved with audit history) and D (required fields enforced). These directly validate the user story's functionality (placing a valid order online), are testable, and ensure a reliable, user-friendly experience-aligning with Appian's Agile and design best practices for user stories.
Appian Documentation: "Writing Effective User Stories and Acceptance Criteria" (Functional Requirements).
Appian Lead Developer Certification: Agile Development Module (Acceptance Criteria Best Practices).
Appian Best Practices: "Designing User Interfaces in Appian" (Form Validation and Data Persistence).
NEW QUESTION # 50
......
Our ACD-301 guide torrent has gone through strict analysis and summary according to the past exam papers and the popular trend in the industry and are revised and updated. The ACD-301 exam questions have simplified the sophisticated notions. The software boosts varied self-learning and self-assessment functions to check the learning results. The software of our ACD-301 Test Torrent provides the statistics report function and help the students find the weak links and deal with them. With this version of our ACD-301 exam questions, you will be able to pass the exam easily.
ACD-301 Reliable Exam Practice: https://www.dumpsquestion.com/ACD-301-exam-dumps-collection.html
What's more, part of that DumpsQuestion ACD-301 dumps now are free: https://drive.google.com/open?id=1wQ0G8d0GEH0JfOEOAo9Z_ifYvpBhMLb1