P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by Prep4sureExam: https://drive.google.com/open?id=1DbmsKY2QHNZAFTYL4AKEdODrMsM2NaFW
We provide free update of our DP-100 exam materials within one year and after one year the client can enjoy the 50% discounts. The old clients enjoy some certain discounts when they buy our DP-100 exam torrent. Our experts check whether there is the update of the test bank every day and if there is an updated version of our DP-100 learning guide, then the system will send it to the client automatically. And that is one of the reasons why our DP-100 study materials are so popular for we give more favourable prices and more considerable service for our customers.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
|
| Topic 2: Explore data and run experiments | 20-25% | - Implement pipelines
|
| Topic 3: Design and prepare a machine learning solution | 20-25% | - Manage data assets
|
| Topic 4: Train and deploy models | 25-30% | - Deploy models
|
Being respected and gaining a high social status maybe what you always long for. But if you want to achieve that you must own good abilities and profound knowledge in some certain area. You only need 20-30 hours to learn and prepare for the exam, because it is enough for you to grasp all content of our study materials, and the passing rate is very high and about 98%-100%. Our laTest DP-100 Quiz torrent provides 3 versions and you can choose the most suitable one for you to learn. All in all, there are many merits of our DP-100 quiz prep.
NEW QUESTION # 219
You need to produce a visualization for the diagnostic test evaluation according to the data visualization requirements.
Which three modules should you recommend be used in sequence? To answer, move the appropriate modules from the list of modules to the answer area and arrange them in the correct order.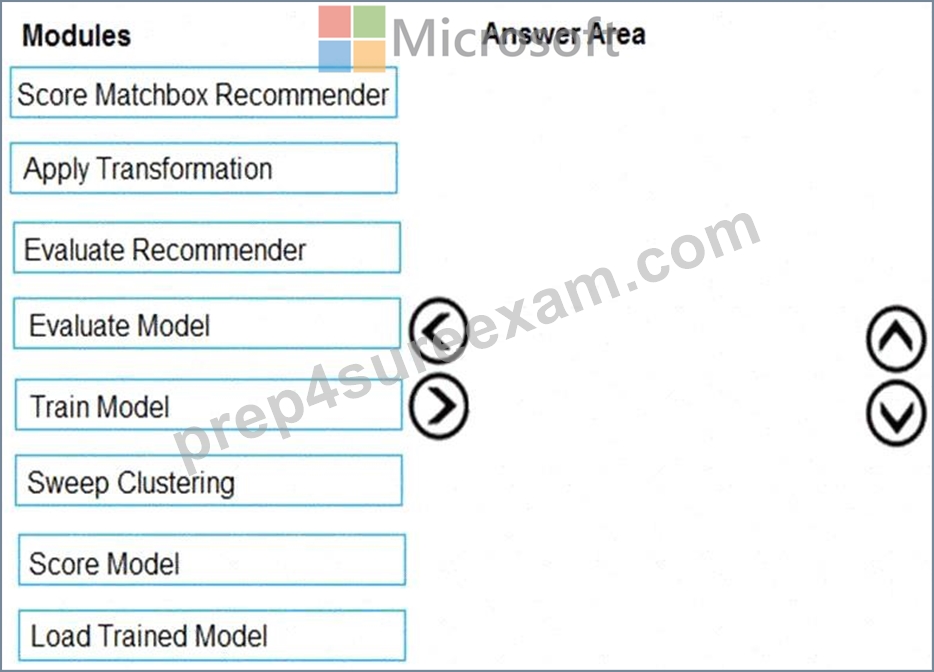
Answer:
Explanation: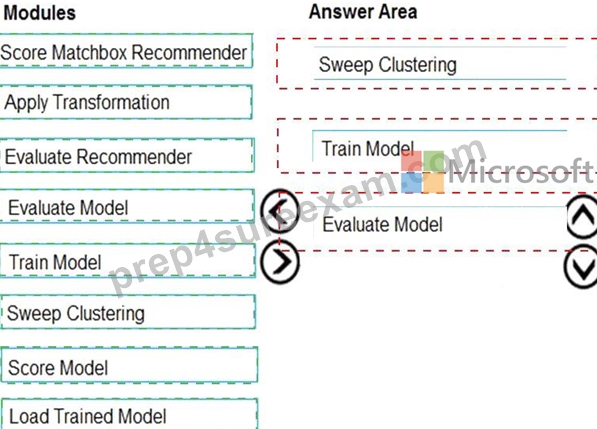
Explanation: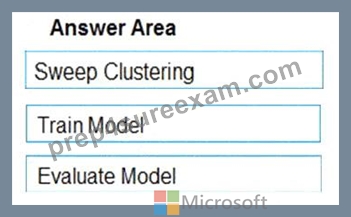
Step 1: Sweep Clustering
Start by using the "Tune Model Hyperparameters" module to select the best sets of parameters for each of the models we're considering.
One of the interesting things about the "Tune Model Hyperparameters" module is that it not only outputs the results from the Tuning, it also outputs the Trained Model.
Step 2: Train Model
Step 3: Evaluate Model
Scenario: You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
References:
http://breaking-bi.blogspot.com/2017/01/azure-machine-learning-model-evaluation.html
NEW QUESTION # 220
You have an Azure Machine Learning workspace.
You plan to use Azure Machine Learning designer to register multiple components in the workspace.
You need to configure the component that supports the registration.
Which component configuration should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.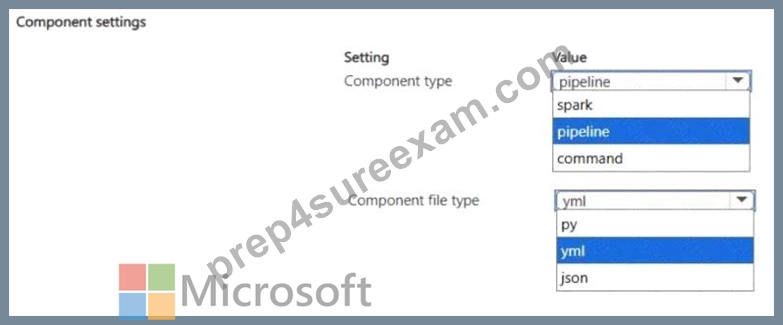
Answer:
Explanation: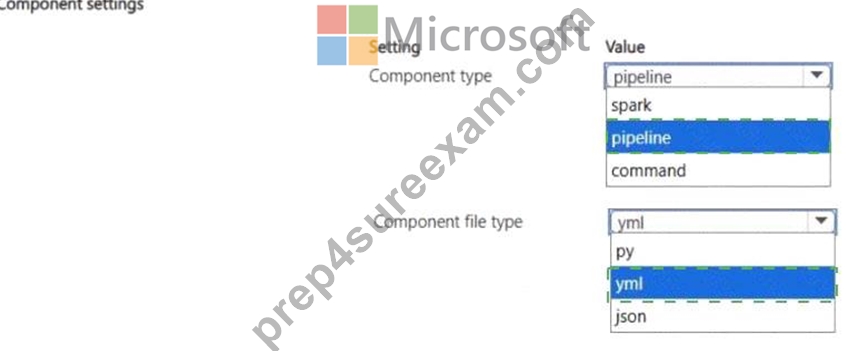
Explanation: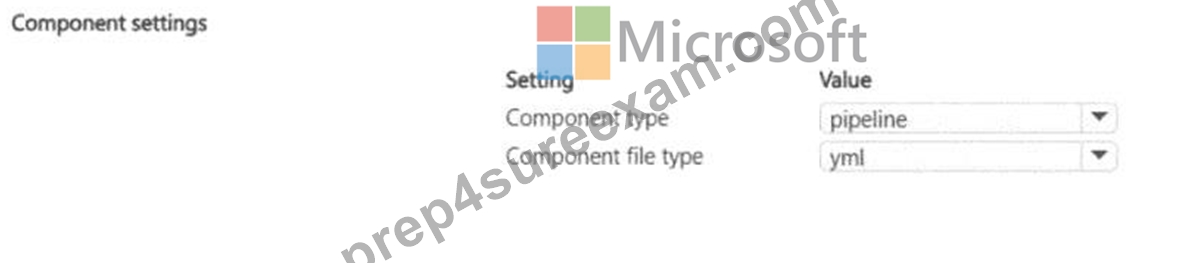
NEW QUESTION # 221
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupyter notebook in the workspace. The experiment must log string metrics. You need to implement the method to log the string metrics. Which method should you use?
Answer: A
NEW QUESTION # 222
You create a multi-class image classification deep learning model.
You train the model by using PyTorch version 1.2.
You need to ensure that the correct version of PyTorch can be identified for the inferencing environment when the model is deployed.
What should you do?
Answer: D
Explanation:
framework_version: The PyTorch version to be used for executing training code.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-train-core/azureml.train.dnn.pytorch?view=azure-ml-py Prepare data for modeling Testlet 1 Case study Overview You are a data scientist in a company that provides data science for professional sporting events. Models will use global and local market data to meet the following business goals:
* Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
* Assess a user's tendency to respond to an advertisement.
* Customize styles of ads served on mobile devices.
* Use video to detect penalty events
Current environment
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and shared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes; recorded video transcripts or radio commentary, and logs from related social media feeds captured during the sporting events.
* Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo formats.
Penalty detection and sentiment
* Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
* Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation.
* Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
* Global penalty detection models must be trained by using dynamic runtime graph computation during training.
* Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics available.
Advertisements
During the initial weeks in production, the following was observed:
* Ad response rated declined.
* Drops were not consistent across ad styles.
* The distribution of features across training and production data are not consistent Analysis shows that, of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrelated features.
* Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
* All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too slow.
* Audio samples show that the length of a catch phrase varies between 25%-47% depending on region
* The performance of the global penalty detection models shows lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation models must optimize for similar ad response history.
* Sampling must guarantee mutual and collective exclusively between local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Ad response models must support non-linear boundaries of features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviated from
0.1 +/- 5%.
* The ad propensity model uses cost factors shown in the following diagram: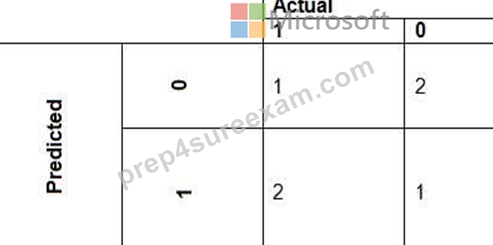
* The ad propensity model uses proposed cost factors shown in the following diagram: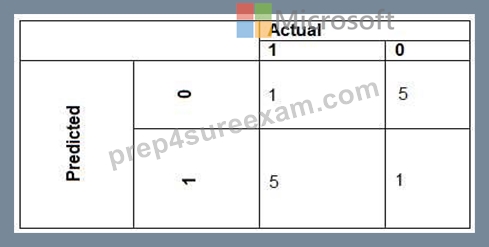
* Performance curves of current and proposed cost factor scenarios are shown in the following diagram: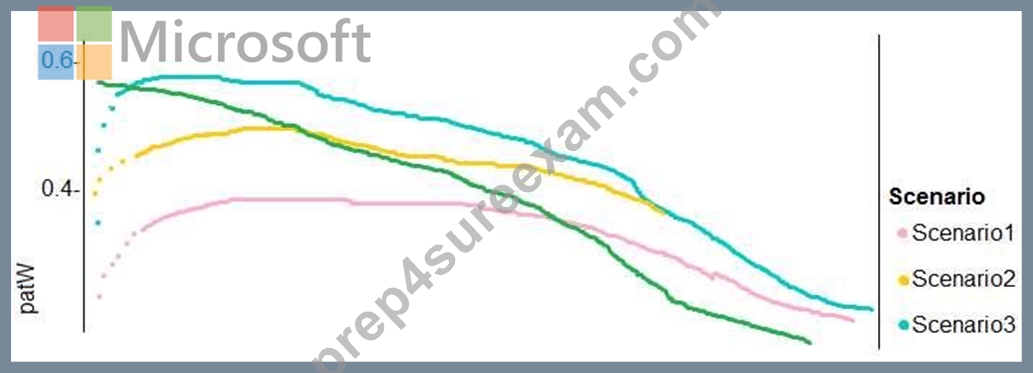
NEW QUESTION # 223
You create a batch inference pipeline by using the Azure ML SDK. You run the pipeline by using the following code:
from azureml.pipeline.core import Pipeline
from azureml.core.experiment import Experiment
pipeline = Pipeline(workspace=ws, steps=[parallelrun_step])
pipeline_run = Experiment(ws, 'batch_pipeline').submit(pipeline)
You need to monitor the progress of the pipeline execution.
What are two possible ways to achieve this goal? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.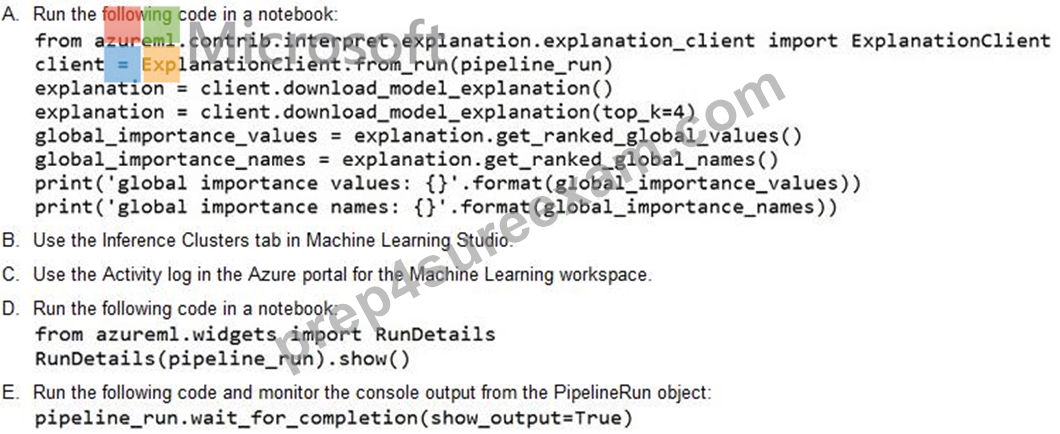
Answer: A,B
Explanation:
A batch inference job can take a long time to finish. This example monitors progress by using a Jupyter widget. You can also manage the job's progress by using:
Azure Machine Learning Studio.
Console output from the PipelineRun object.
from azureml.widgets import RunDetails
RunDetails(pipeline_run).show()
pipeline_run.wait_for_completion(show_output=True)
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-use-parallel-run-step#monitor-the-parallel-run-job
NEW QUESTION # 224
......
Although a lot of products are cheap, but the quality is poor, perhaps users have the same concern for our DP-100 learning materials. Here, we solemnly promise to users that our product error rate is zero. Everything that appears in our products has been inspected by experts. In our DP-100 learning material, users will not even find a small error, such as spelling errors or grammatical errors. It is believed that no one is willing to buy defective products, so, the DP-100 study materials have established a strict quality control system.
DP-100 New Braindumps Pdf: https://www.prep4sureexam.com/DP-100-dumps-torrent.html
2026 Latest Prep4sureExam DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1DbmsKY2QHNZAFTYL4AKEdODrMsM2NaFW