Many clients worry that after they bought our Databricks-Generative-AI-Engineer-Associate exam simulation they might find the exam questions are outdated and waste their time, money and energy. There are no needs to worry about that situation because our Databricks-Generative-AI-Engineer-Associate study materials boost high-quality and it is proved by the high passing rate and hit rate. And we keep updating our Databricks-Generative-AI-Engineer-Associate learing quiz all the time. We provide the best Databricks-Generative-AI-Engineer-Associate practice guide and hope our sincere service will satisfy all the clients.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Databricks-Generative-AI-Engineer-Associate Latest Exam Preparation <<
As the captioned description said, our Databricks-Generative-AI-Engineer-Associate practice materials are filled with the newest points of knowledge about the exam. With many years of experience in this line, we not only compile real test content into our Databricks-Generative-AI-Engineer-Associate learning quiz, but the newest in to them. And our professionals always keep a close eye on the new changes of the subject and keep updating the Databricks-Generative-AI-Engineer-Associate study questions to the most accurate.
NEW QUESTION # 27
A Generative Al Engineer is developing a RAG application and would like to experiment with different embedding models to improve the application performance.
Which strategy for picking an embedding model should they choose?
Answer: A
Explanation:
The task involves improving a Retrieval-Augmented Generation (RAG) application's performance by experimenting with embedding models. The choice of embedding model impacts retrieval accuracy,which is critical for RAG systems. Let's evaluate the options based on Databricks Generative AI Engineer best practices.
* Option A: Pick an embedding model trained on related domain knowledge
* Embedding models trained on domain-specific data (e.g., industry-specific corpora) produce vectors that better capture the semantics of the application's context, improving retrieval relevance. For RAG, this is a key strategy to enhance performance.
* Databricks Reference:"For optimal retrieval in RAG systems, select embedding models aligned with the domain of your data"("Building LLM Applications with Databricks," 2023).
* Option B: Pick the most recent and most performant open LLM released at the time
* LLMs are not embedding models; they generate text, not embeddings for retrieval. While recent LLMs may be performant for generation, this doesn't address the embedding step in RAG. This option misunderstands the component being selected.
* Databricks Reference: Embedding models and LLMs are distinct in RAG workflows:
"Embedding models convert text to vectors, while LLMs generate responses"("Generative AI Cookbook").
* Option C: Pick the embedding model ranked highest on the Massive Text Embedding Benchmark (MTEB) leaderboard hosted by HuggingFace
* The MTEB leaderboard ranks models across general tasks, but high overall performance doesn't guarantee suitability for a specific domain. A top-ranked model might excel in generic contexts but underperform on the engineer's unique data.
* Databricks Reference: General performance is less critical than domain fit:"Benchmark rankings provide a starting point, but domain-specific evaluation is recommended"("Databricks Generative AI Engineer Guide").
* Option D: Pick an embedding model with multilingual support to support potential multilingual user questions
* Multilingual support is useful only if the application explicitly requires it. Without evidence of multilingual needs, this adds complexity without guaranteed performance gains for the current use case.
* Databricks Reference:"Choose features like multilingual support based on application requirements"("Building LLM-Powered Applications").
Conclusion: Option A is the best strategy because it prioritizes domain relevance, directly improving retrieval accuracy in a RAG system-aligning with Databricks' emphasis on tailoring models to specific use cases.
NEW QUESTION # 28
A Generative AI Engineer is developing a chatbot designed to assist users with insurance-related queries. The chatbot is built on a large language model (LLM) and is conversational. However, to maintain the chatbot's focus and to comply with company policy, it must not provide responses to questions about politics. Instead, when presented with political inquiries, the chatbot should respond with a standard message:
"Sorry, I cannot answer that. I am a chatbot that can only answer questions around insurance." Which framework type should be implemented to solve this?
Answer: B
Explanation:
In this scenario, the chatbot must avoid answering political questions and instead provide a standard message for such inquiries. Implementing aSafety Guardrailis the appropriate solution for this:
* What is a Safety Guardrail?Safety guardrails are mechanisms implemented in Generative AI systems to ensure the model behaves within specific bounds. In this case, it ensures the chatbot does not answer politically sensitive or irrelevant questions, which aligns with the business rules.
* Preventing Responses to Political Questions:The Safety Guardrail is programmed to detect specific types of inquiries (like political questions) and prevent the model from generating responses outside its intended domain. When such queries are detected, the guardrail intervenes and provides a pre-defined response: "Sorry, I cannot answer that. I am a chatbot that can only answer questions around insurance."
* How It Works in Practice:The LLM system can include aclassification layeror trigger rules based on specific keywords related to politics. When such terms are detected, the Safety Guardrail blocks the normal generation flow and responds with the fixed message.
* Why Other Options Are Less Suitable:
* B (Security Guardrail): This is more focused on protecting the system from security vulnerabilities or data breaches, not controlling the conversational focus.
* C (Contextual Guardrail): While context guardrails can limit responses based on context, safety guardrails are specifically about ensuring the chatbot stays within a safe conversational scope.
* D (Compliance Guardrail): Compliance guardrails are often related to legal and regulatory adherence, which is not directly relevant here.
Therefore, aSafety Guardrailis the right framework to ensure the chatbot only answers insurance-related queries and avoids political discussions.
NEW QUESTION # 29
A Generative AI Engineer at a legal firm is designing a RAG system to analyze historical legal cases. The system needs to process millions of court opinions and legal documents, already organized by time and topic, to track how interpretations of specific laws have evolved over time. All of these documents are in plain-text.
The engineer needs to choose a chunking method that would most effectively preserve continuity and the temporal nature of the cases. Which method do they choose?
Answer: C
Explanation:
In the context of legal document analysis where the " evolution of interpretation " is the primary goal, preserving narrative continuity is paramount. Windowed summarization with overlapping chunks is the most effective method for this use case. Overlapping (e.g., 10-15% of the chunk size) ensures that sentences or concepts split at the boundary of one chunk are preserved in the next, preventing the loss of critical context that often occurs in legal jargon. Furthermore, windowed summarization allows the system to condense long- form court opinions into manageable parts while maintaining the chronological " thread " of the argument.
While sentence-level embeddings with metadata (D) are useful for filtering, they often lack the sufficient context required to understand the nuances of a legal ruling. A windowed approach provides the LLM with enough surrounding text to understand the " why " behind a legal evolution, rather than just the " when. "
NEW QUESTION # 30
A Generative AI Engineer I using the code below to test setting up a vector store: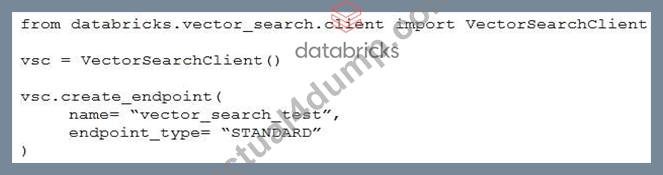
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: A
Explanation:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
NEW QUESTION # 31
All of the following are Python APIs used to query Databricks foundation models. When running in an interactive notebook, which of the following libraries does not automatically use the current session credentials?
Answer: B
Explanation:
When working within a Databricks notebook, several high-level SDKs are "Databricks-aware." The MLflow Deployments SDK (C) and the Databricks Python SDK (D) are designed to automatically look for the DATABRICKS_HOST and DATABRICKS_TOKEN environment variables provided by the notebook context. The OpenAI client (A), when configured for Databricks via Mosaic AI Gateway, also typically handles authentication via workspace integration in recent versions. However, the REST API via the requests library (B) is a generic Python HTTP client. It has no intrinsic knowledge of the Databricks environment. To use it, an engineer must manually extract the token (e.g., via dbutils.notebook.entry_point...) and explicitly pass it in the Authorization: Bearer <token> header of the request. Without this manual step, the requests library will fail with a 401 Unauthorized error.
NEW QUESTION # 32
......
How to get the test Databricks-Generative-AI-Engineer-Associate certification in a short time, which determines enough qualification certificates to test our learning ability and application level. This may be a contradiction of the problem, we hope to be able to spend less time and energy to take into account the test Databricks-Generative-AI-Engineer-Associate Certification, but the qualification examination of the learning process is very wasted energy, so how to achieve the balance? Our Databricks-Generative-AI-Engineer-Associate exam prep can be done with its high-efficient merit. Try it now!
Databricks-Generative-AI-Engineer-Associate Reliable Exam Testking: https://www.actual4dump.com/Databricks/Databricks-Generative-AI-Engineer-Associate-actualtests-dumps.html