BONUS!!! Download part of ActualTorrent SAA-C03 dumps for free: https://drive.google.com/open?id=1DYwbxIS6UbNH7aRiX4yTxWSyMIYajmLU
It is very convenient for all people to use the SAA-C03 study materials from our company. Our study materials will help a lot of people to solve many problems if they buy our products. The online version of SAA-C03 study materials from our company is not limited to any equipment, which means you can apply our study materials to all electronic equipment, including the telephone, computer and so on. So the online version of the SAA-C03 Study Materials from our company will be very useful for you to prepare for your exam. We believe that our SAA-C03 study materials will be a good choice for you.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design Cost-Optimized Architectures | 20% | - Design cost-effective compute and network solutions
|
| Topic 2: Design Secure Architectures | 30% | - Design secure workloads and applications
|
| Topic 3: Design High-Performing Architectures | 24% | - Design high-performance compute solutions
|
| Topic 4: Design Resilient Architectures | 26% | - Design highly available and fault-tolerant architectures
|
>> SAA-C03 Detailed Study Dumps <<
If you want to pass the exam in the shortest time, our SAA-C03 study materials can help you achieve this dream. Our SAA-C03 learning quiz according to your specific circumstances, for you to develop a suitable schedule and learning materials, so that you can prepare in the shortest possible time to pass the exam needs everything. If you use our SAA-C03 training prep, you only need to spend twenty to thirty hours to practice our SAA-C03 study materials, then you are ready to take the exam and pass it successfully.
NEW QUESTION # 906
An ecommerce company runs an application that uses an Amazon DynamoDB table in a single AWS Region.
The company wants to deploy the application to a second Region. The company needs to support multi-active replication with low latency reads and writes to the existing DynamoDB table in both Regions.
Which solution will meet these requirements in the MOST operationally efficient way?
Answer: C
Explanation:
Converting the existing DynamoDB table to aglobal tableprovides active-active replication and low-latency reads and writes in both Regions. DynamoDB global tables are specifically designed for multi-Region and multi-active use cases.
Option A:GSIs do not provide multi-Region replication or active-active capabilities.
Option B and D:Using DynamoDB Streams and custom replication is less operationally efficient than global tables and introduces additional complexity.
AWS Documentation References:
DynamoDB Global Tables
NEW QUESTION # 907
An Amazon EC2 administrator created the following policy associated with an IAM group containing several users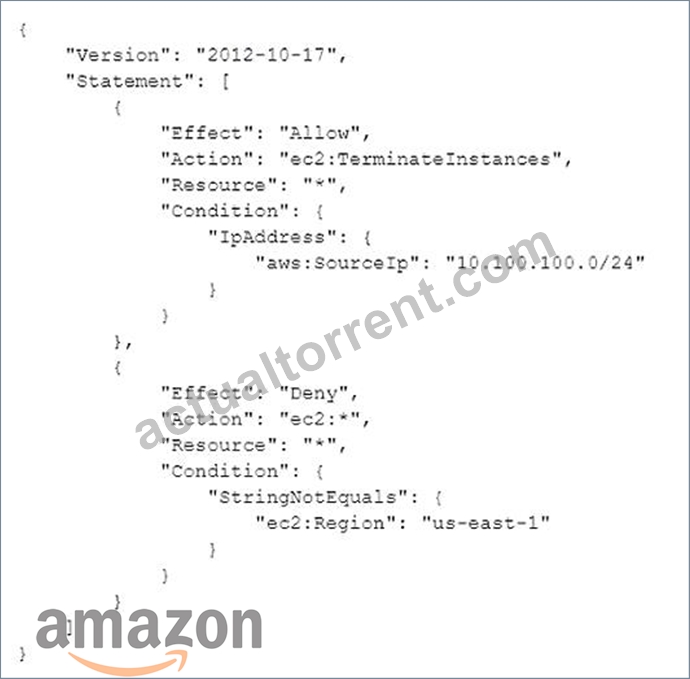
What is the effect of this policy?
Answer: D
Explanation:
as the policy prevents anyone from doing any EC2 action on any region except us-east-1 and allows only users with source ip 10.100.100.0/24 to terminate instances. So user with source ip 10.100.100.254 can terminate instances in us-east-1 region.
NEW QUESTION # 908
An Auto Scaling group (ASG) of Linux EC2 instances has an Amazon FSx for OpenZFS file system with basic monitoring enabled in CloudWatch. The Solutions Architect noticed that the legacy web application hosted in the ASG takes a long time to load. After checking the instances, the Architect noticed that the ASG is not launching more instances as it should be, even though the servers already have high memory usage.
Which of the following options should the Architect implement to solve this issue?
Answer: B
Explanation:
Amazon CloudWatch agent enables you to collect both system metrics and log files from Amazon EC2 instances and on-premises servers. The agent supports both Windows Server and Linux and allows you to select the metrics to be collected, including sub-resource metrics such as per-CPU core.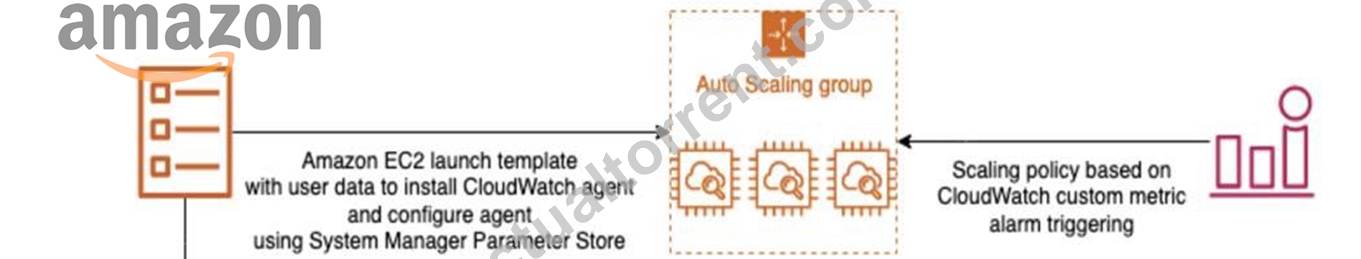
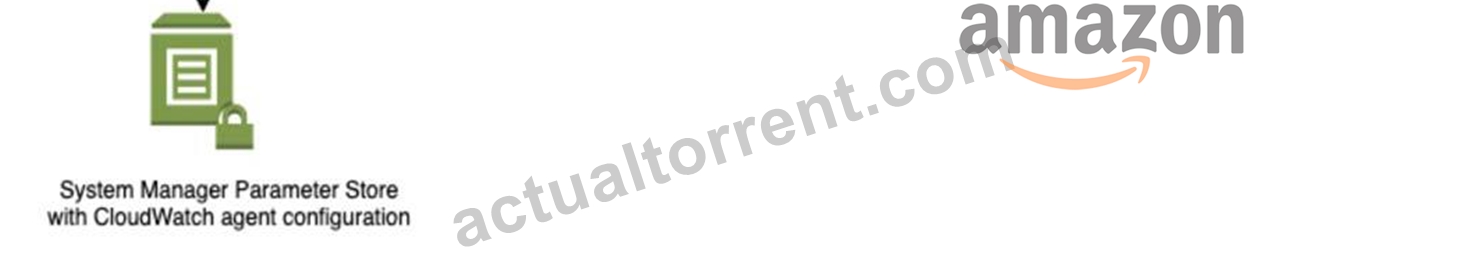
The premise of the scenario is that the EC2 servers have high memory usage, but since this specific metric is not tracked by the Auto Scaling group by default, the scaling out activity is not being triggered.
Remember that by default, CloudWatch doesn't monitor memory usage but only the CPU utilization, Network utilization, Disk performance, and Disk Reads/Writes.
This is the reason why you have to install a CloudWatch agent in your EC2 instances to collect and monitor the custom metric (memory usage), which will be used by your Auto Scaling Group as a trigger for scaling activities.
The AWS Systems Manager Parameter Store is one of the capabilities of AWS Systems Manager. It provides secure, hierarchical storage for configuration data management and secrets management. You can store data such as passwords, database strings, Amazon Machine Image (AMI) IDs, and license codes as parameter values. You can store values as plain text or encrypted data. You can reference Systems Manager parameters in your scripts, commands, SSM documents, and configuration and automation workflows by using the unique name that you specified when you created the parameter.
Hence, the correct answer is: Install the CloudWatch unified agent to the EC2 instances. Set up a custom parameter in AWS Systems Manager Parameter Store with the CloudWatch agent configuration to create an aggregated metric on memory usage percentage. Scale the Auto Scaling group based on the aggregated metric The option that says: Implement an AI solution that leverages Amazon Comprehend to track the near- real-time memory usage of each and every EC2 instance? Use Amazon SageMaker to automatically trigger the Auto Scaling event if there is high memory usage is incorrect because Amazon Comprehend cannot track near-real-time memory usage in Amazon EC2. This is just a natural-language processing (NLP) service that uses machine learning to uncover valuable insights and connections in text. Also, the use of an Amazon SageMaker in this scenario is not warranted since there is no machine learning requirement involved.
The option that says: Enable detailed monitoring on the Amazon EC2 instances of the Auto Scaling group. Use Amazon Forecast to automatically scale out the Auto Scaling group based on the aggregated memory usage of Amazon EC2 instances is incorrect because detailed monitoring does not provide metrics for memory usage. CloudWatch does not monitor memory usage in its default set of EC2 metrics and detailed monitoring just provides a higher frequency of metrics (1-minute frequency). Amazon Forecast is a time-series forecasting service based on machine learning (ML) and built for business metrics analysis - not for scaling out an Auto Scaling group based on an aggregated metfic.
The option that says: Set up Amazon Rekognition to automatically identify and recognize the cause of the high memory usage. Use the AWS Well-Architected Tool to automatically trigger the scale-out event in the ASG based on the overall memory usage is incorrect because Amazon Rekognition is simply an image recognition service that detects objects, scenes, and faces; extracts text; recognizes celebrities; and identifies inappropriate content in images. It can't be used to track the high memory usage of your Amazon EC2 instances. The AWS Well-Architected Tool, on the other hand, is designed to help you review the state of your applications and workloads. It merely provides a central place for architectural best practices in AWS and nothing more.
References:
https://docs.aws.amazon.com/AmazonCloudWatch/latest/monitoring/Install-CloudWatch-Agent.html
https://aws.amazon.com/blogs/mt/create-amazon-ec2-auto-scaling-policy-memory-utilization-metric-linux
/
https://docs.aws.amazon.com/systems-manager/latest/userguide/systems-manager-parameter-store.htm l Check out these Amazon EC2 and CloudWatch Cheat Sheets: https://tutorialsdojo.com/amazon-elastic- compute-cloud-amazon-ec2/ https://tutorialsdojo.com/amazon-cloudwatch/
NEW QUESTION # 909
[Design Resilient Architectures]
A company has a three-tier web application that processes orders from customers. The web tier consists of Amazon EC2 instances behind an Application Load Balancer. The processing tier consists of EC2 instances. The company decoupled the web tier and processing tier by using Amazon Simple Queue Service (Amazon SQS). The storage layer uses Amazon DynamoDB.
At peak times some users report order processing delays and halts. The company has noticed that during these delays, the EC2 instances are running at 100% CPU usage, and the SQS queue fills up. The peak times are variable and unpredictable.
The company needs to improve the performance of the application
Which solution will meet these requirements?
Answer: A
Explanation:
The issue in this case is related to the processing tier, where EC2 instances are overwhelmed at peak times, causing delays.Option D, using anAmazon EC2 Auto Scaling target tracking policybased on theApproximateNumberOfMessagesin the SQS queue, is the best solution.
Auto Scaling with Target Tracking:
Target tracking policiesdynamically scale out or in based on a specific metric. For this use case, you can monitor theApproximateNumberOfMessagesin the SQS queue. When the number of messages (orders) in the queue increases, the Auto Scaling group will scale out more EC2 instances to handle the additional load, ensuring that the queue doesn't build up and cause delays.
This solution is ideal for handling variable and unpredictable peak times, as Auto Scaling can automatically adjust based on real-time load rather than scheduled times.
Why Not the Other Options?:
Option A (Scheduled Scaling): Scheduled scaling works well for predictable peak times, but this company experiencesunpredictable peak usage, making scheduled scaling less effective.
Option B (ElastiCache for Redis): Adding a caching layer would help if DynamoDB were the bottleneck, but in this case, the issue is CPU overload on EC2 instances in the processing tier.
Option C (CloudFront): CloudFront would help cache static content from the web tier, but it wouldn't resolve the issue of the processing tier's overloaded EC2 instances.
AWS Reference:
Amazon EC2 Auto Scaling Target Tracking
Amazon SQS ApproximateNumberOfMessages
NEW QUESTION # 910
A company has deployed a server less application that invokes an AWS Lambda function when new documents are uploaded to an Amazon S3 bucket The application uses the Lambda function to process the documents After a recent marketing campaign the company noticed that the application did not process many of The documents What should a solutions architect do to improve the architecture of this application?
Answer: B
Explanation:
Explanation
To improve the architecture of this application, the best solution would be to use Amazon Simple Queue Service (Amazon SQS) to buffer the requests and decouple the S3 bucket from the Lambda function. This will ensure that the documents are not lost and can be processed at a later time if the Lambda function is not available. This will ensure that the documents are not lost and can be processed at a later time if the Lambda function is not available. By using Amazon SQS, the architecture is decoupled and the Lambda function can process the documents in a scalable and fault-tolerant manner
NEW QUESTION # 911
......
From the ActualTorrent platform, you will get the perfect match SAA-C03 actual test for study. SAA-C03 practice download pdf are researched and produced by Professional Certification Experts who are constantly using industry experience to produce precise, and logical SAA-C03 Training Material. SAA-C03 study material is constantly begining revised and updated for relevance and accuracy. You will pass your real test with our accurate SAA-C03 practice questions and answers.
SAA-C03 Latest Exam Book: https://www.actualtorrent.com/SAA-C03-questions-answers.html
BTW, DOWNLOAD part of ActualTorrent SAA-C03 dumps from Cloud Storage: https://drive.google.com/open?id=1DYwbxIS6UbNH7aRiX4yTxWSyMIYajmLU