Valid Databricks Certified-Data-Engineer-Professional Exam Questions | New Certified-Data-Engineer-Professional Test Camp

Free Databricks Certified-Data-Engineer-Professional exam questions demo download facility, affordable price, 100 percent Databricks Certified-Data-Engineer-Professional exam passing money back guarantee. All these three Databricks Certified-Data-Engineer-Professional exam questions features are designed to help you in Databricks Certified-Data-Engineer-Professional Exam Preparation and enable you to pass the final Databricks Certified-Data-Engineer-Professional certification exam easily.
| Section | Objectives |
|---|
| Topic 1: Data Modelling | - Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 2: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Compare streaming tables and materialized views
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Develop unit and integration tests for data processing code
- 7. Configure environments, dependencies, memory, and retry behavior
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 4: Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Analyze errors and remediate failed job runs
|
| Topic 5: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 6: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 7: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 8: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
|
| Topic 9: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Use row filters and column masks for sensitive data
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
>> Valid Databricks Certified-Data-Engineer-Professional Exam Questions <<
Free PDF Databricks - Certified-Data-Engineer-Professional –The Best Valid Exam Questions
After seeing you struggle, Actual4dump has come up with an idea to provide you with the actual and updated Databricks Certified-Data-Engineer-Professional practice questions so you can pass the Databricks Certified-Data-Engineer-Professional certification test on the first try and your hard work doesn't go to waste. Updated Certified-Data-Engineer-Professional Exam Dumps are essential to pass the Databricks Certified-Data-Engineer-Professional certification exam so you can advance your career in the technology industry and get a job in a good company that pays you well.
Databricks Certified Data Engineer Professional Sample Questions (Q233-Q238):
NEW QUESTION # 233
Each configuration below is identical to the extent that each cluster has 400 GB total of RAM 160 total cores and only one Executor per VM.
Given an extremely long-running job for which completion must be guaranteed, which cluster configuration will be able to guarantee completion of the job in light of one or more VM failures?
- A. - Total VMs: 2
- 200 GB per Executor
- 80 Cores / Executor - B. - Total VMs: 16
- 25 GB per Executor
- 10 Cores / Executor - C. - Total VMs: 8
- 50 GB per Executor
- 20 Cores / Executor - D. - Total VMs: 1
- 400 GB per Executor
- 160 Cores/Executor - E. - Total VMs: 4
- 100 GB per Executor
- 40 Cores / Executor
Answer: B
NEW QUESTION # 234
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
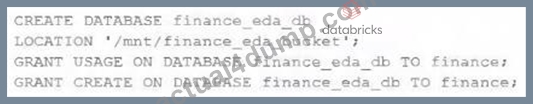
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
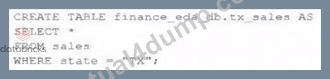
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. A managed table will be created in the DBFS root storage container.
- B. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- C. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
- D. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- E. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
Answer: E
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 235
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
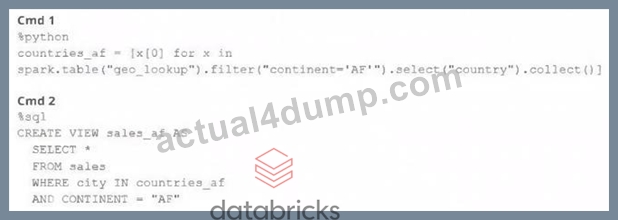
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
- B. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- C. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- D. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
- E. Both commands will fail. No new variables, tables, or views will be created.
Answer: D
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
NEW QUESTION # 236
A data engineer is tasked with ensuring that a Delta table in Databricks continuously retains deleted files for 15 days (instead of the default 7 days), in order to permanently comply with the organization's data retention policy. Which code snippet correctly sets this retention period for deleted files?
- A. spark.sql("VACUUM my_table RETAIN 15 HOURS")
- B. spark.conf.set("spark.databricks.delta.deletedFileRetentionDuration", "15 days")
- C. from delta.tables import *
deltaTable = DeltaTable.forPath(spark, "/mnt/data/my_table")
deltaTable.deletedFileRetentionDuration = "interval 15 days" - D. spark.sql("ALTER TABLE my_table SET TBLPROPERTIES
('delta.deletedFileRetentionDuration' = 'interval 15 days')")
Answer: D
Explanation:
The deleted file retention period in Delta Lake is controlled by the table property delta.deletedFileRetentionDuration. Setting this property via ALTER TABLE ensures the retention policy is persistently enforced at the table level, extending deleted file retention to 15 days in compliance with organizational requirements.
NEW QUESTION # 237
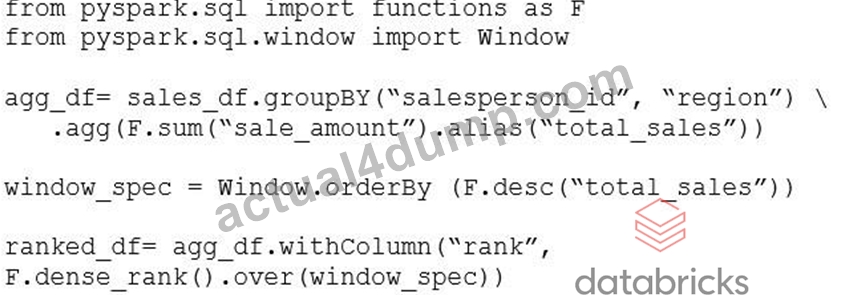
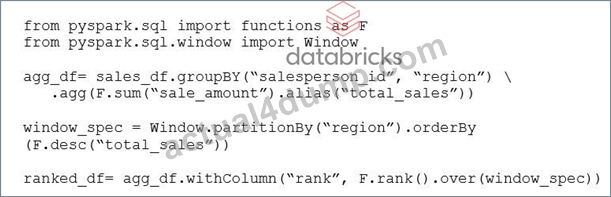
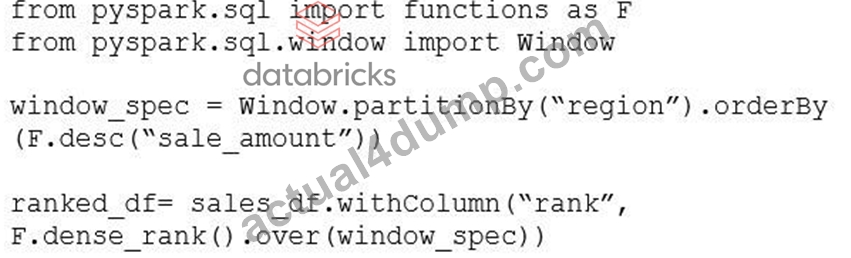
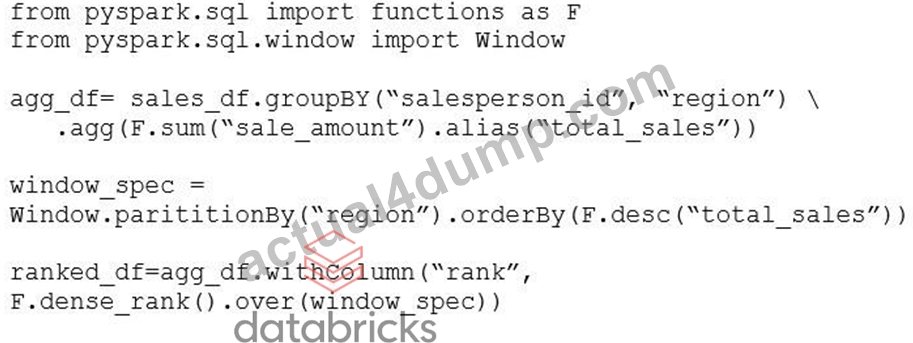
A data engineer is analyzing a large, partitioned retail dataset in Databricks, where each row represents a sale made by a salesperson. The dataset contains millions of records with the following schema:
sales_df: [salesperson_id: string, region: string, sale_amount: double, sale_date: date] The data engineer needs to generate a DataFrame that ranks salespeople within each region based on their total cumulative sales, with the highest seller ranked as 1. If multiple salespeople have the same total sales, they should share the same rank.
The data engineer wants to implement this logic using a PySpark window function and the dense_rank () function.
Which code snippet will perform this ranking?
Answer: D
Explanation:
This approach first aggregates sales by salesperson and region to compute total cumulative sales. It then applies a window function partitioned by region and ordered by total sales in descending order, using dense_rank to assign ranks so that salespeople with equal totals share the same rank and the highest total receives rank 1.
NEW QUESTION # 238
......
No doubt the Databricks Certified-Data-Engineer-Professional certification is a valuable credential that offers countless advantages to Certified-Data-Engineer-Professional exam holders. Beginners and experienced professionals can validate their skills and knowledge level with the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Exam and earn solid proof of their proven skills.
New Certified-Data-Engineer-Professional Test Camp: https://www.actual4dump.com/Databricks/Certified-Data-Engineer-Professional-actualtests-dumps.html
- Certified-Data-Engineer-Professional Exam Pdf - Certified-Data-Engineer-Professional Training Vce - Certified-Data-Engineer-Professional Torrent Updated 🗻 Open { www.practicevce.com } enter ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download 🚖Training Certified-Data-Engineer-Professional Kit
- Reliable Certified-Data-Engineer-Professional Exam Vce ⌛ Certified-Data-Engineer-Professional Reliable Dumps Sheet 🥳 Detail Certified-Data-Engineer-Professional Explanation 📪 Download 【 Certified-Data-Engineer-Professional 】 for free by simply searching on [ www.pdfvce.com ] 🐚Exam Sample Certified-Data-Engineer-Professional Online
- High Pass-Rate - How to Prepare for Databricks Certified-Data-Engineer-Professional Efficiently and Easily 📏 Enter ⏩ www.examdiscuss.com ⏪ and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download for free 🎊Reliable Certified-Data-Engineer-Professional Exam Preparation
- Valid Certified-Data-Engineer-Professional Exam Questions Offer You The Best New Test Camp to pass Databricks Certified Data Engineer Professional exam 🧸 ▷ www.pdfvce.com ◁ is best website to obtain ➽ Certified-Data-Engineer-Professional 🢪 for free download 🏖Training Certified-Data-Engineer-Professional Kit
- 100% Pass 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional –Valid Valid Exam Questions 🥩 Easily obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download through ➥ www.verifieddumps.com 🡄 🔹Certified-Data-Engineer-Professional Latest Mock Exam
- High Pass-Rate - How to Prepare for Databricks Certified-Data-Engineer-Professional Efficiently and Easily 🏰 ⮆ www.pdfvce.com ⮄ is best website to obtain 【 Certified-Data-Engineer-Professional 】 for free download 🐨Valid Certified-Data-Engineer-Professional Torrent
- Databricks Certified Data Engineer Professional latest braindumps - Certified-Data-Engineer-Professional sure pass torrent - Databricks Certified Data Engineer Professional free exam pdf 👸 Search for ✔ Certified-Data-Engineer-Professional ️✔️ on 【 www.examcollectionpass.com 】 immediately to obtain a free download 🆑Detail Certified-Data-Engineer-Professional Explanation
- Detail Certified-Data-Engineer-Professional Explanation 🔄 Test Certified-Data-Engineer-Professional Questions Answers 🎄 Test Certified-Data-Engineer-Professional Dumps.zip ♥ Open website ✔ www.pdfvce.com ️✔️ and search for 「 Certified-Data-Engineer-Professional 」 for free download 🔯Reliable Certified-Data-Engineer-Professional Exam Vce
- Certified-Data-Engineer-Professional Real Dump 🥑 Test Certified-Data-Engineer-Professional Simulator Online 🎵 Certified-Data-Engineer-Professional Exam Fee 🛕 Enter “ www.verifieddumps.com ” and search for ➠ Certified-Data-Engineer-Professional 🠰 to download for free 🏢Training Certified-Data-Engineer-Professional Kit
- Certified-Data-Engineer-Professional Latest Mock Exam 🃏 Exam Sample Certified-Data-Engineer-Professional Online 🎭 Reliable Certified-Data-Engineer-Professional Exam Vce ℹ ⏩ www.pdfvce.com ⏪ is best website to obtain { Certified-Data-Engineer-Professional } for free download ☁Reliable Certified-Data-Engineer-Professional Exam Vce
- Free Certified-Data-Engineer-Professional dumps torrent - Databricks Certified-Data-Engineer-Professional exam prep - Certified-Data-Engineer-Professional examcollection braindumps 🐜 Easily obtain free download of [ Certified-Data-Engineer-Professional ] by searching on ⏩ www.easy4engine.com ⏪ 🕎Certified-Data-Engineer-Professional Real Question
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes