BTW, DOWNLOAD part of DumpsActual DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=1stVM-6s0OQYEoJA77jDU-ABqHNPPymi3
The Developing AI-Enabled Database Solutions (DP-800) certification exam is one of the top-rated career advancement certifications in the market. This DP-800 exam dumps have been inspiring beginners and experienced professionals since its beginning. There are several personal and professional benefits that you can gain after passing the DP-800 Exam. The validation of expertise, more career opportunities, salary enhancement, instant promotion, and membership of Microsoft certified professional community.
| Section | Weight | Objectives |
|---|---|---|
| Secure, optimize, and deploy database solutions | 35-40% | - Optimize performance and reliability
|
| Design and develop database solutions | 35-40% | - Design database solutions
|
| Implement AI capabilities in database solutions | 25-30% | - Use AI-assisted development tools
|
>> Valid Dumps DP-800 Sheet <<
DP-800 real questions in PDF format are vital in enhancing Microsoft Developing AI-Enabled Database Solutions exam preparation. With Developing AI-Enabled Database Solutions (DP-800) exam dumps PDF, you can easily study via your smartphone, laptop, and tablet. DumpsActual has designed the Developing AI-Enabled Database Solutions (DP-800) PDF format for your convenience, so you prepare for the certification exam at any time and anywhere you want. You can also print questions in the Developing AI-Enabled Database Solutions (DP-800) dumps PDF format if you want to avoid eye strain.
NEW QUESTION # 29
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an SDK-style SQL database project stored in a Git repository. The project targets an Azure SQL database.
The CI build fails with unresolved reference errors when the project references system objects.
You need to update the SQL database project to ensure that dotnet build validates successfully by including the correct system objects in the database model for Azure SQL Database.
Solution: Build the project by running dotnet build -bl -flp:v=diag.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* Add the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package to the project.
To resolve system reference errors in an SDK-style SQL project targeting Azure SQL Database, you need to add a reference to the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package.
In your .sqlproj file, include the following item group:
<ItemGroup>
<PackageReference Include="Microsoft.SqlServer.Dacpacs.Azure.Master" Version="1.60.0" />
</ItemGroup>
Why this works:
System Objects: Standard SDK-style projects don't automatically include system views (like sys.database_principals or sys.dm_db_resource_stats). This package provides the necessary metadata for the compiler.
Azure Specifics: It includes Azure-only system objects that aren't present in the standard master database dacpac used for on-premises SQL Server.
CI/CD Friendly: Since it is a NuGet package, the dotnet build command will automatically restore it during the CI process without requiring manual file paths or local installations of Visual Studio.
Incorrect:
* Add an artifact reference to the Azure SQL Database master.dacpac file.
* Add the Microsoft.SqlServer.Dacpacs.Master NuGet package to the project.
* Build the project by running dotnet build -bl -flp:v=diag.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/system-objects
NEW QUESTION # 30
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.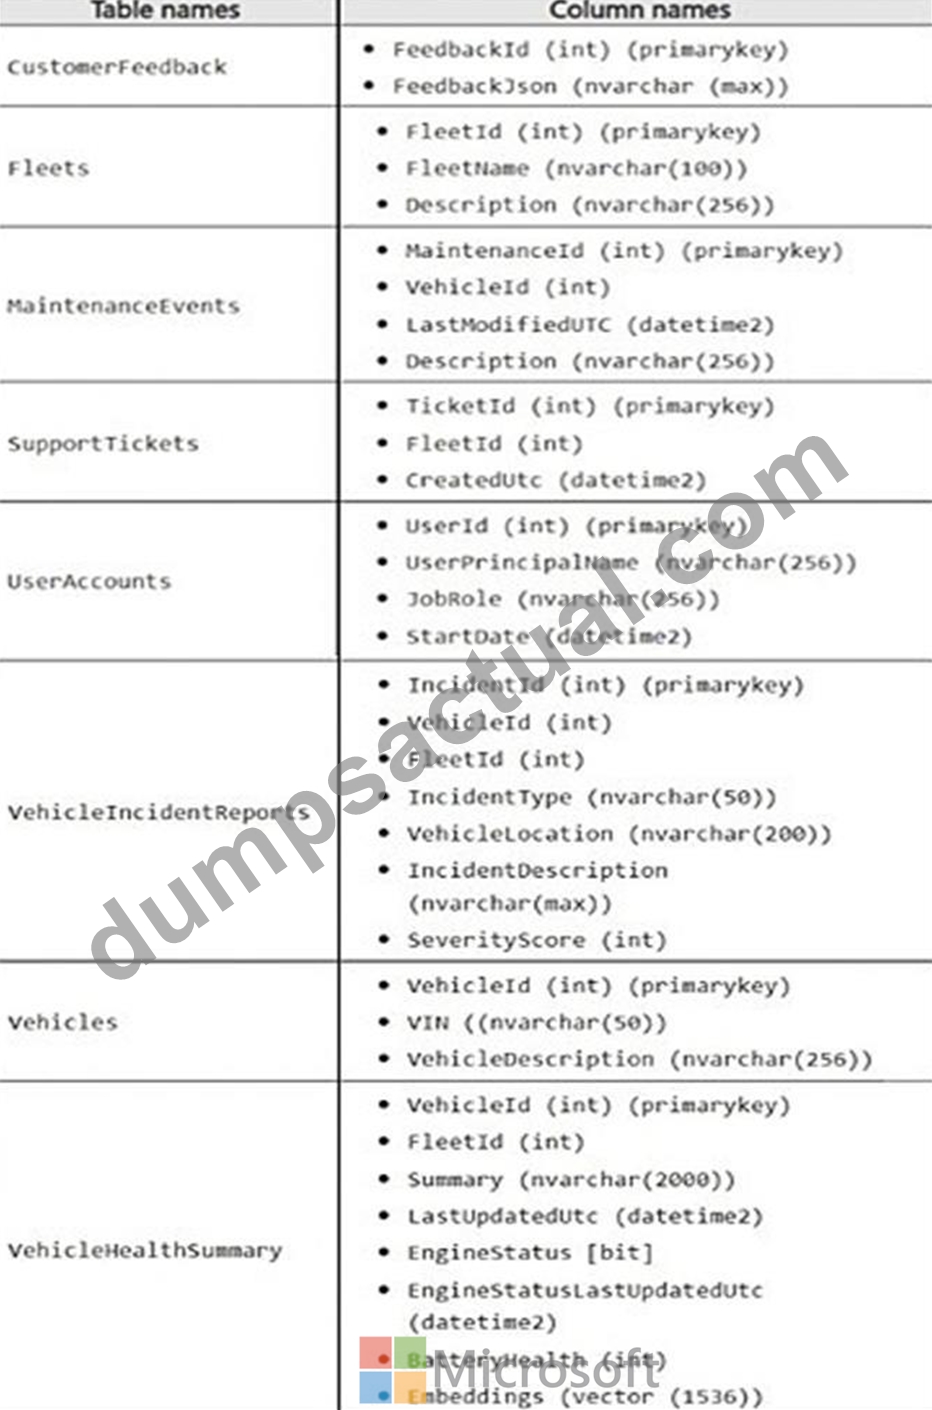
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.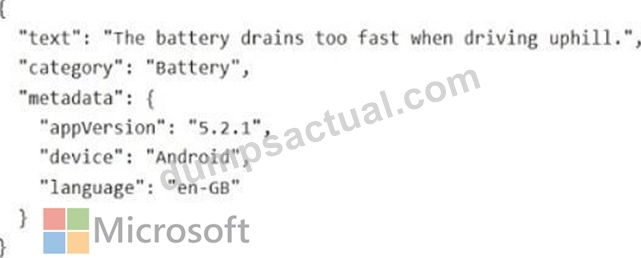
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.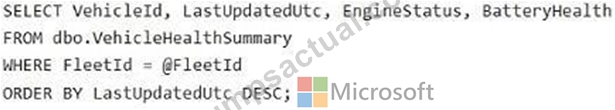
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You are creating a table that will store customer profiles.
You have the following Transact-SQL code.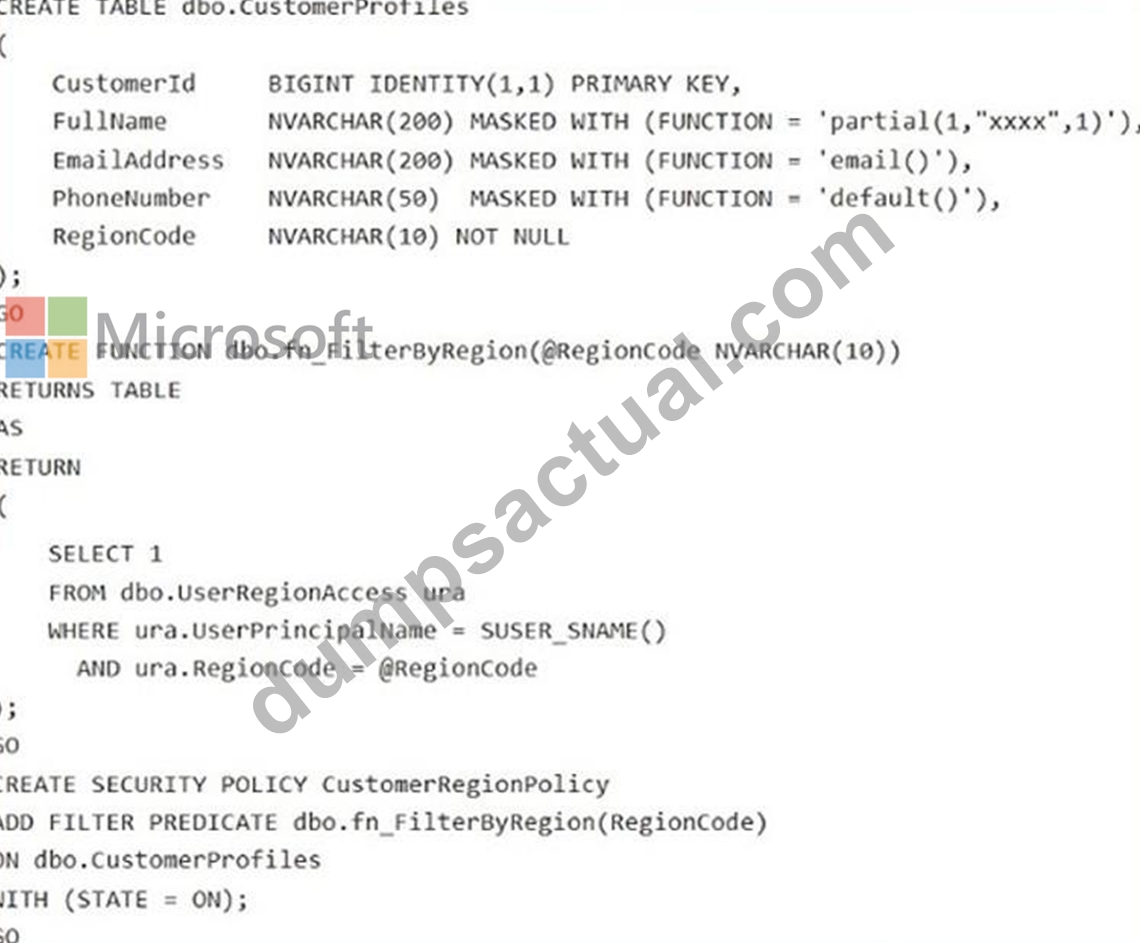
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.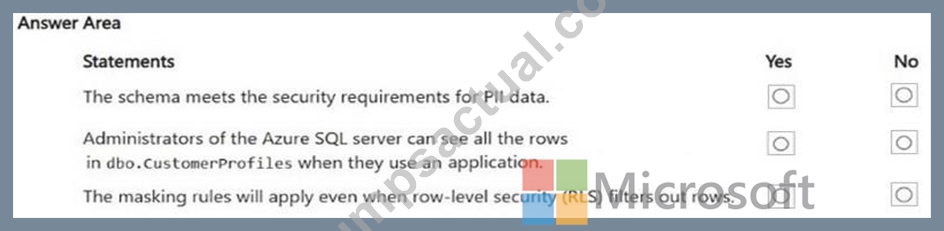
Answer:
Explanation: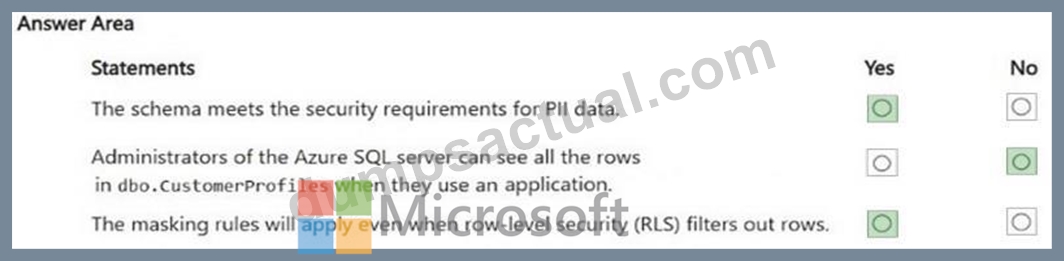
NEW QUESTION # 31
Your development team uses GitHub Copilot Chat in Microsoft SQL Server Management Studio (SSMS) to generate and run Transact-SQL queries against an Azure SQL database named DB1.
DB1 contains tables that store sensitive customer data.
You need to ensure that any Transact-SQL queries that run from GitHub Copilot Chat in SSMS are restricted by the same permissions as the developer's database login.
What prevents the GitHub Copilot Chat-run queries from accessing data beyond the developer's access?
Answer: D
Explanation:
GitHub Copilot Chat in SSMS acts as an extension of the user, meaning it does not have its own separate service account or elevated privileges.
It operates within the security context of your active connection. If your database login is restricted by Role-Based Access Control (RBAC), Row-Level Security (RLS), or specific DENY permissions on sensitive tables, Copilot cannot bypass those hurdles to fetch or manipulate data you couldn't otherwise access manually.
Reference:
https://learn.microsoft.com/en-us/ssms/github-copilot/chat
NEW QUESTION # 32
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
Answer: D
Explanation:
Scenario: VehicleIncidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
The column you should use to generate embeddings is IncidentDescription.
Why this is the correct choice:
Semantic Meaning: Embeddings are designed to capture the semantic meaning of rich, unstructured text. The IncidentDescription column likely contains the detailed natural language notes about weather, traffic, and location that the analysts are struggling to search effectively using standard methods.
Vector Search: By converting the text in IncidentDescription into mathematical vectors (embeddings), you can perform a semantic vector search. This allows the database to find
"similar" incidents based on the context of the description rather than just matching exact keywords or categories.
Incorrect:
[Not A]
VehicleLocation: Typically contains specific coordinates or addresses which are better handled by spatial data types or exact matching.
[Not C]
IncidentType: Is likely a categorical label (e.g., "Fender Bender", "Multi-car pileup") and too simple for meaningful embedding generation.
[Not D]
SeverityScore: Is a numeric value that represents a magnitude, not a semantic concept.
Reference:
https://learn.microsoft.com/en-us/sql/t-sql/spatial-geography/spatial-types-geography
NEW QUESTION # 33
You have an Azure SQL table that contains the following data.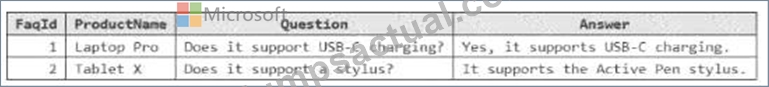
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
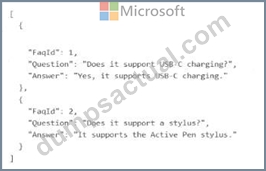
Answer: C
Explanation:
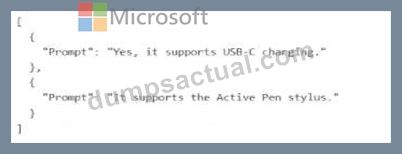
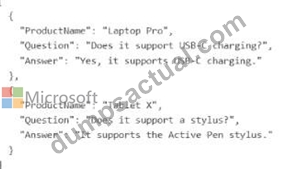
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
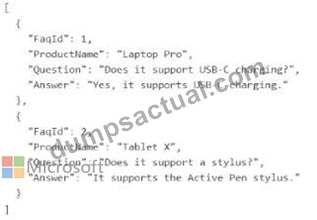
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
NEW QUESTION # 34
......
The modern Microsoft world is changing its dynamics at a fast pace. To stay and compete in this challenging market, you have to learn and enhance your in-demand skills. Fortunately, with the Developing AI-Enabled Database Solutions (DP-800) certification exam you can do this job nicely and quickly. To do this you just need to enroll in the DP-800 certification exam and put all your efforts to pass the Developing AI-Enabled Database Solutions (DP-800) certification exam. After successful competition of the Microsoft DP-800 certification, the certified candidates can put their career on the right track and achieve their professional career objectives in a short time period.
Real DP-800 Questions: https://www.dumpsactual.com/DP-800-actualtests-dumps.html
DOWNLOAD the newest DumpsActual DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1stVM-6s0OQYEoJA77jDU-ABqHNPPymi3