Our company is a multinational company which is famous for the Databricks-Certified-Professional-Data-Engineer training materials in the international market. After nearly ten years' efforts, now our company have become the topnotch one in the field, therefore, if you want to pass the Databricks-Certified-Professional-Data-Engineer Exam as well as getting the related certification at a great ease, I strongly believe that the Databricks-Certified-Professional-Data-Engineer study materials compiled by our company is your solid choice.
| Section | Weight | Objectives |
|---|---|---|
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic - Data transformation and aggregation - Integration with Databricks APIs and tools |
| Monitoring and Alerting | 10% | - Performance and health monitoring - Pipeline observability and logging - Setting up alerts and notifications |
| Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Connecting to diverse data sources - Schema inference and evolution |
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Data Governance | 7% | - Policy enforcement - Unity Catalog management - Data lineage and metadata tracking |
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
| Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Data validation and quality checks - Standardization and normalization |
>> Dumps Databricks-Certified-Professional-Data-Engineer Free <<
Using a smartphone, you may go through the Databricks Databricks-Certified-Professional-Data-Engineer dumps questions whenever and wherever you desire. The Databricks-Certified-Professional-Data-Engineer PDF dumps file is also printable for making handy notes. 2Pass4sure has developed the online Databricks Databricks-Certified-Professional-Data-Engineer practice test to help the candidates get exposure to the actual exam environment. By practicing with web-based Databricks Databricks-Certified-Professional-Data-Engineer Practice Test questions you can get rid of exam nervousness. You can easily track your performance while preparing for the Databricks Certified Professional Data Engineer Exam exam with the help of a self-assessment report shown at the end of Databricks Databricks-Certified-Professional-Data-Engineer practice test.
NEW QUESTION # 69
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalidlatitudeandlongitudevalues in theactivity_detailstable have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to addCHECKconstraints to the Delta Lake table: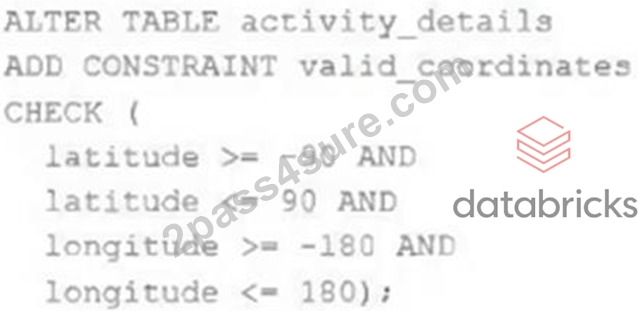
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: B
Explanation:
Explanation
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and 180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Add a CHECK constraint to an existing table" section.
https://docs.databricks.com/en/sql/language-manual/sql-ref-syntax-ddl-alter-table.html#add-constraint
NEW QUESTION # 70
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: A
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.
Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 71
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay." Exact extract: "Records older than the event-time watermark are considered late and may be dropped." Exact extract: "trigger(once) processes all available data once and then stops."
NEW QUESTION # 72
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
Answer: D
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
Reference:
Databricks documentation on using SQL views in Delta Lake: https://docs.databricks.com/delta/quick-start.html#sql-views
NEW QUESTION # 73
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control. The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity.
Which SQL query should the team run from the System catalog to achieve this?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non-existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 74
......
You don't need to wait days or weeks to get your performance report. The software displays the result of the Databricks Databricks-Certified-Professional-Data-Engineer practice test immediately, which is an excellent way to understand which area needs more attention. 2Pass4sure Databricks Databricks-Certified-Professional-Data-Engineer exam dumps save your study and preparation time. Our experts have added hundreds of Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) questions similar to the real exam. You can prepare for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam dumps during your job. You don't need to visit the market or any store because 2Pass4sure Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions are easily accessible from the website. You can try the Databricks Databricks-Certified-Professional-Data-Engineer exam dumps demo before purchasing.
Databricks-Certified-Professional-Data-Engineer Test Sample Online: https://www.2pass4sure.com/Databricks-Certification/Databricks-Certified-Professional-Data-Engineer-actual-exam-braindumps.html