Databricks-Certified-Data-Engineer-Professional日本語関連対策 & Databricks-Certified-Data-Engineer-Professional日本語版試験勉強法

2026年Xhs1991の最新Databricks-Certified-Data-Engineer-Professional PDFダンプおよびDatabricks-Certified-Data-Engineer-Professional試験エンジンの無料共有:https://drive.google.com/open?id=1wybZCf30GzsJpBpxL48mAaJcW8k1HlE4
Databricks-Certified-Data-Engineer-Professional認定は、あなたの能力の最高の証明です。ただし、このようなDatabricks-Certified-Data-Engineer-Professional試験を準備する自由時間が少ない作業担当者にとっては容易ではなく、人々は常に未知のものに対する恐怖を感じ、突然の変化に対処することはできません。ただし、Databricks-Certified-Data-Engineer-Professional試験問題はあなたのそばに立つことができます。そして、優れたDatabricks-Certified-Data-Engineer-Professional学習教材を提供することに専念する決意です。 Databricks-Certified-Data-Engineer-Professional試験問題の無料デモをお試しください。詳細を理解して選択することができます。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
- Workspace and cluster architecture
|
| Delta Lake and Data Management | - Schema evolution and enforcement
- Time travel and versioning
- Delta Lake transactions and ACID properties
|
| Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Data Modeling and Transformation | - Spark SQL transformations
- Performance optimization techniques
- Dimensional modeling concepts
|
| Data Ingestion and Processing | - ETL pipeline design patterns
- Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
|
>> Databricks-Certified-Data-Engineer-Professional日本語関連対策 <<
Databricks Databricks-Certified-Data-Engineer-Professional Exam | Databricks-Certified-Data-Engineer-Professional日本語関連対策 - あなたのDatabricks-Certified-Data-Engineer-Professional試験の合格的なプロバイダー
当社は、Databricks-Certified-Data-Engineer-Professionalトレーニング質問の研究分野で非常に専門的であると信じてください。これは、試験の合格率が高いことで説明できます。他の分野では優れているにもかかわらず、品質と効率がDatabricks-Certified-Data-Engineer-Professionalの実際の試験の最初のものであると常に信じていました。学習資料の場合、合格率は品質と効率の最良のテストです。教材を使用すると、試験に参加できるのは準備に約20〜30時間かかる場合のみです。残りの時間は、やりたいことを何でもできます。これにより、レビューのプレッシャーを完全に軽減できます。 Databricks-Certified-Data-Engineer-Professional学習教材の一貫した目的は、時間の節約と効率の向上です。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q163-Q168):
質問 # 163
A data engineering team is setting up deployment automation. To deploy workspace assets remotely using the Databricks CLI command, they must configure it with proper authentication.
Which authentication approach will provide the highest level of security?
- A. Use a service principal ID and its OAuth client secret.
- B. Use a service principal with OAuth token federation.
- C. Use a shared user account and its OAuth client secret.
- D. Use a service principal and its Personal Access Token.
正解:B
解説:
The most secure and enterprise-recommended authentication method for Databricks automation is OAuth token federation with service principals.
This configuration allows service principals (non-human identities) to authenticate using temporary OAuth access tokens from a trusted identity provider (such as Azure AD or AWS IAM federation). These tokens are short-lived and scoped, significantly reducing credential exposure risks.
By contrast, static client secrets (B) or PATs (C) are long-lived and require periodic manual rotation, increasing security vulnerability. Shared user accounts (D) violate least-privilege and auditability principles. Therefore, A provides the strongest, most compliant authentication model for automated CLI and CI/CD workflows.
質問 # 164
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
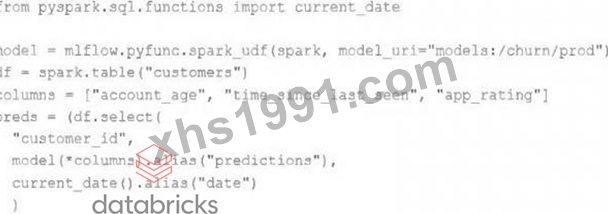
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A. preds.write.mode("append").saveAsTable("churn_preds")
- B.
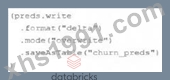
- C.
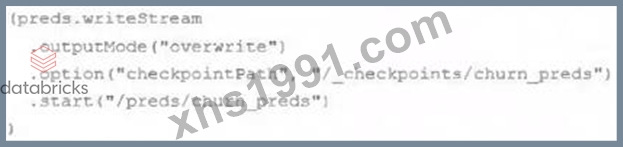
- D.
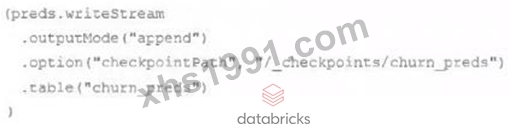
- E. preds.write.format("delta").save("/preds/churn_preds")
正解:A
質問 # 165
When a new Databricks project starts, the central IP team provisions the required infrastructure using Terraform and a Service Principal. This includes creating a Databricks workspace, a Unity Catalog linked to an External Location, and a Databricks group containing all project team members. Project teams must store all assets - e.g., tables and volumes, as Managed assets in Unity Catalog. This model hides infrastructure complexity while giving teams autonomy within their catalog. They can create and manage schemas, tables, volumes, and related objects but cannot rename, delete, or change catalog permissions, those remain under IT's control. Which rights should the project group be granted to enable this model?
- A. The group needs to have ALL PRIVILEGES and the MANAGE on the catalog.
- B. The group needs to have ALL PRIVILEGES on the catalog.
- C. The group needs to have USE CATALOG and USE SCHEMA on the catalog.
- D. The group should be made OWNER of the catalog.
正解:C
解説:
Granting the project group USE CATALOG (and USE SCHEMA on existing schemas) allows team members to work within the catalog without giving them ownership or administrative control.
This enables teams to create and manage schemas, tables, and volumes inside the catalog while preventing them from renaming, deleting, or modifying catalog-level permissions, which remain under central IT governance.
質問 # 166
A data engineer manages a Unity Catalog table customer_data in schema finance that includes sensitive fields like ssn and credit_score. Intern Group should only see masked values, while Analyst Group should only access rows for their assigned region. The data engineer needs to restrict access based on user role and region without duplicating data. How should the data engineer enforce this security policy?
- A. Use Unity Catalog's row filters based on the region and column masks based on user roles.
- B. Create views using current_user() and is_account_group_member() functions, and apply masking logic inside the SQL SELECT clause for each sensitive column.
- C. Create dynamic views for each user role and manage access with ACLs.
- D. Use Unity Catalog's row filters based on the user roles and column masks based on the region.
正解:A
解説:
Unity Catalog row filters can restrict which rows are visible based on attributes such as the user's assigned region, while column masks can dynamically obfuscate sensitive fields like ssn and credit_score based on user roles. This enforces fine-grained, role-and region-based access control directly at the table level without duplicating data or relying on custom views.
質問 # 167
Which statement regarding spark configuration on the Databricks platform is true?
- A. When the same spar configuration property is set for an interactive to the same interactive cluster.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - B. The Databricks REST API can be used to modify the Spark configuration properties for an interactive cluster without interrupting jobs.
- C. Spark configuration properties can only be set for an interactive cluster by creating a global init script.
- D. Spark configuration properties set for an interactive cluster with the Clusters UI will impact all notebooks attached to that cluster.
- E. Spark configuration set within an notebook will affect all SparkSession attached to the same interactive cluster
正解:D
解説:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
質問 # 168
......
Databricks知ってほしいのは、人々が私たちの製造哲学の中心にいるということです。そのため、Databricks-Certified-Data-Engineer-Professional試験問題をより高度なものにする直感的な機能に重点を置いています。 したがって、Databricks-Certified-Data-Engineer-Professionalガイドトレントを使用すると、Databricks-Certified-Data-Engineer-Professional試験に最も効率的かつ生産的な方法で簡単に合格し、献身と熱意を持って勉強する方法を学ぶことができます。 Databricks Certified Data Engineer Professional Exam試験に合格して目標を達成するためのXhs1991最良のツールでなければなりません。
Databricks-Certified-Data-Engineer-Professional日本語版試験勉強法: https://www.xhs1991.com/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional試験感想 👡 Databricks-Certified-Data-Engineer-Professional問題トレーリング 🕥 Databricks-Certified-Data-Engineer-Professional試験勉強攻略 🤸 ⏩ www.goshiken.com ⏪に移動し、▛ Databricks-Certified-Data-Engineer-Professional ▟を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Data-Engineer-Professional基礎訓練
- Databricks-Certified-Data-Engineer-Professional試験解説 🤳 Databricks-Certified-Data-Engineer-Professional試験参考書 🧗 Databricks-Certified-Data-Engineer-Professional基礎訓練 ✴ { Databricks-Certified-Data-Engineer-Professional }を無料でダウンロード▛ www.goshiken.com ▟で検索するだけDatabricks-Certified-Data-Engineer-Professional出題内容
- Databricks-Certified-Data-Engineer-Professional試験の準備方法|100%合格率のDatabricks-Certified-Data-Engineer-Professional日本語関連対策試験|ユニークなDatabricks Certified Data Engineer Professional Exam日本語版試験勉強法 🌟 ▶ www.jpexam.com ◀から➥ Databricks-Certified-Data-Engineer-Professional 🡄を検索して、試験資料を無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional復習テキスト
- 一番優秀なDatabricks-Certified-Data-Engineer-Professional日本語関連対策試験-試験の準備方法-最高のDatabricks-Certified-Data-Engineer-Professional日本語版試験勉強法 🈵 今すぐ「 www.goshiken.com 」を開き、✔ Databricks-Certified-Data-Engineer-Professional ️✔️を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional試験解説
- Databricks-Certified-Data-Engineer-Professional学習範囲 🆚 Databricks-Certified-Data-Engineer-Professional試験参考書 📉 Databricks-Certified-Data-Engineer-Professional試験参考書 🙍 ウェブサイト⮆ www.japancert.com ⮄を開き、▛ Databricks-Certified-Data-Engineer-Professional ▟を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional復習テキスト
- 信頼的なDatabricks-Certified-Data-Engineer-Professional日本語関連対策試験-試験の準備方法-効率的なDatabricks-Certified-Data-Engineer-Professional日本語版試験勉強法 😷 ▷ www.goshiken.com ◁を開き、《 Databricks-Certified-Data-Engineer-Professional 》を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional独学書籍
- Databricks-Certified-Data-Engineer-Professional試験の準備方法|100%合格率のDatabricks-Certified-Data-Engineer-Professional日本語関連対策試験|ユニークなDatabricks Certified Data Engineer Professional Exam日本語版試験勉強法 🌳 { Databricks-Certified-Data-Engineer-Professional }を無料でダウンロード《 www.xhs1991.com 》ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional資格準備
- ハイパスレートのDatabricks-Certified-Data-Engineer-Professional日本語関連対策 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional日本語版試験勉強法 | 権威のあるDatabricks-Certified-Data-Engineer-Professional合格受験記 🥖 ウェブサイト{ www.goshiken.com }から▛ Databricks-Certified-Data-Engineer-Professional ▟を開いて検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional試験感想
- Databricks-Certified-Data-Engineer-Professional試験解説 🎂 Databricks-Certified-Data-Engineer-Professional試験問題 🦦 Databricks-Certified-Data-Engineer-Professional復習テキスト 📭 時間限定無料で使える【 Databricks-Certified-Data-Engineer-Professional 】の試験問題は「 www.japancert.com 」サイトで検索Databricks-Certified-Data-Engineer-Professional勉強資料
- 権威のあるDatabricks-Certified-Data-Engineer-Professional日本語関連対策試験-試験の準備方法-有効的なDatabricks-Certified-Data-Engineer-Professional日本語版試験勉強法 🧙 ➤ www.goshiken.com ⮘は、「 Databricks-Certified-Data-Engineer-Professional 」を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional試験解答
- Databricks-Certified-Data-Engineer-Professional試験の準備方法|有効的なDatabricks-Certified-Data-Engineer-Professional日本語関連対策試験|高品質なDatabricks Certified Data Engineer Professional Exam日本語版試験勉強法 ❗ ウェブサイト▛ www.passtest.jp ▟を開き、➤ Databricks-Certified-Data-Engineer-Professional ⮘を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional出題内容
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S.Xhs1991がGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=1wybZCf30GzsJpBpxL48mAaJcW8k1HlE4