In order to serve you better, we have a complete system if you buying Databricks-Certified-Professional-Data-Engineer exam bootcamp from us. You can try the free demo before buying Databricks-Certified-Professional-Data-Engineer exam materials, so that you can know what the complete version is like. If you are quite satisfied with the free demo and want the complete version, you just need to add them to card, and pay for them. You will receive your download link and password for Databricks-Certified-Professional-Data-Engineer Exam Dumps within ten minutes after payment. We have after-service for you after buying Databricks-Certified-Professional-Data-Engineer exam dumps, if you have any question, you can contact us by email, and we will give you reply as soon as possible.
Databricks Certified Professional Data Engineer certification exam covers a wide range of topics, including data ingestion, data processing, data storage, and data analysis. Candidates are required to demonstrate their ability to design and implement data solutions using Databricks, as well as their understanding of best practices for data engineering. Databricks-Certified-Professional-Data-Engineer exam consists of multiple-choice questions and takes approximately two hours to complete.
Databricks Certified Professional Data Engineer exam is a comprehensive assessment of a candidate's ability to design, implement, and manage data pipelines on the Databricks platform. Databricks Certified Professional Data Engineer Exam certification exam covers a wide range of topics, including data ingestion, data processing, data transformation, and data storage. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the candidate's knowledge of best practices for building efficient and scalable data pipelines that can handle large volumes of data.
>> Training Databricks-Certified-Professional-Data-Engineer Pdf <<
We have authoritative production team made up by thousands of experts helping you get hang of our Databricks-Certified-Professional-Data-Engineer study question and enjoy the high quality study experience. We will update the content of Databricks-Certified-Professional-Data-Engineer test guide from time to time according to recent changes of examination outline and current policies. Besides, our Databricks-Certified-Professional-Data-Engineer Exam Questions can help you optimize your learning method by simplifying obscure concepts so that you can master better. One more to mention, with our Databricks-Certified-Professional-Data-Engineer test guide, there is no doubt that you can cut down your preparing time in 20-30 hours of practice before you take the exam.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to demonstrate their skills and proficiency in using Databricks for data engineering tasks. Databricks Certified Professional Data Engineer Exam certification can help data engineers to advance their careers and increase their earning potential. It can also help organizations to identify and hire skilled data engineers who can design and implement data solutions using Databricks.
NEW QUESTION # 192
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by thedatevariable: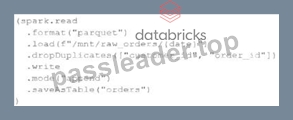
Assume that the fieldscustomer_idandorder_idserve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
Answer: E
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "DROP DUPLICATES" section.
NEW QUESTION # 193
Which of the statements are incorrect when choosing between lakehouse and Datawarehouse?
Answer: A
Explanation:
Explanation
The answer is Lakehouse cannot serve low query latency with high reliability for BI workloads, only suitable for batch workloads.
Lakehouse can replace traditional warehouses by leveraging storage and compute optimizations like caching to serve them with low query latency with high reliability.
Focus on comparisons between Spark Cache vs Delta Cache.
https://docs.databricks.com/delta/optimizations/delta-cache.html
What Is a Lakehouse? - The Databricks Blog
Graphical user interface, text, application Description automatically generated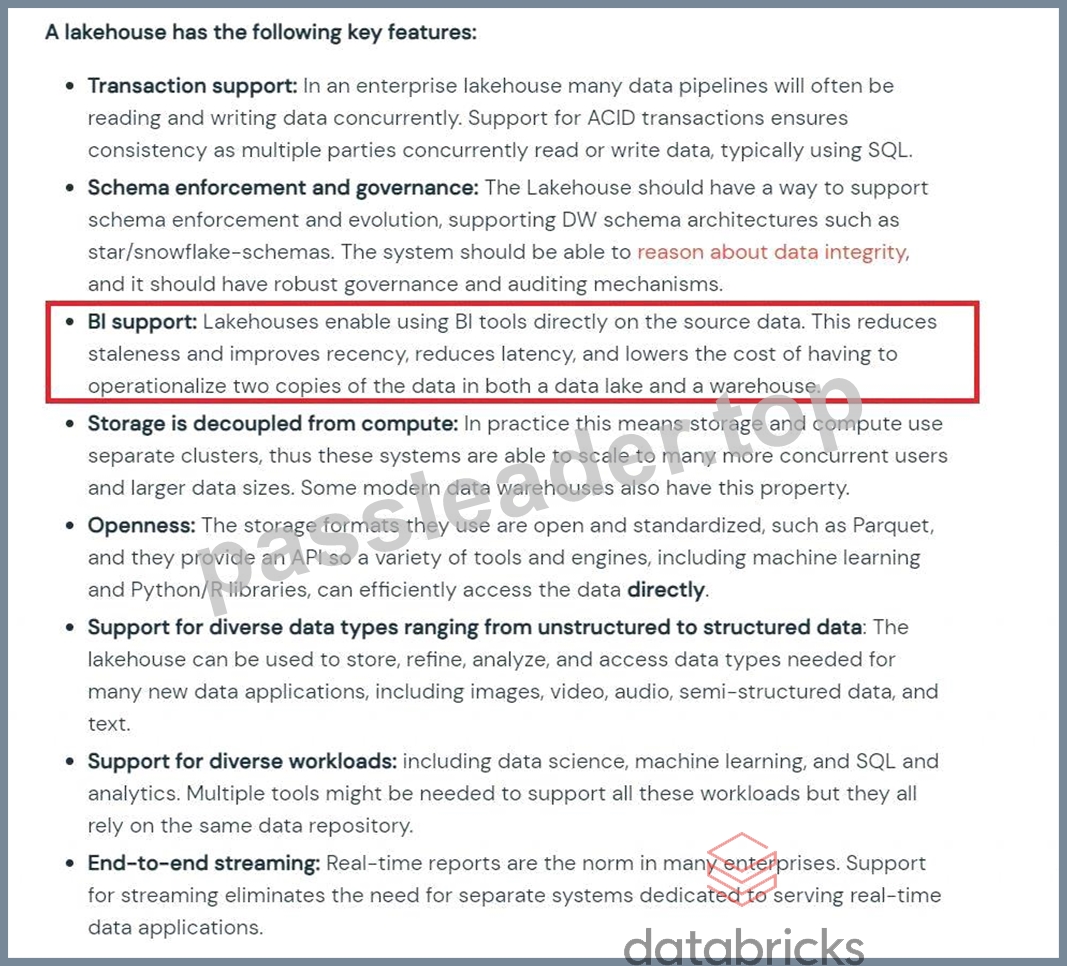
Bottom of Form
Top of Form
NEW QUESTION # 194
Which of the following SQL command can be used to insert or update or delete rows based on a condition to check if a row(s) exists?
Answer: D
Explanation:
Explanation
here is the additional documentation for your review.
https://docs.databricks.com/spark/latest/spark-sql/language-manual/delta-merge-into.html
1.MERGE INTO target_table_name [target_alias]
2. USING source_table_reference [source_alias]
3. ON merge_condition
4. [ WHEN MATCHED [ AND condition ] THEN matched_action ] [...]
5. [ WHEN NOT MATCHED [ AND condition ] THEN not_matched_action ] [...]
6.
7.matched_action
8. { DELETE |
9. UPDATE SET * |
10. UPDATE SET { column1 = value1 } [, ...] }
11.
12.not_matched_action
13. { INSERT * |
14. INSERT (column1 [, ...] ) VALUES (value1 [, ...])
NEW QUESTION # 195
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
MERGE INTO customers
USING (
SELECT updates.customer_id as merge_ey, updates .*
FROM updates
UNION ALL
SELECT NULL as merge_key, updates .*
FROM updates JOIN customers
ON updates.customer_id = customers.customer_id
WHERE customers.current = true AND updates.address <> customers.address ) staged_updates ON customers.customer_id = mergekey WHEN MATCHED AND customers. current = true AND customers.address <> staged_updates.address THEN UPDATE SET current = false, end_date = staged_updates.effective_date WHEN NOT MATCHED THEN INSERT (customer_id, address, current, effective_date, end_date) VALUES (staged_updates.customer_id, staged_updates.address, true, staged_updates.effective_date, null) Which statement describes this implementation?
Answer: C
Explanation:
The provided MERGE statement is a classic implementation of a Type 2 SCD in a data warehousing context.
In this approach, historical data is preserved by keeping old records (marking them as not current) and adding new records for changes. Specifically, when a match is found and there's a change in the address, the existing record in the customers table is updated to mark it as no longer current (current = false), and an end date is assigned (end_date = staged_updates.effective_date). A new record for the customer is then inserted with the updated information, marked as current. This method ensures that the full history of changes to customer information is maintained in the table, allowing for time-based analysis of customer data.References:
Databricks documentation on implementing SCDs using Delta Lake and the MERGE statement (https://docs.databricks.com/delta/delta-update.html#upsert-into-a-table-using-merge).
NEW QUESTION # 196
Unity catalog helps you manage the below resources in Databricks at account level
Answer: C
Explanation:
Explanation
The answer is all of the above.
Unity Catalog is a unified governance solution for all data and AI assets including files, tables, machine learning models, and dashboards in your lakehouse on any cloud.
NEW QUESTION # 197
......
Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Sheet: https://www.passleader.top/Databricks/Databricks-Certified-Professional-Data-Engineer-exam-braindumps.html