Certified-Data-Engineer-Professional Practice Engine | Certified-Data-Engineer-Professional Valid Test Format

The immediate downloading feature of our Certified-Data-Engineer-Professional certification guide is an eminent advantage of our products. Once the pay is done, our customers will receive an e-mail from our company. Our Certified-Data-Engineer-Professional exam study materials are available for downloading without any other disturbing requirements as long as you have paid successfully, which is increasingly important to an examinee as he or she has limited time for personal study for the Certified-Data-Engineer-Professional Exam. Therefore, our Databricks Certified Data Engineer Professional guide torrent is attributive to high-efficient learning as you will pass the Certified-Data-Engineer-Professional exam only after study for 20 to 30 hours.
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 5. Create pipeline components using control flow operators such as if/else and foreach
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
>> Certified-Data-Engineer-Professional Practice Engine <<
Certified-Data-Engineer-Professional Valid Test Format - Reliable Certified-Data-Engineer-Professional Exam Syllabus
Free update for 365 days is available for Certified-Data-Engineer-Professional study guide, so that you can have a better understanding of what you are going to buy. Through free demo, you can also know what the complete version is like. In addition, with experienced experts to compile the Certified-Data-Engineer-Professional Exam Dumps, quality can be guaranteed. Therefore, if you choose us, you can use them at ease. We have online and offline chat service stuff, who are quite familiar with Certified-Data-Engineer-Professional study guide, if you have any questions, you can consult us.
Databricks Certified Data Engineer Professional Sample Questions (Q124-Q129):
NEW QUESTION # 124
A data company uses Databricks Unity Catalog and has multiple enterprise data sources, including PostgreSQL, Snowflake, and SQL Server. The central data platform team wants to configure Lakehouse Federation so analysts can query external tables directly in Databricks using Databricks SQL, without duplicating data. Which steps are necessary to configure Lakehouse Federation in a secure and governed manner?
- A. Create external locations and storage credentials to connect to each database, then register foreign tables in Unity Catalog.
- B. Mirror the external datasets into Delta Lake using Auto Loader, and govern them using Data Lineage and System Tables.
- C. Use Partner Connect to create linked datasets, and apply table ACLs at the source system to govern access through Databricks.
- D. Configure connections and foreign catalog in Unity Catalog, then grant access to foreign catalogs, schemas, and tables using Unity Catalog permissions.
Answer: D
Explanation:
Lakehouse Federation is configured by defining secure connections to external data sources and registering them as foreign catalogs in Unity Catalog. Access is then governed using Unity Catalog permissions at the catalog, schema, and table levels, enabling analysts to query external tables securely without data duplication.
NEW QUESTION # 125
A data engineer needs to install the PyYAML Python package within an air-gapped Databricks environment. The workspace has no direct internet access to PyPI. The engineer has downloaded the .whl file locally and wants it available automatically on all new clusters. Which approach should the data engineer use?
- A. Upload the PyYAML .whl file to the user home directory and create a cluster-scoped init script to install it.
- B. Upload the PyYAML .whl file to a Unity Catalog Volume, ensure it's allow-listed, and create a cluster-scoped init script that installs it from that path.
- C. Add the .whl file to Databricks Git Repos and assume automatic installation.
- D. Set up a private PyPI repository and install via pip index URL.
Answer: B
Explanation:
For secure, air-gapped Databricks deployments, the recommended practice is to host dependency files such as .whl packages in Unity Catalog Volumes -- a managed storage layer governed by Unity Catalog.
Once stored in a volume, these files can be safely referenced from cluster-scoped init scripts, which automatically execute installation commands (e.g., pip install
/Volumes/catalog/schema/path/PyYAML.whl) during cluster startup.
This ensures consistent environment setup across clusters and compliance with data governance rules.
User directories (A) lack enterprise security controls; private repositories (C) are not viable in air- gapped setups; and Git repos (D) do not trigger package installation. Therefore, B is the correct and officially approved method.
NEW QUESTION # 126
What is a method of installing a Python package scoped at the notebook level to all nodes in the currently active cluster?
- A. Use &Pip install in a notebook cell
- B. Install libraries from PyPi using the cluster UI
- C. Run source env/bin/activate in a notebook setup script
- D. Use &sh install in a notebook cell
Answer: B
Explanation:
Installing a Python package scoped at the notebook level to all nodes in the currently active cluster in Databricks can be achieved by using the Libraries tab in the cluster UI. This interface allows you to install libraries across all nodes in the cluster. While the %pip command in a notebook cell would only affect the driver node, using the cluster UI ensures that the package is installed on all nodes.
NEW QUESTION # 127
A data engineer is building a customer data pipeline in Lakeflow Spark Declarative Pipelines. The source is a cloud-based event stream with limited retention containing inserts, updates, and deletes for customer records. These changes are being applied using the AUTO CDC INTO syntax to maintain an SCD Type 1 table as the target table, customer_dim. How should the data engineer build a downstream job that streams from the customer_dim table to only act on updates and delete events, processing data incrementally?
- A. Streaming from customer_dim table would only be possible in the case of SCD 2 retention.
- B. Use ignoreChanges flag while streaming from customer_dim to avoid breaking the pipeline during updates and deletes.
- C. When stored as SCD 1, the target of AUTO CDC INTO includes updates and deletes. Streaming from customer_dim can fail due to these operations. Instead, build another stream from the original source.
- D. Read change data feed from customer_dim table and apply filters to incrementally act on the change events.
Answer: D
Explanation:
Reading the change data feed from the customer_dim table enables downstream processing to react specifically to update and delete events while operating incrementally. Change data feed exposes row-level change types and versions, making it the correct mechanism for streaming only the relevant changes from an SCD Type 1 table maintained with AUTO CDC INTO.
NEW QUESTION # 128
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
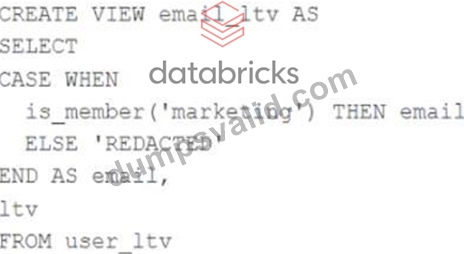
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
- A. The email, age. and ltv columns will be returned with the values in user ltv.
- B. Only the email and ltv columns will be returned; the email column will contain the string
"REDACTED" in each row. - C. The email and ltv columns will be returned with the values in user itv.
- D. Three columns will be returned, but one column will be named "redacted" and contain only null values.
- E. Only the email and itv columns will be returned; the email column will contain all null values.
Answer: B
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
NEW QUESTION # 129
......
DumpsValid also offer a free demo before the purchase of the Databricks Certified-Data-Engineer-Professional exam prep material. You can try a free demo to examine the Databricks Certified-Data-Engineer-Professional practice exam material of DumpsValid. Similarly, we also provide up to 365 days of free updates of Selling Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam product if the content of the real Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions changes after your shopping.
Certified-Data-Engineer-Professional Valid Test Format: https://www.dumpsvalid.com/Certified-Data-Engineer-Professional-still-valid-exam.html
- Efficient Certified-Data-Engineer-Professional Practice Engine Covers the Entire Syllabus of Certified-Data-Engineer-Professional 😪 Enter ☀ www.examcollectionpass.com ️☀️ and search for 【 Certified-Data-Engineer-Professional 】 to download for free 🌻Latest Test Certified-Data-Engineer-Professional Experience
- Reliable Certified-Data-Engineer-Professional Test Tips 🐆 Practice Test Certified-Data-Engineer-Professional Fee 🤍 Latest Certified-Data-Engineer-Professional Test Guide 🦡 Search for 《 Certified-Data-Engineer-Professional 》 on ➽ www.pdfvce.com 🢪 immediately to obtain a free download ☂Valid Certified-Data-Engineer-Professional Learning Materials
- Test Certified-Data-Engineer-Professional Prep 🏹 Examcollection Certified-Data-Engineer-Professional Questions Answers 🍖 Best Certified-Data-Engineer-Professional Study Material ⛴ Download ➥ Certified-Data-Engineer-Professional 🡄 for free by simply searching on ➡ www.examcollectionpass.com ️⬅️ ▛Dumps Certified-Data-Engineer-Professional Download
- Latest Certified-Data-Engineer-Professional Test Voucher 💭 Dumps Certified-Data-Engineer-Professional Download 🧫 Certified-Data-Engineer-Professional Trustworthy Practice ⭐ Go to website ▛ www.pdfvce.com ▟ open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🎥Test Certified-Data-Engineer-Professional Prep
- Best Certified-Data-Engineer-Professional Study Material 🧥 Latest Certified-Data-Engineer-Professional Test Voucher 😿 Certified-Data-Engineer-Professional Latest Dumps Free 🦼 Easily obtain free download of ⮆ Certified-Data-Engineer-Professional ⮄ by searching on ☀ www.verifieddumps.com ️☀️ ↔Reliable Certified-Data-Engineer-Professional Test Tips
- Hot Certified-Data-Engineer-Professional Practice Engine Free PDF | Reliable Certified-Data-Engineer-Professional Valid Test Format: Databricks Certified Data Engineer Professional 🐓 Search on ▛ www.pdfvce.com ▟ for ⏩ Certified-Data-Engineer-Professional ⏪ to obtain exam materials for free download 🧘Certified-Data-Engineer-Professional Actual Test Pdf
- Certified-Data-Engineer-Professional Practice Engine - Realistic Quiz Databricks Databricks Certified Data Engineer Professional Valid Test Format 🧳 Download { Certified-Data-Engineer-Professional } for free by simply entering ➥ www.prep4sures.top 🡄 website 🌄Latest Certified-Data-Engineer-Professional Test Voucher
- 100% Pass Certified-Data-Engineer-Professional Practice Engine - Realistic Databricks Certified Data Engineer Professional Valid Test Format 🎀 Download ➥ Certified-Data-Engineer-Professional 🡄 for free by simply entering ⇛ www.pdfvce.com ⇚ website ◀Certified-Data-Engineer-Professional Trustworthy Practice
- Certified-Data-Engineer-Professional Exam Labs 👤 Certified-Data-Engineer-Professional Latest Dumps Free 🙁 Certified-Data-Engineer-Professional Exam Labs 🏔 Immediately open ▶ www.examcollectionpass.com ◀ and search for 【 Certified-Data-Engineer-Professional 】 to obtain a free download 🍺Certified-Data-Engineer-Professional Trustworthy Practice
- Certified-Data-Engineer-Professional Practice Engine - Realistic Quiz Databricks Databricks Certified Data Engineer Professional Valid Test Format ⌚ ( www.pdfvce.com ) is best website to obtain ▛ Certified-Data-Engineer-Professional ▟ for free download 🏰Latest Certified-Data-Engineer-Professional Test Guide
- Databricks Certified-Data-Engineer-Professional VCE dumps - Testking Certified-Data-Engineer-Professional test 🍄 The page for free download of [ Certified-Data-Engineer-Professional ] on ▷ www.examcollectionpass.com ◁ will open immediately 🙇Certified-Data-Engineer-Professional Actual Test Pdf
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes