さらに、JPTestKing SPS-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1Lb-wSiJhA8rlS3tU1Wca7xM_d2sq8X6r
なぜ我々社は試験に合格しないなら、全額での返金を承諾するのは大勢の客様が弊社のSnowflake SPS-C01問題集を使用して試験に合格するのは我々に自信を与えるからです。Snowflake SPS-C01試験はIT業界での人にとって、とても重要な能力証明である一方で、大変難しいことです。それで、弊社の専門家たちは多くの時間と精力を尽くし、Snowflake SPS-C01試験資料を研究開発されます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Performance Optimization and Best Practices | 20% | - Debugging and explain plans - Warehouse sizing for Snowpark - Caching strategies - Vectorized UDFs - Minimizing data transfer - Query pushdown and optimization |
| Topic 2: Snowpark API for Python | 30% | - Working with Semi-structured data - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management - DataFrame creation and manipulation |
| Topic 3: Snowpark Concepts | 15% | - Snowpark Sessions and connection management - Client-side vs. Server-side execution - Transformations vs. Actions - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Stored procedures and conditional logic |
| Topic 4: Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Filtering, Aggregating, and Joining DataFrames - Persisting transformed data - Using built-in functions - Window functions |
多くのIT業界の友達によるとSnowflake認証試験を準備することが多くの時間とエネルギーをかからなければなりません。もし訓練班とオンライン研修などのルートを通じないと試験に合格するのが比較的に難しい、一回に合格率非常に低いです。JPTestKingはもっとも頼られるトレーニングツールで、SnowflakeのSPS-C01認定試験の実践テストソフトウェアを提供したり、SnowflakeのSPS-C01認定試験の練習問題と解答もあって、最高で最新なSnowflakeのSPS-C01認定試験「Snowflake Certified SnowPro Specialty - Snowpark」問題集も一年間に更新いたします。
質問 # 33
Consider the following Snowpark Python code snippet designed to calculate a custom metric on financial data, using a vectorized UDF for performance. Identify potential performance bottlenecks and recommend optimization strategies.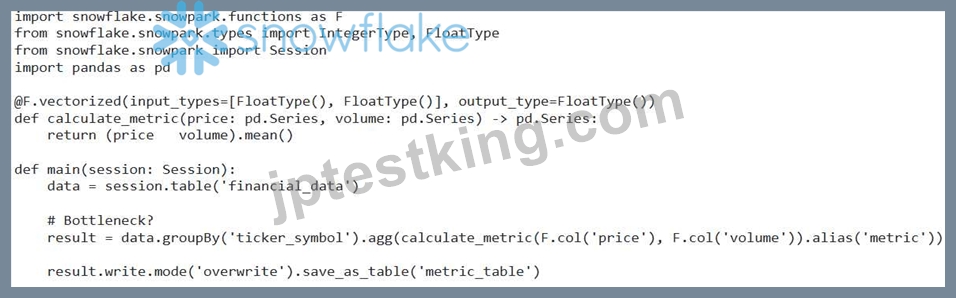
Which of the following actions (may be more than one) would MOST likely improve the performance of this Snowpark application?
正解:B、C、E
解説:
Clustering by 'ticker_symbol' significantly optimizes the 'groupBy' operation by organizing data physically for efficient retrieval. Caching the result before writing to a table is crucial if the intermediate result 'result' will be used multiple times, avoiding redundant computations. Repartitioning by 'ticker_symbol' before grouping helps distribute data evenly, improving parallelism and locality. While Pandas is generally available, explicitly declaring it might be necessary in certain isolated environments, so B can be considered a good practice, but not as impactful. Changing FloatType to DoubleType (C) will not lead to performnace improvement. It only changes precision level which is not required here.
質問 # 34
You have a Snowpark Python application that reads data from multiple Snowflake tables, performs complex transformations using UDFs, and writes the results to a new table. During peak hours, the application experiences performance bottlenecks. The Snowflake warehouse associated with the Snowpark session is already configured with the 'SNOWPARK OPTIMIZED warehouse type. Which of the following strategies, when implemented together, would BEST improve the application's performance?
正解:B、E
解説:
Increasing the warehouse size provides more compute resources. Partitioning tables improves join performance. Optimizing UDFs reduces execution time. Utilizing vectorized UDFs allows for processing batches of data at once, reducing overhead. Snowpark's optimized join operations use efficient algorithms. Options A and C, while helpful, don't address the underlying issues as directly. Caching might help repetitive tasks, rewriting UDFs in SQL isn't always feasible or optimal if specialized logic is implemented. Option E is most optimal because it also utilizes vectorized UDFs where possible.
質問 # 35
You are developing a Snowpark application to analyze customer data'. You need to create a Snowpark DataFrame from a list of dictionaries, where each dictionary represents a customer with 'id', 'name', and 'city' keys. The data should be loaded efficiently. Consider these scenarios: 1 . The input data can sometimes contain missing values (e.g., a customer might not have a city specified). 2. You want to ensure optimal performance when loading the data, as the list can be very large. 3. You need the resulting DataFrame's schema to correctly infer the datatypes based on the input dictionary's values. Which of the following methods and considerations should be used to create a Snowpark DataFrame from a list of dictionaries to meet these requirements?
正解:A、C
解説:
Options B and D are the most appropriate. Providing an explicit schema, including specifying the 'nullable' property and datatypes, offers several advantages: 1. Handles missing values: By explicitly setting 'nullable=True' in the schema for columns that might contain missing values, you ensure that Snowflake correctly handles these as 'NULC. 2. Optimizes Performance: Specifying the schema avoids Snowflake's need to infer it, which can be a performance bottleneck, especially for large datasets. Explicit datatypes also help with storage and processing efficiency. 3. Data Type Control: You can ensure the correct data types are used for each column, preventing potential issues with data type conversions later om Option A relies on automatic schema inference, which can be inefficient and may not always correctly handle missing values or data types as expected. Option C requires explicit casting after DataFrame creation which is less efficient than specifying in the schema initially. Option E can add an unneccessary overhead since converting to Pandas DataFrame and then to Snowpark DataFrame may not be optimized.
質問 # 36
A data engineer is tasked with transforming a large dataset of customer transactions using Snowpark Python. The dataset contains personally identifiable information (PII) that needs to be masked before further analysis. They decide to use a UDF to perform the masking. Consider the following Python UDF:
The engineer registers this UDF and attempts to apply it to a column named 'customer email' in a Snowpark DataFrame named 'customer data'. Which of the following code snippets is the MOST efficient and secure way to apply this UDF and replace the 'customer email' column with the masked values?





正解:E
解説:
The most efficient and secure way is to directly call the UDF on the DataFrame column using 'with_column'. This leverages Snowpark's lazy evaluation and avoids unnecessary data movement. It also modifies the original 'customer_email' column as requested. Option A requires the string name of the UDF instead of the function and option D adds a new column named 'masked_email' instead of replacing customer_email. Option B and E do not replace the current 'customer_email' column.
質問 # 37
You've transformed a large Snowpark DataFrame and want to persist it to a Snowflake stage for downstream applications. Your requirements are: 1. The data must be written in CSV format. 2. The files must be GZIP compressed. 3. A header row should be included in each file. 4. The files should be stored in a stage named 'customer_stage' in your Snowflake database. Which of the following code snippets correctly implements this, ensuring optimal performance and resource utilization?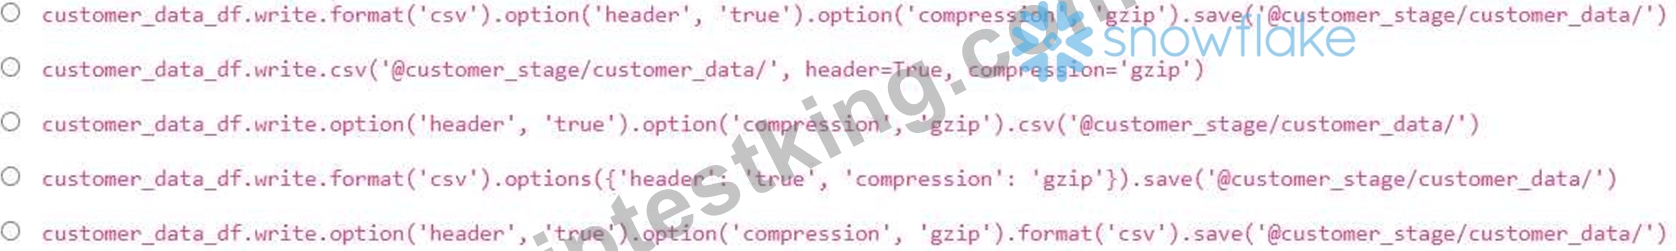
正解:C
解説:
Option B provides the most concise and readable way to achieve the desired outcome using the dedicated writer method. It directly specifies the header and compression options as parameters. Options A, D, and E require specifying the file format separately using 'format('csv')' and configuring header and compression through options, which is less direct. Option C has incorrect order - it need to set format first before setting options, so its less readable.
質問 # 38
......
現在の社会の中で優秀なIT人材が揃て、競争も自ずからとても大きくなって、だから多くの方はITに関する試験に参加してIT業界での地位のために奮闘しています。SPS-C01はSnowflakeの一つ重要な認証試験で多くのIT専門スタッフが認証される重要な試験です。
SPS-C01学習資料: https://www.jptestking.com/SPS-C01-exam.html
P.S. JPTestKingがGoogle Driveで共有している無料かつ新しいSPS-C01ダンプ:https://drive.google.com/open?id=1Lb-wSiJhA8rlS3tU1Wca7xM_d2sq8X6r