
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=1MiUpka4nPONrByIkIc4kmp1It33Nlgj-
Our MLA-C01 study question has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit MLA-C01 exam questions. It points to the exam heart to solve your difficulty. So high quality materials can help you to pass your exam effectively, make you feel easy, to achieve your goal. With the MLA-C01 Test Guide use feedback, it has 98%-100% pass rate. That’s the truth from our customers. And it is easy for you to pass the MLA-C01 exam after 20 hours’ to 30 hours’ practice.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Exam Duration: | 170 minutes |
| Available Languages: | Traditional Chinese, Simplified Chinese, Japanese, English, Korean |
| Certificate Validity Period: | 3 years |
| Exam Price: | 150 USD |
| Related Certifications: | AWS Certified Solutions Architect - Associate AWS Certified Data Engineer - Associate AWS Certified Developer - Associate |
| Exam Format: | Multiple response, Multiple choice |
| Passing Score: | 1000-2000 scaled score (passing score approximately 720) |
| Real Exam Qty: | 85 |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored (Pearson VUE) or in-person testing center |
| Pre Condition: | Recommended: 2+ years of ML engineering experience, familiarity with AWS ML services |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
>> New Amazon MLA-C01 Exam Dumps <<
A considerable amount of effort goes into our products. So in most cases our MLA-C01 exam study materials are truly your best friend. On one hand, our MLA-C01 learning guide is the combination of the latest knowledge and the newest technology, which could constantly inspire your interest of study. On the other hand, our MLA-C01 test answers can predicate the exam correctly. Therefore you can handle the questions in the real exam like a cork. Through highly effective learning method and easily understanding explanation, you will pass the MLA-C01 Exam with no difficulty. Our slogans are genuinely engraving on our mind that is to help you pass the MLA-C01 exam, and ride on the crest of success!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 50
Case Study
A company is building a web-based AI application by using Amazon SageMaker. The application will provide the following capabilities and features: ML experimentation, training, a central model registry, model deployment, and model monitoring.
The application must ensure secure and isolated use of training data during the ML lifecycle. The training data is stored in Amazon S3.
The company needs to use the central model registry to manage different versions of models in the application.
Which action will meet this requirement with the LEAST operational overhead?
Answer: B
Explanation:
Amazon SageMaker Model Registry is a feature designed to manage machine learning (ML) models throughout their lifecycle. It allows users to catalog, version, and deploy models systematically, ensuring efficient model governance and management.
Key Features of SageMaker Model Registry:
Centralized Cataloging: Organizes models into Model Groups, each containing multiple versions.
Version Control: Maintains a history of model iterations, making it easier to track changes.
Metadata Association: Attach metadata such as training metrics and performance evaluations to models.
Approval Status Management: Allows setting statuses like PendingManualApproval or Approved to ensure only vetted models are deployed.
Seamless Deployment: Direct integration with SageMaker deployment capabilities for real-time inference or batch processing.
Implementation Steps:
Create a Model Group: Organize related models into groups to simplify management and versioning.
Register Model Versions: Each model iteration is registered as a version within a specific Model Group.
Set Approval Status: Assign approval statuses to models before deploying them to ensure quality control.
Deploy the Model: Use SageMaker endpoints for deployment once the model is approved.
Benefits:
Centralized Management: Provides a unified platform to manage models efficiently.
Streamlined Deployment: Facilitates smooth transitions from development to production.
Governance and Compliance: Supports metadata association and approval processes.
By leveraging the SageMaker Model Registry, the company can ensure organized management of models, version control, and efficient deployment workflows with minimal operational overhead.
AWS Documentation: SageMaker Model Registry
AWS Blog: Model Registry Features and Usage
NEW QUESTION # 51
A company is planning to use Amazon SageMaker to make classification ratings that are based on images. The company has 6 GB of training data that is stored on an Amazon FSx for NetApp ONTAP system virtual machine (SVM). The SVM is in the same VPC as SageMaker.
An ML engineer must make the training data accessible for ML models that are in the SageMaker environment.
Which solution will meet these requirements?
Answer: D
NEW QUESTION # 52
Hotspot Question
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
- Embedding
- Retrieval Augmented Generation (RAG)
- Temperature
- Token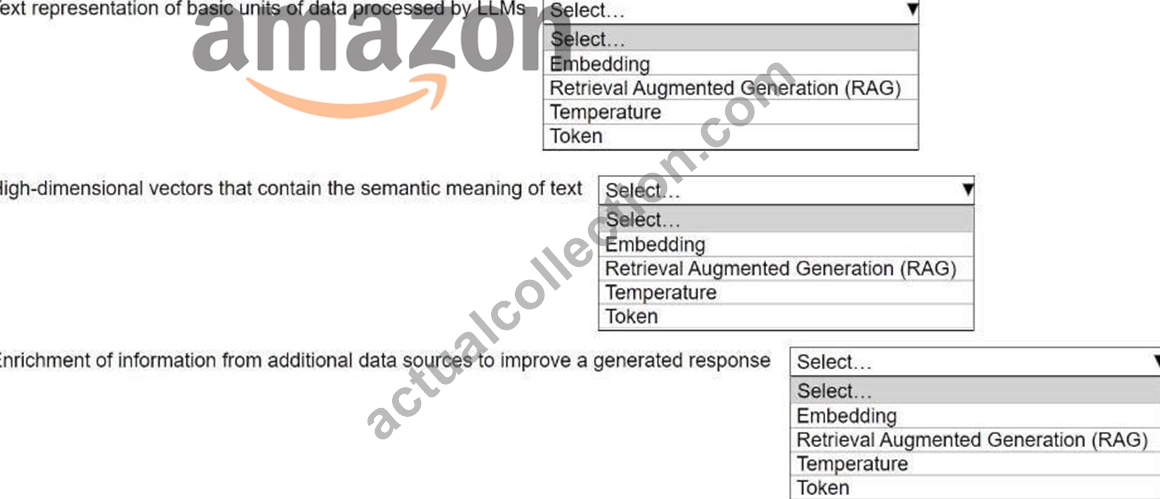
Answer:
Explanation: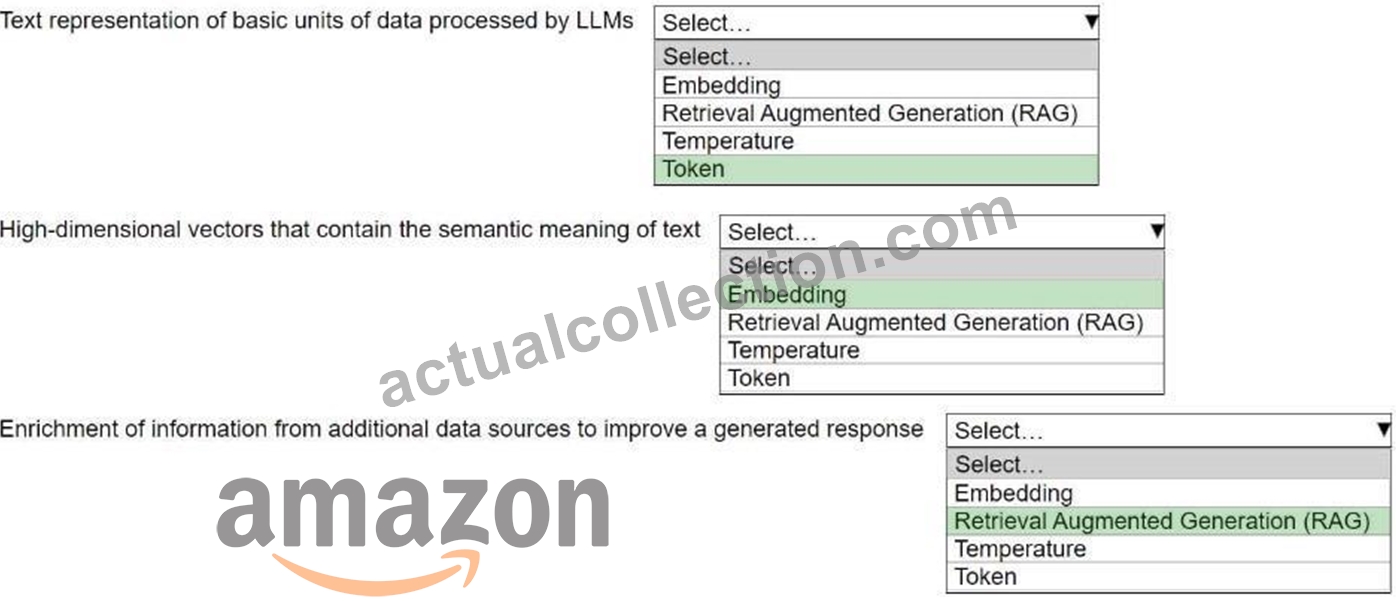
NEW QUESTION # 53
A company has an ML model that generates text descriptions based on images that customers upload to the company's website. The images can be up to 50 MB in total size.
An ML engineer decides to store the images in an Amazon S3 bucket. The ML engineer must implement a processing solution that can scale to accommodate changes in demand.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
SageMaker Asynchronous Inference is designed for processing large payloads, such as images up to 50 MB, and can handle requests that do not require an immediate response.
It scales automatically based on the demand, minimizing operational overhead while ensuring cost-efficiency.
A script can be used to send inference requests for each image, and the results can be retrieved asynchronously. This approach is ideal for accommodating varying levels of traffic with minimal manual intervention.
NEW QUESTION # 54
A company needs to combine data from multiple sources. The company must use Amazon Redshift Serverless to query an AWS Glue Data Catalog database and underlying data that is stored in an Amazon S3 bucket.
Select and order the correct steps from the following list to meet these requirements. Select each step one time or not at all. (Select and order three.)
* Attach the IAM role to the Redshift cluster.
* Attach the IAM role to the Redshift namespace.
* Create an external database in Amazon Redshift to point to the Data Catalog schema.
* Create an external schema in Amazon Redshift to point to the Data Catalog database.
* Create an IAM role for Amazon Redshift to use to access only the S3 bucket that contains underlying data.
* Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.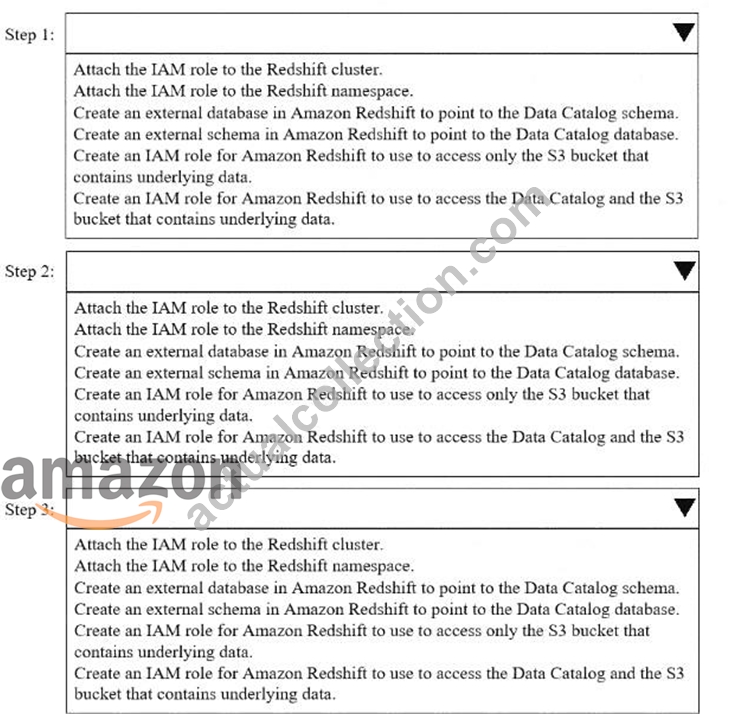
Answer:
Explanation: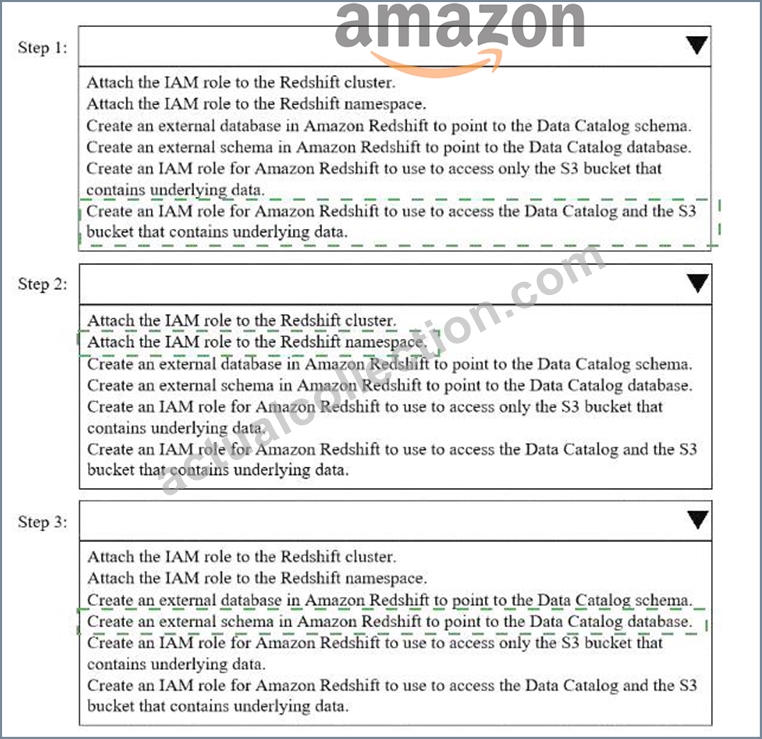
Explanation:
Step 1
Create an IAM role for Amazon Redshift to use to access the Data Catalog and the S3 bucket that contains underlying data.
This role must include:
Permissions for AWS Glue Data Catalog (e.g., glue:GetDatabase, glue:GetTables) Permissions for the Amazon S3 bucket that stores the underlying data Step 2 Attach the IAM role to the Redshift namespace.
Redshift Serverless uses a namespace, not a cluster, so the role must be associated with the namespace to allow Redshift to assume it when querying external data.
Step 3
Create an external schema in Amazon Redshift to point to the Data Catalog database.
The external schema maps Redshift to the Glue Data Catalog database so Redshift can query the tables stored in S3.
NEW QUESTION # 55
......
MLA-C01 Cert Guide: https://www.actualcollection.com/MLA-C01-exam-questions.html
What's more, part of that ActualCollection MLA-C01 dumps now are free: https://drive.google.com/open?id=1MiUpka4nPONrByIkIc4kmp1It33Nlgj-