What's more, part of that ActualVCE Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1VRJ5MstPJYbHhCLhIUsK5mIUHdXdHHkK
Nowadays, a certificate is not only an affirmation of your ablity but also help you enter a better company. Professional-Machine-Learning-Engineer learning materials will offer you an opportunity to get the certificate successfully. We have a professional team to search for the information about the exam, therefore Professional-Machine-Learning-Engineer Exam Dumps of us are high-quality. We also pass guarantee and money back guarantee. Just think that, you just need to spend some money, and you can get a certificate, therefore you can have more competitive force in the job market as well as improve your salary.
| Section | Weight | Objectives |
|---|---|---|
| Monitor and optimize AI solutions | 16% | - Troubleshoot and maintain production systems - Optimize cost, latency, and resource usage - Monitor data quality and pipeline health - Monitor model performance, fairness, and drift |
| Automate and orchestrate ML pipelines | 18% | - Automate retraining and model updates - Use Vertex AI Pipelines, TFX, and other orchestration tools - Implement CI/CD for ML systems - Design end-to-end ML workflows |
| Train and deploy models | 20% | - Deploy models for online, batch, and streaming prediction - Configure training jobs and environments - Implement generative AI deployment patterns - Use Vertex AI deployment features and infrastructure |
| Scale prototypes into AI models | 18% | - Optimize model performance and generalization - Design and run experiments - Select appropriate model architectures and frameworks - Work with foundation models and generative AI techniques |
| Collaborate to manage data and models | 16% | - Address data privacy, compliance, and governance - Manage datasets and features in Vertex AI - Organize and prepare enterprise data
|
| Architect low-code AI solutions | 12% | - Identify use cases for low-code/no-code AI tools - Design solutions using Vertex AI Studio, Model Garden, and Agent Builder - Apply responsible AI principles to low-code designs |
>> New Professional-Machine-Learning-Engineer Test Questions <<
All of our considerate designs have a strong practicability. We are still researching on adding more useful buttons on our Professional-Machine-Learning-Engineer test answers. The aim of our design is to improve your learning and all of the functions of our products are completely real. Then the learning plan of the Professional-Machine-Learning-Engineer exam torrent can be arranged reasonably. The scores are calculated by every question of the Professional-Machine-Learning-Engineer Exam guides you have done. So the final results will display how many questions you have answered correctly and mistakenly. You even can directly know the score of every question, which is convenient for you to know the current learning condition.
NEW QUESTION # 313
You have been asked to productionize a proof-of-concept ML model built using Keras. The model was trained in a Jupyter notebook on a data scientist's local machine. The notebook contains a cell that performs data validation and a cell that performs model analysis. You need to orchestrate the steps contained in the notebook and automate the execution of these steps for weekly retraining. You expect much more training data in the future. You want your solution to take advantage of managed services while minimizing cost. What should you do?
Answer: C
NEW QUESTION # 314
You work for a magazine publisher and have been tasked with predicting whether customers will cancel their annual subscription. In your exploratory data analysis, you find that 90% of individuals renew their subscription every year, and only 10% of individuals cancel their subscription. After training a NN Classifier, your model predicts those who cancel their subscription with 99% accuracy and predicts those who renew their subscription with 82% accuracy. How should you interpret these results?
Answer: D
Explanation:
This is not a good result because the model is performing worse than predicting that people will always renew their subscription. This option has the following reasons:
* It indicates that the model is not learning from the data, but rather memorizing the majority class. Since
90% of the individuals renew their subscription every year, the model can achieve a 90% accuracy by simply predicting that everyone will renew their subscription, without considering the features or the patterns in the data. However, the model's accuracy for predicting those who renew their subscription is
* only 82%, which is lower than the baseline accuracy of 90%. This suggests that the model is overfitting to the minority class (those who cancel their subscription), and underfitting to the majority class (those who renew their subscription).
* It implies that the model is not useful for the business problem, as it cannot identify the customers who are at risk of churning. The goal of predicting whether customers will cancel their annual subscription is to prevent customer churn and increase customer retention. However, the model's accuracy for predicting those who cancel their subscription is 99%, which is too high and unrealistic, as it means that the model can almost perfectly identify the customers who will churn, without any false positives or false negatives. This may indicate that the model is cheating or exploiting some leakage in the data, such as a feature that reveals the outcome of the prediction. Moreover, the model's accuracy for predicting those who renew their subscription is 82%, which is too low and unreliable, as it means that the model can miss many customers who will churn, and falsely label them as renewing customers. This can lead to losing customers and revenue, and failing to take proactive actions to retain them.
References:
* How to Evaluate Machine Learning Models: Classification Metrics | Machine Learning Mastery
* Imbalanced Classification: Predicting Subscription Churn | Machine Learning Mastery
NEW QUESTION # 315
You work for a gaming company that develops massively multiplayer online (MMO) games. You built a TensorFlow model that predicts whether players will make in-app purchases of more than $10 in the next two weeks. The model's predictions will be used to adapt each user's game experience. User data is stored in BigQuery. How should you serve your model while optimizing cost, user experience, and ease of management?
Answer: D
Explanation:
The best option to serve the model while optimizing cost, user experience, and ease of management is to deploy the model to Vertex AI Prediction, which is a managed service that can scale up or down according to the demand and provide low latency and high availability. Vertex AI Prediction can also handle TensorFlow models natively, without requiring any additional steps or conversions. By using batch prediction, the model can process large volumes of data efficiently and periodically, without affecting the user experience. The data can be read from Cloud Bigtable, which is a scalable and performant NoSQL database that can store user data in a flexible schema. The predictions can then be pushed to Cloud SQL, which is a fully managed relational database that can store the predictions in a structured format and enable easy querying and analysis. This option also simplifies the management of the model and the data, as it leverages the existing Google Cloud services and does not require any additional infrastructure or code.
The other options are not optimal for the following reasons:
* A. Importing the model into BigQuery ML is not a good option, as it requires converting the TensorFlow model into a format that BigQuery ML can understand, which can introduce errors and reduce the performance. Moreover, BigQuery ML is not designed for serving real-time predictions, but rather for training and evaluating models using SQL queries. Reading and writing data from BigQuery and Cloud SQL can also incur additional costs and latency, as they are both relational databases that require schema definition and data transformation.
* C. Embedding the model in the mobile application is not a good option, as it increases the size and complexity of the application, and requires updating the application every time the model changes.
Moreover, it exposes the model to the users, which can pose security and privacy risks, as well as potential misuse or abuse. Additionally, it does not leverage the benefits of the cloud, such as scalability, reliability, and performance.
* D. Embedding the model in the streaming Dataflow pipeline is not a good option, as it requires building and maintaining a custom pipeline that can handle the model inference and data processing. This can increase the development and operational costs and complexity, as well as the potential for errors and failures. Moreover, it does not take advantage of the batch prediction feature of Vertex AI Prediction, which can optimize the resource utilization and cost efficiency.
:
P rofessional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Profess ional Certificate Google Cloud launches machine learning engineer certification Vertex AI Prediction documentation Cloud Bigtable documentation Cloud SQL documentation
NEW QUESTION # 316
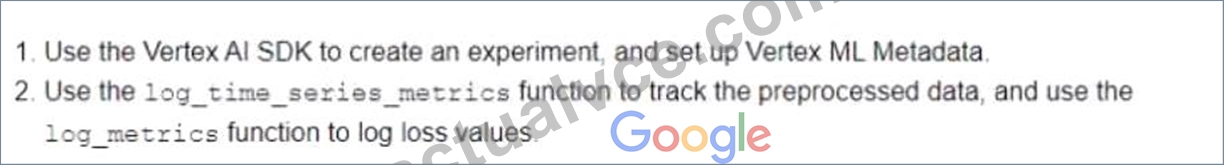
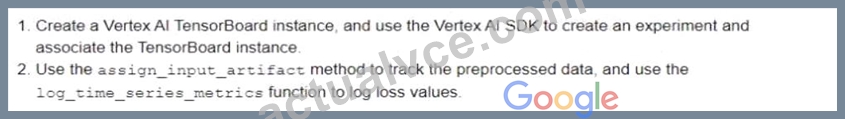
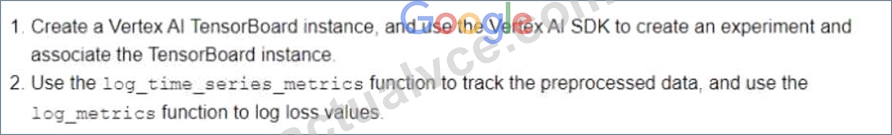
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?
Answer: B
Explanation:
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References:
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
NEW QUESTION # 317
You manage a team of data scientists who use a cloud-based backend system to submit training jobs. This system has become very difficult to administer, and you want to use a managed service instead. The data scientists you work with use many different frameworks, including Keras, PyTorch, theano. Scikit-team, and custom libraries. What should you do?
Answer: C
Explanation:
A cloud-based backend system is a system that runs on a cloud platform and provides services or resources to other applications or users. A cloud-based backend system can be used to submit training jobs, which are tasks that involve training a machine learning model on a given dataset using a specific framework and configuration1 However, a cloud-based backend system can also have some drawbacks, such as:
* High maintenance: A cloud-based backend system may require a lot of administration and management, such as provisioning, scaling, monitoring, and troubleshooting the cloud resources and services. This can be time-consuming and costly, and may distract from the core business objectives2
* Low flexibility: A cloud-based backend system may not support all the frameworks and libraries that the data scientists need to use for their training jobs. This can limit the choices and capabilities of the data scientists, and affect the quality and performance of their models3
* Poor integration: A cloud-based backend system may not integrate well with other cloud services or
* tools that the data scientists need to use for their machine learning workflows, such as data processing, model deployment, or model monitoring. This can create compatibility and interoperability issues, and reduce the efficiency and productivity of the data scientists.
Therefore, it may be better to use a managed service instead of a cloud-based backend system to submit training jobs. A managed service is a service that is provided and operated by a third-party provider, and offers various benefits, such as:
* Low maintenance: A managed service handles the administration and management of the cloud resources and services, and abstracts away the complexity and details of the underlying infrastructure. This can save time and money, and allow the data scientists to focus on their core tasks2
* High flexibility: A managed service can support multiple frameworks and libraries that the data scientists need to use for their training jobs, and allow them to customize and configure their training environments and parameters. This can enhance the choices and capabilities of the data scientists, and improve the quality and performance of their models3
* Easy integration: A managed service can integrate seamlessly with other cloud services or tools that the data scientists need to use for their machine learning workflows, and provide a unified and consistent interface and experience. This can solve the compatibility and interoperability issues, and increase the efficiency and productivity of the data scientists.
One of the best options for using a managed service to submit training jobs is to use the AI Platform custom containers feature to receive training jobs using any framework. AI Platform is a Google Cloud service that provides a platform for building, deploying, and managing machine learning models. AI Platform supports various machine learning frameworks, such as TensorFlow, PyTorch, scikit-learn, and XGBoost, and provides various features, such as hyperparameter tuning, distributed training, online prediction, and model monitoring.
The AI Platform custom containers feature allows the data scientists to use any framework or library that they want for their training jobs, and package their training application and dependencies as a Docker container image. The data scientists can then submit their training jobs to AI Platform, and specify the container image and the training parameters. AI Platform will run the training jobs on the cloud infrastructure, and handle the scaling, logging, and monitoring of the training jobs. The data scientists can also use the AI Platform features to optimize, deploy, and manage their models.
The other options are not as suitable or feasible. Configuring Kubeflow to run on Google Kubernetes Engine and receive training jobs through TFJob is not ideal, as Kubeflow is mainly designed for TensorFlow-based training jobs, and does not support other frameworks or libraries. Creating a library of VM images on Compute Engine and publishing these images on a centralized repository is not optimal, as Compute Engine is a low-level service that requires a lot of administration and management, and does not provide the features and integrations of AI Platform. Setting up Slurm workload manager to receive jobs that can be scheduled to run on your cloud infrastructure is not relevant, as Slurm is a tool for managing and scheduling jobs on a cluster of nodes, and does not provide a managed service for training jobs.
References: 1: Cloud computing 2: Managed services 3: Machine learning frameworks : [Machine learning workflow] : [AI Platform overview] : [Custom containers for training]
NEW QUESTION # 318
......
You can also trust on ActualVCE Google Professional-Machine-Learning-Engineer exam dumps and start Professional-Machine-Learning-Engineer exam preparation with confidence. The ActualVCE Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) practice questions are designed and verified by experienced and qualified Google exam trainers. They utilize their expertise, experience, and knowledge and ensure the top standard of ActualVCE Professional-Machine-Learning-Engineer Exam Dumps. So you can trust ActualVCE Google Professional-Machine-Learning-Engineer exam questions with complete peace of mind and satisfaction.
Professional-Machine-Learning-Engineer Online Exam: https://www.actualvce.com/Google/Professional-Machine-Learning-Engineer-valid-vce-dumps.html
BONUS!!! Download part of ActualVCE Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=1VRJ5MstPJYbHhCLhIUsK5mIUHdXdHHkK