從Google Drive中免費下載最新的VCESoft Workday-Pro-Integrations PDF版考試題庫:https://drive.google.com/open?id=1STSyDsHPW65OV-heQqVmIyTqLi-RiWof
VCESoft Workday的Workday-Pro-Integrations考試認證培訓資料是互聯網裏最好的培訓資料,在所有的培訓資料裏是佼佼者。它不僅可以幫助你順利通過考試,還可以提高你的知識和技能,也有助於你的職業生涯在不同的條件下都可以發揮你的優勢,所有的國家一視同仁。
| Certification Vendor: | Workday |
|---|---|
| Exam Name: | Workday Pro Integrations Certification Exam |
| Exam Number: | Workday-Pro-Integrations |
| Related Certifications: | Workday Pro Certifications Workday Integrations |
| Available Languages: | English |
| Exam Format: | Multiple Choice |
| Sample Questions: | Workday Workday-Pro-Integrations Sample Questions |
| Official Syllabus URL: | https://www.workday.com/en-us/services/certifications.html |
>> Workday-Pro-Integrations考試資訊 <<
不需要大量的時間和金錢,僅需30個小時左右的特殊培訓,你就能輕鬆通過你的第一次參加的Workday Workday-Pro-Integrations 認證考試。VCESoft能為你提供與真實的考試題目有緊密相似性的考試練習題。
| 主題 | 簡介 |
|---|---|
| 主題 1 |
|
| 主題 2 |
|
| 主題 3 |
|
| 主題 4 |
|
| 主題 5 |
|
問題 #55
Refer to the following XML to answer the question below.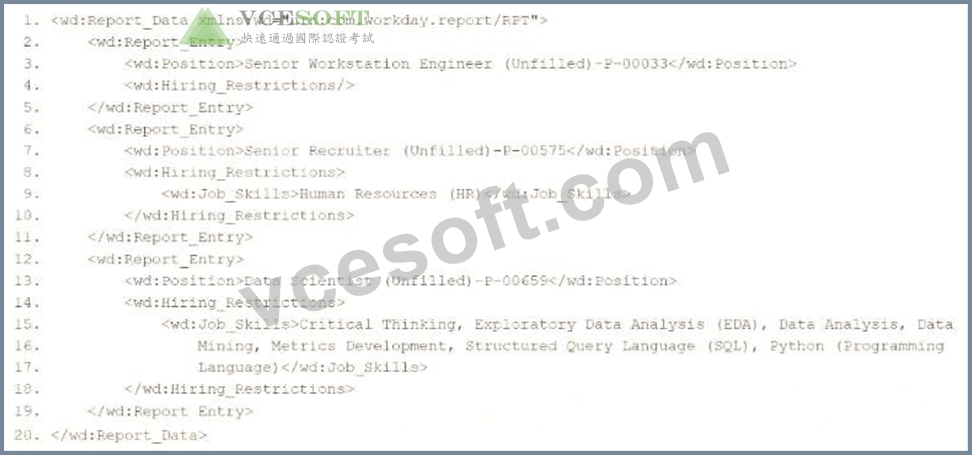
You are an integration developer and need to write X8LT to transform the output of an ElB which is using a web service enabled report to output position data along with hiring restrictions around skills. You currently have a template which matches on wd:Report Data/wd: Report .Entry for creating a record from each report entry.
Within the template which matches on wd:Report_Entry you would like to conditionally process the wd:
Job_Skills element by using a series of < xsl:if > elements so as to categorize the job skills data.
Assuming all jobs will have the wd:Job_Skills element, what XSLT syntax would be used to output the text HR Skills if the value of wd:Job_Skills contains the text HR and output NON-HR Skills if the value of wd:
Job_Skills does not contain the text HR?

答案:B
解題說明:
The task is to write XSLT within a template matching wd:Report_Data/wd:Report_Entry to categorize wd:
Job_Skills data, outputting " HR Skills " if the value contains " HR " and " NON-HR Skills " if it does not, using a series of < xsl:if > elements. The correct syntax must use the contains() function to check for the substring " HR " within wd:Job_Skills, as the question implies partial matching (e.g., " HR Specialist " or " Senior HR " ), not exact equality.
Let's analyze each option:
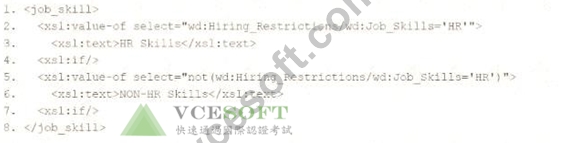
* Option A:
xml
< job_skill >
< xsl:value-of select= " wd:Hiring_Restrictions/wd:Job_Skills= ' HR ' " >
< xsl:text > HR Skills < /xsl:text >
< xsl:if/ >
< xsl:value-of select= " not(wd:Hiring_Restrictions/wd:Job_Skills= ' HR ' ) " >
< xsl:text > NON-HR Skills < /xsl:text >
< xsl:if/ >
< /job_skill >
* Issues:
* < xsl:value-of > is misused here. It outputs the result of the expression (e.g., " true " or " false " for a comparison), not the conditional text. The < xsl:text > inside won't execute as intended.
* The = operator checks for exact equality (e.g., wd:Job_Skills must be exactly " HR " ), not substring presence, which contradicts the requirement to check if " HR " is contained within the value.
* < xsl:if/ > is malformed (self-closing without a test attribute) and misplaced.
* Verdict: Incorrect syntax and logic.
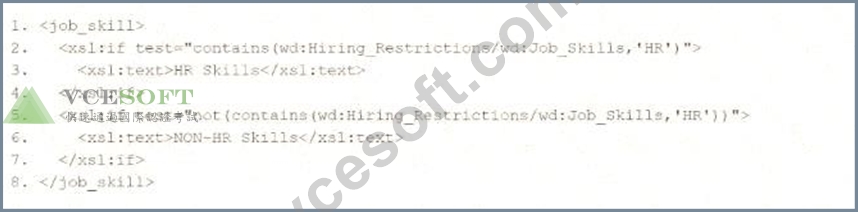
* Option B:
xml
< job_skill >
< xsl:value-of select= " contains(wd:Hiring_Restrictions/wd:Job_Skills, ' HR ' ) " >
< xsl:text > HR Skills < /xsl:text >
< xsl:if/ >
< xsl:value-of select= " not(contains(wd:Hiring_Restrictions/wd:Job_Skills, ' HR ' )) " >
< xsl:text > NON-HR Skills < /xsl:text >
< xsl:if/ >
< /job_skill >
* Issues:
* Similar to A, < xsl:value-of > outputs the boolean result of contains() ( " true " or " false " ), not the conditional text " HR Skills " or " NON-HR Skills. "
* The < xsl:text > elements are inside invalid < xsl:if/ > tags (self-closing, no test), rendering them ineffective.
* While contains() is correct for substring checking, the structure fails to meet the < xsl:if > requirement.
* Verdict: Incorrect structure despite using contains().
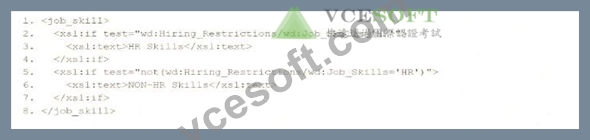
* Option C:
xml
< job_skill >
< xsl:if test= " wd:Hiring_Restrictions/wd:Job_Skills= ' HR ' " >
< xsl:text > HR Skills < /xsl:text >
< /xsl:if >
< xsl:if test= " not(wd:Hiring_Restrictions/wd:Job_Skills= ' HR ' ) " >
< xsl:text > NON-HR Skills < /xsl:text >
< /xsl:if >
< /job_skill >
* Analysis:
* Uses < xsl:if > correctly with test attributes, satisfying the " series of < xsl:if > elements " requirement.
* However, wd:Job_Skills= ' HR ' tests for exact equality, not whether " HR " is contained within the value. For example, " HR Specialist " would fail this test, outputting " NON-HR Skills " incorrectly.
* Verdict: Semantically incorrect due to exact matching instead of substring checking.
* Option D:
xml
< job_skill >
< xsl:if test= " contains(wd:Hiring_Restrictions/wd:Job_Skills, ' HR ' ) " >
< xsl:text > HR Skills < /xsl:text >
< /xsl:if >
< xsl:if test= " not(contains(wd:Hiring_Restrictions/wd:Job_Skills, ' HR ' )) " >
< xsl:text > NON-HR Skills < /xsl:text >
< /xsl:if >
< /job_skill >
* Analysis:
* Correctly uses < xsl:if > with test attributes, aligning with the question's requirement.
* The contains() function properly checks if " HR " is a substring within wd:Job_Skills (e.g.,
" HR Manager " or " Senior HR " returns true).
* not(contains()) ensures the opposite condition, covering all cases (mutually exclusive).
* < xsl:text > outputs the exact strings " HR Skills " or " NON-HR Skills " as required.
* Note: The closing tag < /xs1:if > is a typo in the option (should be < /xsl:if > ), but in context, it's an obvious formatting error, not a substantive issue.
* Verdict: Correct logic and syntax, making D the best answer.
Correct Implementation in Context:
xml
< xsl:template match= " wd:Report_Data/wd:Report_Entry " >
< job_skill >
< xsl:if test= " contains(wd:Hiring_Restrictions/wd:Job_Skills, ' HR ' ) " >
< xsl:text > HR Skills < /xsl:text >
< /xsl:if >
< xsl:if test= " not(contains(wd:Hiring_Restrictions/wd:Job_Skills, ' HR ' )) " >
< xsl:text > NON-HR Skills < /xsl:text >
< /xsl:if >
< /job_skill >
< /xsl:template >
* Example Input: < wd:Job_Skills > Senior HR Analyst < /wd:Job_Skills > # Output: < job_skill > HR Skills < /job_skill >
* Example Input: < wd:Job_Skills > IT Specialist < /wd:Job_Skills > # Output: < job_skill > NON-HR Skills < /job_skill > Workday Pro Integrations Study Guide: " Configure Integration System - TRANSFORMATION " section, detailing < xsl:if > and contains() for conditional XSLT logic in Workday.
Workday Documentation: " XSLT Transformations in Workday " under EIB, confirming wd: namespace usage and string functions.
W3C XSLT 1.0 Specification: Section 9.1, " Conditional Processing with < xsl:if > , " and Section 11.2, " String Functions " (contains()).
Workday Community: Examples of substring-based conditionals in XSLT for report transformations.
問題 #56
You are configuring a Core Connector: Worker integration to send data to a new external compliance and certification tracking vendor. You have begun to configure the connector with the Data Initialization Service (DIS) enabled. Your goal is to extract worker qualification data, but the vendor has three specific requirements:
The file must only include Active workers who are in the "Clinical Staff" job family.
The vendor has specified that for each worker's Education data, they want to receive the Institution Name, Institution Type, and Degrees.
The vendor requires a custom "License ID" that must combine the Certification Name and Issuing State, for example "RN-CA". A Calculated Field that provides this custom "License ID" already exists in the tenant.
What configuration step should you modify to ensure the integration only includes Active workers in the Clinical Staff job family?
答案:B
解題說明:
The requirement is population filtering, not output formatting. In a Core Connector: Worker integration, Integration Population Eligibility determines which workers qualify for extraction before the connector produces the output file. To include only active workers in the Clinical Staff job family, the eligibility rule must evaluate worker status and job family together. Integration Field Overrides are used when replacing or adding output values, such as a calculated License ID. Integration Attributes control connector-level configuration and do not restrict the worker population. Transaction Log configuration controls which transaction types are detected for change processing, not whether a worker belongs to the desired eligible population. Therefore, the correct configuration step is Integration Population Eligibility.
問題 #57
Refer to the scenario. You are configuring a Core Connector: Worker integration with the Data Initialization Service (DIS) enabled to extract worker demographic and contact information. The integration must include worker fields such as name, address, and a calculated field identifying workers eligible for a phone allowance.
The Phone Allowance Type calculated field exists and is functional in the tenant, but it is not displaying in the output.
What configuration step should you complete to include this field in the output?
答案:C
解題說明:
In this scenario, a calculated field (Phone Allowance Type) is available and validated in the tenant, but it does not appear in the Core Connector: Worker output. The integration is configured with DIS enabled, and the expected behavior is for all specified worker data - including name, address, and calculated fields - to be included in the output file.
The correct action is to enable the field from the Configure Integration Field Attributes step.
From Workday Pro: Integrations materials:
"In order for a calculated field to be included in a Core Connector output, it must be explicitly located and selected from within the Configure Integration Field Attributes task. This step determines what fields are extracted in the integration output - including any standard or calculated fields available in the object model." Even though the field exists and is functional, it must be manually located within the relevant section (e.g., Worker Data > Compensation or Worker Details), and marked to include in the output.
Incorrect Options Explained:
A . Configure Integration Field Overrides: This is used to change or override output formatting but does not control field visibility.
B . Configure Integration Maps: Used for mapping values or converting code sets, not for selecting fields for output.
C . Create a Custom Field Override service: This is not necessary for simply adding a calculated field; the existing field can be enabled via attributes configuration.
Reference:
Workday Pro: Core Connector - Field Selection Using Configure Integration Field Attributes Workday Community: How to Include Calculated Fields in Connector Outputs
問題 #58
You are creating an outbound connector using the Core Connector: Organization Outbound template. The vendor has provided the following requirements for how the data should appear in the output file.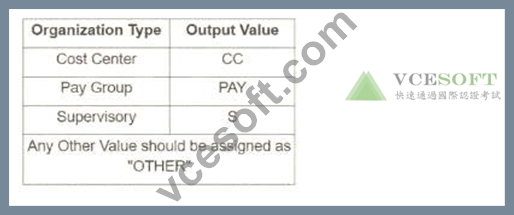
The vendor would also like to change the default document retention policy of 30 days to 7 days. What tasks do you need to use to configure this in your connector?
答案:B
解題說明:
When creating an outbound connector using the Workday Core Connector: Organization Outbound template, you need to configure the connector to meet specific vendor requirements, such as formatting output data and adjusting document retention policies. Let ' s break down the question and analyze the requirements and options based on Workday ' s integration framework, specifically focusing on the Core Connector and its configuration tasks.
Understanding the Requirements
* Output Data Formatting:The vendor has provided a table specifying how organization types should appear in the output file (e.g., Cost Center as " CC " , Pay Group as " PAY " , Supervisory as " S " , and any other value as " OTHER " ). This indicates a need to transform or map Workday organization data into specific output values, which is typically handled by configuring how fields are processed or mapped in the integration.
* Document Retention Policy Change:The vendor wants to change the default document retention policy from 30 days to 7 days. In Workday, document retention policies for integrations (e.g., files stored on SFTP or other delivery methods) are managed through integration settings, specifically attributes related to file retention or delivery options.
Analyzing Workday Core Connector: Organization Outbound
The Core Connector: Organization Outbound template is a pre-built Workday integration template used to extract organization-related data (e.g., cost centers, pay groups, supervisory organizations) and send it to an external system. It leverages Workday ' s integration framework, including integration maps, field overrides, and attributes, to customize data output and behavior.
* Integration Maps: Used to define how data is transformed or mapped from Workday to the output format, often involving XSLT or predefined mappings.
* Integration Field Overrides: Allow you to override or customize how specific fields are displayed or formatted in the output, such as mapping " Cost Center " to " CC " as per the vendor ' s table.
* Integration Attributes: Control broader integration settings, such as delivery methods, file formats, and retention policies (e.g., document retention duration).
* Integration Field Attributes: Typically focus on specific field-level properties but are less commonly used for retention policies or broad mappings compared to the above options.
Evaluating the Vendor ' s Output Requirements
The table provided (Cost Center # " CC " , Pay Group # " PAY " , Supervisory # " S " , any other value # " OTHER " ) suggests a need to transform or override the default output values for organization types. This is a field-level customization, best handled by Integration Field Overrides, which allow you to specify custom values or formats for specific fields in the output.
* For example, in the Core Connector, you can use Integration Field Overrides to map the Workday organization type (e.g., " Cost_Center " ) to the vendor ' s desired output ( " CC " ). This is a common practice for outbound integrations where external systems require specific formatting.
Evaluating the Retention Policy Change
The default document retention policy of 30 days needs to be changed to 7 days. In Workday, retention policies for integration output files (e.g., files delivered via SFTP or email) are configured as part of the integration ' s attributes, not field-level settings.
* Integration Attributes are used to manage integration-wide settings, including delivery options, file retention periods, and other global configurations. You can specify the retention period (e.g., 7 days) in the attributes section of the Core Connector configuration.
* This is distinct from field-level overrides or maps, as retention is not tied to individual data fields but to the integration ' s output management.
Analyzing the Options
Now, let ' s evaluate each option to determine which tasks are needed to meet both requirements:
* A. Configure Integration Maps and Configure Integration Attributes
* Integration Maps: These are used for broader data transformations or mappings, such as converting Workday XML to another format or defining complex data relationships. While they could theoretically handle the output value mappings (e.g., Cost Center # " CC " ), they are typically more complex and less granular than field overrides for simple value changes.
* Integration Attributes: Correct for configuring the retention policy (e.g., changing from 30 to 7 days), as attributes manage integration-wide settings like retention.
* Why Not Sufficient?: Integration Maps are overkill for simple field value overrides like the vendor ' s table, and field-level customization is better handled by Integration Field Overrides for precision and ease.
* B. Configure Integration Field Overrides and Configure Integration Field Attributes
* Integration Field Overrides: Correct for mapping specific field values (e.g., Cost Center # " CC " ), as they allow granular control over output formats for individual fields.
* Integration Field Attributes: These are less commonly used and typically focus on field-specific properties (e.g., data type, length), not broad integration settings like retention policies. Retention is not managed at the field level, so this is incorrect for the retention requirement.
* Why Not Sufficient?: Integration Field Attributes do not handle retention policies, making this option incomplete.
* C. Configure Integration Field Overrides and Configure Integration Attributes
* Integration Field Overrides: Perfect for mapping the vendor ' s output values (e.g., Cost Center #
" CC " , Pay Group # " PAY " , etc.), as they allow precise control over field-level output formatting.
* Integration Attributes: Correct for configuring the retention policy (e.g., changing from 30 to 7 days), as attributes manage integration-wide settings like file retention.
* Why Sufficient?: This combination addresses both requirements-field-level output formatting and integration-wide retention policy changes-making it the most accurate choice.
* D. Configure Integration Maps and Configure Integration Field Attributes
* Integration Maps: As explained, these are better for complex transformations, not simple field value overrides like the vendor ' s table. They could work but are less efficient than field overrides.
* Integration Field Attributes: As noted, these do not handle retention policies or broad integration settings, making them incorrect for the retention requirement.
* Why Not Sufficient?: This combination fails to address retention effectively and uses Integration Maps when Integration Field Overrides would be more appropriate for the output formatting.
Conclusion
Based on the analysis, the vendor ' s requirements for output formatting (mapping organization types to specific values) and changing the retention policy (from 30 to 7 days) are best met by:
* Integration Field Overrides: To customize the output values for organization types (e.g., Cost Center # " CC " ) as shown in the table.
* Integration Attributes: To adjust the document retention policy from 30 days to 7 days.
問題 #59
You have configured a filename sequence generator for a connector integration. The vendor decides that a unique filename is no longer required.
How would you modify the integration to meet this requirement?
答案:D
解題說明:
Key Points:
The correct approach is adjusting the connector's filename launch parameter, which allows setting a static filename and meeting the vendor's requirement of no longer needing unique filenames.
This method ensures that the filename sequence generator is bypassed without disrupting the integration process.
Comprehensive Detailed
In Workday Pro Integrations, filename sequence generators are commonly used to generate unique filenames to avoid overwrites in integrations. However, when a vendor no longer requires unique filenames, modifications must be made to use a fixed filename instead.
Why Option D?
Adjusting the connector's filename launch parameter lets you set a static filename at runtime, effectively overriding any sequence generator settings.
Unlike deleting the sequence generator (which could cause errors), this method ensures smooth execution of the integration with a fixed filename.
This aligns with Workday's best practices for integration configurations, particularly in External Integration Business (EIB) and other Workday connector integrations.
Steps to Implement:
Access the integration's configuration in Workday.
Locate the filename launch parameter for the connector.
Set it to a static value (e.g., "data.txt") to ensure consistent naming.
Supporting Documentation:
Workday documentation on integration configurations, particularly for EIB systems, confirms that filename settings can be adjusted via launch parameters.
The "Get_Sequence_Generators Operation Details" in Workday API documentation supports modifying filename configurations through launch parameters.
問題 #60
......
Workday-Pro-Integrations考試大綱: https://www.vcesoft.com/Workday-Pro-Integrations-pdf.html
P.S. VCESoft在Google Drive上分享了免費的、最新的Workday-Pro-Integrations考試題庫:https://drive.google.com/open?id=1STSyDsHPW65OV-heQqVmIyTqLi-RiWof