그리고 ExamPassdump Databricks-Certified-Professional-Data-Engineer 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1RL0omEmE7IKs5EjHLritcCzan0W4trs6
목표가 있다면 목표를 향해 끊임없이 달려야 멋진 인생이 됩니다. 지금의 현황에 만족하여 아무런 노력도 하지 않는다면 언젠가는 치열한 경쟁을 이겨내지 못하게 될것입니다. IT업종에 종사중이시라면 다른분들이 모두 취득하는 자격증쯤은 마련해야 되지 않겠습니까? Databricks인증 Databricks-Certified-Professional-Data-Engineer시험은 요즘 가장 인기있는 자격증 시험의 한과목입니다. IT업계에서 살아남으려면ExamPassdump에서Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프를 마련하여 자격증에 도전하여 자기의 자리를 찾아보세요.
Databricks Certified Professional Data Engineer Certification Exam은 후보자가 Databricks를 사용하여 데이터 파이프 라인 및 워크 플로우 구축에 대한 기술을 시연 해야하는 실습 시험입니다. 이 시험은 후보자가 데이터 사업 환경에서 데이터 솔루션을 설계, 구현 및 관리 해야하는 일련의 성능 기반 작업으로 구성됩니다. 응시자에게는 일련의 데이터 엔지니어링 시나리오가 제공되며 각 시나리오의 요구 사항을 충족하는 솔루션을 구축하기 위해 데이터 사업을 사용해야합니다.
Databricks Certified Professional Data Engineer Exam은 빅 데이터 기술, 특히 Databricks 플랫폼에서 작업하는 전문가의 기술과 지식을 검증하는 인증 프로그램입니다. 이 시험은 후보자의 데이터 파이프 라인을 설계, 구축 및 유지 관리하고 기계 학습 워크 플로우 구현 및 Databricks 플랫폼에서 성능을 최적화하는 능력을 테스트하도록 설계되었습니다. 이 인증은 데이터 엔지니어, 데이터 아키텍트 및 분야의 전문 지식을 보여 주려고하는 빅 데이터 전문가에게 이상적입니다.
>> Databricks-Certified-Professional-Data-Engineer최고품질 덤프데모 다운 <<
ExamPassdump의Databricks인증 Databricks-Certified-Professional-Data-Engineer시험대비 덤프는 가격이 착한데 비하면 품질이 너무 좋은 시험전 공부자료입니다. 시험문제적중율이 높아 패스율이 100%에 이르고 있습니다.다른 IT자격증에 관심이 있는 분들은 온라인서비스에 문의하여 덤프유무와 적중율등을 확인할수 있습니다. Databricks인증 Databricks-Certified-Professional-Data-Engineer덤프로 어려운 시험을 정복하여 IT업계 정상에 오릅시다.
Databricks Certified Professional Data Engineer(Databricks-Certified-Professional-Data-Engineer) 시험은 Databricks를 사용하여 데이터 파이프라인을 구축하고 관리하는 데이터 엔지니어의 지식과 기술을 검증하는 자격증 시험입니다. Databricks는 클라우드 기반 데이터 처리 및 분석 플랫폼으로, 데이터 과학자, 데이터 엔지니어 및 비즈니스 분석가가 대규모 데이터와 함께 협업하고 작업할 수 있는 통합 워크스페이스를 제공합니다. 이 시험은 Databricks를 사용하여 데이터 파이프라인을 개발하고 유지 관리하는 경험이 있는 데이터 엔지니어들이 자신의 기술과 지식을 검증하고자 할 때 응시할 수 있습니다.
질문 # 71
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property " contains_pii " = true .
The following SQL DDL statement is executed to create a new table: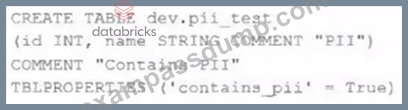
Which command allows manual confirmation that these three requirements have been met?
정답:D
설명:
This is the correct answer because it allows manual confirmation that these three requirements have been met.
The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property
"contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement. Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "DESCRIBE EXTENDED" section.
질문 # 72
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank:
Which response correctly fills in the blank to meet the specified requirements?
정답:D
설명:
Option B correctly fills in the blank to meet the specified requirements. Option B uses the
"cloudFiles.schemaLocation" option, which is required for the schema detection and evolution functionality of Databricks Auto Loader. Additionally, option B uses the "mergeSchema" option, which is required for the schema evolution functionality of Databricks Auto Loader. Finally, option B uses the "writeStream" method, which is required for the incremental processing of JSON files as they arrive in a source directory. The other options are incorrect because they either omit the required options, use the wrong method, or use the wrong format. References:
* Configure schema inference and evolution in Auto Loader:
https://docs.databricks.com/en/ingestion/auto-loader/schema.html
* Write streaming data:
https://docs.databricks.com/spark/latest/structured-streaming/writing-streaming-data.html
질문 # 73
Which of the statements are incorrect when choosing between lakehouse and Datawarehouse?
정답:B
설명:
Explanation
The answer is Lakehouse cannot serve low query latency with high reliability for BI workloads, only suitable for batch workloads.
Lakehouse can replace traditional warehouses by leveraging storage and compute optimizations like caching to serve them with low query latency with high reliability.
Focus on comparisons between Spark Cache vs Delta Cache.
https://docs.databricks.com/delta/optimizations/delta-cache.html
What Is a Lakehouse? - The Databricks Blog
Graphical user interface, text, application Description automatically generated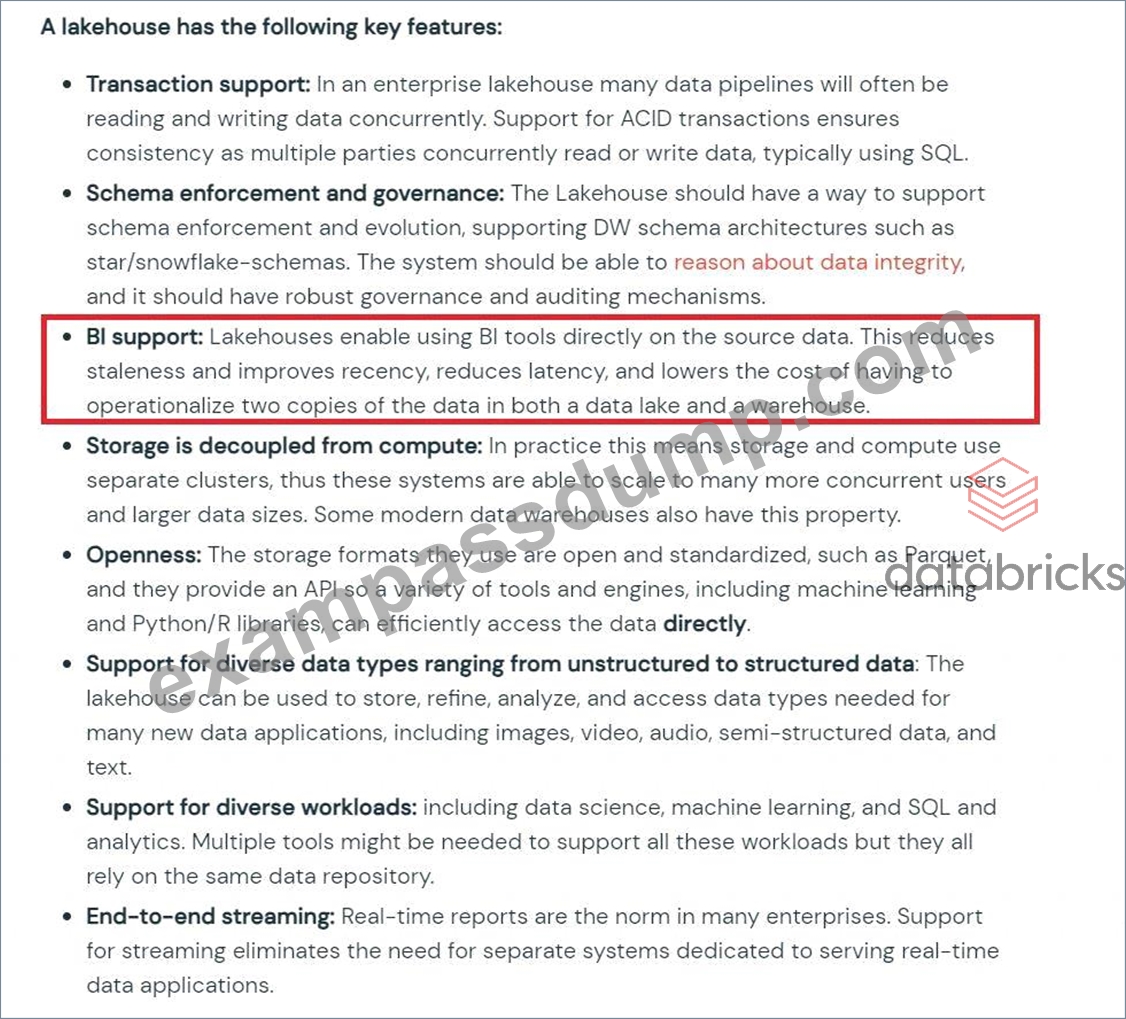
Bottom of Form
Top of Form
질문 # 74
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: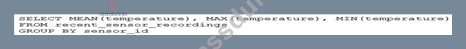
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
정답:E
설명:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120. Verified Reference: [Databricks Certified Data Engineer Professional], under "SQL Analytics" section; Databricks Documentation, under "Alerts" section.
질문 # 75
A company wants to implement Lakehouse Federation across multiple data sources but is concerned about data consistency and ensuring that all teams access the same authoritative version of their data.
Which statement is applicable for Lakehouse Federations to maintain data consistency?
정답:C
설명:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Lakehouse Federation allows Databricks to query and manage external data sources through a single governance layer, without moving or copying data. The documentation specifies that "Federated queries provide read-only access to data, reflecting the current state of the underlying source system." This ensures consistency across teams since all users access the same source of truth directly from the external system through Unity Catalog. Federation does not perform CDC replication or local caching; it queries live data on demand. Hence, option A accurately represents how Lakehouse Federation maintains consistency across federated sources.
질문 # 76
......
Databricks-Certified-Professional-Data-Engineer시험패스 가능한 인증덤프자료: https://www.exampassdump.com/Databricks-Certified-Professional-Data-Engineer_valid-braindumps.html
그리고 ExamPassdump Databricks-Certified-Professional-Data-Engineer 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1RL0omEmE7IKs5EjHLritcCzan0W4trs6