BONUS!!! Download part of BraindumpsPrep SPS-C01 dumps for free: https://drive.google.com/open?id=1abJ_u4zhiagqdTvOuWW8XR9PfF9_VqgR
The Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 exam is a valuable credential that will assist you to advance your career. To pass the SPS-C01 exam is not an easy job. It always gives tough times to their candidates. The best SPS-C01 Exam Preparation strategy along with the BraindumpsPrep SPS-C01 exam practice test questions can help you to crack the Snowflake SPS-C01 exam easily.
| Section | Objectives |
|---|---|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
>> SPS-C01 New Exam Braindumps <<
We own the profession experts on compiling the SPS-C01 exam questions and customer service on giving guide on questions from our clients. Our SPS-C01 preparation materials contain three versions: the PDF, the Software and the APP online. They give you different experience on trying out according to your interests and hobbies. And our SPS-C01 Study Guide can assure your success by precise and important information.
NEW QUESTION # 342
You have a Snowpark Python UDF that performs sentiment analysis on customer reviews. The UDF relies on a pre-trained machine learning model stored as a file in a Snowflake stage. To enhance security, you want to create a secure UDF. Which of the following steps are necessary to achieve this?
Answer: A,B
Explanation:
Secure UDFs require explicit grants to access resources. Granting READ privilege on the stage to the UDF owner ensures access during definition. 'secure=True' makes the UDF secure. 'USAGE ON STAGE must be granted to the role executing the UDF to allow it to read from the stage at runtime. 'SNOWFLAKE.DATA GOVERNANCE' role doesn't automatically grant access, and 'EXECUTE AS CALLER is not directly related to granting access to the model file. 'context' is not a standard parameter for UDF definitions and does not manage security context directly.
NEW QUESTION # 343
Consider a Snowpark DataFrame with a containing date values, some of which are corrupted (e.g., invalid date formats or out-of-range values). You need to identify and either remove or correct these corrupted date values. Which of the following approaches can be effectively used in Snowpark Python to handle such scenarios? (Select all that apply)
Answer: A,C,E
Explanation:
Options A, B, and D are valid approaches. Option A allows converting the column to date, setting incorrect values as NULL, which can then be filtered. Option B (UDF) provides flexibility for custom date parsing and error handling. Option D is valid as well, as it filters out data which doesn't match the expression. Option C is incorrect. The 'to_date' function in Snowpark does not have an 'IGNORE' keyword to replace invalid dates with NULL automatically. If it fails to convert to date, it will throw an error. Option E assumes that the corrupted dates can be pre-identified, which is generally not the case as the process aims to identify the dates that are corrupt, thus making it an incorrect answer.
NEW QUESTION # 344
You are tasked with building a Snowpark application to process sensor data from IoT devices. The data arrives as JSON strings and needs to be transformed into a tabular format before being stored in a Snowflake table. You decide to use a User-Defined Table Function (UDTF) written in Python to handle this transformation. Which of the following approaches is the MOST efficient and scalable way to deploy and execute this UDTF in a production Snowpark environment, considering the possibility of high data volumes and concurrency?
Answer: D
Explanation:
Option E is the MOST efficient and scalable. Deploying the UDTF with explicit package management and optimized batch sizing allows Snowflake to distribute the processing across multiple worker nodes, leveraging the platform's parallel processing capabilities. Specifying dependencies using the 'packages' parameter ensures that the required Python libraries are available on each worker node. Properly tuning max_batch_size' prevents memory exhaustion and optimizes processing speed. Options A, C, and D are generally less scalable and efficient due to client-side execution, serial processing, or added external latency. Option B is correct in mentioning batch sizing, but is incomplete. Option E offers the best balance of performance, scalability, and maintainability.
NEW QUESTION # 345
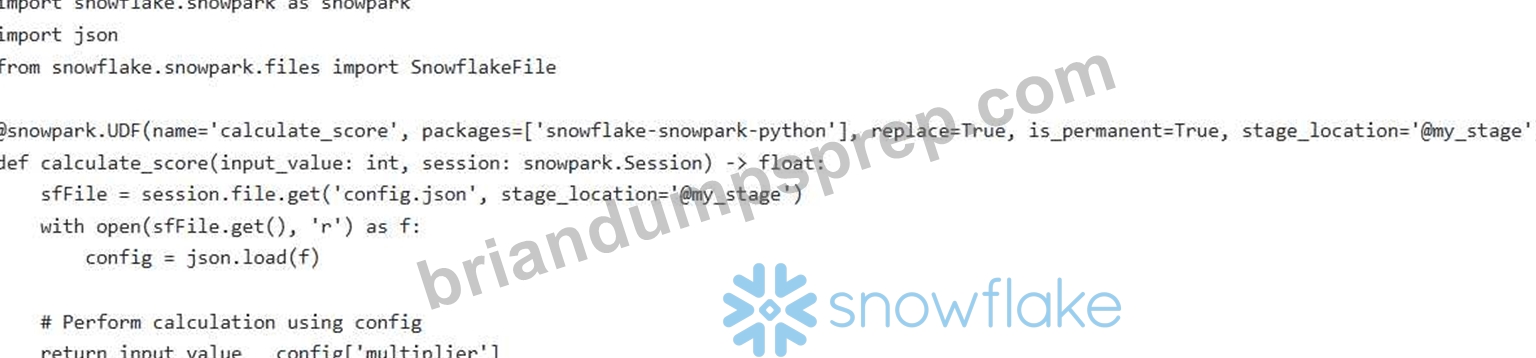
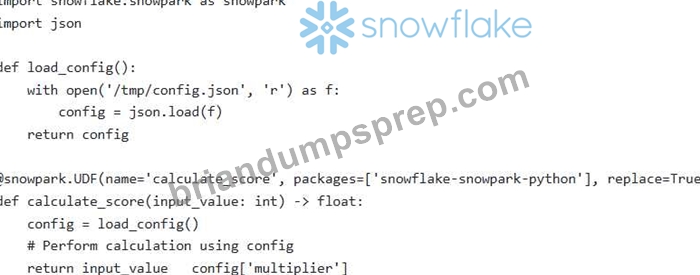
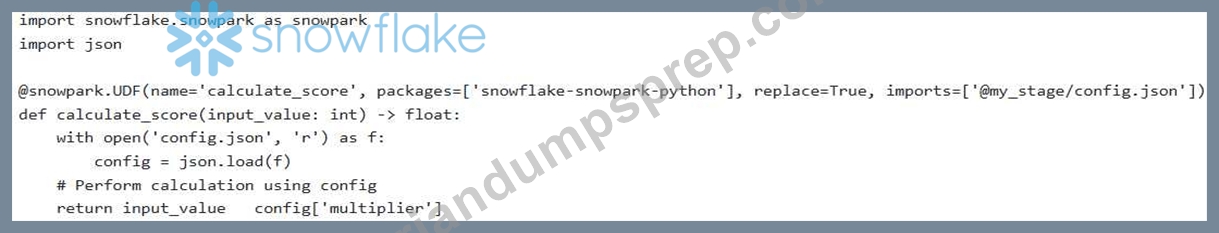
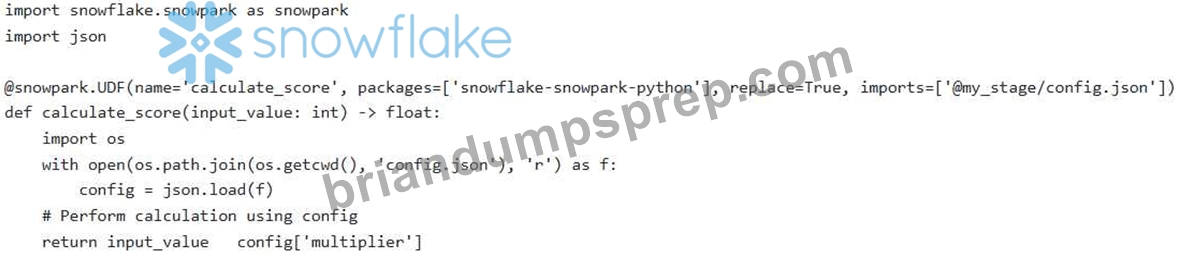
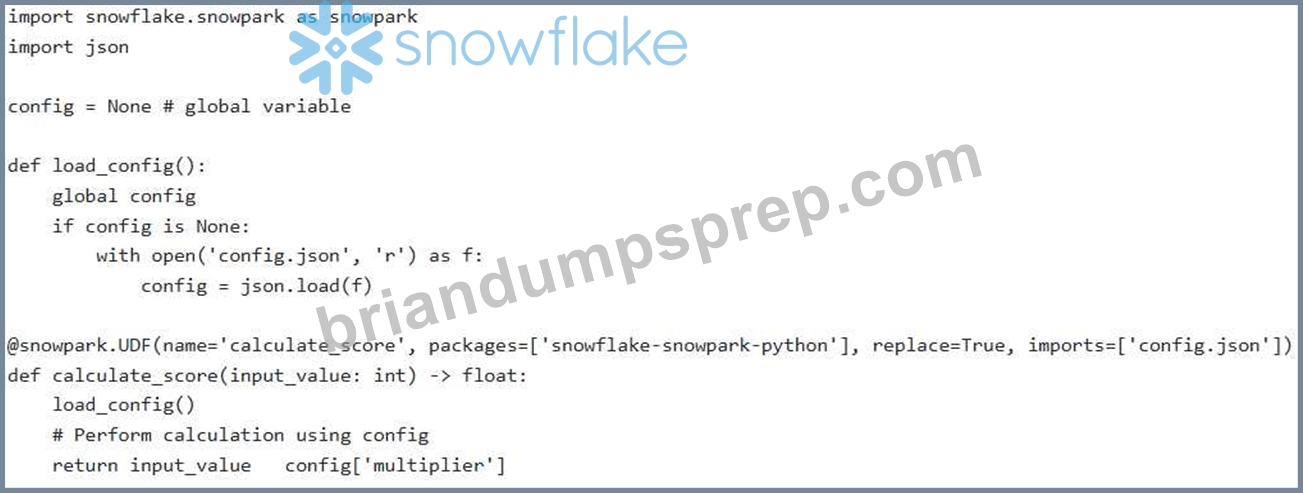
Consider the following Snowpark Python code snippet designed to read data from a Snowflake table, apply a user-defined function (UDF) for data transformation, and then write the transformed data to another table. The UDF, 'calculate_score' , requires a configuration file ('config.json') to be loaded. Which of the following code snippets demonstrates the CORRECT and MOST efficient way to load and access the "config.json' file within the UDF, ensuring that it's available to all UDF invocations without requiring network access?
Answer: C
Explanation:
Option E is the most correct answer, leveraging the 'imports' parameter to efficiently load the 'config.json' file from the specified stage into the UDF's environment. The file is then accessed using a relative path ('config.json'), which is the location where Snowflake places the imported file. Option A is incorrect because it attempts to load from '/tmp/config.json' , which is not accessible within the UDF's environment. Option B is incorrect due to it being Permanent UDF and trying to access the session which are mutually exclusive. In addition , the stage location must be at the time of registration rather than in the UDF definitition, which isn't right. Option C is almost right but incorrect because it accesses file with 'os.path.join(os.getcwd(), 'config.json'Y which is unecessary and wrong. Option D is incorrect because files specified in the 'imports' parameter are available in the current working directory directly, no need to import and declare a global variable
NEW QUESTION # 346
You are tasked with building a Snowpark application that receives a DataFrame 'new customers_df containing customer data'. Your application needs to insert this data into the 'CUSTOMERS' table in Snowflake. The 'CUSTOMERS table has columns 'CUSTOMER ONT), 'NAME' (VARCHAR), and 'JOIN DATE' (DATE). However, contains all columns as VARCHAR. Which of the following approaches ensures the correct data types are inserted into the 'CUSTOMERS' table, minimizing errors and maximizing performance? Assume the 'session' object is already defined and a valid connection exists.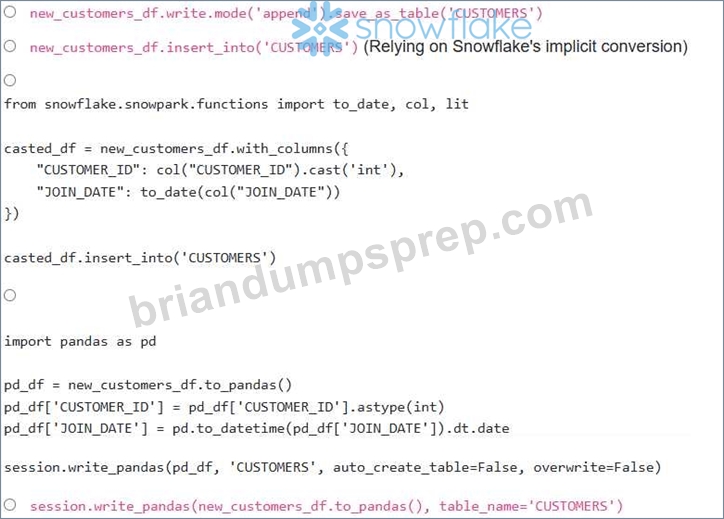
Answer: A
Explanation:
Option C provides explicit casting of the VARCHAR columns to their respective data types (INT and DATE) using Snowpark functions before inserting them into the 'CUSTOMERS' table. This approach ensures data type compatibility and prevents potential errors during the insertion process. Option A, while seemingly simple, might lead to data type mismatch errors if Snowflake cannot implicitly convert the VARCHAR values to INT and DATE. Option B relies on implicit conversion, which is risky. Option D, although it converts to pandas, performs the correct transformations. However, converting to a Pandas DataFrame and using session.write_pandas is less performant and not necessary when using Snowpark. Option E, does not do type conversions and assumes the dataframe is already in required format.
NEW QUESTION # 347
......
The education level of the country has been continuously improved. At present, there are more and more people receiving higher education, and even many college graduates still choose to continue studying in school. Getting the test SPS-C01 certification maybe they need to achieve the goal of the learning process, have been working for the workers, have more qualifications can they provide wider space for development. The SPS-C01 Study Materials can provide them with efficient and convenient learning platform so that they can get the certification as soon as possible in the shortest possible time.
SPS-C01 Test Engine: https://www.briandumpsprep.com/SPS-C01-prep-exam-braindumps.html
BTW, DOWNLOAD part of BraindumpsPrep SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1abJ_u4zhiagqdTvOuWW8XR9PfF9_VqgR