Preparation Material with Free Demos and Updates [2026]

P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1TN7-rz49gQJU-uNuluO6oh8akxIMNG2y
The price for Databricks-Machine-Learning-Professional training materials is quite reasonable, and no matter you are a student at school or an employee in the company, you can afford the expense. You just think that you only need to spend some money, and you can pass the exam and get the certificate, which is quite self-efficient. In addition, Databricks-Machine-Learning-Professional Exam Dumps are edited by the professional experts, who are quite familiar with the professional knowledge and testing center, and the quality and accuracy can be guaranteed. We have 24 hours service stuff, and if you any questions about Databricks-Machine-Learning-Professional training materials, just contact us.
| Topic | Details |
|---|
| Topic 1 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 2 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 3 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 4 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 5 | - Identify live serving benefits of querying precomputed batch predictions
- Describe Structured Streaming as a common processing tool for ETL pipelines
|
| Topic 6 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 7 | - Identify less performant data storage as a solution for other use cases
- Describe why complex business logic must be handled in streaming deployments
|
| Topic 8 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 9 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 10 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 11 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
>> Certificate Databricks-Machine-Learning-Professional Exam <<
Latest Databricks-Machine-Learning-Professional Exam Simulator & Databricks-Machine-Learning-Professional Premium Exam
Pass4suresVCE is a website that can provide all information about different IT certification exam. Pass4suresVCE can provide you with the best and latest exam resources. To choose Pass4suresVCE you can feel at ease to prepare your Databricks Databricks-Machine-Learning-Professional exam. Our training materials can guarantee you 100% to pass Databricks certification Databricks-Machine-Learning-Professional exam, if not, we will give you a full refund and exam practice questions and answers will be updated quickly, but this is almost impossible to happen. Pass4suresVCE can help you pass Databricks Certification Databricks-Machine-Learning-Professional Exam and can also help you in the future about your work. Although there are many ways to help you achieve your purpose, selecting Pass4suresVCE is your wisest choice. Having Pass4suresVCE can make you spend shorter time less money and with greater confidence to pass the exam, and we also provide you with a free one-year after-sales service.
Databricks Certified Machine Learning Professional Sample Questions (Q109-Q114):
NEW QUESTION # 109
A machine learning engineer has found drift in a production machine learning application. The engineer has determined that retraining and deploying a new model is necessary. Which statement must be true prior to deploying the new model?
- A. All of these statements must be true prior to deploying the new model
- B. The now model must perform better than the original model on all of the available data
- C. The new model must perform better than the original model on the most recently available data
- D. The new model must perform better than the original model on a random subset of the available data
Answer: C
Explanation:
When drift is detected, it indicates that the data distribution has changed. Therefore, the new model must perform better than the original model on the most recently available data, as that data reflects current conditions. This ensures the new model is well-adapted to the current environment and will deliver more reliable predictions.
NEW QUESTION # 110
A data scientist has developed a model model and computed the RMSE of the model on the test set. They have assigned this value to the variable rmse. They now want to manually store the RMSE value with the MLflow run.
They write the following incomplete code block:
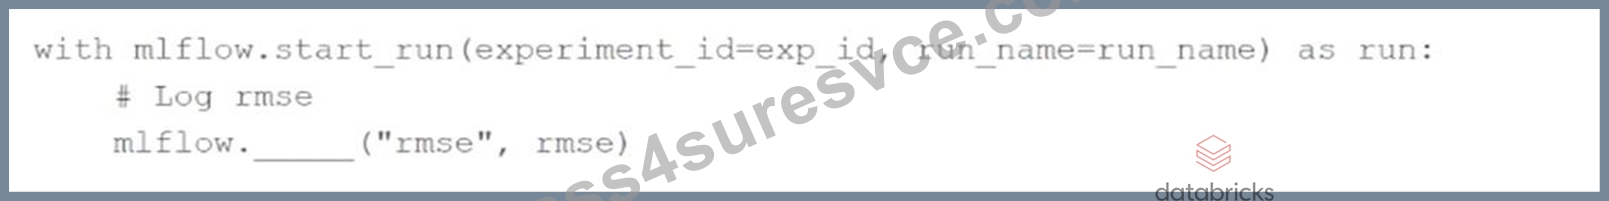
Which of the following lines of code can be used to fill in the blank so the code block can successfully complete the task?
- A. log_param
- B. log_artifact
- C. log_model
- D. log_metric
- E. There is no way to store values like this.
Answer: B
NEW QUESTION # 111
A machine learning engineer needs to deliver predictions of a machine learning model in real- time. However, the feature values needed for computing the predictions are available one week before the query time. Which feature is a benefit of using a batch serving deployment in this scenario rather than a real-time serving deployment where predictions are computed at query time?
- A. There is no advantage to using batch serving deployments over real-time serving deployments
- B. Testing is not possible in real-time serving deployments
- C. Computing predictions in real-time provides more up-to-date results
- D. Querying stored predictions can be faster than computing predictions in real-time
- E. Batch serving has built-in capabilities in Databricks Machine Learning
Answer: E
NEW QUESTION # 112
A data scientist has created a Python function compute_features that returns a Spark DataFrame with the following schema:
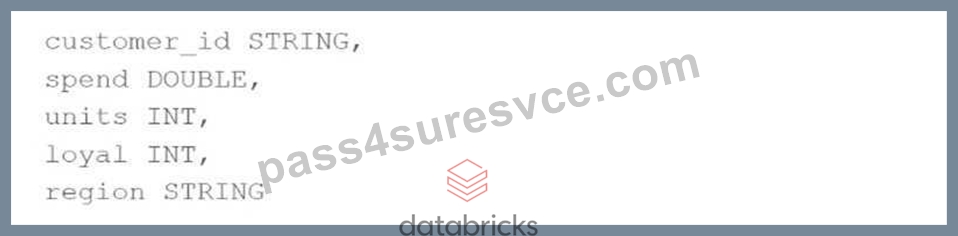
The resulting DataFrame is assigned to the features_df variable. The data scientist wants to create a Feature Store table using features_df.
Which of the following code blocks can they use to create and populate the Feature Store table using the Feature Store Client fs?
- A. features_df.write.mode("fs").path("new_table")
- B.
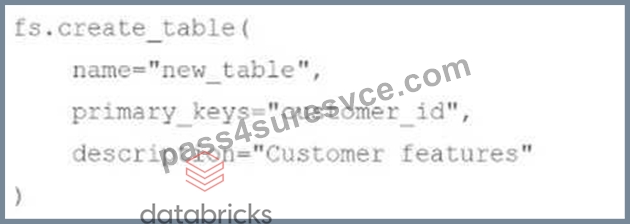
- C.
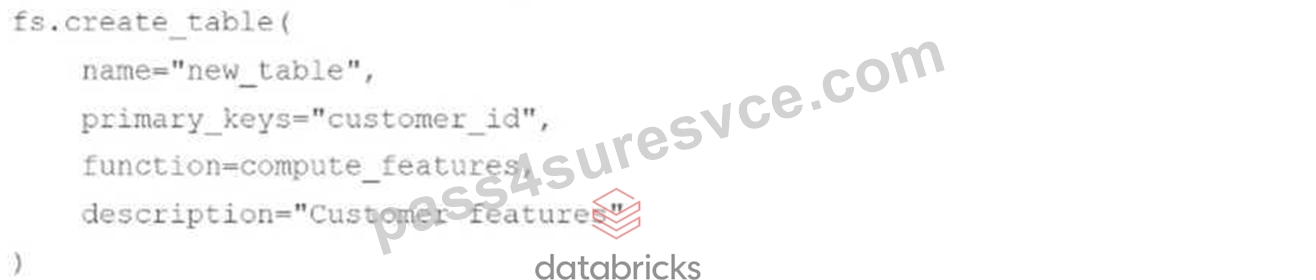
- D. features_df.write.mode("feature").path("new_table")
- E.
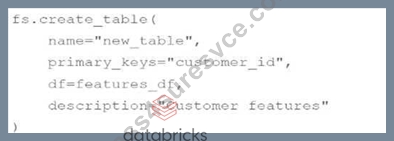
Answer: C
NEW QUESTION # 113
A Machine Learning Engineer needs to deploy a custom model using Databricks Model Serving.
The model requires an external tokenizer file (for example, a vocabulary or pre-trained tokenizer) to function correctly. They need to ensure this tokenizer file is included with the model so it is available during model serving. How should they package this tokenizer file as part of the model deployment?
- A. Use the code_paths parameter in mlflow.pyfunc.log_model() to include the tokenizer file, assuming it's part of the custom Python logic needed by the model.
- B. Include tokenizer file as part of the model's software dependencies by adding it to the conda_env specification.
- C. Use the artifacts parameter in mlflow.pyfunc.log_model() to package the tokenizer file, referencing its path in Volumes.
- D. Access the tokenizer file directly from Volumes at model inference time, which requires pre- provisioning access to the Volume for every model serving endpoint.
Answer: C
Explanation:
The artifacts parameter in mlflow.pyfunc.log_model is designed for packaging non-code assets required at inference time, such as tokenizer files. By logging the tokenizer as a model artifact and referencing its path, MLflow ensures the file is versioned with the model and automatically made available to Databricks Model Serving during inference.
NEW QUESTION # 114
......
It means you can use the Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) PDF version of Pass4suresVCE anywhere at any time on the smart device you have. Our team of professionals continuously updates the collection of Databricks Databricks-Machine-Learning-Professional PDF Questions according to changes in the real test's content. Due to these regular updates, you will get a better experience.
Latest Databricks-Machine-Learning-Professional Exam Simulator: https://www.pass4suresvce.com/Databricks-Machine-Learning-Professional-pass4sure-vce-dumps.html
- Databricks-Machine-Learning-Professional Exam Blueprint 🌀 Databricks-Machine-Learning-Professional Valid Braindumps Files 🔉 Databricks-Machine-Learning-Professional Exam Simulator 💜 Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and download it for free immediately on 【 www.validtorrent.com 】 ❤️Reliable Databricks-Machine-Learning-Professional Mock Test
- Reliable Databricks-Machine-Learning-Professional Exam Review 🗣 Databricks-Machine-Learning-Professional Testking 😆 Valid Databricks-Machine-Learning-Professional Exam Question 🚑 Open 「 www.pdfvce.com 」 and search for ➽ Databricks-Machine-Learning-Professional 🢪 to download exam materials for free 🍺Databricks-Machine-Learning-Professional Exam Simulator
- Databricks-Machine-Learning-Professional Dump Torrent 🔘 Clearer Databricks-Machine-Learning-Professional Explanation ☮ Valid Databricks-Machine-Learning-Professional Exam Question 👵 Easily obtain ➽ Databricks-Machine-Learning-Professional 🢪 for free download through 《 www.torrentvce.com 》 🌌Databricks-Machine-Learning-Professional Exam Collection
- Valid Databricks-Machine-Learning-Professional Test Questions 🖊 Valid Databricks-Machine-Learning-Professional Exam Forum 📭 Vce Databricks-Machine-Learning-Professional File 🦡 Go to website ( www.pdfvce.com ) open and search for “ Databricks-Machine-Learning-Professional ” to download for free 👲Databricks-Machine-Learning-Professional Exam Collection
- Databricks-Machine-Learning-Professional Exam Blueprint 🔶 Clear Databricks-Machine-Learning-Professional Exam 🚰 Vce Databricks-Machine-Learning-Professional File 🍑 ➠ www.practicevce.com 🠰 is best website to obtain 「 Databricks-Machine-Learning-Professional 」 for free download 📓Clear Databricks-Machine-Learning-Professional Exam
- Valid Databricks-Machine-Learning-Professional Exam Forum 🟩 Databricks-Machine-Learning-Professional Valid Braindumps Files 🕰 Vce Databricks-Machine-Learning-Professional File 🍷 Download 《 Databricks-Machine-Learning-Professional 》 for free by simply searching on ➤ www.pdfvce.com ⮘ ⌛Clearer Databricks-Machine-Learning-Professional Explanation
- Databricks-Machine-Learning-Professional Exam Collection ⭐ Databricks-Machine-Learning-Professional Test Collection 📓 Valid Databricks-Machine-Learning-Professional Exam Forum 🍘 Search for ➠ Databricks-Machine-Learning-Professional 🠰 and easily obtain a free download on 「 www.vce4dumps.com 」 ℹVce Databricks-Machine-Learning-Professional File
- Databricks-Machine-Learning-Professional Exam Blueprint 🏂 Vce Databricks-Machine-Learning-Professional File 💸 Databricks-Machine-Learning-Professional Practice Tests 🦪 Search for { Databricks-Machine-Learning-Professional } on ➠ www.pdfvce.com 🠰 immediately to obtain a free download 🦳Databricks-Machine-Learning-Professional Dump Torrent
- Valid Databricks-Machine-Learning-Professional Exam Forum 🙂 New Databricks-Machine-Learning-Professional Study Notes 🕥 New Databricks-Machine-Learning-Professional Study Notes 🚪 Open ⮆ www.pass4test.com ⮄ enter ⮆ Databricks-Machine-Learning-Professional ⮄ and obtain a free download 👨Databricks-Machine-Learning-Professional Testking
- 100% Pass 2026 Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Latest Certificate Exam 💂 Copy URL 《 www.pdfvce.com 》 open and search for 【 Databricks-Machine-Learning-Professional 】 to download for free 😋Exam Databricks-Machine-Learning-Professional Questions Pdf
- Free PDF Quiz Databricks - Efficient Databricks-Machine-Learning-Professional - Certificate Databricks Certified Machine Learning Professional Exam 🦝 Open ➤ www.vce4dumps.com ⮘ enter ✔ Databricks-Machine-Learning-Professional ️✔️ and obtain a free download 🔖Clear Databricks-Machine-Learning-Professional Exam
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.flirtic.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest Pass4suresVCE Databricks-Machine-Learning-Professional PDF Dumps and Databricks-Machine-Learning-Professional Exam Engine Free Share: https://drive.google.com/open?id=1TN7-rz49gQJU-uNuluO6oh8akxIMNG2y