P.S. Free 2026 Nutanix NCP-BC-7.5 dumps are available on Google Drive shared by Itcerttest: https://drive.google.com/open?id=1wfM-TUc4TSCWA5_p20NcjCuYAljlTr7m
You can write down your doubts or any other question of our Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 test questions. We warmly welcome all your questions. Our online workers are responsible for solving all your problems with twenty four hours service. You still can enjoy our considerate service after you have purchased our NCP-BC-7.5 test guide. If you don’t know how to install the study materials, our professional experts can offer you remote installation guidance. Also, we will offer you help in the process of using our NCP-BC-7.5 Exam Questions. Also, if you have better suggestions to utilize our study materials, we will be glad to take it seriously. All of our assistance is free of charge. We are happy that our small assistance can change you a lot. You don’t need to feel burdened. Remember to contact us!
| Section | Weight | Objectives |
|---|---|---|
| Perform BCDR Operational Tasks | 25% | - Execute failover and failback workflows - Migrate legacy protection domains to modern policies - Self-service restore operations - Post-failover cleanup and re-protection - Snapshot-based VM and volume recovery |
| Troubleshoot BCDR Failures | 20% | - Troubleshoot replication and protection policy issues - Resolve misconfigurations in DR environments - Fix third-party backup integration problems - Resolve storage and snapshot errors - Diagnose network-related replication failures |
| Interpret and Configure BCDR Requirements | 30% | - Configure snapshot policies and retention - Create and configure recovery plans - Design secure BCDR environments: segmentation, RBAC, approval policies - Determine prerequisites for BCDR configuration - Configure network and storage for BCDR - Translate business requirements into RPO/RTO objectives - Select replication types: Async, NearSync, Synchronous, Metro |
| Test BCDR Solutions | 25% | - Perform disaster recovery validation procedures - Verify site connectivity and replication throughput - Validate recovery plan execution and outcomes - Execute planned, unplanned, and test failovers |
NCP-BC-7.5 pdf dumps carry real Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) exam questions which are printable. It means candidates can take printed actual questions to any place. Furthermore, the Nutanix Certified Professional - Business Continuity (NCP-BC) 7.5 (NCP-BC-7.5) PDF dumps format is also portable. Therefore, you can access this valid Nutanix NCP-BC-7.5 questions PDF document on tablets, smartphones, and laptops.
NEW QUESTION # 61
After a failover and stabilization of workloads at the recovery AZ, an administrator removes several VMs from the protection policy because they are no longer required. Which action should be performed as part of post-failover cleanup to prevent unnecessary storage consumption?
Answer: D
Explanation:
Post-failover cleanup is a vital operational step to ensure that the environment remains optimized and that resources are not being wasted on workloads that are no longer part of the production environment. When virtual machines are removed from a Protection Policy after a failover, the orchestration engine stops creating new recovery points for them; however, the existing schedule metadata and historical snapshots may still consume space on both the primary and recovery clusters. Reconfiguring the replication schedule (Option B) is the specific task that refreshes the policy ' s state and forces the system to re-evaluate the storage requirements for the remaining entities. This action ensures that the background cleanup processes (managed by Cerebro and Curator) can properly identify and purge the snapshots associated with the removed VMs once their retention period has passed. Failing to reconfigure the schedule or the associated protection policy can leave " orphaned " snapshots in the storage tier, leading to a steady increase in storage utilization over time. By reconfiguring the schedule, the administrator confirms the new steady-state of the DR environment, ensuring that storage is only consumed by the active, required workloads.
NEW QUESTION # 62
An organization has two Nutanix clusters managed by a single Prism Central (PC) instance. They intend to implement Synchronous Replication between the sites. During a failover test, the administrator notices that automatic failover does not occur when the primary site ' s storage becomes unavailable. What is the most likely cause of this behavior based on an analysis of the requirements?
Answer: D
Explanation:
In a Nutanix Synchronous Replication or Metro Availability setup, data is mirrored in real-time, but the " intelligence " required to automate a failover resides outside of the two primary clusters. Without a Witness VM (Option C), the secondary cluster cannot distinguish between a total primary site failure and a simple network partition between the two data centers. If the clusters lose communication but there is no Witness to act as an independent tie-breaker, the secondary cluster will stay in a " Standby " state and will not automatically " promote " its storage to " Active " or power on the VMs. This is a safety mechanism to prevent " split-brain " where two clusters might try to serve the same data, leading to corruption. To enable automatic failover, a Witness VM must be deployed at a third, independent site and registered to both clusters. The Witness allows the secondary site to verify that the primary site has indeed failed; once verified, the Witness grants the " lock " to the secondary site, allowing the automated failover process to begin. Thus, the lack of a Witness is the " most likely cause " for why a failover test would fail to trigger automatically during a storage or site outage.
NEW QUESTION # 63
A third-party backup solution is configured to use Nutanix application-consistent snapshots. Backups are failing for several Windows VMs, although crash-consistent snapshots succeed.
What is the most likely cause of the failure?
Answer: A
Explanation:
Nutanix supports two main types of snapshots: crash-consistent and application-consistent. A crash-consistent snapshot is taken at the storage layer without any awareness of the guest OS state; it is equivalent to pulling the power plug on a server. An application-consistent snapshot is more complex because it requires the Nutanix cluster to " quiesce " the applications (such as SQL Server or Exchange) inside the guest OS, flushing pending writes to disk to ensure data integrity.
To perform this quiescence on Windows VMs, the Nutanix cluster must communicate with the Windows Volume Shadow Copy Service (VSS). This communication is handled exclusively by Nutanix Guest Tools (NGT). If NGT is not installed on the VM, or if the NGT agent is not running/communicating with the cluster, the system cannot trigger the VSS hardware provider. In this situation, any request for an " application- consistent " snapshot from a third-party backup solution will fail because the cluster lacks the necessary hooks into the guest OS. However, a " crash-consistent " snapshot will still succeed because it does not require any guest-level interaction. Therefore, when app-consistent backups fail but crash-consistent ones succeed, the most likely root cause is a missing or broken NGT installation on the affected virtual machines.
NEW QUESTION # 64
An administrator is troubleshooting a hung replication. When checking the replication status, the complete percent and bytes completed do not increase. The administrator checks the Stargate logs on the destination cluster and confirms the writes are failing with " nfs status 28 " . Checking the container info on the destination cluster, free space on the container is 0. The administrator confirms that there is sufficient space available in the storage pool. What could be the reason for free space on the container to be 0?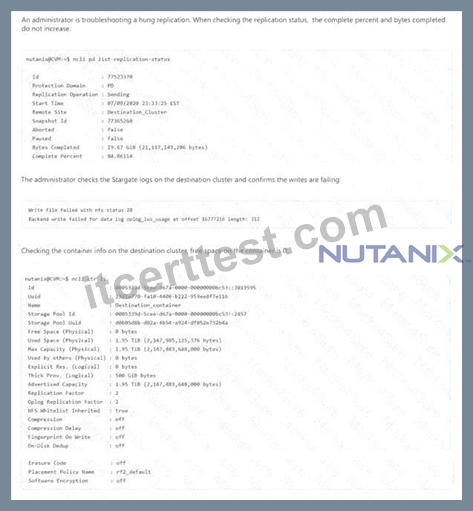
Answer: B
Explanation:
In a Nutanix environment, " Advertised Capacity " is a logical limit (a quota) that an administrator can set on a specific storage container. Even if the physical storage pool has terabytes of free space, if a container ' s advertised capacity is reached, the hypervisor and the Nutanix services will perceive the container as being
100% full.
In this troubleshooting scenario, the " nfs status 28 " error code is a standard indicator for " No space left on device " . Since the administrator confirmed the pool is healthy, the logical limit on the container is the only remaining bottleneck. Replication jobs will " hang " because the destination Stargate service cannot write the incoming data blocks to a container that reports zero free space. To resolve this, the administrator must either increase the advertised capacity value in Prism or remove the limit entirely to allow the container to consume the available physical space in the pool. This highlights a common configuration " trap " where logical quotas-intended for multi-tenant management-can inadvertently block critical BCDR processes like replication if not monitored or sized correctly according to the protected VM growth.
NEW QUESTION # 65
An administrator builds a single recovery plan that includes workloads protected with Asynchronous (async) and Nearsync replication schedules together with workloads protected by Synchronous replication (syncrep) schedules. Which statement is true regarding this configuration?
Answer: D
Explanation:
Nutanix Recovery Plans are designed to orchestrate the failover of complex applications that may consist of multiple virtual machines with different protection requirements. However, there are rules regarding which types of replication schedules can be mixed within a single plan.
Nutanix supports mixing Asynchronous and NearSync replication schedules within the same Recovery Plan.
This is because both Async and NearSync are fundamentally snapshot-based, " passive " recovery models where the system pulls from recovery points stored at the destination cluster. However, the system generally restricts or warns against mixing Synchronous replication with other types in a single orchestrated plan.
Synchronous replication (syncrep) is an " active-active " or " stretched " model that behaves differently during a failover compared to snapshot-based models. In some software versions, including entities protected by synchronous schedules with those on async/nearsync within a single plan can cause the failover task to fail validation because the orchestration logic for zero-RPO failover is distinct from snapshot restoration.
Therefore, while mixing Async and NearSync is a supported and common practice, administrators must be cautious with Synchronous workloads.
NEW QUESTION # 66
......
Itcerttest Nutanix NCP-BC-7.5 Practice Test dumps can help you pass IT certification exam in a relaxed manner. In addition, if you first take the exam, you can use software version dumps. Because the SOFT version questions and answers completely simulate the actual exam. You can experience the feeling in the actual test in advance so that you will not feel anxious in the real exam. After you use the SOFT version, you can take your exam in a relaxed attitude which is beneficial to play your normal level.
NCP-BC-7.5 Best Practice: https://www.itcerttest.com/NCP-BC-7.5_braindumps.html
What's more, part of that Itcerttest NCP-BC-7.5 dumps now are free: https://drive.google.com/open?id=1wfM-TUc4TSCWA5_p20NcjCuYAljlTr7m