Thousands of Designing and Implementing Multi-Agent AI Solutions (AI-500) exam applicants are satisfied with our AI-500 practice test material because it is according to the latest Designing and Implementing Multi-Agent AI Solutions (AI-500) exam syllabus and we also offer up to 1 year of free Microsoft Dumps updates. Visitors of Test4Engine can check the Designing and Implementing Multi-Agent AI Solutions (AI-500) product by trying a free demo. Buy the AI-500 test preparation material now and start your journey towards success in the Designing and Implementing Multi-Agent AI Solutions (AI-500) examination.
| Section | Weight | Objectives |
|---|---|---|
| Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
| Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Implement observability
|
| Secure, govern, and deploy multi-agent solutions | 20–25% | - Deploy and maintain solutions
|
>> Reliable AI-500 Exam Topics <<
If you also need to take the AI-500 exam and want to get the related certification, you can directly select our study materials. We can promise that our AI-500 study question has a higher quality than other study materials in the market. If you want to keep making progress and transcending yourself, we believe that you will harvest happiness and growth. So if you buy and use the AI-500 test dump from our company, we believe that our study materials will make study more interesting and colorful, and it will be very easy for a lot of people to pass their exam and get the related certification if they choose our AI-500 Test Dump and take it into consideration seriously. Now we are willing to introduce the AI-500 exam reference guide from our company to you in order to let you have a deep understanding of our study materials. We believe that you will benefit a lot from our AI-500 study question.
NEW QUESTION # 24
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
Answer: B
NEW QUESTION # 25
You have a Microsoft Foundry agent that handles customer support chats. The agent has two tools named get_contract_terms and calculate_refund.
On turns where refunds must be calculated, the agent inconsistently calls the tools.
You need to reliably force refund-estimate turns to call calculate_refund.
Which request configuration should you use?
Answer: C
Explanation:
The requirement is to force one specific tool, `calculate_refund`, whenever the application determines that a refund estimate is required. A named function in `tool_choice` removes ambiguity by directing the model to invoke that exact function. `tool_choice: " auto " ` allows the model to decide whether to call a tool and which tool to use. `tool_choice: " required " ` forces some tool call but does not guarantee that `calculate_refund` is selected when multiple tools are available. A natural-language instruction remains probabilistic and is not equivalent to an API-level enforcement setting. Microsoft ' s function-calling API documents named tool choice as the deterministic way to force a specific function. Therefore A is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure OpenAI - Function calling and tool choice
NEW QUESTION # 26
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
Answer: C
Explanation:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
NEW QUESTION # 27
You have a Microsoft Foundry agent built by using LangGraph. The agent retrieves policy content from a vector store. The LangGraph orchestration runs in Azure Container Apps, and the operations team uses Azure Monitor to inspect agent runs.
You discover that the vector store is sometimes unreachable during Azure regional maintenance windows You need to configure the tool ecosystem to ensure that the agent can answer policy questions during outages The solution must meet the following requirements:
* Use the project vector store without adding a local retrieval node for the primary path.
* Run the cached-policy lookup in the same compute environment as the LangGraph code.
* Emit agent, model, and tool spans that can be inspected in Azure Monitor How should you configure the tool ecosystem? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.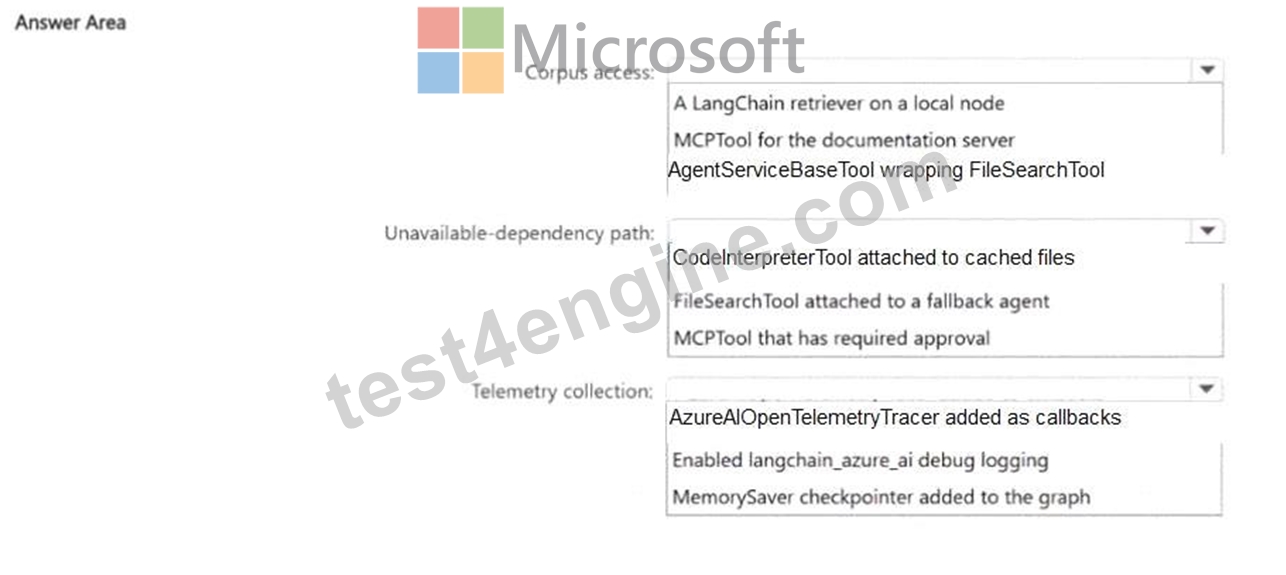
Answer:
Explanation: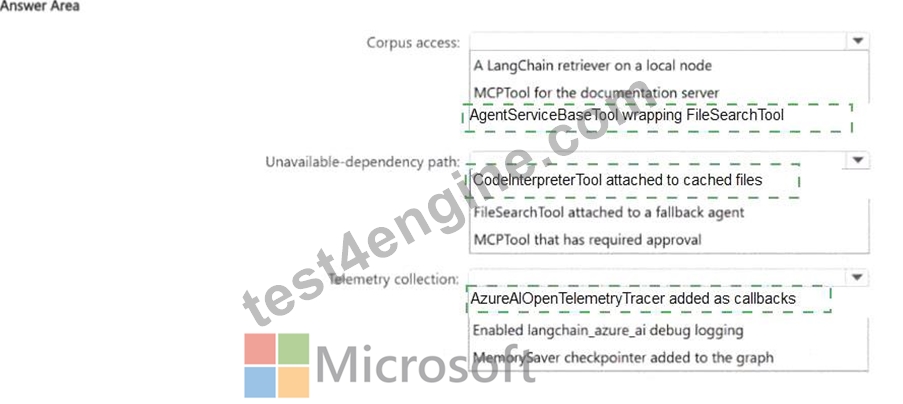
Explanation:
Corpus access: AgentServiceBaseTool wrapping FileSearchTool; Outage fallback: No listed option fully satisfies the requirement to run the cached-policy lookup in the same Azure Container Apps compute; Telemetry: AzureAIOpenTelemetryTracer added as callbacks.
Current Microsoft LangGraph integration guidance supports wrapping Foundry ' s FileSearchTool through AgentServiceBaseTool for the primary project-vector-store path and attaching AzureAIOpenTelemetryTracer through LangGraph callbacks for OpenTelemetry traces. The problematic part is the proposed outage fallback. Code Interpreter is a Foundry-hosted built-in tool, so it does not execute in the same Azure Container Apps compute environment as the LangGraph application. That means a CodeInterpreterTool- based fallback cannot satisfy the explicit same-compute requirement. A technically correct design would use a local LangGraph/LangChain callable or tool over cached policy content mounted or stored with the Container Apps workload. Because that local-tool option is absent from the answer set, there is no fully valid listed selection for the fallback row. The updated answer therefore preserves the two valid selections and explicitly identifies the missing valid option rather than endorsing an inconsistent one. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Foundry - develop LangChain/LangGraph agents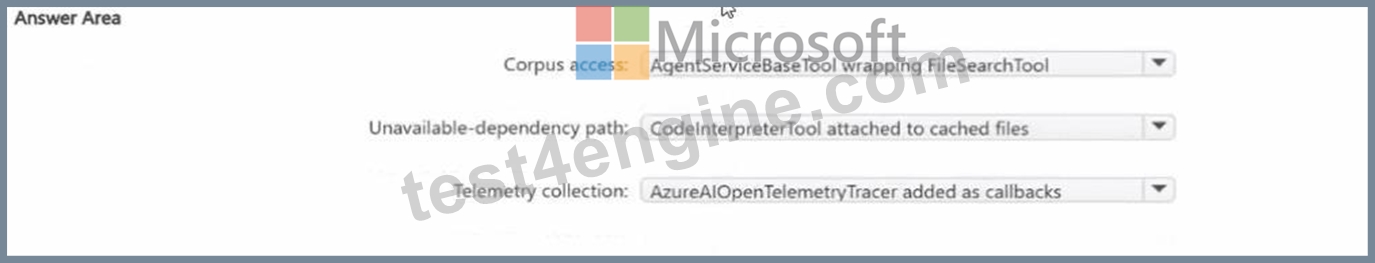
NEW QUESTION # 28
You have a Microsoft Foundry multi-agent solution that includes a orchestrator and agents named Agent1 and Agent2. The solution has the following characteristics:
* The orchestrator routes tasks to both agents.
* The agents invoice Model Context Protocol (MCP)-hosted tools.
* Agent? sends model-generated JSON parameters directly to tool endpoints.
* The agents use a shared managed identity that has contributor access to the resource group that contains the tool-backed Azure resources.
You need to implement a guardrail strategy for tool calls. The solution must meet the following requirements:
* Prevent invalid or out-of-range tool parameters from reaching the tool endpoints.
* Scope each agent ' s permissions to its assigned tools
* Limit Agent? to refund-processing tools only.
* Log tool invocations for audit purposes.
What should you do?
Answer: B
Explanation:
The solution needs deterministic validation before model-generated tool arguments reach MCP endpoints, per- agent authorization boundaries, tool scoping, and audit logging. Validating typed payload schemas at the tool boundary prevents malformed or out-of-range arguments before execution, which is stronger than validating outputs after a tool has already run. Per-agent managed identities and scoped RBAC roles reduce lateral movement and contain the impact of a compromised agent. A per-agent tool-access policy also ensures the refund-focused agent cannot invoke unrelated tools. Finally, Azure Monitor/trace logging provides an auditable record of tool invocations. A2A capability cards describe remote-agent capabilities rather than validate tool arguments. System instructions are not an authorization boundary, and shared Contributor access leaves an excessive blast radius. Option D is therefore the only answer that satisfies all four requirements at enforceable platform boundaries. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: AI-500 Study Guide - tool scopes, permission boundaries, and auditing
NEW QUESTION # 29
......
Test4Engine Microsoft AI-500 Practice Test dumps are doubtless the best reference materials compared with other AI-500 exam related materials. If you still don't believe it, come on and experience it and then you will know what I was telling you was true. You can visit Test4Engine.com to download our free demo. There are two versions of Test4Engine dumps. The one is PDF version and another is SOFT version. You can experience it in advance. In this, you can check its quality for yourself.
AI-500 Accurate Prep Material: https://www.test4engine.com/AI-500_exam-latest-braindumps.html