We now live in a world which needs the talents who can combine the practical abilities and knowledge to apply their knowledge into the practical working conditions. To prove that you are that kind of talents you must boost some authorized and useful certificate and the test DP-750 certificate is one kind of these certificate. Most important of all, as long as we have compiled a new version of the DP-750 Exam Questions, we will send the latest version of our DP-750 exam questions to our customers for free during the whole year after purchasing. Our product can improve your stocks of knowledge and your abilities in some area and help you gain the success in your career.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 3: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
>> Reliable Microsoft DP-750 Test Online <<
The Getcertkey offers latest Implementing Data Engineering Solutions Using Azure Databricks DP-750 exam questions and answers, with Microsoft DP-750 exam practice test questions you can ace your Microsoft DP-750 exam preparation simply and quickly and pass the final DP-750 Exam easily. The Microsoft DP-750 exam practice test questions will assist you in Microsoft DP-750 exam preparation.
NEW QUESTION # 32
You have an Azure Databricks workspace.
Users report that a Databricks notebook that runs each day takes longer than expected to run.
When reading the Directed Acyclic Graph (DAG), you discover the following issues concerning the Apache Spark stage:
* Most tasks in the stage finish quickly.
* A few tasks in the stage run more slowly.
* The CPU is underutilized at the end of the stage.
* The slow tasks process many more input records.
* The stage is blocked while it waits for the few slow tasks.
What is the root cause of the issues?
Answer: B
Explanation:
The symptoms indicate data skew. Spark partitions the stage's work into tasks, but a few partitions contain substantially more records than the others. Tasks processing the smaller partitions finish quickly, leaving the cluster underutilized while the stage waits for the oversized partitions. Caching would concern whether reused data is stored in memory and does not inherently explain an uneven distribution of input records. Shuffling transfers data between executors and can be expensive, but the decisive evidence is that only a few tasks process far more records. Spilling occurs when an executor cannot keep intermediate data in memory and writes it to disk; the scenario does not identify high spill volumes. Examining per-task input sizes in the Spark UI would confirm the skewed partition distribution.
NEW QUESTION # 33
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to create a job in Lakeflow Jobs named Job1 that:
* Ingests data from cloud storage
* Runs two independent transformation tasks
The transformation tasks must run only after the ingestion completes and must run in parallel.
You need to design the task logic for Job1.
What should you configure?
Answer: B
Explanation:
Job1 should contain one ingestion task that acts as the common upstream dependency for two separate transformation tasks. Once ingestion succeeds, Lakeflow Jobs can start both downstream tasks concurrently because neither transformation depends on the other. This design represents the actual workflow, avoids duplicated ingestion, and reduces total execution time through parallelism. Creating two ingestion tasks would repeat the same source processing and could introduce inconsistent results or unnecessary costs. A single sequential task would prevent parallel transformation and make failures harder to isolate and retry. Defining three independent tasks without dependencies could allow transformations to start before ingestion has completed. An explicit directed task graph therefore provides the required execution order while preserving parallelism for independent downstream processing.
NEW QUESTION # 34
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: D
Explanation:
The correct answer is C - the Databricks CLI.
Databricks Asset Bundles are deployed using the Databricks CLI (v0.205+) with the commands databricks bundle validate, databricks bundle deploy, and databricks bundle run. The CLI reads the databricks.yml file, resolves the target environment settings, and creates or updates all declared resources (jobs, pipelines, apps) in the workspace. This is the documented, supported deployment mechanism for DABs and integrates naturally into CI/CD pipelines.
Option A (Azure Developer CLI / azd) is a general Azure IaC tool with no native understanding of Databricks bundles. Option B (Git folders) syncs notebook and file content from a Git repository into a workspace - useful for code, but it doesn't deploy Lakeflow Jobs, SDP pipelines, or bundle configurations. Option D (Azure CLI) manages Azure infrastructure (resource groups, storage accounts, etc.) and has no native DAB deployment support.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deploy-bundle
NEW QUESTION # 35
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.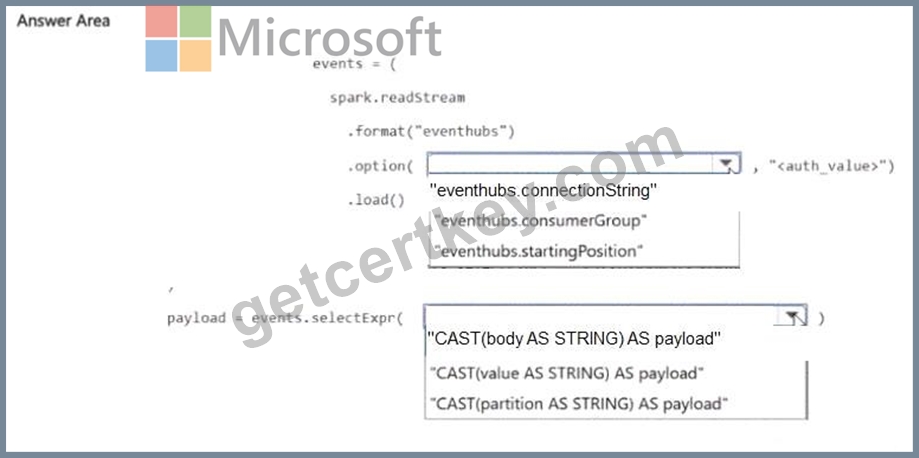
Answer:
Explanation: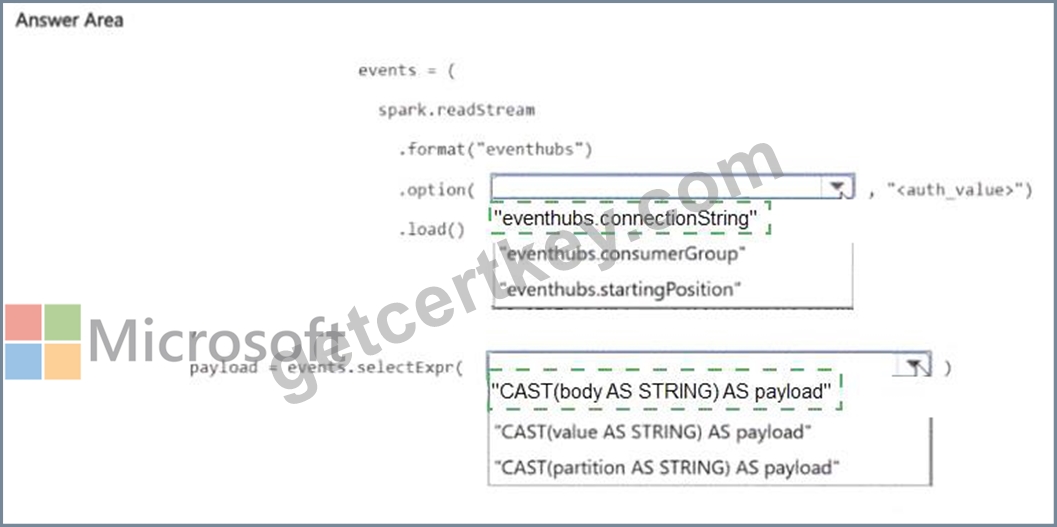
Explanation:
Reading from Azure Event Hubs in Spark Structured Streaming requires three things:
An EventHubsConf object built with the Event Hubs connection string (eventhubs.connectionString). This object is then converted to a map with .toMap before being passed to Spark.
spark.readStream.format( ' eventhubs ' ).options(**ehConf).load() to create the streaming DataFrame. The ' eventhubs ' format is provided by the azure-eventhubs-spark connector library.
A cast( ' string ' ) on the body column to decode the binary payload. Event Hubs delivers messages with the raw event bytes in a column called body - without the cast, you get binary data rather than the readable JSON or text payload.
This is the standard, documented integration pattern for connecting Azure Databricks to Event Hubs with Structured Streaming, providing the checkpoint-based exactly-once semantics required by the Contoso telemetry pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/storage/events/eventhubs
NEW QUESTION # 36
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.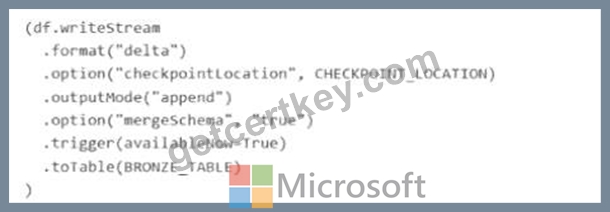
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.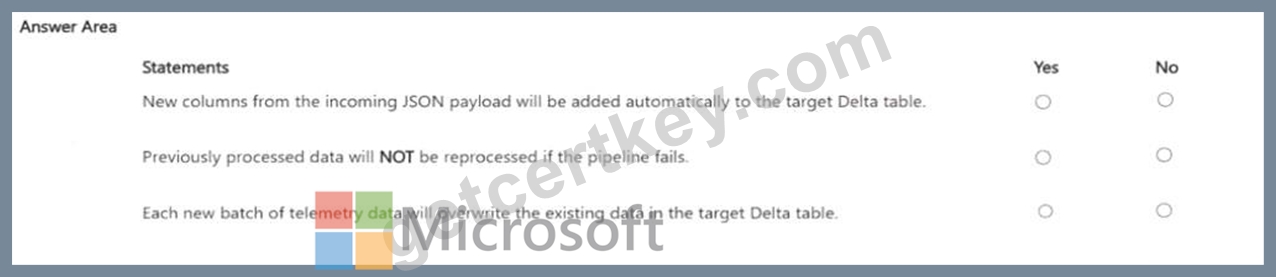
Answer:
Explanation: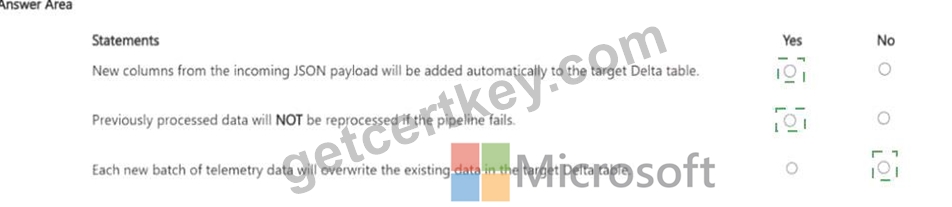
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 37
......
If you purchase DP-750 exam questions and review it as required, you will be bound to successfully pass the exam. And if you still don't believe what we are saying, you can log on our platform right now and get a trial version of DP-750 study engine for free to experience the magic of it. Of course, if you encounter any problems during free trialing, feel free to contact us and we will help you to solve all problems on the DP-750 practice engine.
DP-750 Valid Vce Dumps: https://www.getcertkey.com/DP-750_braindumps.html