What's more, part of that SurePassExams Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1tjqu8OCj9y8QGO6rKX3anibd80Q6qk--
SurePassExams's providing training material is very close to the content of the formal examination. Through our short-term special training You can quickly grasp IT professional knowledge, and then have a good preparation for your exam. We promise that we will do our best to help you pass the Google Certification Professional-Machine-Learning-Engineer Exam.
Google Professional Machine Learning Engineer Certification Exam consists of multiple-choice questions and performance-based scenarios that test your ability to design and implement machine learning models on the Google Cloud Platform. Professional-Machine-Learning-Engineer Exam covers a wide range of topics, including data preparation, model training and evaluation, and deployment of machine learning models in a production environment.
>> Exam Professional-Machine-Learning-Engineer Reference <<
We always learned then forget, how to solve this problem, the answer is to have a good memory method, our Professional-Machine-Learning-Engineer exam question will do well on this point. Our Professional-Machine-Learning-Engineer real exam materials have their own unique learning method, abandon the traditional rote learning, adopt diversified memory patterns, such as the combination of text and graphics memory method, to distinguish between the memory of knowledge. Our Professional-Machine-Learning-Engineer learning reference files are so scientific and reasonable that you can buy them safely.
Google Professional Machine Learning Engineer Certification Exam is a professional certification that is designed to test an individual's proficiency in designing, building, and deploying machine learning models on the Google Cloud Platform. Google Professional Machine Learning Engineer certification is intended for individuals who have a thorough understanding of machine learning principles and experience with the Google Cloud Platform. Professional-Machine-Learning-Engineer exam is designed to test an individual's ability to analyze and interpret data, design machine learning models, train and optimize models, and deploy models into production.
Google Professional Machine Learning Engineer Certification Exam is a challenging and rewarding test that requires a deep understanding of machine learning principles and their practical application. Professional-Machine-Learning-Engineer Exam is designed to test the candidate's ability to design, implement, and deploy machine learning models using Google Cloud Platform. It covers a broad range of topics, including data preprocessing, model training, hyperparameter tuning, and model evaluation.
NEW QUESTION # 49
You want to migrate a scikrt-learn classifier model to TensorFlow. You plan to train the TensorFlow classifier model using the same training set that was used to train the scikit-learn model and then compare the performances using a common test set. You want to use the Vertex Al Python SDK to manually log the evaluation metrics of each model and compare them based on their F1 scores and confusion matrices. How should you log the metrics?




Answer: A
NEW QUESTION # 50
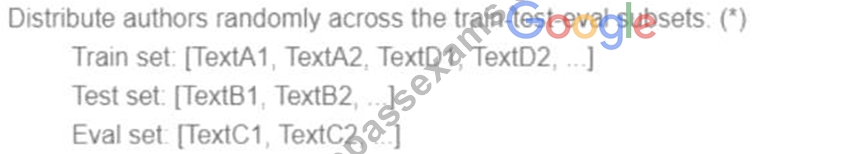
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: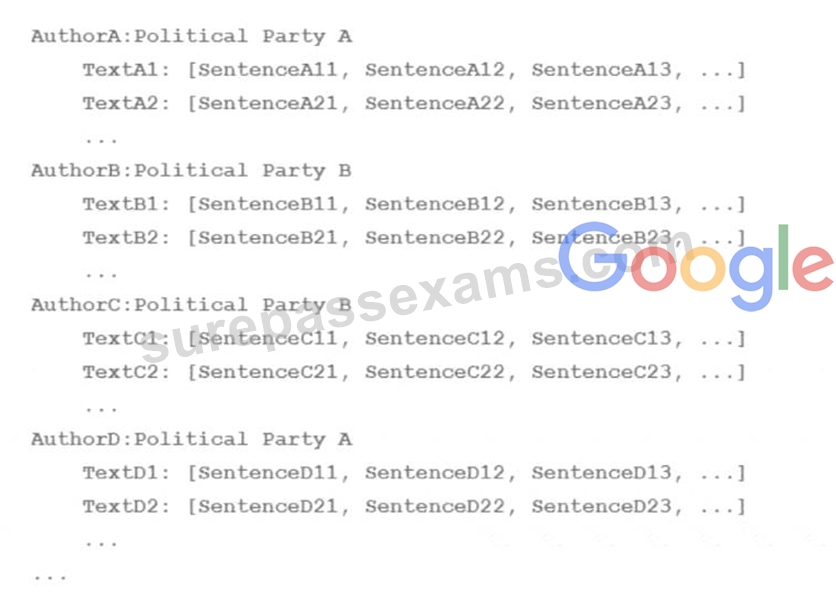
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets.
How should you distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion?
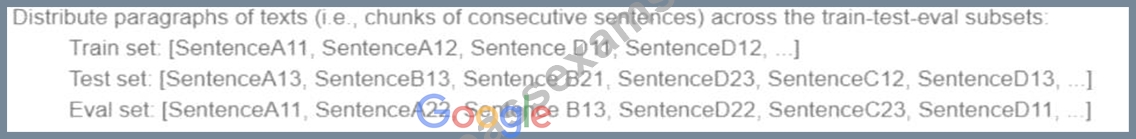
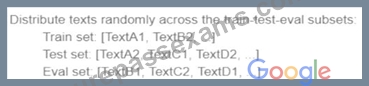
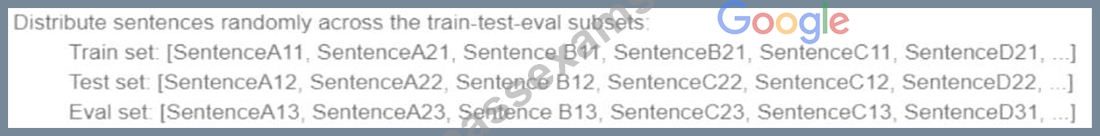
Answer: C
Explanation:
The best way to distribute the training examples across the train-test-eval subsets while maintaining the
80-10-10 proportion is to use option C. This option ensures that each subset contains a balanced and representative sample of the different classes (Democrat and Republican) and the different authors. This way, the model can learn from a diverse and comprehensive set of articles and avoid overfitting or underfitting.
Option C also avoids the problem of data leakage, which occurs when the same author appears in more than one subset, potentially biasing the model and inflating its performance. Therefore, option C is the most suitable technique for this use case.
NEW QUESTION # 51
You are developing a mode! to detect fraudulent credit card transactions. You need to prioritize detection because missing even one fraudulent transaction could severely impact the credit card holder. You used AutoML to tram a model on users ' profile information and credit card transaction data. After training the initial model, you notice that the model is failing to detect many fraudulent transactions. How should you adjust the training parameters in AutoML to improve model performance?
Choose 2 answers
Answer: A,D
Explanation:
The best options for adjusting the training parameters in AutoML to improve model performance are to decrease the score threshold and add more positive examples to the training set. These options can help increase the detection rate of fraudulent transactions, which is the priority for this use case. The score threshold is a parameter that determines the minimum probability score that a prediction must have to be classified as positive. Decreasing the score threshold can increase the recall of the model, which is the proportion of actual positive cases that are correctly identified. Increasing the recall can help reduce the number of false negatives, which are fraudulent transactions that are missed by the model. However, decreasing the score threshold can also decrease the precision of the model, which is the proportion of positive predictions that are actually correct. Decreasing the precision can increase the number of false positives, which are legitimate transactions that are flagged as fraudulent by the model. Therefore, there is a trade-off between recall and precision, and the optimal score threshold depends on the business objective and the cost of errors 1 . Adding more positive examples to the training set can help balance the data distribution and improve the model performance. Positive examples are the instances that belong to the target class, which in this case are fraudulent transactions. Negative examples are the instances that belong to the other class, which in this case are legitimate transactions. Fraudulent transactions are usually rare and imbalanced compared to legitimate transactions, which can cause the model to be biased towards the majority class and fail to learn the characteristics of the minority class. Adding more positive examples can help the model learn more features and patterns of the fraudulent transactions, and increase the detection rate 2 .
The other options are not as good as options B and C, for the following reasons:
* Option A: Increasing the score threshold would decrease the detection rate of fraudulent transactions, which is the opposite of the desired outcome. Increasing the score threshold would decrease the recall of the model, which is the proportion of actual positive cases that are correctly identified. Decreasing the recall would increase the number of false negatives, which are fraudulent transactions that are missed by the model. Increasing the score threshold would increase the precision of the model, which is the proportion of positive predictions that are actually correct. Increasing the precision would decrease the number of false positives, which are legitimate transactions that are flagged as fraudulent by the model. However, in this use case, the cost of false negatives is much higher than the cost of false positives, so increasing the score threshold is not a good option 1 .
* Option D: Adding more negative examples to the training set would not improve the model performance, and could worsen the data imbalance. Negative examples are the instances that belong to the other class, which in this case are legitimate transactions. Legitimate transactions are usually abundant and dominant compared to fraudulent transactions, which can cause the model to be biased towards the majority class and fail to learn the characteristics of the minority class. Adding more negative examples would exacerbate th is problem, and decrease the detection rate of the fraudulent transactions 2 .
* Option E: Reducing the maximum number of node hours for training would not improve the model performance, and could limit the model optimization. Node hours are the units of computation that are used to train an AutoML model. The maximum number of node hours is a parameter that determines the upper limit of node hours that can be used for training. Reducing the maximum number of node hours would reduce the training time and cost, but also the model quality and accuracy. Reducing the maximum number of node hours wo uld limit the number of iterations, trials, and evaluations that the model can perform, and prevent the model from finding the optimal hyperparameters and architecture 3 .
References:
Preparing for Google Cloud Certification: Machine Learning Engineer , Course 5: Responsible AI, Week 4:
Evaluation
Google Cloud Professional Machine Learning Engineer Exam Guide , Section 2: Developing high-quality ML models, 2.2 Handling imbalanced data Official Google Cloud Certified Professional Machine Learning Engineer Study Guide, Chapter 4: Low-code ML Solutions, Section 4.3: AutoML Understanding the score threshold slider Handling imbalanced data sets in machine learning AutoML Vision pricing
NEW QUESTION # 52
You have created a Vertex Al pipeline that includes two steps. The first step preprocesses 10 TB data completes in about 1 hour, and saves the result in a Cloud Storage bucket The second step uses the processed data to train a model You need to update the model's code to allow you to test different algorithms You want to reduce pipeline execution time and cost, while also minimizing pipeline changes What should you do?
Answer: B
NEW QUESTION # 53
Your team trained and tested a DNN regression model with good results. Six months after deployment, the model is performing poorly due to a change in the distribution of the input dat a. How should you address the input differences in production?
Answer: B
NEW QUESTION # 54
......
Professional-Machine-Learning-Engineer Valid Practice Materials: https://www.surepassexams.com/Professional-Machine-Learning-Engineer-exam-bootcamp.html
What's more, part of that SurePassExams Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1tjqu8OCj9y8QGO6rKX3anibd80Q6qk--