AI-103試験は難しいです。だから、AI-103復習教材を買いました。本当に助かりました。先月、AI-103試験に参加しました。今日は、試験の結果をチエックし、嬉しいことに、AI-103試験に合格しました。AI-103復習教材は有効的な資料です。
| Section | Weight | Objectives |
|---|---|---|
| Plan and manage Azure AI solutions | 25–30% | - Manage AI solution development lifecycle
|
| Implement text and speech analysis solutions | 10–15% | - Implement natural language processing
|
| Implement computer vision solutions | 10–15% | - Build multimodal solutions
|
| Implement generative AI and agentic solutions | 30–35% | - Design and implement intelligent agents
|
| Implement information extraction and knowledge mining | 10–15% | - Extract structured data from documents
|
>> Microsoft AI-103日本語版試験解答 <<
もしあなたはIT業種でもっと勉強になりたいなら、Jpshikenを選んだ方が良いです。JpshikenのMicrosoftのAI-103試験トレーニング資料は豊富な経験を持っている専門家が長年の研究を通じて開発されたものです。それは正確性が高くて、カバー率も広いです。JpshikenのMicrosoftのAI-103試験トレーニング資料を手に入れたら、成功に導く鍵を手に入れるのに等しいです。
質問 # 72
You are building a customer support web app named App1 in Microsoft Foundry that uses a GPT realtime model.
App1 must support:
- Live, low-latency voice conversations that use Azure OpenAI
- Streaming audio input from users and playback audio responses
You need to configure a connection method that supports real-time audio streaming in client application and targets approximately 100 ms latency.
Which connection method should you use?
正解:D
解説:
WebSockets is the best connection method for this application because it enables full-duplex, bi- directional streaming over a single TCP connection, meeting the strict ~100 ms latency requirement for real-time audio.
Reference:
https://www.chat-data.com/blog/implement-openai-realtime-api-for-chatgpt-voice
質問 # 73
You have an Azure AI agent solution.
You plan to create an agent-based app named App1 that will analyze and summarize data for users and generate data-driven recommendations. App1 will be used by non-technical business users and must adapt to new and unforeseen business challenges and improve its performance over time.
You need to identity which type of agent to use in App1. The solution must meet the following requirements:
- Adapt and improve the agents' performance over time based on user
feedback.
- Provide tailored recommendations to help users make informed
decisions.
- Provide the best possible performance of the app.
Which agent type should you identify?
正解:C
解説:
A cognitive agent is designed to mimic human thought processes, making it ideal for the complex, data-driven tasks described in the query.
Analyze and summarize data and generate data-driven recommendations:
Cognitive agents use machine learning and natural language processing to analyze historical data and act on their learnings, which includes generating insights and recommendations.
Adapt and improve over time based on user feedback:
They are designed to learn and adapt to user behavior and preferences over time, improving their responses and performance through feedback.
Used by non-technical business users:
These agents can be accessed through user-friendly interfaces, often natural language-based (like virtual assistants), making them suitable for non-technical users.
Provide tailored recommendations to help users make informed decisions:
By learning from data and interactions, they can deliver personalized recommendations that support better decision-making.
質問 # 74
You have an application named App1 that uses Azure Speech in Foundry Tools to transcribe live calls.
Transcript segments often contain both English and Spanish. App1 sends each segment to Azure Translator in Foundry Tools to translate to another language.
Sometimes, mixed-language segments result in incomplete or incorrect translations.
You need to reduce translation errors. The solution must ensure that the entire transcript is translated successfully.
What should you do before sending the segments to Translator?
正解:D
解説:
To fix incomplete or incorrect translations from mixed-language transcripts, you must identify and isolate the languages at the sentence or phrase level before sending the text to Azure Translator.
Azure Translator performs best when a single request contains only one source language. When it receives a mixed-language segment under a single source language code, it often fails to parse the secondary language correctly.
Here is the step-by-step pipeline you should implement inside your application before hitting the Translator API.
1. Split Segments into Sentences
Live call transcript segments can contain multiple sentences. Do not send the raw, multi-sentence segment directly to the translator if it contains mixed languages.Break the segment into individual sentences.Use regex punctuation rules or a lightweight sentence-splitting library.
2. Run Language Detection Per Sentence
Azure Translator has a built-in Detect API, but for mixed-language live calls, executing a dedicated detection step per sentence provides better control.
Reference:
https://medium.com/neural-engineer/azure-ai-speech-to-text-real-time-transcription-58bfd5fd1a28
質問 # 75
You have a Microsoft Foundry project that contains an agent.
The agent ingests scanned PDF vendor invoices that contain tables and embedded QR codes.
The agent must preserve the PDF layout in the extracted output to ensure that downstream processing can reference sections and tables.
You plan to call Azure Content Understanding in Foundry Tools.
You need to extract content and layout elements and detect QR codes without requiring a language model deployment.
Which built-in analyzer should you use?
正解:C
解説:
The correct built-in analyzer is prebuilt-layout because the requirement is to preserve document layout while extracting content from scanned PDFs. Microsoft's Content Understanding prebuilt analyzer guidance states that prebuilt-layout extracts content and layout elements such as words, figures, paragraphs, and tables, identifies document structure including sections and formatting, and provides detailed layout information beyond basic text extraction. It also states that prebuilt-layout does not require a language model or embedding model, which directly satisfies the no language model deployment requirement.
QR codes are handled through barcode extraction. The analyzer configuration reference states that enableBarcode detects and extracts barcodes and QR codes, returns decoded values, and supports QR Code and Micro QR Code among other barcode types. This option is supported by document-based analyzers, making it compatible with layout-oriented document processing.
prebuilt-read is insufficient because it provides OCR and barcode extraction but foundational text extraction without layout analysis. prebuilt-documentSearch is optimized for RAG ingestion and semantic analysis, which is broader than required. prebuilt-documentFieldSchema proposes extraction schemas rather than extracting full document layout. Reference topics: Content Understanding prebuilt analyzers, layout analysis, OCR, barcode detection, QR code extraction, and document-based analyzers.
質問 # 76
Hotspot Question
You have a Python application named App1 that integrates with a Microsoft Foundry project named Project1.
You need to ensure that App1 meets the following requirements:
- Authenticates by using a Microsoft Entra managed identity
- Sends prompts to a deployed model by using the Azure OpenAI Responses API How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.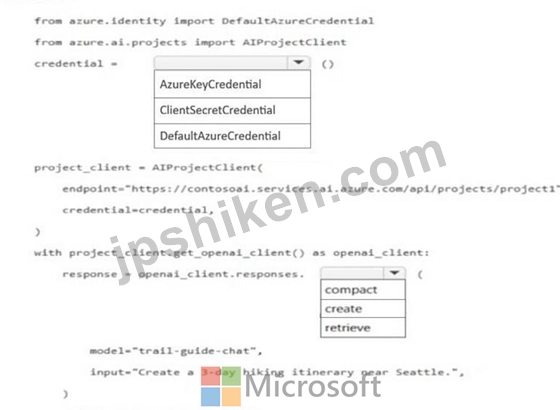
正解:
解説: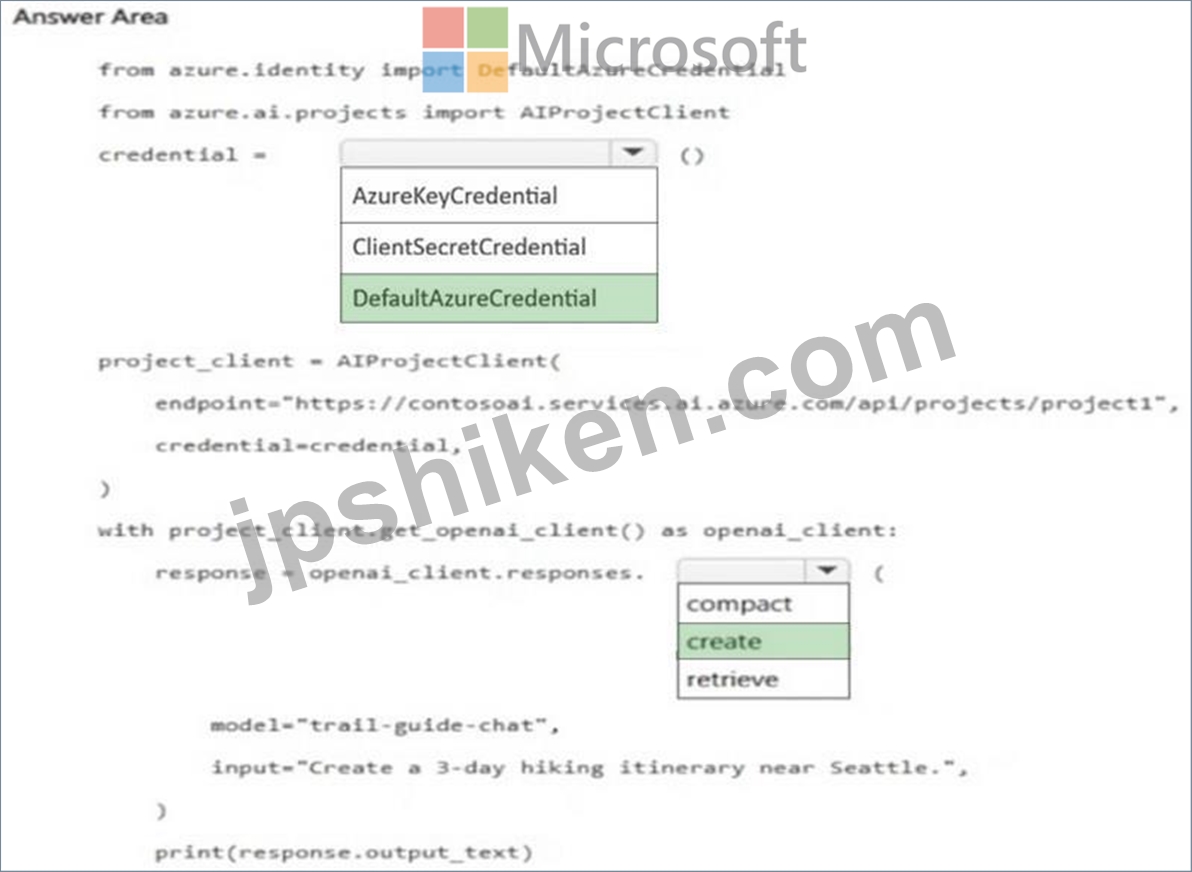
質問 # 77
......
AI-103テストガイドのサービスは非常に優れています。開発プロセスにおける顧客のニーズを常に考慮します。 AI-103学習質問には、PDF、PC、およびAPPの3つのバージョンがあります。必要に応じて選択できます。もちろん、事前にAI-103試験トレーニングの試用版を使用できます。それを使用した後、あなたはより深い経験を持つことになります。あなたの気持ちに応じて、お気に入りのAI-103学習教材バージョンを選択できます。 AI-103学習質問など、優れたサービス製品を選択する傾向があると思います
AI-103専門トレーリング: https://www.jpshiken.com/AI-103_shiken.html