BONUS!!! Download part of PDFVCE ACD-301 dumps for free: https://drive.google.com/open?id=1_AIVS4jLyzRhn_4V6V-txBljKysUyQ8_
There are many large and small platforms for selling examination materials in the market, which are dazzling, but most of them cannot guarantee sufficient safety and reliability. Are you worried about the security of your payment while browsing? ACD-301 Test Torrent can ensure the security of the purchase process, product download and installation safe and virus-free. If you have any doubt about this, we will provide you professional personnel to remotely guide the installation and use.
| Section | Objectives |
|---|---|
| Application Design and Development | - Evaluate how Appian can meet user requirements - Design applications leveraging Appian functionality - Implement best practices for multiple application development - Evaluate and design applications for consistency and reusability |
| Extending Appian | - Program advanced APIs that allow Appian to communicate with external systems - Evaluate existing plug-ins and recognize when to develop custom plug-ins - Design and troubleshoot advanced integrations - Evaluate advanced document generation options - Evaluate and implement authentication using connected systems |
| Platform Management | - Implement administration console settings - Describe basic platform enterprise architecture and how it's used - Troubleshoot and resolve issues at the environment level, involving Appian Support when necessary - Schedule, execute, and troubleshoot application deployments across environments |
| Project and Resource Management | - Manage and lead essential activities across an Agile team - Recommend the protocols and procedures involved in Appian governance - Interpret client requirements and recommend technical design options |
| Data Management | - Diagnose and troubleshoot data fabric complexities - Implement advanced database features - Plan, execute, and troubleshoot data migrations - Analyze, evaluate, and troubleshoot high-volume database structures - Analyze and design secure data models - Determine the best way to leverage data fabric, data types, and data migration |
| Proactively Design for Scalability and Performance | - Build and maintain scalable applications - Plan and evaluate load testing - Monitor and troubleshoot issues at the application level - Design and implement performant Appian components |
>> ACD-301 Valid Test Duration <<
In order to serve you better, we have a complete service system for you if you purchasing ACD-301 learning materials. We offer you free demo to have a try before buying, so that you can have a better understanding of what you are going to buy. After your payment for ACD-301 exam dumps, you can receive your downloading link and password within ten minutes, if you don’t receive, you can contact with us, and we will solve it for you. You can enjoy free update for 365 days after buying ACD-301 Exam Dumps, and the update version will be sent to your email automatically. If you have any questions about ACD-301 exam dumps after buying, you can contact with our after-sale service.
NEW QUESTION # 31
You are reviewing log files that can be accessed in Appian to monitor and troubleshoot platform-based issues.
For each type of log file, match the corresponding Information that it provides. Each description will either be used once, or not at all.
Note: To change your responses, you may deselect your response by clicking the blank space at the top of the selection list.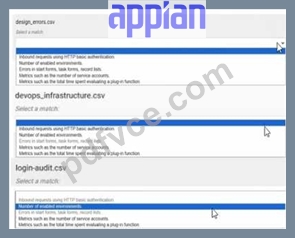
Answer:
Explanation: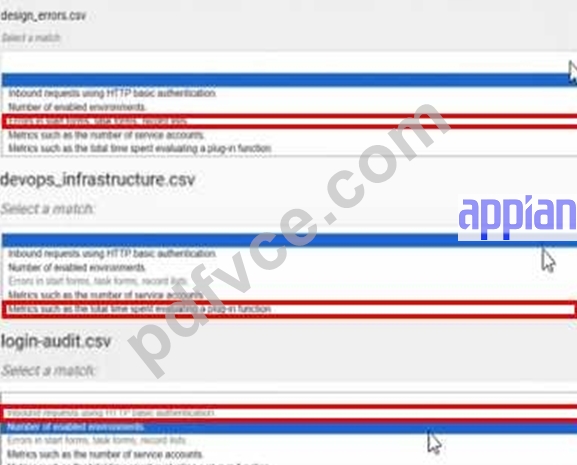
NEW QUESTION # 32
You are developing a case management application to manage support cases for a large set of sites. One of the tabs in this application s site Is a record grid of cases, along with Information about the site corresponding to that case. Users must be able to filter cases by priority level and status.
You decide to create a view as the source of your entity-backed record, which joins the separate case/site tables (as depicted in the following Image).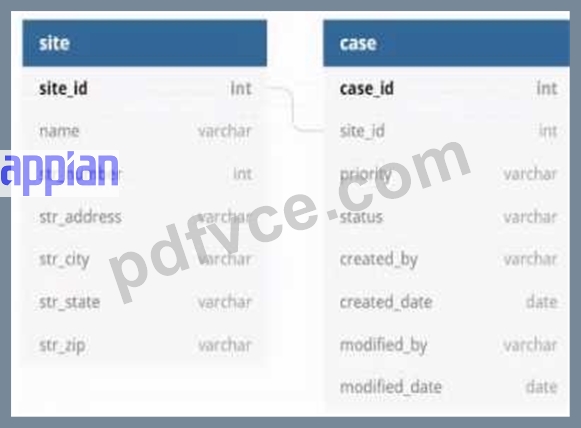
Which three column should be indexed?
Answer: C,D,E
Explanation:
Indexing columns can improve the performance of queries that use those columns in filters, joins, or order by clauses. In this case, the columns that should be indexed are site_id, status, and priority, because they are used for filtering or joining the tables. Site_id is used to join the case and site tables, so indexing it will speed up the join operation. Status and priority are used to filter the cases by the user's input, so indexing them will reduce the number of rows that need to be scanned. Name, modified_date, and case_id do not need to be indexed, because they are not used for filtering or joining. Name and modified_date are only used for displaying information in the record grid, and case_id is only used as a unique identifier for each record. Verified Appian Records Tutorial,Appian Best Practices As an Appian Lead Developer, optimizing a database view for an entity-backed record grid requires indexing columns frequently used in queries, particularly for filtering and joining. The scenario involves a record grid displaying cases with site information, filtered by "priority level" and "status," and joined via the site_id foreign key. The image shows two tables (site and case) with a relationship via site_id. Let's evaluate each column based on Appian's performance best practices and query patterns:
A . site_id:This is a primary key in the site table and a foreign key in the case table, used for joining the tables in the view. Indexing site_id in the case table (and ensuring it's indexed in site as a PK) optimizes JOIN operations, reducing query execution time for the record grid. Appian's documentation recommends indexing foreign keys in large datasets to improve query performance, especially for entity-backed records. This is critical for the join and must be included.
B . status:Users filter cases by "status" (a varchar column in the case table). Indexing status speeds up filtering queries (e.g., WHERE status = 'Open') in the record grid, particularly with large datasets. Appian emphasizes indexing columns used in WHERE clauses or filters to enhance performance, making this a key column for optimization. Since status is a common filter, it's essential.
C . name:This is a varchar column in the site table, likely used for display (e.g., site name in the grid). However, the scenario doesn't mention filtering or sorting by name, and it's not part of the join or required filters. Indexing name could improve searches if used, but it's not a priority given the focus on priority and status filters. Appian advises indexing only frequently queried or filtered columns to avoid unnecessary overhead, so this isn't necessary here.
D . modified_date:This is a date column in the case table, tracking when cases were last updated. While useful for sorting or historical queries, the scenario doesn't specify filtering or sorting by modified_date in the record grid. Indexing it could help if used, but it's not critical for the current requirements. Appian's performance guidelines prioritize indexing columns in active filters, making this lower priority than site_id, status, and priority.
E . priority:Users filter cases by "priority level" (a varchar column in the case table). Indexing priority optimizes filtering queries (e.g., WHERE priority = 'High') in the record grid, similar to status. Appian's documentation highlights indexing columns used in WHERE clauses for entity-backed records, especially with large datasets. Since priority is a specified filter, it's essential to include.
F . case_id:This is the primary key in the case table, already indexed by default (as PKs are automatically indexed in most databases). Indexing it again is redundant and unnecessary, as Appian's Data Store configuration relies on PKs for unique identification but doesn't require additional indexing for performance in this context. The focus is on join and filter columns, not the PK itself.
Conclusion: The three columns to index are A (site_id), B (status), and E (priority). These optimize the JOIN (site_id) and filter performance (status, priority) for the record grid, aligning with Appian's recommendations for entity-backed records and large datasets. Indexing these columns ensures efficient querying for user filters, critical for the application's performance.
Appian Documentation: "Performance Best Practices for Data Stores" (Indexing Strategies).
Appian Lead Developer Certification: Data Management Module (Optimizing Entity-Backed Records).
Appian Best Practices: "Working with Large Data Volumes" (Indexing for Query Performance).
NEW QUESTION # 33
Users must be able to navigate throughout the application while maintaining complete visibility in the application structure and easily navigate to previous locations. Which Appian Interface Pattern would you recommend?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
The requirement emphasizes navigation with complete visibility of the application structure and the ability to return to previous locations easily. The Breadcrumbs pattern is specifically designed to meet this need. According to Appian's design best practices, the Breadcrumbs pattern provides a visual trail of the user's navigation path, showing the hierarchy of pages or sections within the application. This allows users to understand their current location relative to the overall structure and quickly navigate back to previous levels by clicking on the breadcrumb links.
Option A (Billboards as Cards): This pattern is useful for presenting high-level options or choices on a homepage in a visually appealing way. However, it does not address navigation visibility or the ability to return to previous locations, making it irrelevant to the requirement.
Option B (Activity History): This pattern tracks and displays a log of activities or actions within the application, typically for auditing or monitoring purposes. It does not enhance navigation or provide visibility into the application structure.
Option C (Drilldown Report): This pattern allows users to explore detailed data within reports by drilling into specific records. While it supports navigation within data, it is not designed for general application navigation or maintaining structural visibility.
Option D (Breadcrumbs): This is the correct choice as it directly aligns with the requirement. Per Appian's Interface Patterns documentation, Breadcrumbs improve usability by showing a hierarchical path (e.g., Home > Section > Subsection) and enabling backtracking, fulfilling both visibility and navigation needs.
NEW QUESTION # 34
As part of your implementation workflow, users need to retrieve data stored in a third-party Oracle database on an interface. You need to design a way to query this information.
How should you set up this connection and query the data?
Answer: B
Explanation:
Comprehensive and Detailed In-Depth Explanation:
As an Appian Lead Developer, designing a solution to query data from a third-party Oracle database for display on an interface requires secure, efficient, and maintainable integration. The scenario focuses on real-time retrieval for users, so the design must leverage Appian's data connectivity features. Let's evaluate each option:
A . Configure a Query Database node within the process model. Then, type in the connection information, as well as a SQL query to execute and return the data in process variables:
The Query Database node (part of the Smart Services) allows direct SQL execution against a database, but it requires manual connection details (e.g., JDBC URL, credentials), which isn't scalable or secure for Production. Appian's documentation discourages using Query Database for ongoing integrations due to maintenance overhead, security risks (e.g., hardcoding credentials), and lack of governance. This is better for one-off tasks, not real-time interface queries, making it unsuitable.
B . Configure a timed utility process that queries data from the third-party database daily, and stores it in the Appian business database. Then use a!queryEntity using the Appian data source to retrieve the data:
This approach syncs data daily into Appian's business database (e.g., via a timer event and Query Database node), then queries it with a!queryEntity. While it works for stale data, it introduces latency (up to 24 hours) for users, which doesn't meet real-time needs on an interface. Appian's best practices recommend direct data source connections for up-to-date data, not periodic caching, unless latency is acceptable-making this inefficient here.
C . Configure an expression-backed record type, calling an API to retrieve the data from the third-party database. Then, use a!queryRecordType to retrieve the data:
Expression-backed record types use expressions (e.g., a!httpQuery()) to fetch data, but they're designed for external APIs, not direct database queries. The scenario specifies an Oracle database, not an API, so this requires building a custom REST service on the Oracle side, adding complexity and latency. Appian's documentation favors Data Sources for database queries over API calls when direct access is available, making this less optimal and over-engineered.
D . In the Administration Console, configure the third-party database as a "New Data Source." Then, use a!queryEntity to retrieve the data:
This is the best choice. In the Appian Administration Console, you can configure a JDBC Data Source for the Oracle database, providing connection details (e.g., URL, driver, credentials). This creates a secure, managed connection for querying via a!queryEntity, which is Appian's standard function for Data Store Entities. Users can then retrieve data on interfaces using expression-backed records or queries, ensuring real-time access with minimal latency. Appian's documentation recommends Data Sources for database integrations, offering scalability, security, and governance-perfect for this requirement.
Conclusion: Configuring the third-party database as a New Data Source and using a!queryEntity (D) is the recommended approach. It provides direct, real-time access to Oracle data for interface display, leveraging Appian's native data connectivity features and aligning with Lead Developer best practices for third-party database integration.
Appian Documentation: "Configuring Data Sources" (JDBC Connections and a!queryEntity).
Appian Lead Developer Certification: Data Integration Module (Database Query Design).
Appian Best Practices: "Retrieving External Data in Interfaces" (Data Source vs. API Approaches).
NEW QUESTION # 35
Your Agile Scrum project requires you to manage two teams, with three developers per team. Both teams are to work on the same application in parallel. How should the work be divided between the teams, avoiding issues caused by cross-dependency?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
In an Agile Scrum environment with two teams working on the same application in parallel, effective work division is critical to avoid cross-dependency, which can lead to delays, conflicts, and inefficiencies. Appian's Agile Development Best Practices emphasize team autonomy and minimizing dependencies to ensure smooth progress.
Option B (Group epics and stories by feature, and allocate work between each team by feature):
This is the recommended approach. By dividing the application's functionality into distinct features (e.g., Team 1 handles customer management, Team 2 handles campaign tracking), each team can work independently on a specific domain. This reduces cross-dependency because teams are not reliant on each other's deliverables within a sprint. Appian's guidance on multi-team projects suggests feature-based partitioning as a best practice, allowing teams to own their backlog items, design, and testing without frequent coordination. For example, Team 1 can develop and test customer-related interfaces while Team 2 works on campaign processes, merging their work during integration phases.
Option A (Group epics and stories by technical difficulty, and allocate one team the more challenging stories):
This creates an imbalance, potentially overloading one team and underutilizing the other, which can lead to morale issues and uneven progress. It also doesn't address cross-dependency, as challenging stories might still require input from both teams (e.g., shared data models), increasing coordination needs.
Option C (Allocate stories to each team based on the cumulative years of experience of the team members):
Experience-based allocation ignores the project's functional structure and can result in mismatched skills for specific features. It also risks dependencies if experienced team members are needed across teams, complicating parallel work.
Option D (Have each team choose the stories they would like to work on based on personal preference):
This lacks structure and could lead to overlap, duplication, or neglect of critical features. It increases the risk of cross-dependency as teams might select interdependent stories without coordination, undermining parallel development.
Feature-based division aligns with Scrum principles of self-organization and minimizes dependencies, making it the most effective strategy for this scenario.
NEW QUESTION # 36
......
Don't be trapped by one exam and give up the whole Appian certification. If you have no confidence in passing exam, PDFVCE releases the latest and valid ACD-301 guide torrent files which is useful for you to get through your exam certainly. The earlier you pass exams and get certification with our ACD-301 Latest Braindumps, the earlier you get further promotion and better benefits. Sometimes opportunity knocks but once. Timing is everything.
Exam ACD-301 Collection: https://www.pdfvce.com/Appian/ACD-301-exam-pdf-dumps.html
What's more, part of that PDFVCE ACD-301 dumps now are free: https://drive.google.com/open?id=1_AIVS4jLyzRhn_4V6V-txBljKysUyQ8_